Coding models in October 2026: benchmarks, prices and flat-rate plans, open weights against Claude, GPT and Gemini
Companies are told to use more AI and to spend less on it. KPMG's Global CEO Outlook, published in October 2026, surveyed 1,400 chief executives. Of those, 79% call AI a top investment priority. And 72% expect to spend more than a tenth of their budget on it.
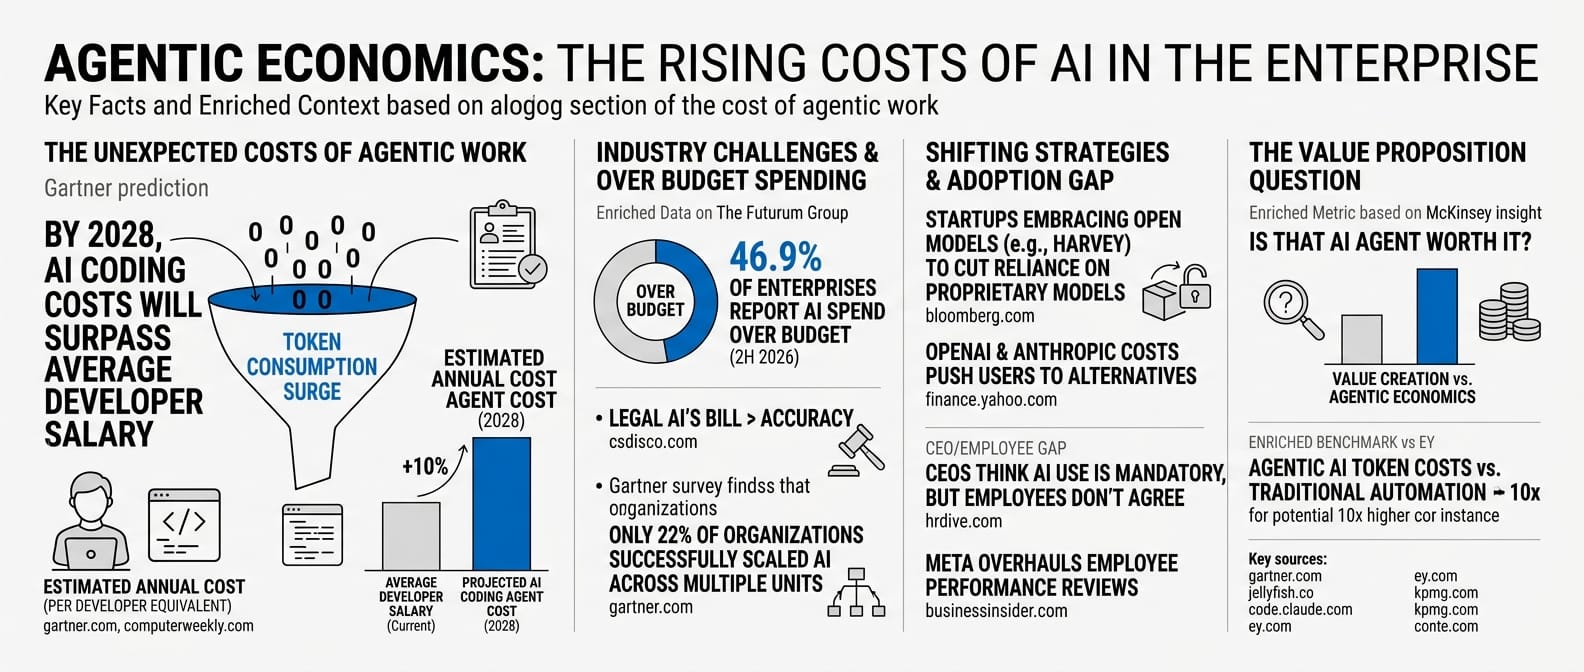
In September, Futurum found AI spend over budget at 46.9% of 1,636 enterprises. Uber pushed its engineers onto Claude Code with usage leaderboards. Then it ran through its 2026 AI budget within months, Fortune reported in August.
Coding agents are where both pressures meet first. In June, Gartner predicted that by 2028 "AI coding costs will overtake the average developer's salary". The list price is not what sets that bill. It depends on how much of each request the provider serves from its cache at a discount, and on how long your sessions run. It also depends on where you buy: a subscription plan, or a hoster that sells the model per token.
This report prices 26 benchmarked models, 26 subscription vendors and 77 pay-per-use hosters at one measured token mix. It shows where each kind of offer wins.
Prices, plans and benchmark scores as of 18 October 2026.
The position. A coding agent resends most of its conversation with every request. Providers keep that repeated part in a cache and bill it at a steep discount: the cached-input price. In October 2026 that price decides an agentic coding bill, not the list price.
Priced that way, two subscriptions (a fixed monthly price for a usage limit) stand out. Claude Max and ChatGPT Pro buy 11 to 59 times more work than the same money spent on the API, where you pay for each token. But neither is meant for your own agent or automation. Anthropic forbids automated access, and OpenAI points automation to the API.
Once you need either, you pay per token. That is where open-weight models matter: models whose makers publish the trained weights, so anyone can run them. GLM 5.3 comes within three points of Claude Fable 5, about two months after it. They cost 9% to 59% of the price of a comparable closed model.
The short answers:
- Strongest models: Terminal-Bench 4.0 (TB4 for short) has agents solve real tasks in a terminal. Claude Opus 5.5 leads it at 64.8%. Next come Sonnet 5.5 (61.8%), GPT-6 Astra and GPT-6.1 Sol (58.2%), Fable 5.1 (57.9%) and Gemini 4 Argon (57.1%). The best open-weight model, GLM 5.3, scores 41.8%.
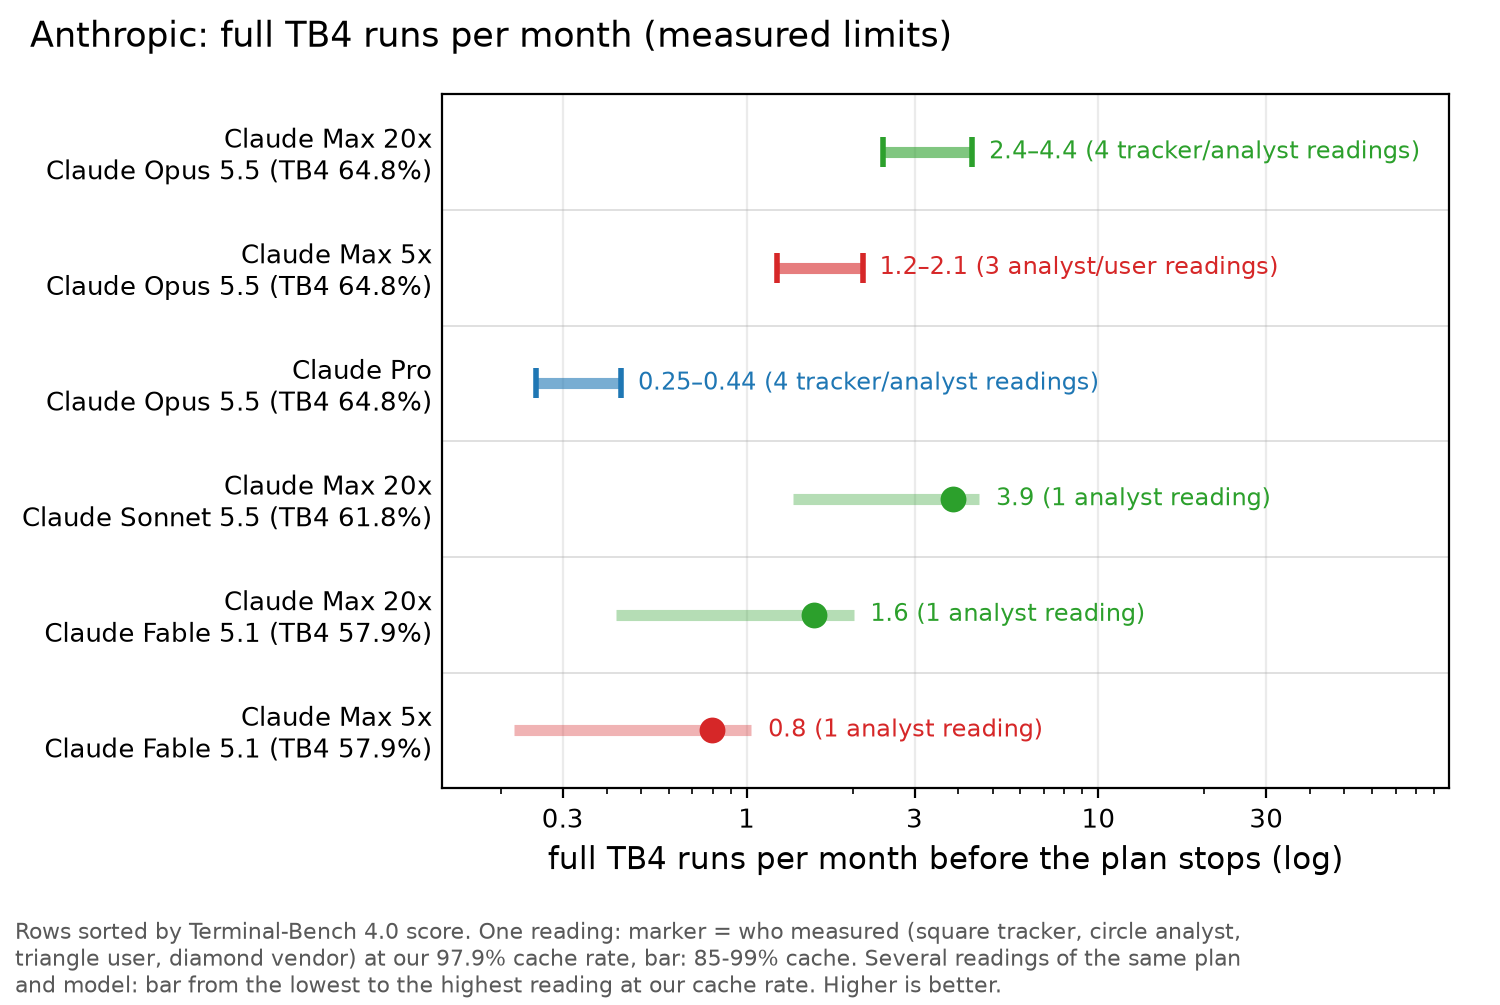
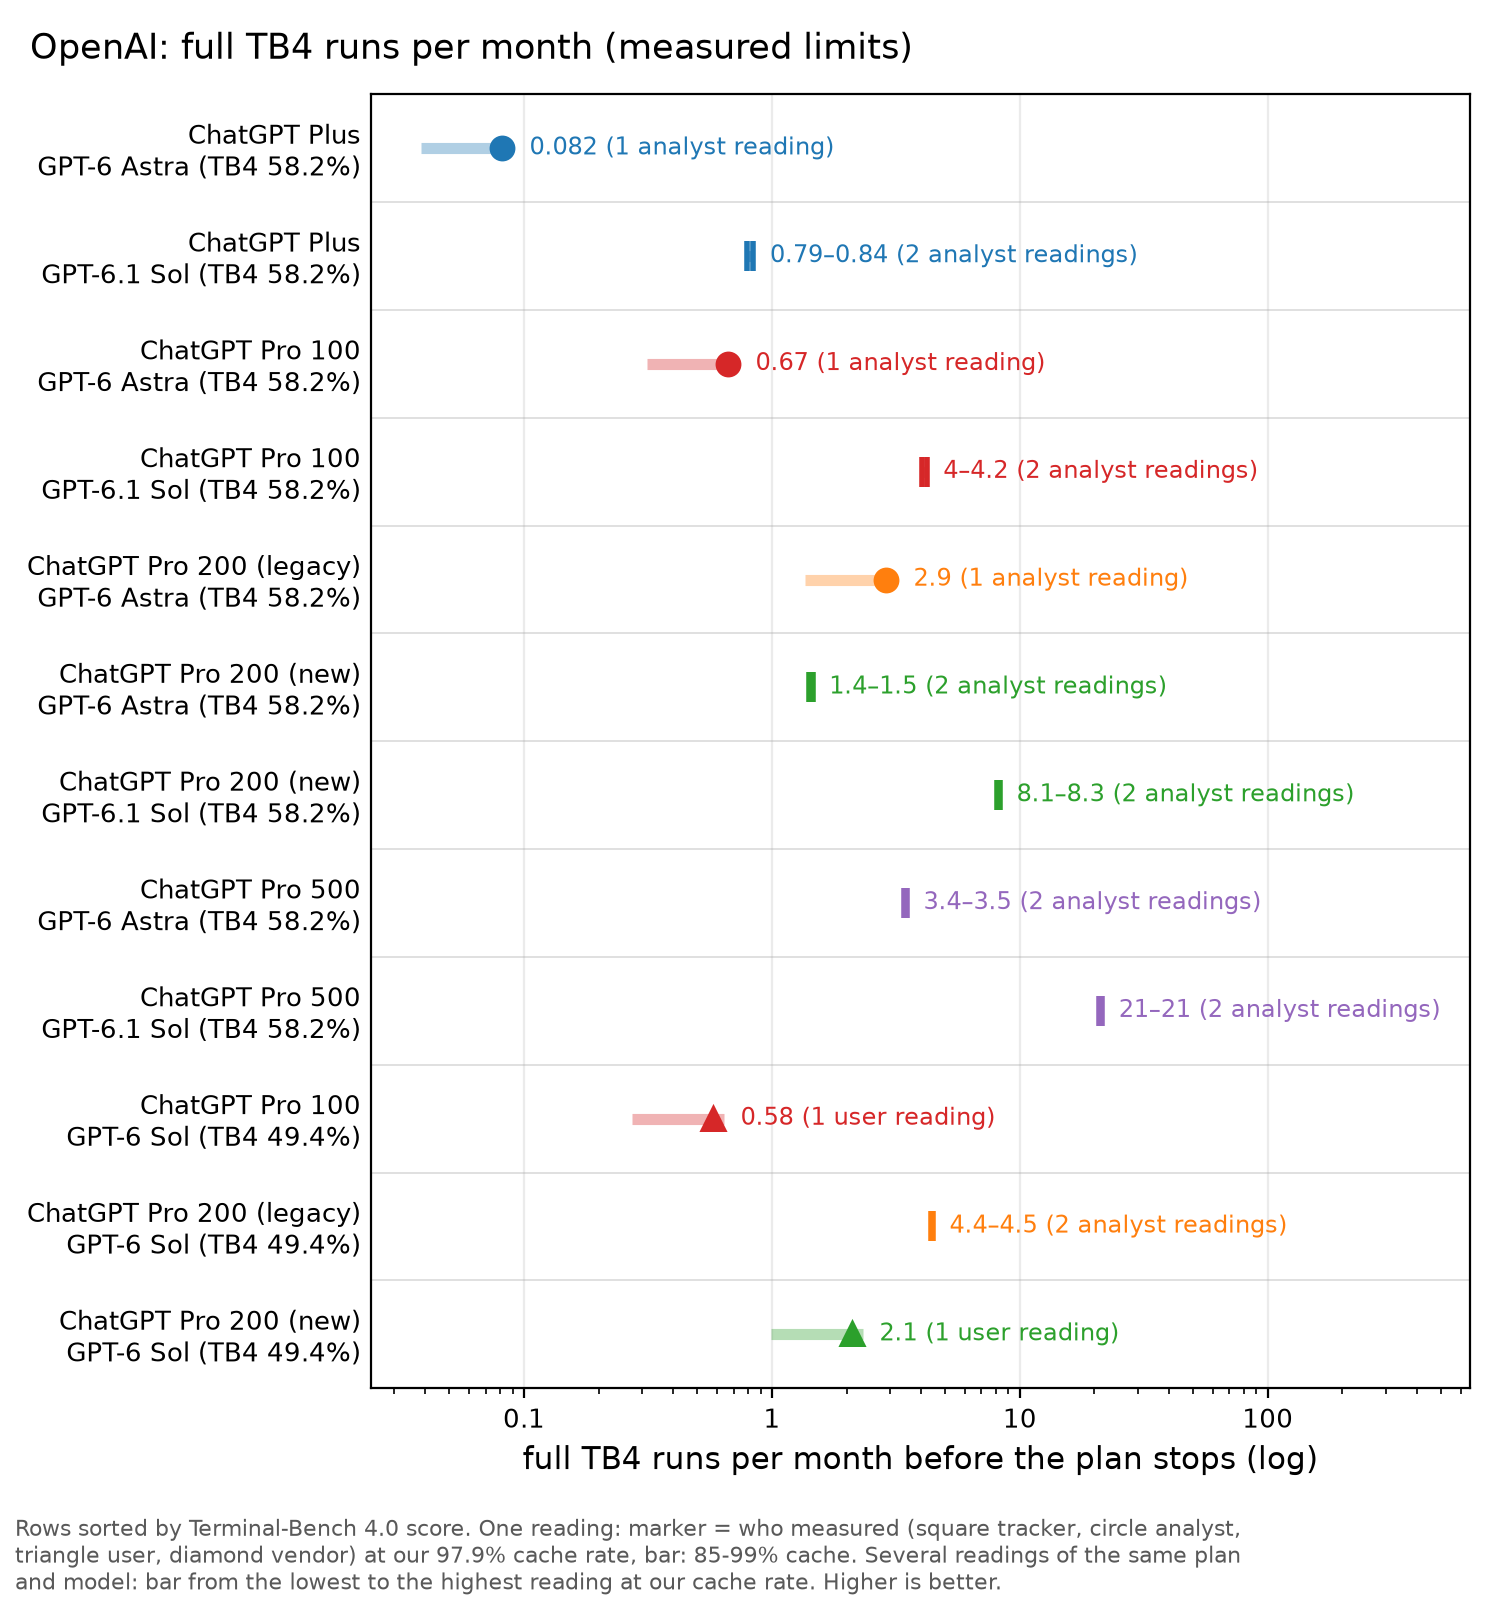
- Token use differs thirteenfold: one full benchmark run takes 1.5 billion tokens on GPT-6.1 Sol and 19.4 billion on Sonnet 5.5. At our token mix that is USD 489 against USD 3,243 per run. Our token mix is the split of cached, fresh and output tokens we measured in one month of our own use, explained below.
- Subscriptions that beat the API: Claude Max 20x (USD 200) buys about 59 times the tokens the same money buys on Anthropic's API. ChatGPT Pro 500 buys about 11 times. Both limits are measured by third parties, not published by the vendor. Anthropic forbids unattended automation, and OpenAI recommends an API key for it.
- Subscriptions that do not: Ollama Cloud Max, Atlas Cloud, Cursor Ultra, Warp Max and NanoGPT buy fewer tokens per dollar than the cheapest pay-per-use offer for the same model.
- Pay-per-use hosters: a hoster runs a model and sells access to it per token; the model maker is the company that built it. For closed models, clouds and gateways charge the maker's list price at standard rates. For open-weight models, prices really differ, but less than public price data suggests. Of 19 hosters that looked cheap, 10 list a higher price on their own site, most of them several times higher.
- Open weights: the strong open models trail the first closed model at least as strong by 2.2 to 3.4 months. They cost 9% to 59% of the cheapest closed model that is at least as strong.
- Teams and startups: team seats for Claude and ChatGPT have settled at the same two prices, USD 25 (standard) and USD 125 (premium). Of the startup programmes, only AWS Activate covers Claude and GPT, through Bedrock.
The recommendation for October 2026
The right choice depends on two questions. How many tokens do you use a month? And do you need your own agent or automation, or is the vendor's tool enough? The figure answers both for six typical profiles. Each bar is the cheapest option that meets the profile's quality bar on Terminal-Bench 4.0 (TB4).
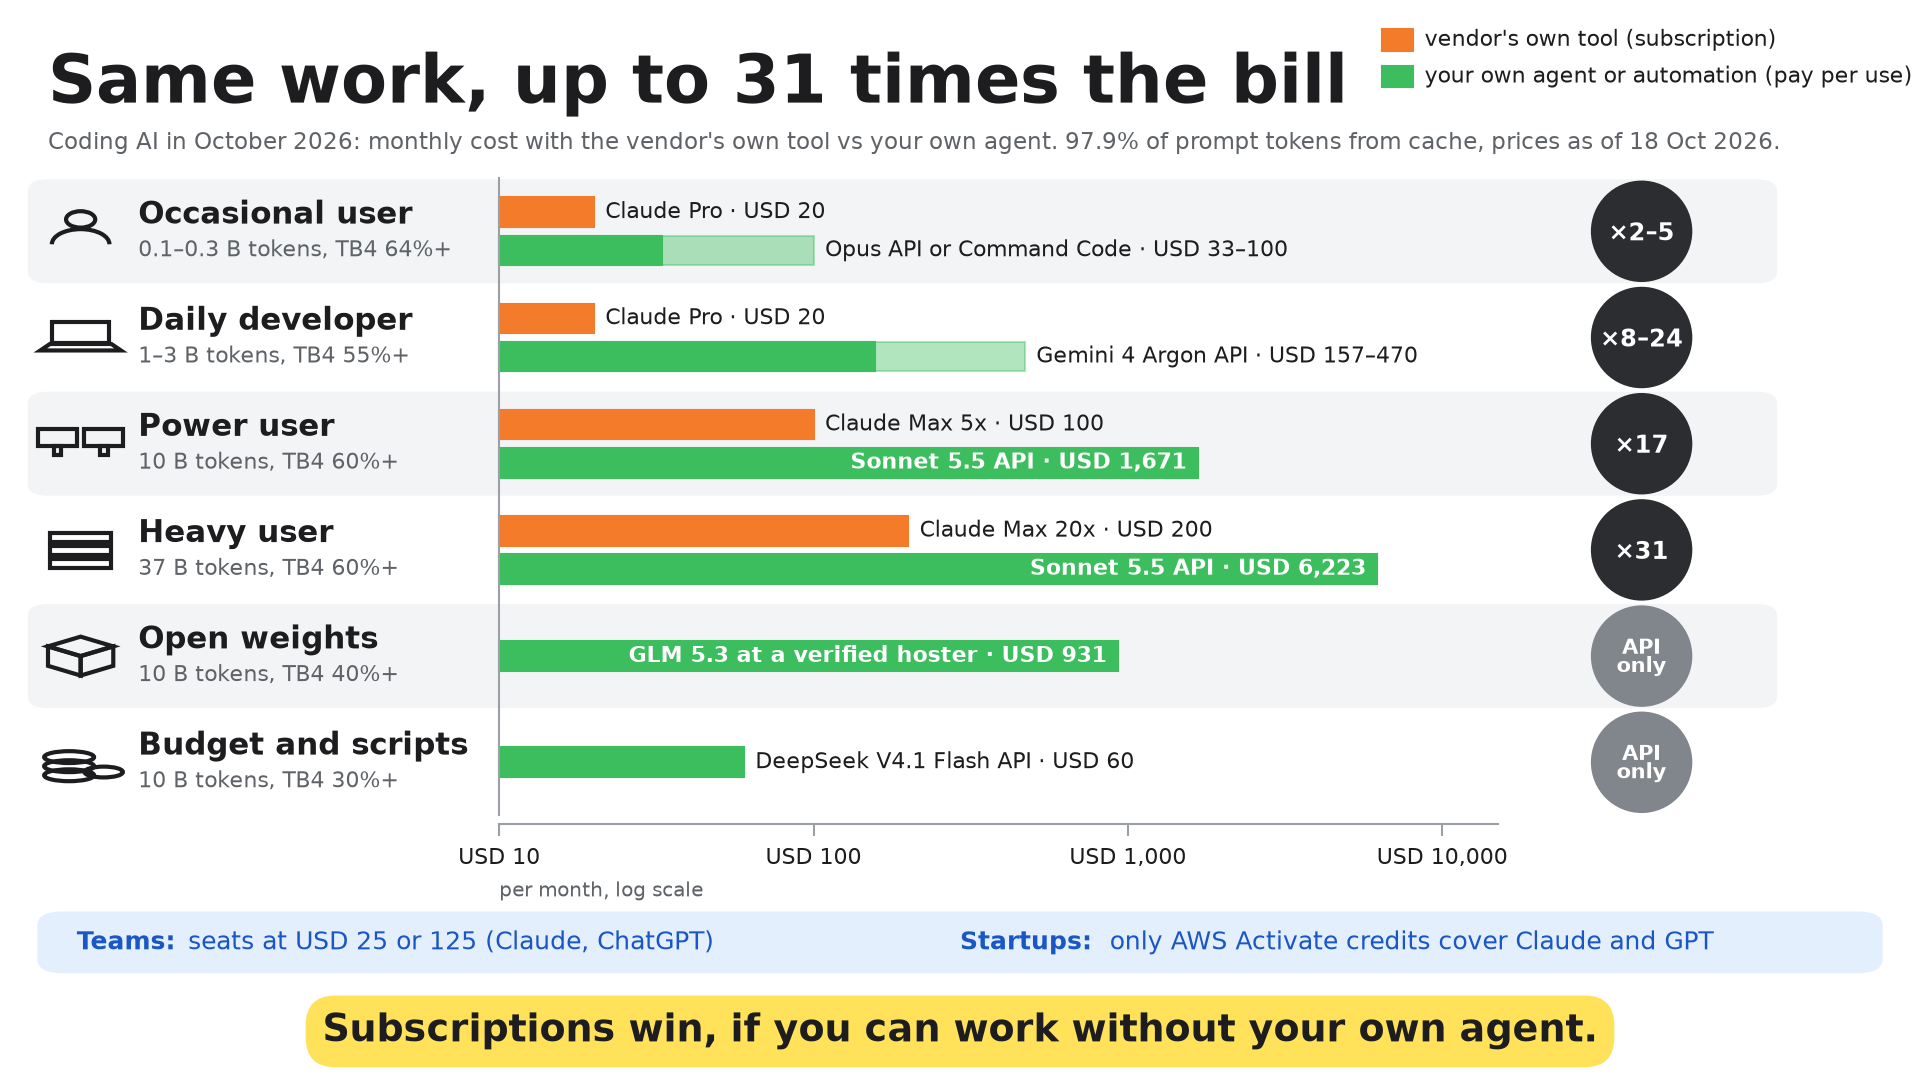
Monthly cost for the same work, cheapest option per usage profile. 97.9% of prompt tokens served from cache. Prices as of 18 October 2026. Orange: the vendor's own tool on a subscription. Green: your own agent or automation, paid per token. Details in the finder below.
How to read it:
- If the vendor's tool is enough, subscribe. Claude Pro at USD 20 covers occasional and daily use. Claude Max 20x at USD 200 covers 37 billion tokens a month. The same work on the Sonnet 5.5 API costs USD 6,223, 31 times as much.
- The gap grows with use. It is 2 to 5 times for an occasional user and 31 times for a heavy user.
- Your own agent means pay-per-use. Claude Max and ChatGPT Pro are not meant for it. Then the model decides the bill: Gemini 4 Argon for daily work, Sonnet 5.5 for heavy work.
- Open weights and budget models cut the API bill. GLM 5.3 at a verified hoster does 10 billion tokens for USD 931, against USD 1,671 for Sonnet 5.5. DeepSeek V4.1 Flash does it for USD 60, at a lower quality bar.
In this article:
- What agentic work costs in 2026: what companies spend, and the token mix behind every price here
- What changed since September: 18 new models, new plan tiers, a new benchmark
- How coding agents are billed: the four token prices, and seven ways plans count usage
- How much context you need: how large requests get, and what a smaller limit does to tokens and cost
- How the models compare on benchmarks: Terminal-Bench 4.0 scores and cost per run
- Subscriptions: which plan for which need: what each plan allows, plan against API, a finder by volume
- Pay-per-use: which hoster for which model: hoster against maker price, cheapest by cache rate, six model rankings
- Teams and startups: seat prices, enterprise API terms, startup credits
- Open weights or frontier models: how far open models trail, and what they cost
- Where this is going
- Vendor by vendor: every subscription and pay-per-use vendor with tables and charts
- Sources
What agentic work costs in 2026
The spend figures come from executive surveys, gateway data and reporting:
| Source | Finding |
|---|---|
| KPMG Global CEO Outlook (October 2026) | 79% of 1,400 CEOs call AI a top investment priority; 72% expect to spend more than 10% of their budget on it; 51% rate cost as very or mostly challenging |
| Futurum, 2H 2026 survey of chief information officers (10 September 2026) | 46.9% of 1,636 enterprises run AI spend over budget; 5.6% under |
| CloudZero (24 June 2026) | 66% of 260 senior finance leaders say their boards make further AI funding conditional on proof of return; 60% spend more on AI than they can justify |
| Fortune (7 August 2026) | Uber encouraged Claude Code use with leaderboards and blew through its 2026 AI budget in the first months of the year |
| Gartner (24 June 2026) | AI coding costs will overtake the average developer's salary by 2028. Peer Insights research, as reported by Computer Weekly: 23% of tech leaders spend USD 200 to 500 per developer per month on tokens for coding agents, 6% of organisations more than USD 2,000 |
| Jellyfish, H1 2026 report | At a typical company the median user went from about USD 5 a month to USD 81 in ten months. In March 2026 the first user spent more on tokens in a month than a junior developer earns |
| Anthropic, Claude Code documentation | Across enterprise deployments, about USD 13 per developer per active day and USD 150 to 250 per month |
| Requesty, The Coding Agent Economy (May 2026) | On its gateway, Claude models power 92% of coding-agent spend; cache hit rates rose from 52% to 86% in twelve months |
| McKinsey (13 July 2026) | About five trillion tokens a month internally as of May 2026; roughly 10% of users account for 65% of consumption |
| Bloomberg (21 September 2026) | Harvey's gross margin fell from about 50% to -50% by June after a usage spike, according to a person familiar with the matter; margins turned positive again after an August model built on Kimi K3 |
| DISCO legal AI report (23 September 2026) | Participants raised, without being asked, the shift to token and credit pricing and the difficulty of budgeting against it |
| EY, Can AI pay for itself? (16 September 2026) | EY estimates the token is roughly a third of what an agent costs to run |
Two of these numbers explain most of what follows. On one gateway the cache hit rate, the share of input served from cache at a discount, reached 86%. So the cached-input price sets the bill, not the list price. And Harvey's swing from plus to minus 50% shows how fast a margin goes when usage grows on an expensive model.
The token mix behind every number here
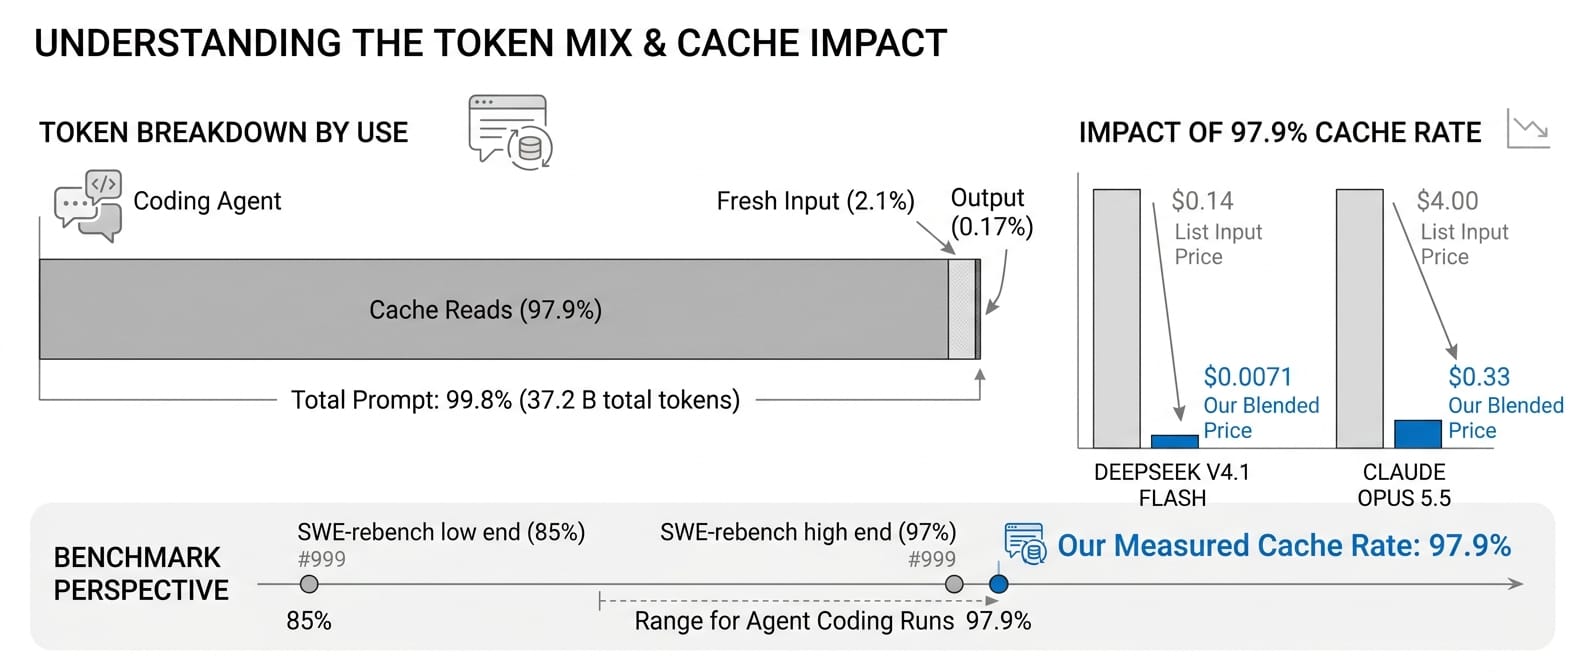
A coding agent sends the whole conversation with every request. That includes the system prompt, repository files, tool output and earlier turns. Most of it is identical to the previous request. So providers serve it from a cache and bill it at a fraction of the input price. The share of prompt tokens served this way is the cache hit rate, called cache rate from here on.
That leaves four prices that matter. How much each one weighs depends on your workload (k = thousand tokens):
| Part of the bill | Our measured share | Price that applies |
|---|---|---|
| Cache reads | 97.9% of prompt tokens | cached-input price |
| Fresh input (new context, sent for the first time) | 2.1% of prompt tokens | input price, or the cache-write price (a fee for storing new context in the cache) where a provider charges one |
| Output | 0.17% of all tokens | output price |
| Average prompt | 305,000 tokens | long-prompt tier, a higher rate for very large requests, where one applies (OpenAI above 272k, xAI above 200k, Anthropic Haiku above 100k) |
The mix comes from one month of our own coding-agent use, 19 September to 18 October 2026, on our own projects. Client work is not included. Usage varies from month to month, so read it as one month's pattern, not a constant:
| Tool | Prompt tokens | Served from cache | Median request | Largest request |
|---|---|---|---|---|
| Claude Code (incl. sub-agents) | 33.3 B | 98.2% | 287k | 971k |
| Codex | 3.7 B | 95.6% | 128k | 258k |
| OpenCode | 0.2 B | 97.6% | 127k | 459k |
| Total | 37.2 B | 97.9% |
This is one heavy user, not a market average. SWE-rebench measures cache rates of 85% to 97% for agent coding runs. So every chart with a cache axis shows that band next to ours.
At this mix, one million tokens costs USD 0.33 on Claude Opus 5.5 and USD 0.0071 on DeepSeek V4.1 Flash. Their list input prices are USD 4.00 and USD 0.14. "At our mix" means this blended price throughout the article. Your cache rate is lower if your agent runs shorter sessions or pauses longer than the cache keeps content. Then every API price with a cache discount rises. Plans that count raw tokens do not get more expensive.
What changed since September
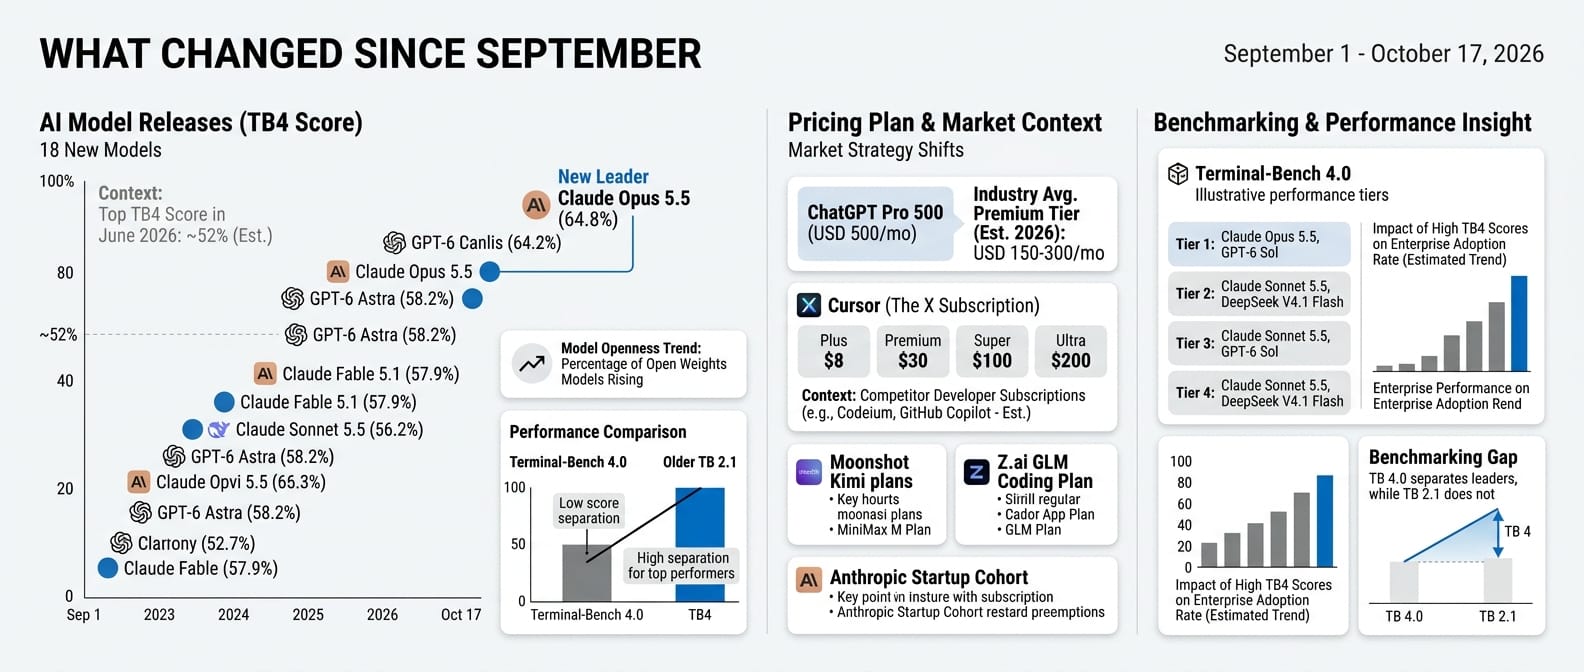
New models. 18 models with a TB4 score were released or first listed between 1 September and 17 October 2026:
| Date (2026) | Model | Weights | TB4 score |
|---|---|---|---|
| 1 Sep | Claude Fable 5.1 | closed | 57.9% |
| 2 Sep | Gemini 3.8 Flash | closed | 19.1% |
| 2 Sep | Qwen 3.8 Max (0902) | closed | 27.0% |
| 2 Sep | Muse Spark 1.3 | closed | 14.5% |
| 3 Sep | GPT-6 Astra | closed | 58.2% |
| 10 Sep | DeepSeek V4.1 Flash | open | 31.2% (vendor) |
| 21 Sep | Grok 4.7 | closed | 37.6% |
| 22 Sep | Claude Opus 5.5 | closed | 64.8% |
| 22 Sep | GPT-6 Sol, GPT-6 Luna | closed | 49.4%, 16.4% |
| 22 Sep | MiMo V2.6 Pro, MiMo V2.6 Flash | open | 34.8%, 28.8% (vendor) |
| 28 Sep | Claude Sonnet 5.5 | closed | 61.8% |
| 29 Sep | GPT-6.1 Sol | closed | 58.2% |
| 8 Oct | Claude Haiku 5.5 | closed | 39.2% (vendor) |
| 8 Oct | Step 5 Preview | open | 33.3% |
| 14 Oct | Gemini 4 Argon | closed | 57.1% |
| 17 Oct | DeepSeek V4.1 Flash 1017 | open | update, same score |
Dates are release dates from the Terminal-Bench leaderboard. For a model not on the leaderboard, the date is when OpenRouter, a large API gateway, first listed it.
Plans. These plans changed:
- OpenAI introduced ChatGPT Pro 500 (USD 500 a month) and reopened Pro 200 for new subscriptions on 29 September.
- Cursor: since October, new customers buy The X Subscription: Plus USD 8, Premium USD 30, Super USD 100, Ultra USD 200. Cursor's own Pro, Pro+ and Ultra continue for existing subscribers.
- Moonshot replaced its Kimi tiers with new plans. They drop the weekly limit for Kimi Code. They keep a rolling five-hour limit plus a monthly pool.
- MiniMax sells an M Plan next to its Token Plan. It comes in three sizes: Go, Explore (3x Go) and Build (7.5x Go). MiniMax publishes no absolute limit for it.
- Z.ai has metered its GLM Coding Plan in credits since 30 July.
- Anthropic's startup cohort filled on 13 October.
Benchmarks. This article uses Terminal-Bench 4.0 because it still separates the leaders. The top score is 64.8%. For each entry, the leaderboard also publishes the agent harness (the agent software that drives the model), the tokens per run and the cost per run. Vendors still report the older Terminal-Bench 2.1. Models that score 2 to 13 on version 4.0 score 66 to 88 there. So the old version barely tells models apart.
How coding agents are billed
Pay-per-use bills each request at four prices: input, cached input, cache write and output. Providers differ on all four:
| Rule | Range in the catalogue |
|---|---|
| Cached-input discount | 50% (Fireworks default, Z.ai) to about 99% (DeepSeek V4 Pro) |
| Cache write | no separate fee listed at most open-weight hosters. For Claude at Anthropic, Bedrock and Vertex: 1.25× input to keep it 5 minutes, 2× to keep it 1 hour |
| Cache lifetime (how long cached content stays) | 5 minutes (Anthropic, Moonshot default) to 24 hours (Vertex implicit), or undisclosed |
| No cache at all | some hosters list no cached price. At our mix they cost 30 to 45 times the maker's price |
| Long-prompt tier | OpenAI doubles input above 272k tokens. xAI raises rates above 200k. Anthropic Haiku 5.5 above 100k |
| Peak pricing | DeepSeek halves prices off-peak |
Subscriptions count usage in seven different ways. Across the 141 tiers we catalogued:
| Plans count usage in | Tiers |
|---|---|
| credits | 47 |
| USD of usage at list prices | 27 |
| a multiple of another plan | 23 |
| requests | 10 |
| tokens | 6 |
| messages | 2 |
| not published at all | 26 |
Only tiers that count tokens or USD, credits with a published formula, or published multiples of a measured tier can be converted to tokens. For the rest, someone has to measure the limit.
How the unpublished limits were measured. Claude Pro and Max, ChatGPT Plus and Pro, Kimi and Cursor do not publish limits in tokens. Two kinds of third-party measurement fill the gap. This report uses both:
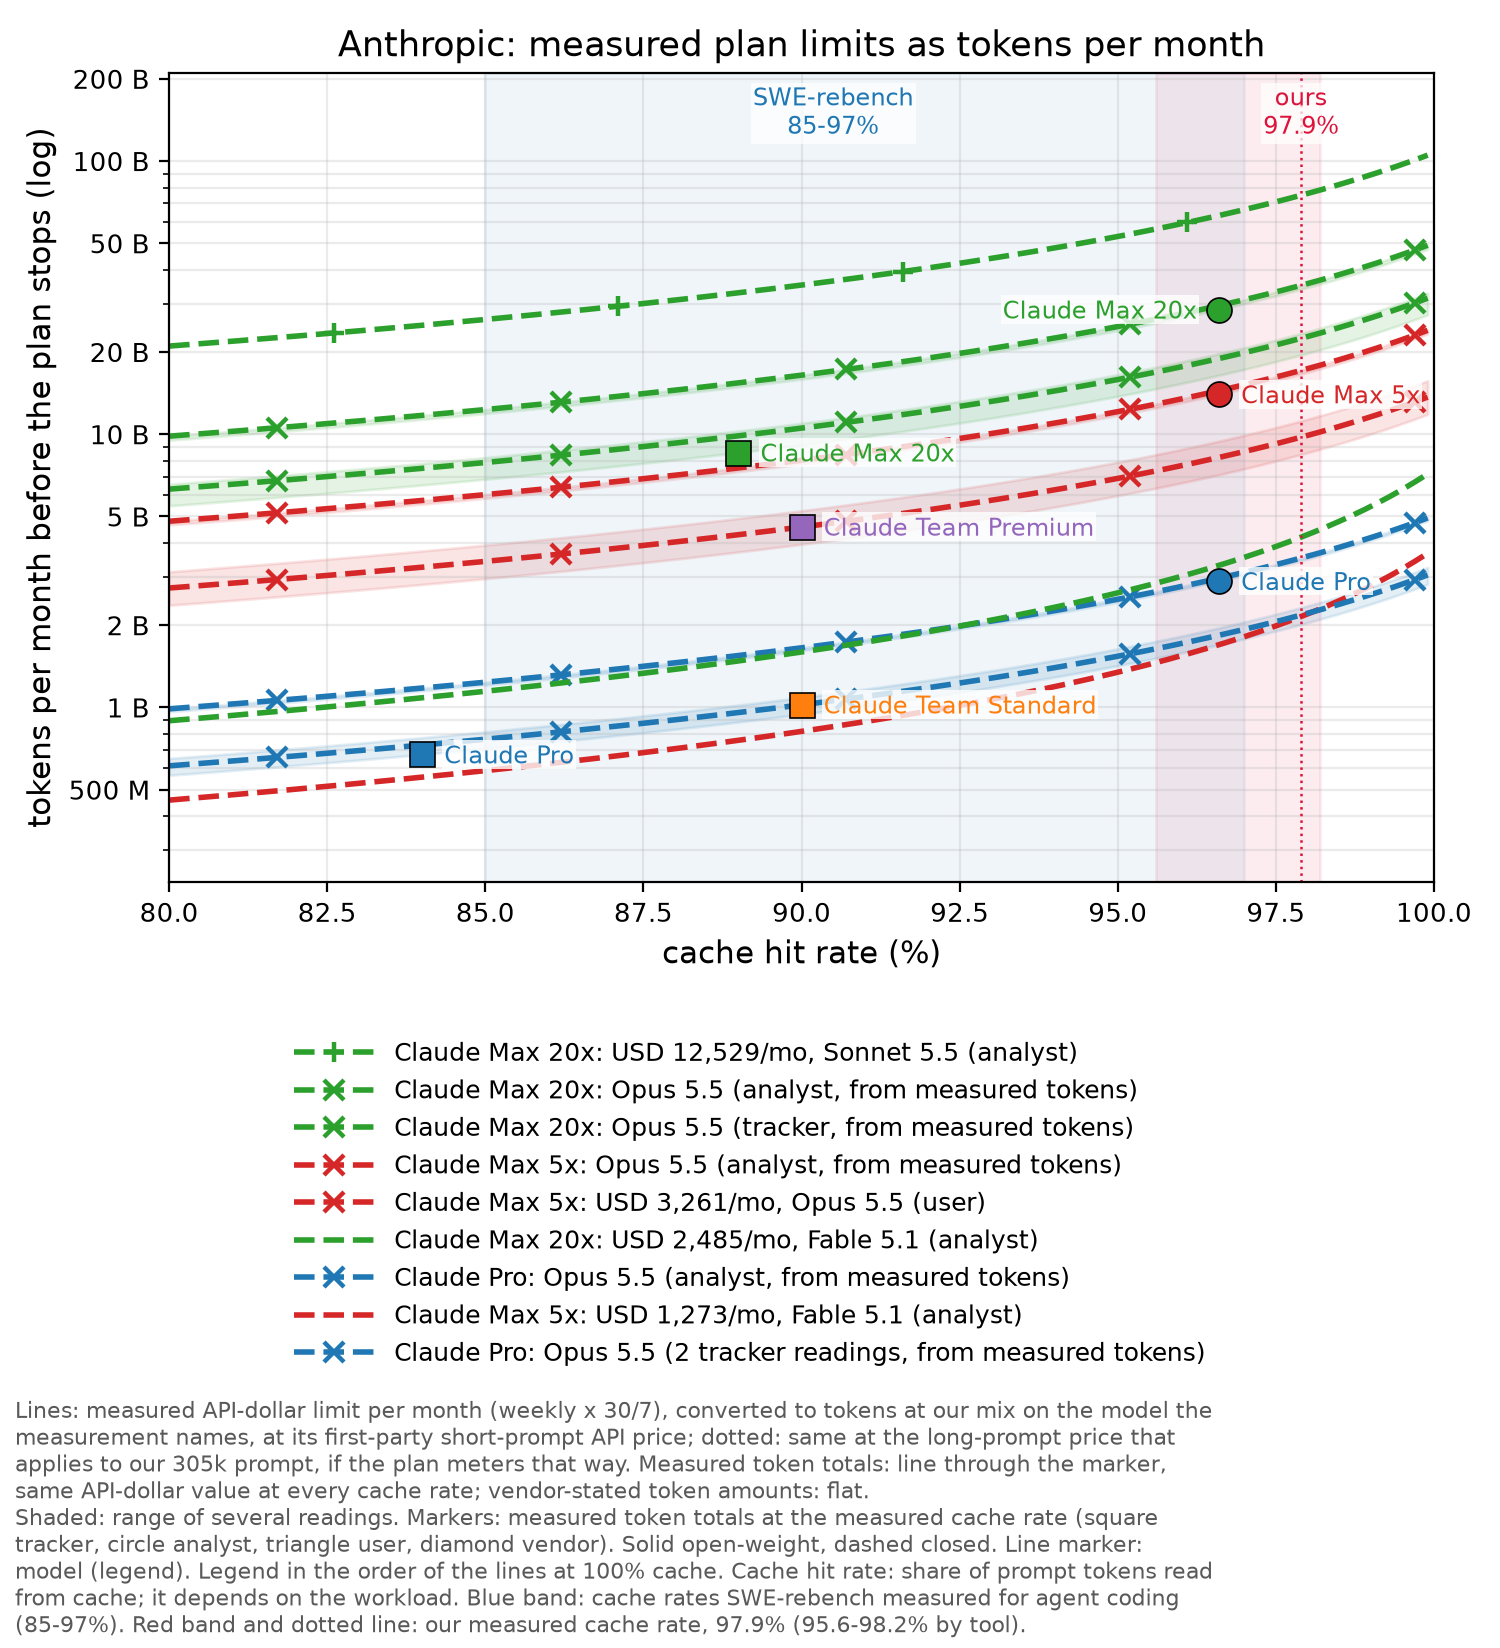
- Trackers such as Wokey route real subscription traffic through a gateway. They take what that traffic would cost on the API and divide it by how far the plan's usage meter moved. Wokey reports Claude Pro at about USD 170 of API value a week, across 559 accounts. Max 20x comes to about USD 1,751 a week, across 36 accounts.
- Analysts run controlled experiments. SemiAnalysis measured the tiers of Claude, ChatGPT, Kimi, MiniMax and Z.ai with an agentic workload at a 96.6% cache rate. For example, it got 2.9 billion tokens a month on Claude Pro and 28.6 billion on Max 20x.
Our catalogue holds 387 such readings for 19 vendors, plus 27 searches that found none. Where readings conflict, we keep both. Within one vendor, every tier uses the source that covers the most tiers, so tiers stay comparable. For Anthropic, OpenAI and Kimi that source is SemiAnalysis. We rescale measured token totals to our cache rate by keeping their API-dollar value the same.
This conversion rests on one assumption. The plans meter usage in API dollars, so a cached token counts at the cached price. SemiAnalysis's measured token totals fit that. Priced at list rates, their Claude and Kimi totals match the dollar values within about 10%. For OpenAI they match only at the short-prompt price. So it is open whether Codex counts prompts above 272k tokens at the doubled API rate.
How much context you need
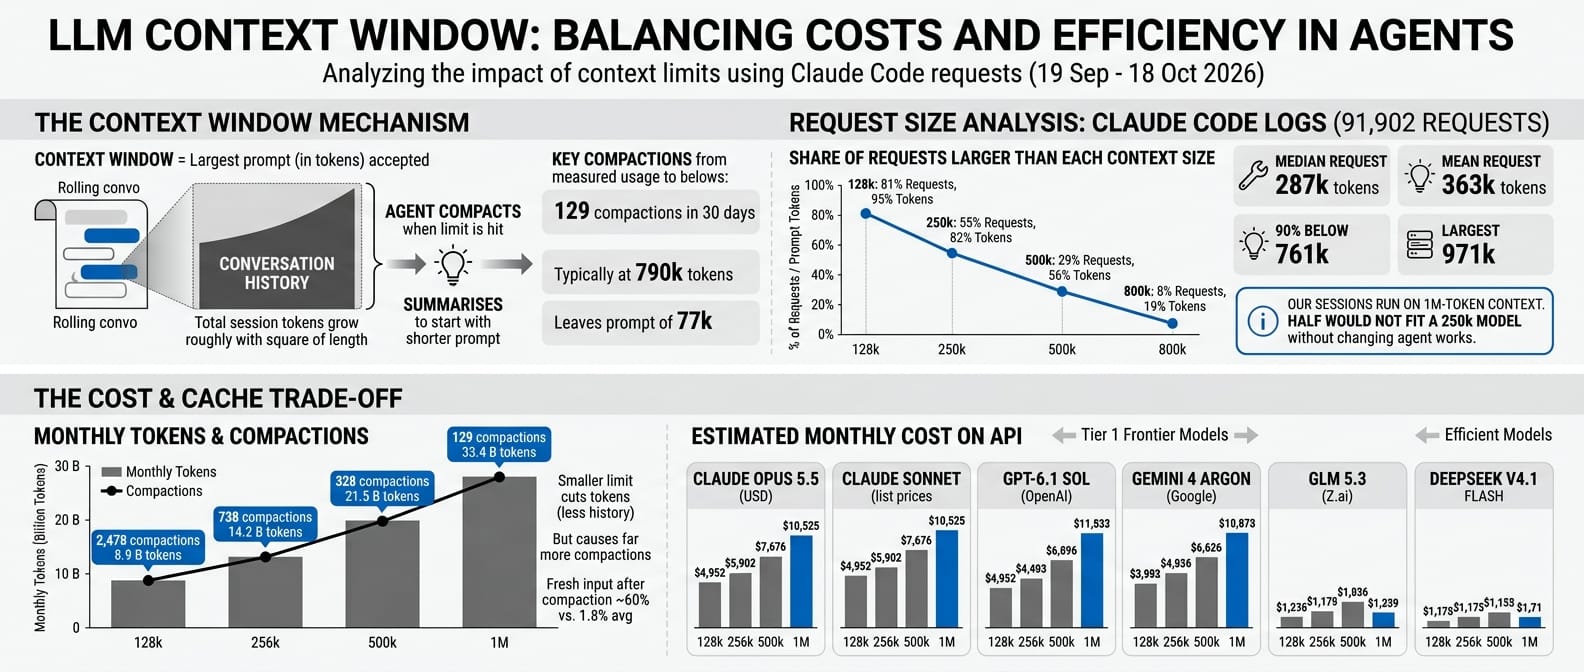
The context window is the largest prompt a model accepts in one request, counted in tokens. It drives cost on its own. An agent resends the whole conversation with every turn. So until the agent compacts, the total tokens of a session grow roughly with the square of its length. The context limit decides when the agent has to compact: summarise the conversation and start again from a shorter prompt.
What our own requests look like. We logged 91,902 Claude Code requests, including sub-agents, from 19 September to 18 October 2026:
| Request size | Value |
|---|---|
| Median | 287k tokens |
| Mean | 363k tokens |
| 90% of requests below | 761k |
| Largest | 971k |
| Context limit | Requests larger than that | Prompt tokens in those requests |
|---|---|---|
| 128k | 81% | 95% |
| 200k | 64% | 88% |
| 250k | 55% | 82% |
| 500k | 29% | 56% |
| 800k | 8% | 19% |
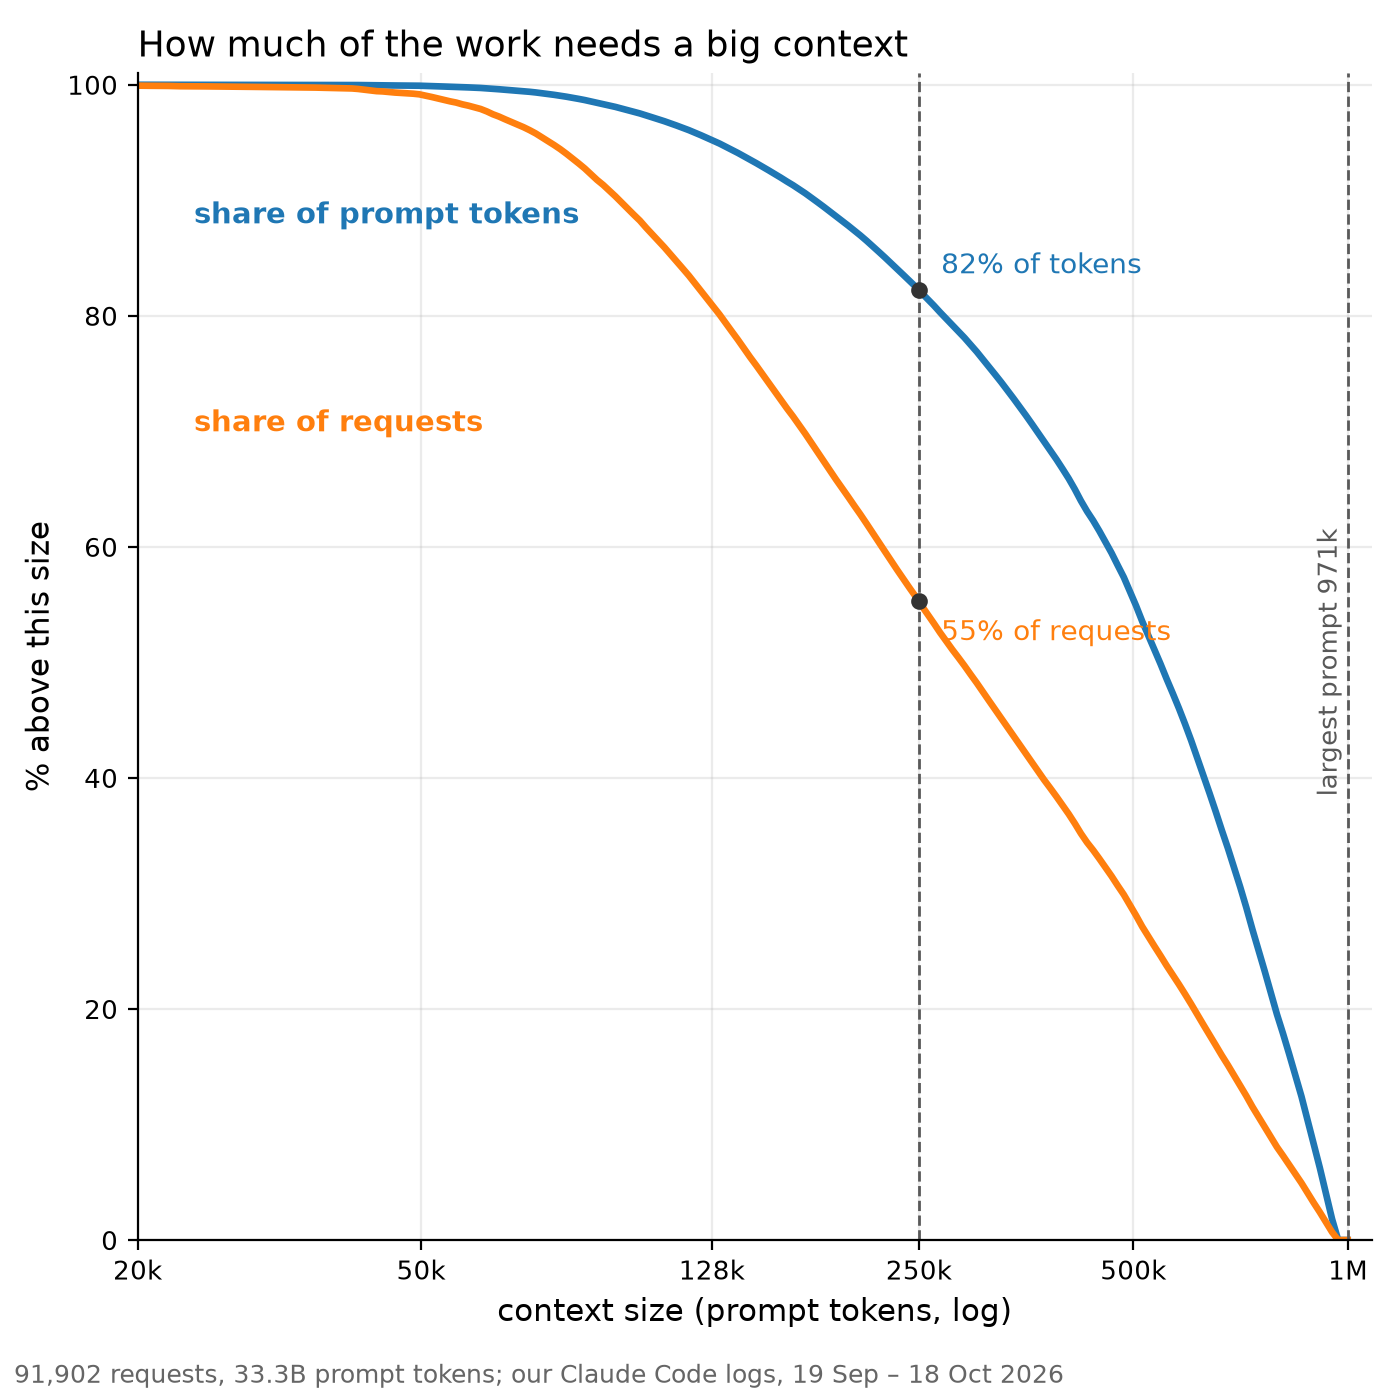
Our sessions run on models with a 1M-token context. Claude Code compacts only near that limit. We saw 129 compactions in 30 days, typically at about 790k tokens. Each one left a prompt of about 77k. Half of our requests would not fit a 250k model without changing how the agent works.
What a smaller limit would do. We replayed the same month turn by turn. The replay compacts whenever a request would exceed the limit. It keeps every turn's measured growth:
| Limit | Prompt tokens a month | Compactions | Share served from cache |
|---|---|---|---|
| 128k | 8.9 B | 2,478 | 94.9% |
| 256k | 14.2 B | 738 | 97.0% |
| 500k | 21.5 B | 328 | 97.7% |
| 1M (replay, matches the measured total) | 33.4 B | 129 | 98.2% |
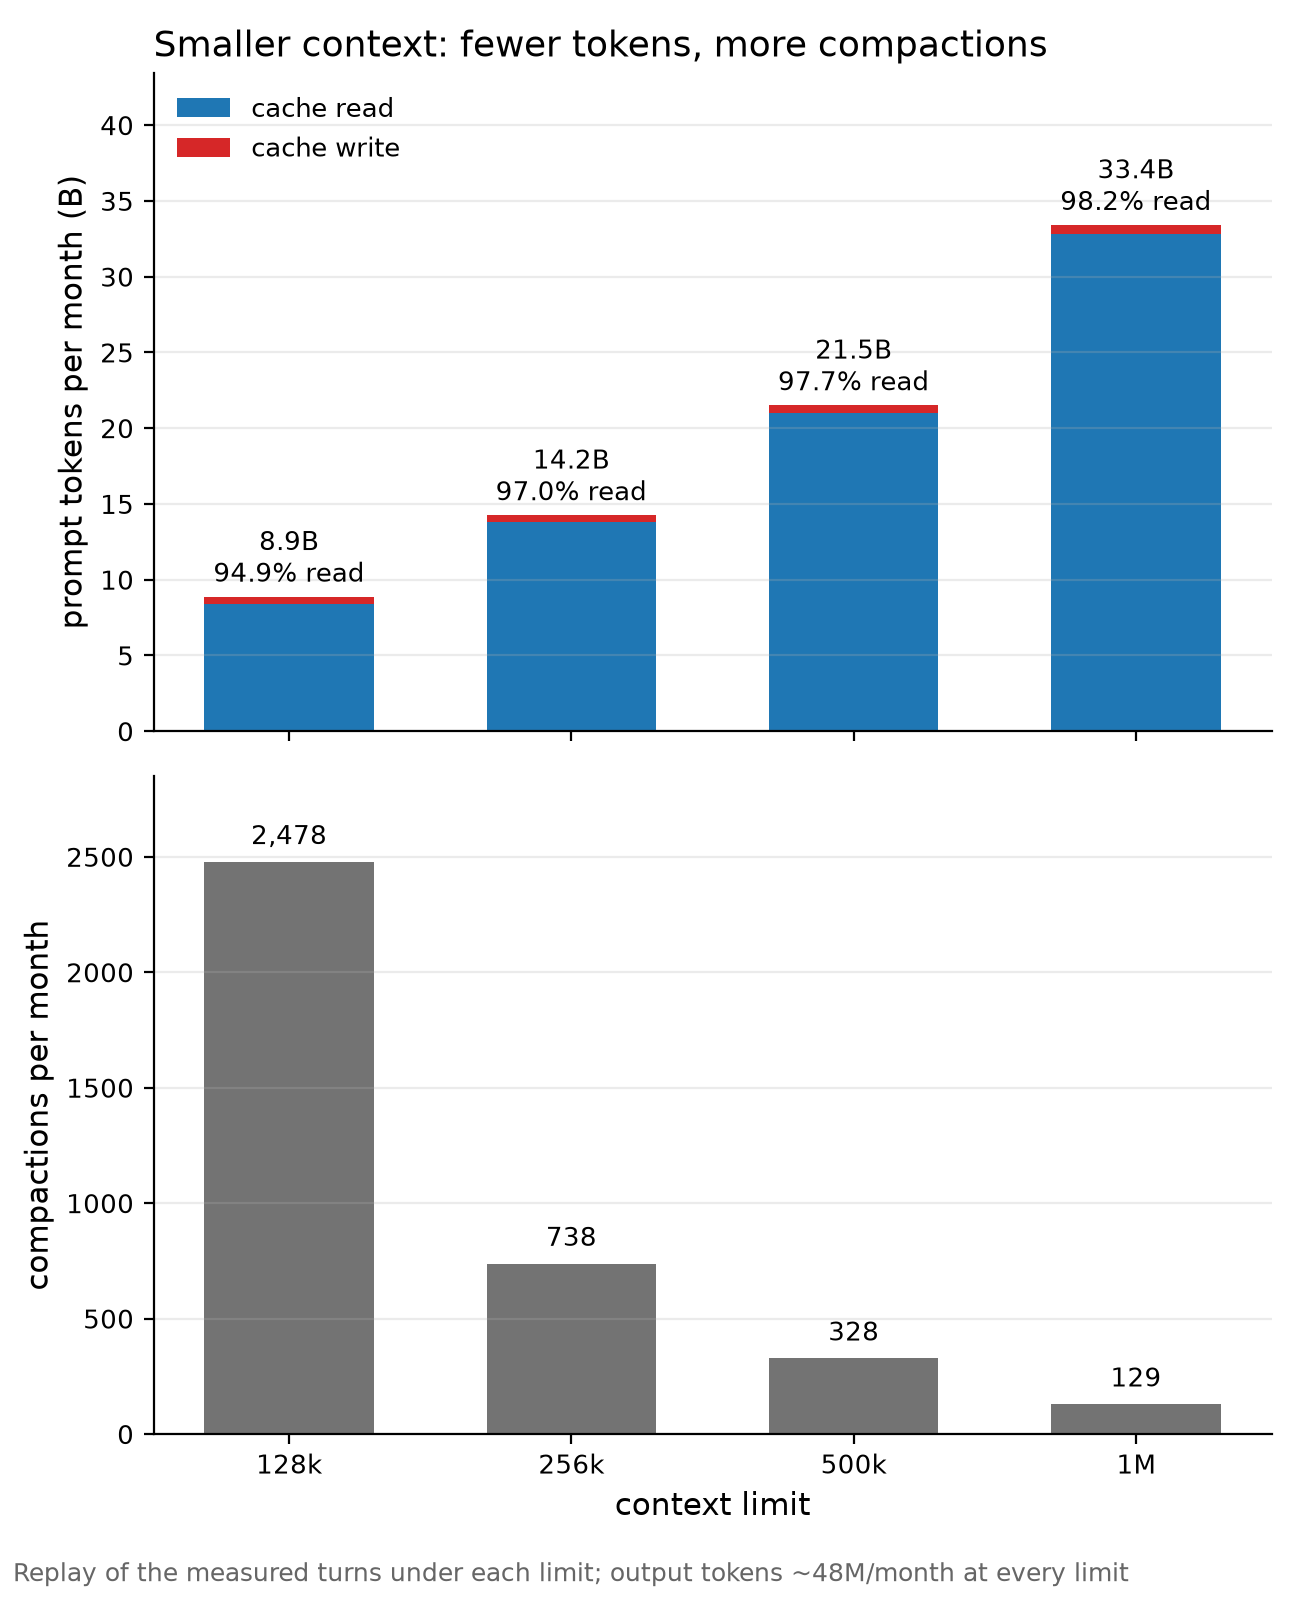
A smaller limit cuts tokens, because each turn carries less history. But the agent also compacts far more often. The request after each compaction is mostly fresh input, not read from cache: 60% fresh in our logs, against 1.8% on average.
What our Claude Code usage would cost on the API. Prices are each model maker's list price. This is not what we pay. These sessions ran mostly on a Claude subscription, and the plan section makes that comparison. USD a month by context limit:
| Model | 128k | 256k | 500k | 1M |
|---|---|---|---|---|
| Claude Opus 5.5 | USD 4,952 | 5,902 | 7,676 | 10,525 |
| Claude Sonnet 5.5 | 2,476 | 2,951 | 3,838 | 5,263 |
| GPT-6.1 Sol | 2,476 | 2,951 | 5,719 | 8,628 (at its 922k input cap) |
| Gemini 4 Argon (promotion) | 2,248 | 2,734 | 3,587 | 4,962 |
| GLM 5.3 (Z.ai) | 3,044 | 4,413 | 6,377 | 9,582 |
| Kimi K3 (Moonshot) | 4,635 | 6,173 | 8,531 | 12,365 |
| DeepSeek V4.1 Flash | 123 | 136 | 167 | 217 |
| MiniMax M3 | 701 | 1,017 | 1,469 | not offered (524k) |
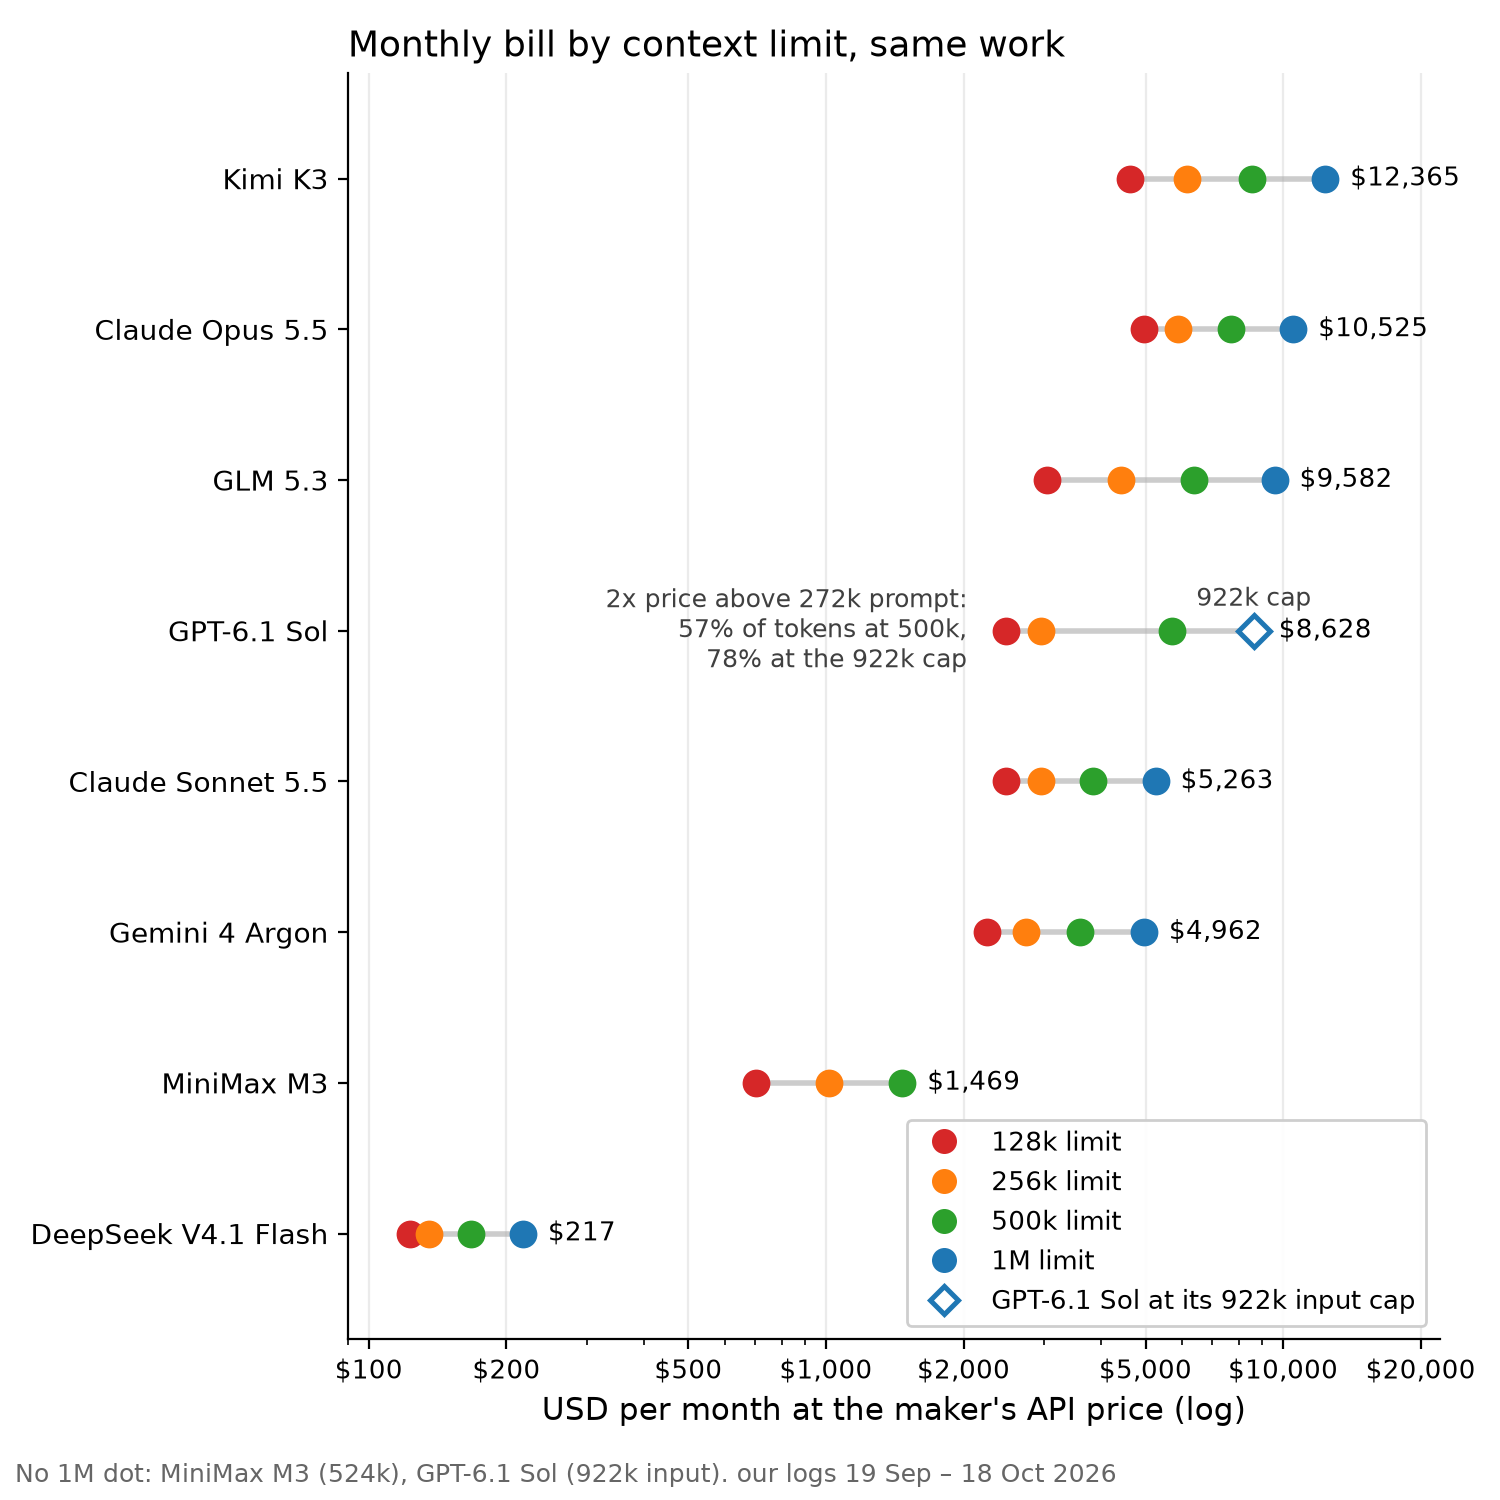
For most models, halving the context from 1M to 500k cuts the bill by about a quarter to a third. GPT-6.1 Sol is the exception. Up to 256k it costs the same as Sonnet 5.5. Above 272k its price doubles, so at 500k it already costs 50% more than Sonnet.
What the replay cannot show is the effect on quality. After each compaction the agent works from a summary. It may need extra turns to recover details. The replay assumes the same turns at every limit. A 128k model would compact 19 times as often as we do today. The savings above shrink by whatever extra work that causes.
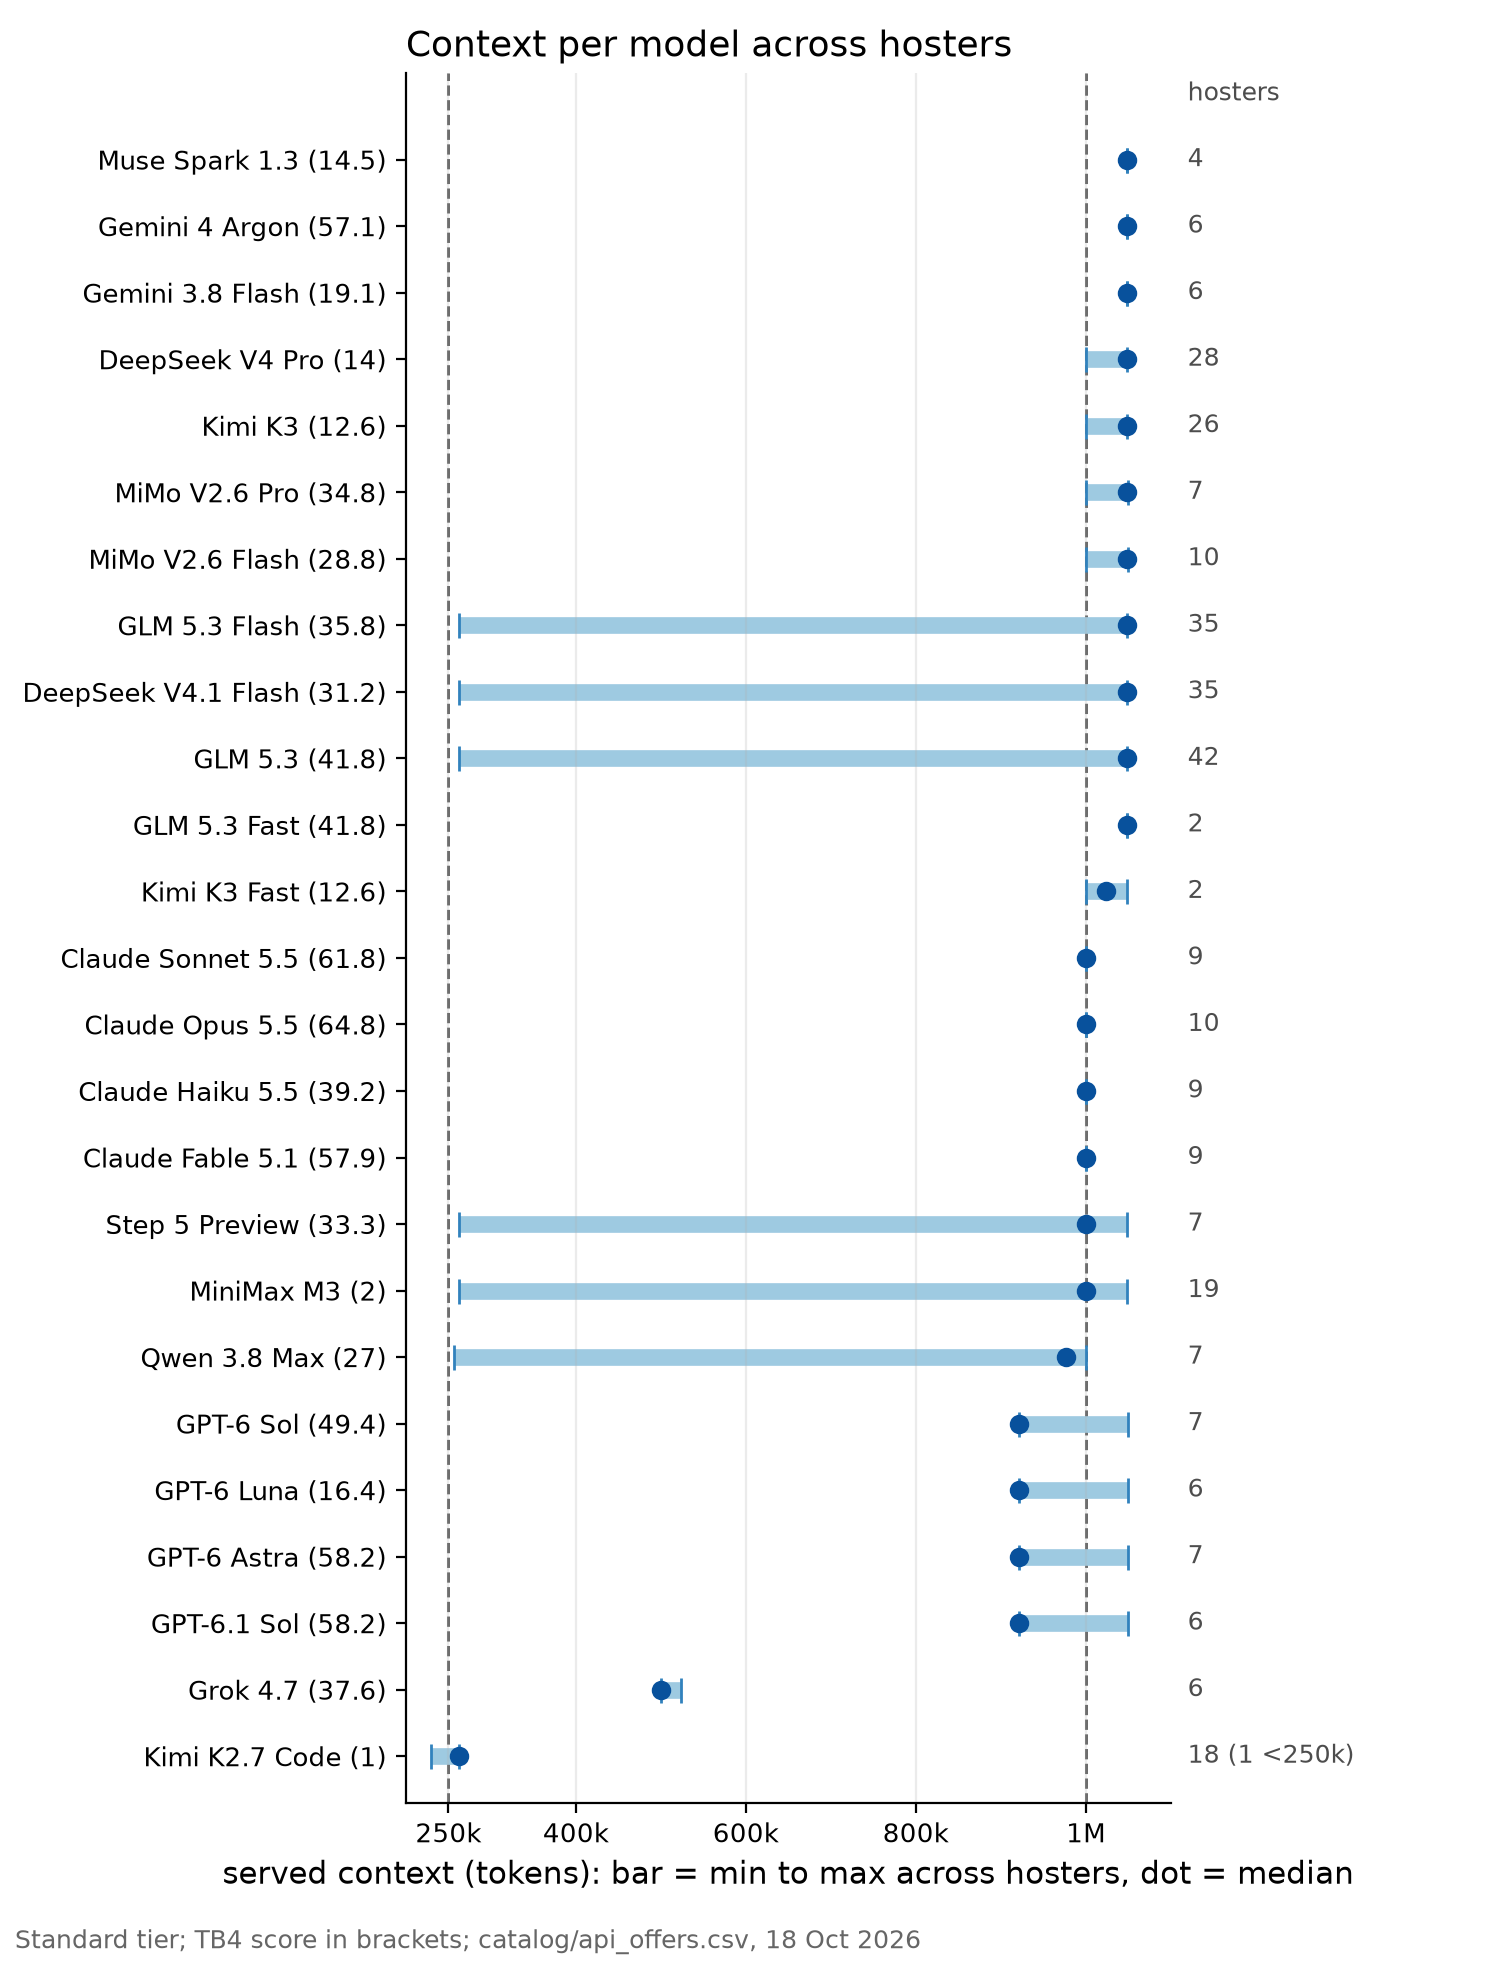
Context offered per model. Most current models reach 1M context at most hosters. Only a few offers fall below the 250k minimum this article uses. Only one offer falls below it (Kimi K2.7 Code at Alibaba, 229k). Several open-weight models bottom out at 262k at some hosters.
What drives request size. In our logs, session length more than the size of the codebase. Five of our projects in the same month:
| Task type | Repository (tracked source) | Median request | Requests per session (median) |
|---|---|---|---|
| Agent left running for days | 0.3 MB | 508k | 2,139 |
| Long coding sessions | 4.7 MB | 464k | 965 |
| One session per task (code) | 3.2 MB | 288k | 51 |
| One session per task (code) | 37 MB | 244k | 29 |
| Documents and writing | 44 MB | 152k | 25 |
The largest requests come from the smallest repository, where one session runs for thousands of turns. The largest repository has small requests and short sessions. A coding agent reads only the files it needs. What fills the context is how long the session runs.
So estimate your need from how you work:
- Long autonomous sessions (agents left running for hours, long debugging, multi-hour refactoring): requests grow to 500k and beyond. Plan for about 1M context, and for the long-prompt price where one applies.
- One session per task (a feature, a bug, a review): medians of 150k to 300k in our data. A 250k context covers most requests.
- Documentation, writing, small scripts: mostly below 250k. Nearly every offer in this report fits.
How the models compare on benchmarks
Terminal-Bench 4.0 runs an agent through real terminal tasks. For each entry it publishes the agent harness, the tokens one full run used and the cost of that run. Cost per run in the table is tokens per run times the cheapest offer's price at our mix.
| Model | Weights | TB4 score | Tokens per run | USD per 1M at our mix (maker) | USD per run at our mix (cheapest offer) |
|---|---|---|---|---|---|
| Claude Opus 5.5 | closed | 64.8% | 8.0 B | 0.334 | 2,674 |
| Claude Sonnet 5.5 | closed | 61.8% | 19.4 B | 0.167 | 3,243 |
| GPT-6.1 Sol | closed | 58.2% | 1.5 B | 0.326 | 489 |
| GPT-6 Astra | closed | 58.2% | 1.5 B | 2.61 | 3,909 |
| Claude Fable 5.1 | closed | 57.9% | 2.7 B | 0.591 | 1,597 |
| Gemini 4 Argon | closed | 57.1% | not published | 0.157 (promotion until 30 Nov; list price from 1 Dec is about twice) | – |
| GPT-6 Sol | closed | 49.4% | 5.0 B | 0.521 | 2,606 |
| GLM 5.3 | open | 41.8% | 8.7 B | 0.291 (cheapest hoster 0.093) | 810 |
| Claude Haiku 5.5 | closed | 39.2% (vendor) | not published | 0.0662 | – |
| Grok 4.7 | closed | 37.6% | 5.5 B | 1.08 | 5,949 |
| GLM 5.3 Flash | open | 35.8% | 2.9 B | 0.0333 (cheapest hoster 0.0098) | 28 |
| MiMo V2.6 Pro | open | 34.8% | not published | 0.0141 | – |
| DeepSeek V4.1 Flash | open | 31.2% (vendor) | not published | 0.0071 (cheapest hoster 0.006) | – |
| MiMo V2.6 Flash | open | 28.8% (vendor) | not published | 0.00615 (cheapest hoster 0.0058) | – |
| Qwen 3.8 Max | closed | 27% | 3.0 B | 0.296 (cheapest hoster 0.24) | 733 |
| Gemini 3.8 Flash | closed | 19.1% | 17.2 B | 0.0954 | 1,641 |
| GPT-6 Luna | closed | 16.4% | 3.9 B | 0.0261 | 102 |
| DeepSeek V4 Pro | open | 14% | not published | 0.0387 | – |
| Kimi K3 | open | 12.6% | not published | 0.382 (cheapest hoster 0.2) | – |
| MiniMax M3 | open | 2% | not published | 0.067 (cheapest hoster 0.054) | – |
| Kimi K2.7 Code | open | 1% | not published | 0.212 (cheapest hoster 0.15) | – |
"(vendor)" marks a score the model maker reported, not one the leaderboard measured. On the leaderboard, Kimi K3 scores 12.6% and MiniMax M3 2.0%. Their makers report 88.3 and 66.0 on the older Terminal-Bench 2.1.
Three things stand out.
- The top is closed. Six closed models score between 57% and 65%. The best open model, GLM 5.3, scores 41.8%. That is close to Claude Fable 5 from June (44.5%).
- Tokens per task decide the cost per task. GPT-6.1 Sol and GPT-6 Astra both score 58.2%. But Sol costs an eighth as much per token. Sonnet 5.5 is cheaper per token than Opus 5.5 and still costs more per run. It uses 19.4 billion tokens against 8.0 billion.
- The leaderboard's own costs are higher. It reports USD 4.7k per run for Opus 5.5 and USD 0.6k for GPT-6.1 Sol. That is 1.8 times our figure for Opus 5.5 and 1.2 times for GPT-6.1 Sol. Your own cost depends on how much of your sessions the cache serves.
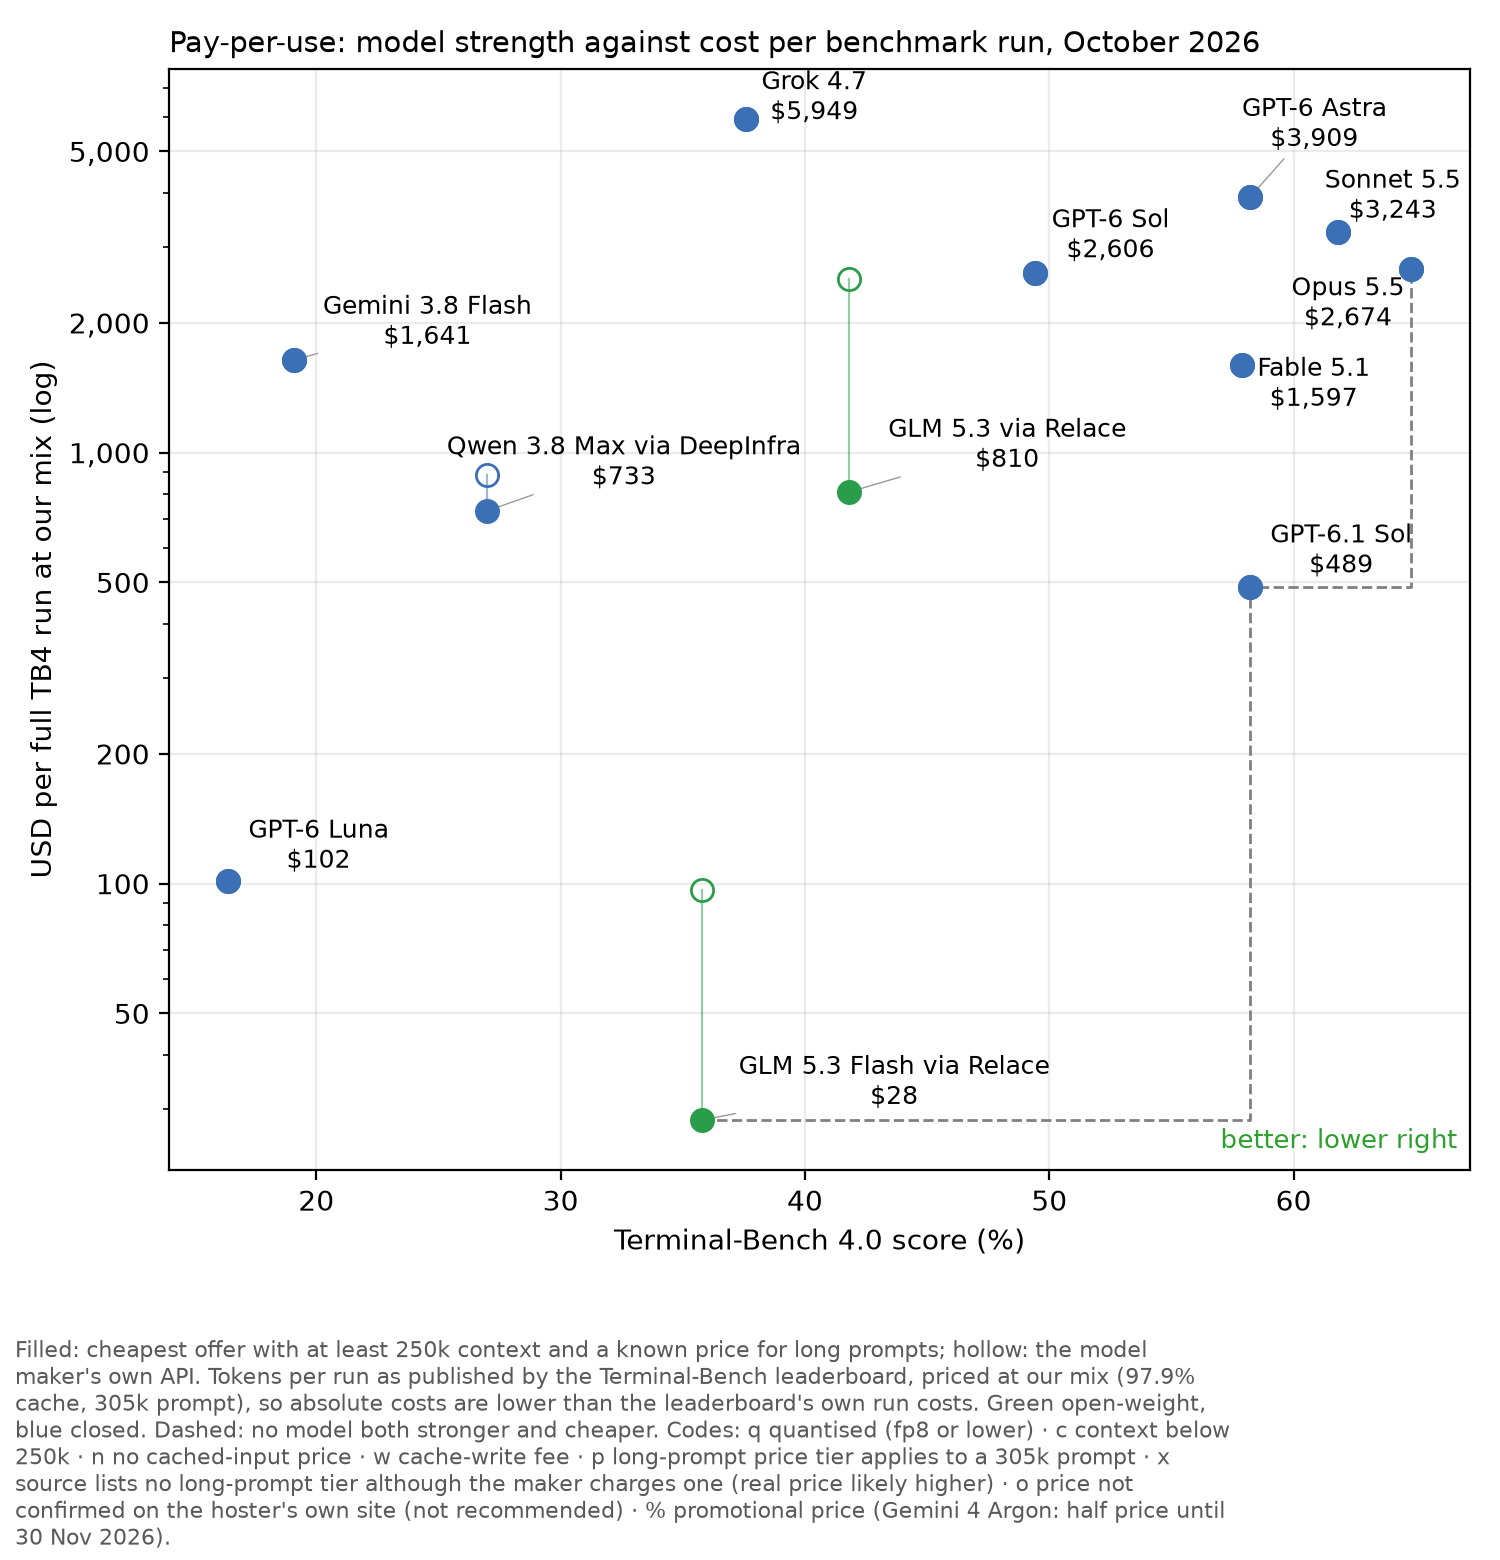
Filled dot: cheapest offer with at least 250k context and a known long-prompt price. Hollow dot: the model maker's own API. Only models whose tokens per run the leaderboard publishes.
Subscriptions: which plan for which need
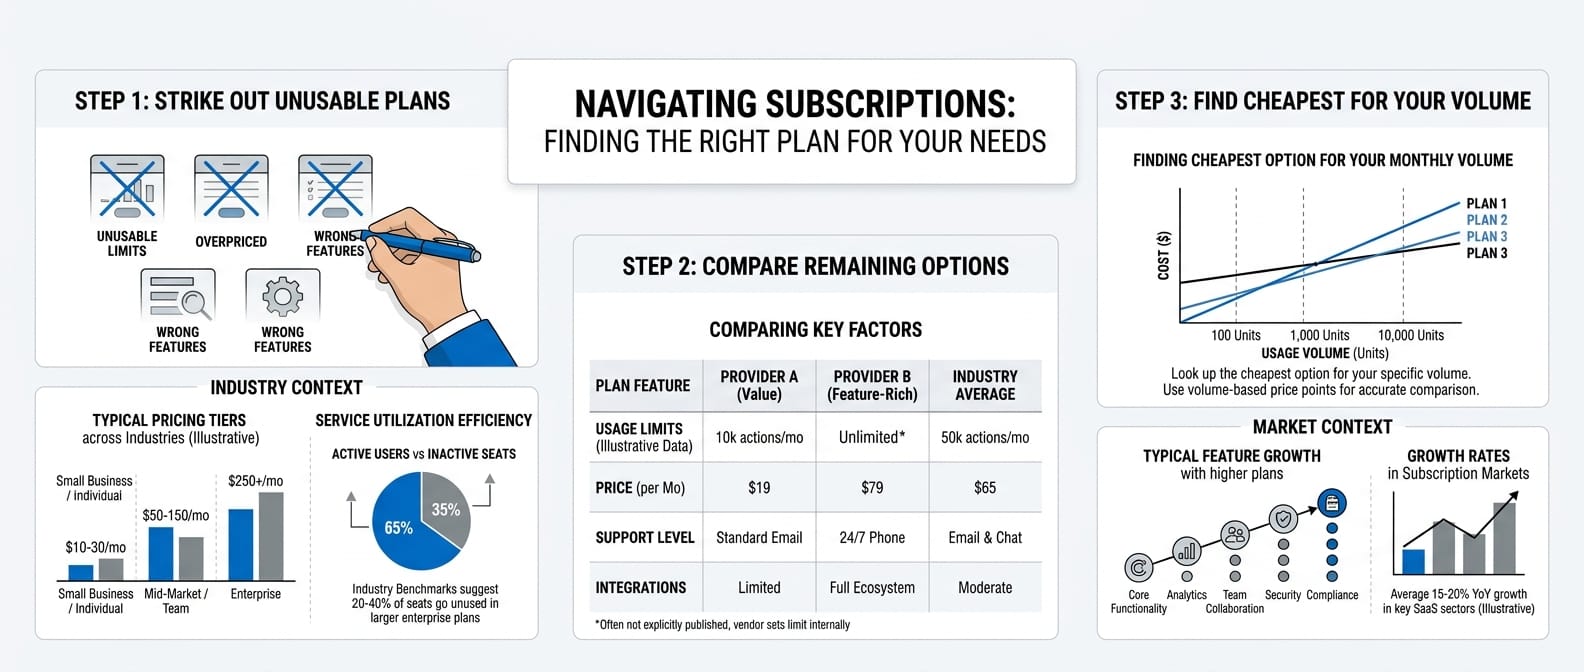
A subscription is a fixed monthly price for a usage limit. The vendor sets that limit and often does not publish it. The guide below has three steps. First, strike out what you cannot use. Second, see where the rest stand. Third, look up the cheapest option for your monthly volume.
Step 1: what you can use
✓ yes · ◐ partly, restricted or opt-out · ✗ no · ? not in sources. Flags read from each vendor's terms and pricing pages.
| Vendor | Largest individual tier | USD/month | Own agent / third-party tools | Automation, CI (continuous integration) | No training on your data | Context ≥ 250k | At the limit | Limit known |
|---|---|---|---|---|---|---|---|---|
| Anthropic | Claude Max 20x | 200 | ◐ | ✗ | ◐ | ✓ | pay more | measured |
| OpenAI | ChatGPT Pro 500 | 500 | ◐ | ◐ | ? | ✓ | pay more | measured |
| Google AI Ultra (20x) | 200 | ? | ? | ? | ✓ | pay more | published | |
| xAI | The X Subscription Ultra | 200 | ? | ✓ | ? | ✓ | pay more | published |
| Z.ai | GLM Coding Plan Max | 168 | ◐ | ✗ | ? | ✓ | stops | published |
| Moonshot AI | Ultra (USD) | 199 | ✓ | ✗ | ? | ✓ | pay more | measured |
| MiniMax | Token Plan Ultra | 120 | ? | ? | ? | ✓ | ? | published |
| Alibaba Cloud | Coding Plan Pro | 50 | ✓ | ✗ | ✓ | ◐ | stops | published |
| Xiaomi | Token Plan Individual Max | 100 | ✓ | ✗ | ? | ✓ | stops | published |
| BytePlus / Volcengine | Coding Plan Pro | 50 | ✓ | ✗ | ? | ✓ | stops | published |
| Tencent Cloud | TokenHub Token Plan Personal Max (intl, Singapore) | 103 | ◐ | ✗ | ? | ◐ | stops | published |
| Meta | Muse Code Maximum Usage | 200 | ✗ | ✓ | ◐ | ✓ | stops | published |
| Mistral | Pro | 14.99 | ✗ | ◐ | ◐ | ✗ | pay more | no |
| GitHub Copilot | Copilot Max | 100 | ◐ | ✓ | ◐ | ◐ | pay more | published |
| Cursor | Cursor Ultra (legacy) | 200 | ? | ✗ | ? | ? | pay more | measured |
| Factory | Droid Max | 200 | ? | ✓ | ✗ | ? | pay more | published |
| Devin Desktop (formerly Windsurf) | Pro | ? | ✗ | ◐ | ? | ? | pay more | no |
| Warp | Max | 200 | ? | ✓ | ◐ | ? | pay more | published |
| Command Code | Max 20× | 200 | ✓ | ✓ | ✓ | ◐ | pay more | published |
| ClinePass | ClinePass | 9.99 | ✓ | ✓ | ? | ✓ | ? | no |
| OpenCode | Go Plus | 40 | ✓ | ◐ | ✓ | ✓ | pay more | published |
| Atlas Cloud | $500 tier (unnamed) | 500 | ✓ | ✓ | ✓ | ? | pay more | published |
| Standard Compute | Scale | 2499 | ✓ | ✓ | ✓ | ? | pay more | published |
| Synthetic | Standard | ? | ✓ | ✓ | ✓ | ✓ | pay more | published |
| NanoGPT | Pro | 12 | ✓ | ◐ | ✓ | ◐ | pay more | published |
| Ollama Cloud | Max | 100 | ✓ | ◐ | ✓ | ✓ | pay more | published |
Two rules remove most plans if you run your own agent or automation. Anthropic's Claude plans forbid automation and limit use in third-party tools. Moonshot, Alibaba, BytePlus and Xiaomi allow third-party coding tools, Z.ai and Tencent partly. But they forbid scripted or unattended use. Training on your data is opt-out at Anthropic, OpenAI's Plus tier and GitHub Copilot. Most Chinese plans do not state it.
Step 2: where each plan stands
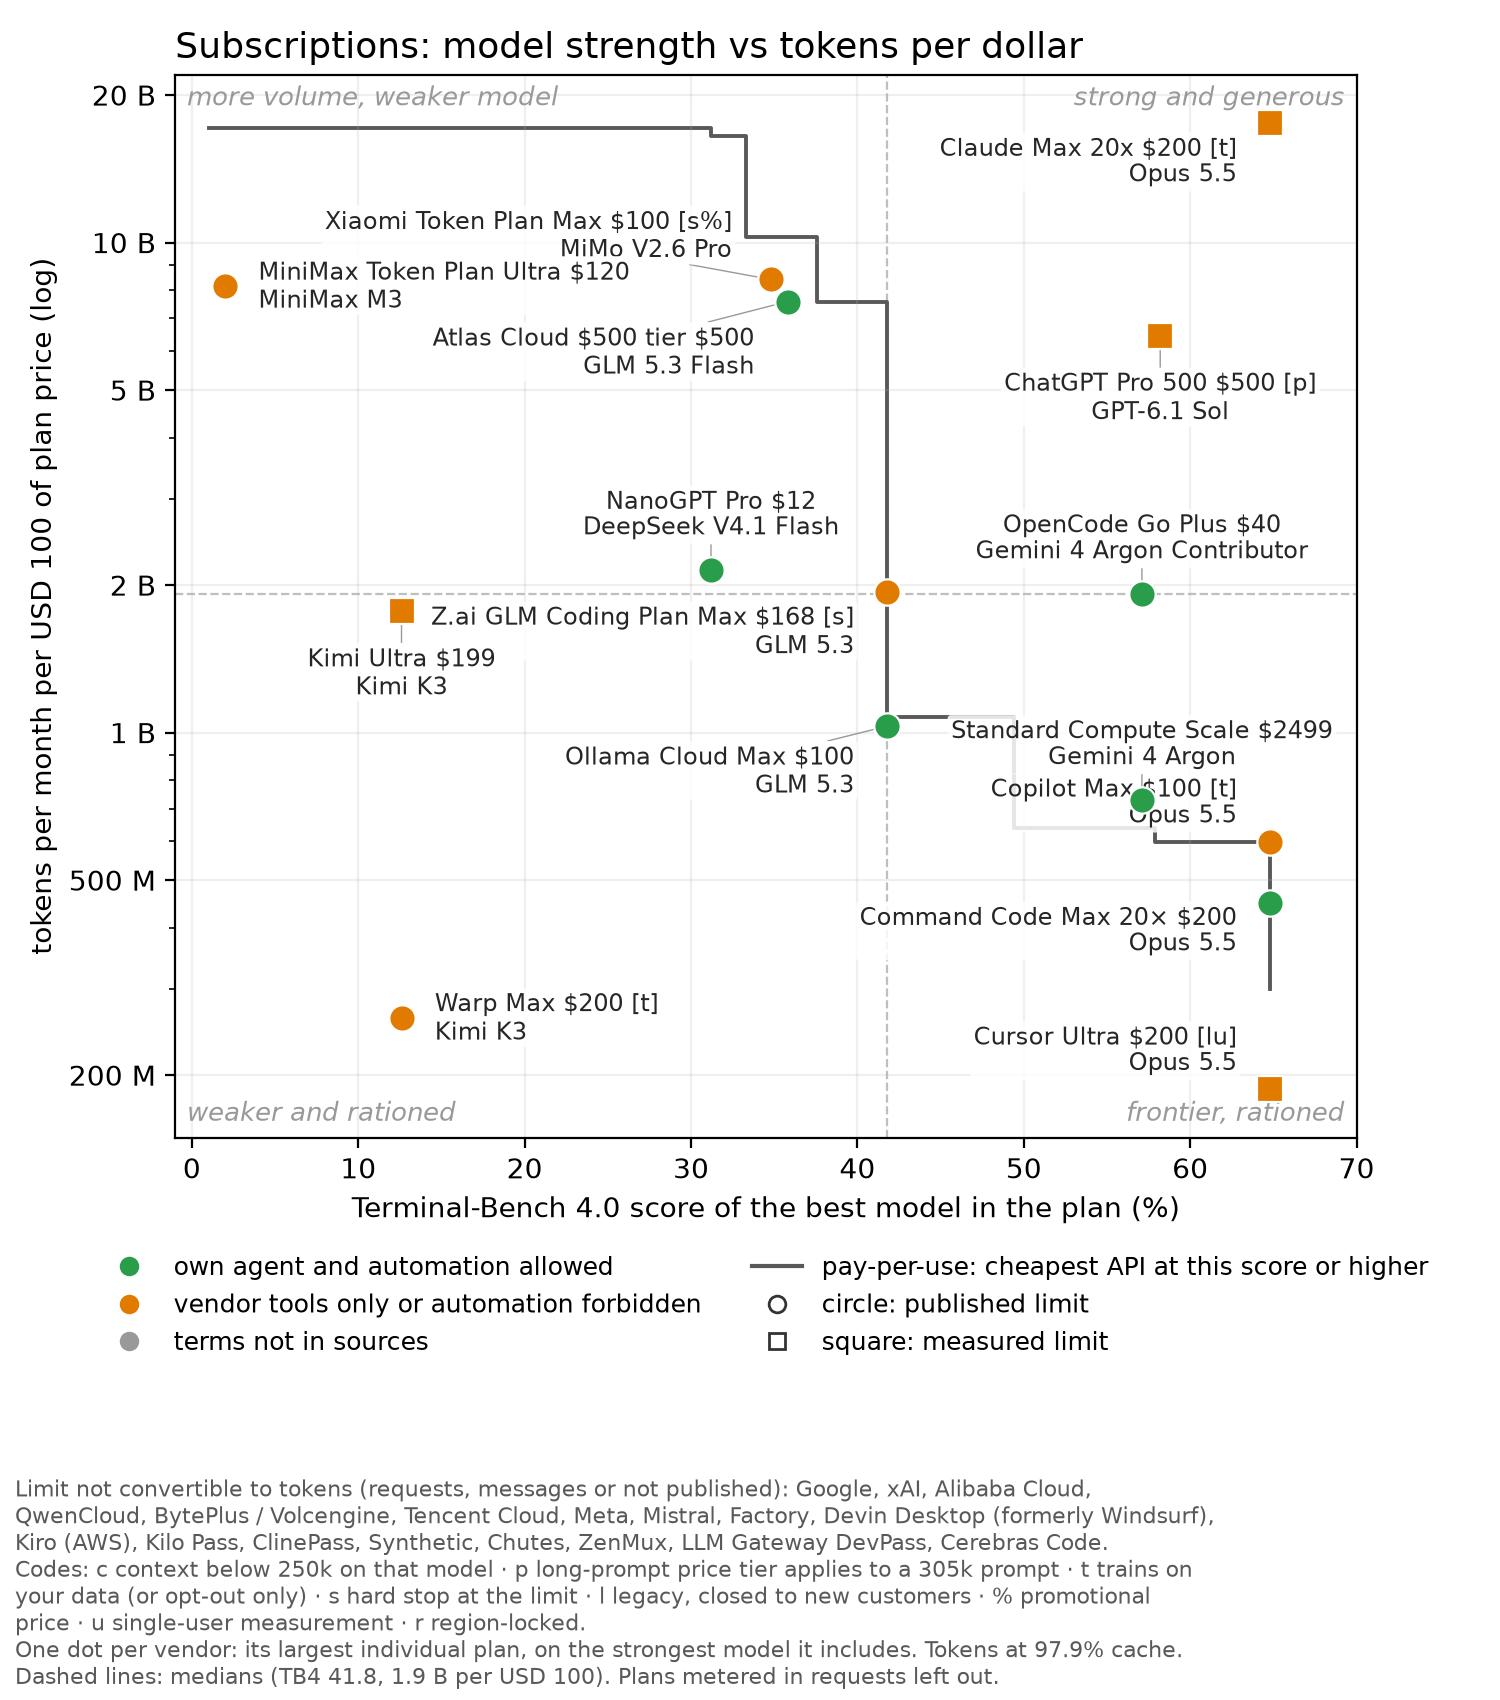
One dot per vendor: its largest individual plan, on the strongest model it includes. Tokens at 97.9% cache. The line shows the cheapest pay-per-use offer at that score or higher. A plan below the line buys fewer tokens per dollar than the API.
Only two plans reach the upper right: Claude Max 20x on Opus 5.5 and ChatGPT Pro 500 on GPT-6.1 Sol. Neither is meant for your own automation. Every plan that allows your own agent (green) sits close to the pay-per-use line or below it.
Plan against pay-per-use
The dot plot shows whether a plan buys more tokens than the same money spent on the API, for the same model. That is the first thing a buyer wants to know. The multiple says how many times as many tokens the plan buys.
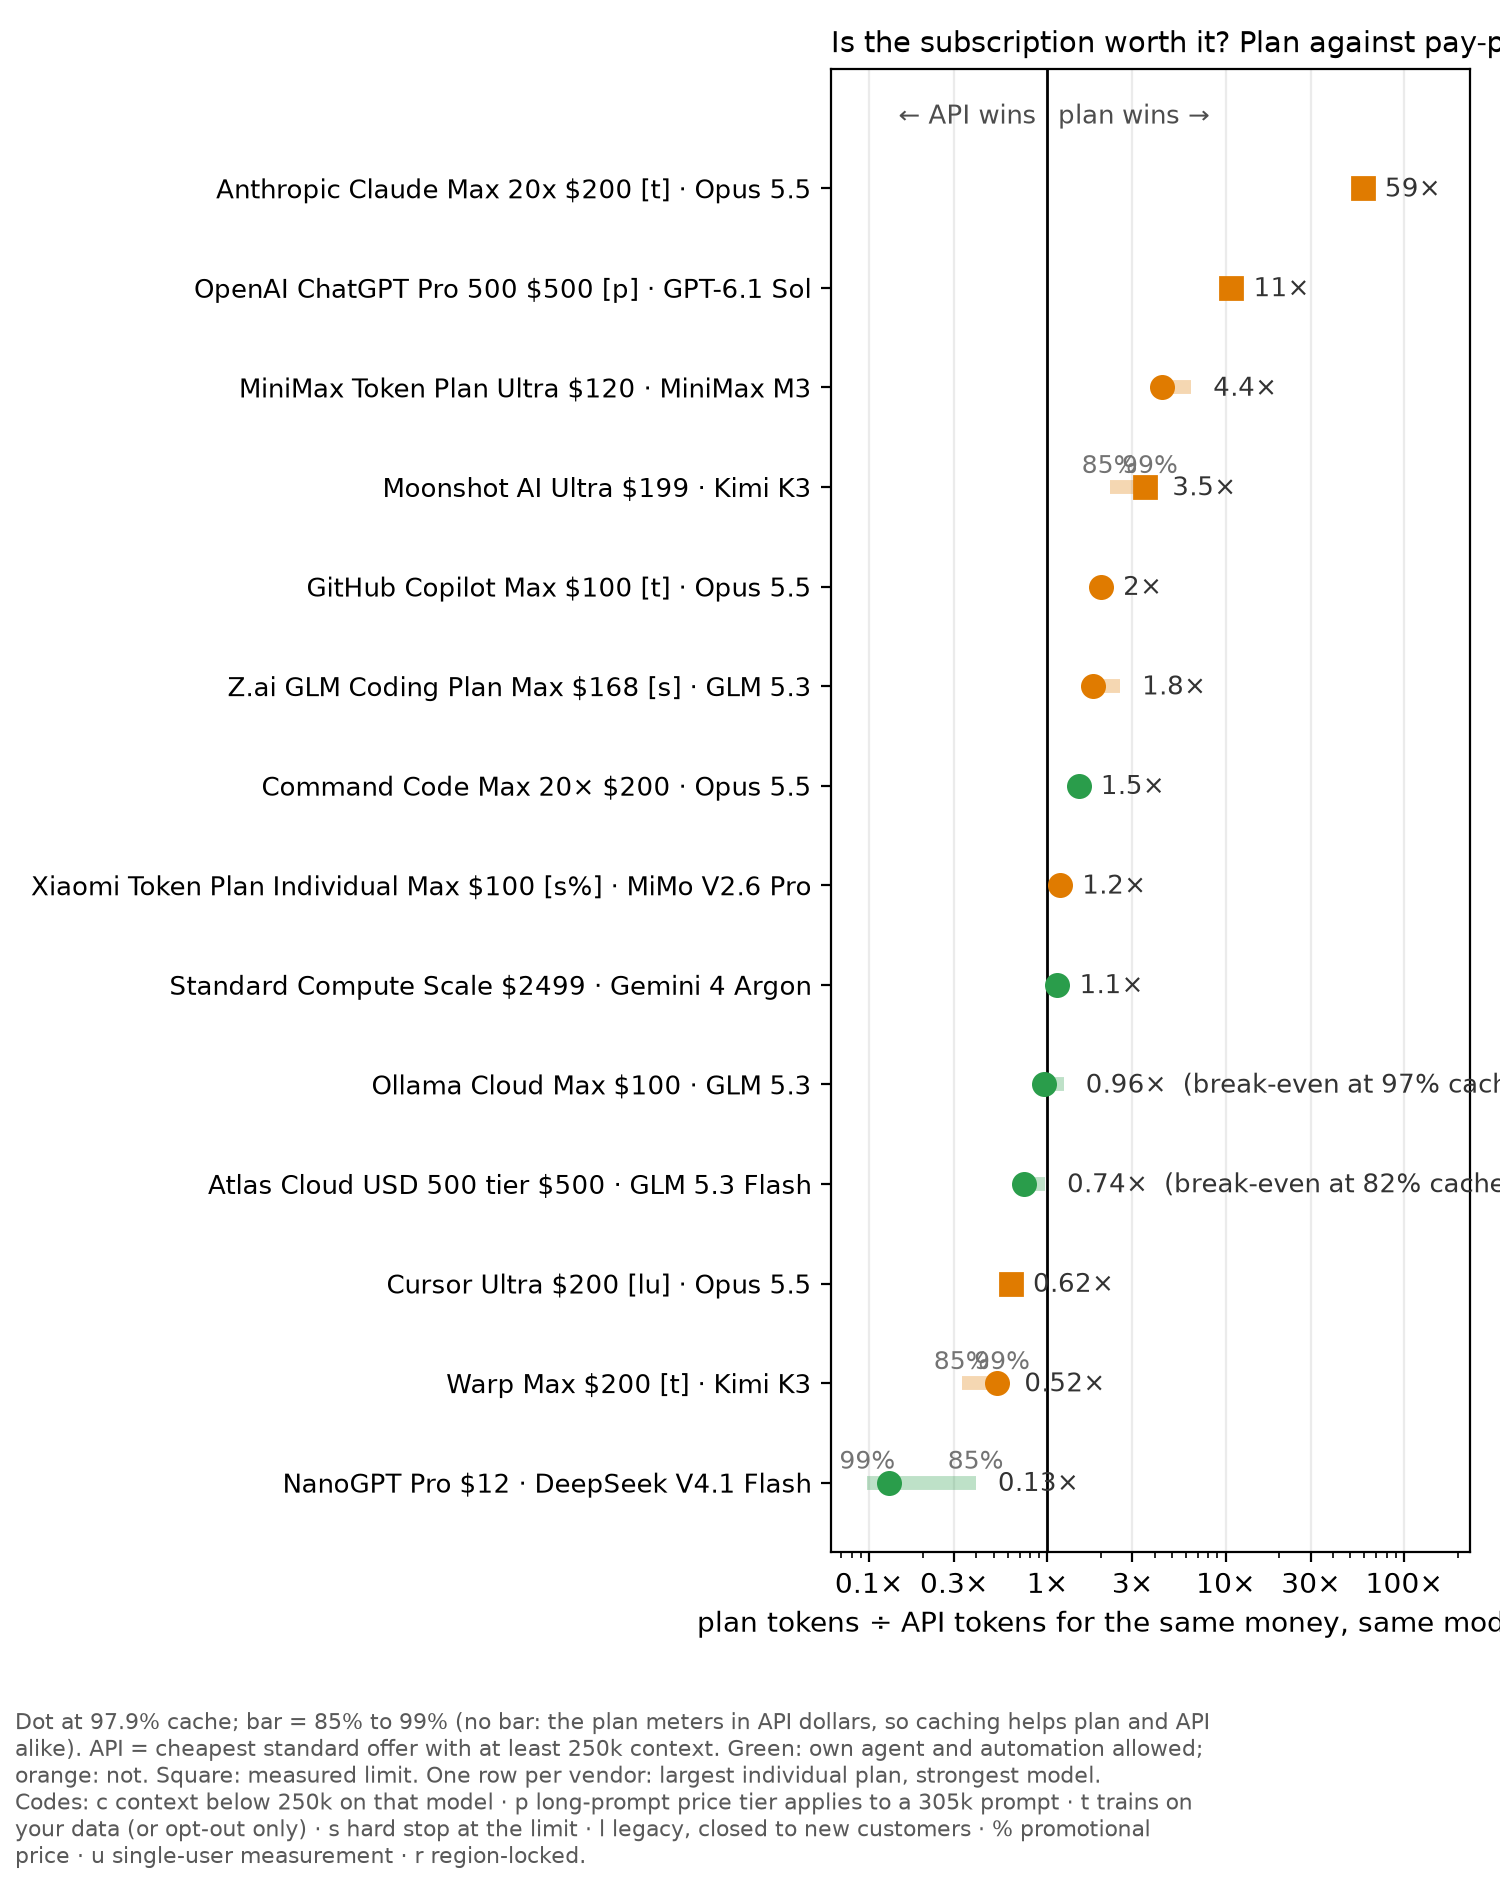
| Plan | Price | Model | Plan ÷ API, same money | Tokens a month at our mix |
|---|---|---|---|---|
| Claude Max 20x | USD 200 | Opus 5.5 | 59x | 35 B |
| ChatGPT Pro 500 | USD 500 | GPT-6.1 Sol | 11x | 32 B |
| MiniMax Token Plan Ultra | USD 120 | MiniMax M3 | 4.4x (6.4x at 85% cache, 4.2x at 99%) | 9.8 B |
| Kimi Ultra | USD 199 | Kimi K3 | 3.5x (2.2x at 85% cache, 3.8x at 99%) | 3.5 B |
| Copilot Max | USD 100 | Opus 5.5 | 2x | 0.6 B |
| Z.ai GLM Coding Plan Max | USD 168 | GLM 5.3 | 1.8x (2.6x at 85% cache, 1.7x at 99%) | 3.2 B |
| Command Code Max 20× | USD 200 | Opus 5.5 | 1.5x | 0.9 B |
| Xiaomi Token Plan Max | USD 100 | MiMo V2.6 Pro | 1.2x | 8.4 B |
| Standard Compute Scale | USD 2,499 | Gemini 4 Argon | 1.1x | 18 B |
| Ollama Cloud Max | USD 100 | GLM 5.3 | 0.96x (1.2x at 85% cache, 0.92x at 99%) | 1 B |
| Atlas Cloud $500 tier | USD 500 | GLM 5.3 Flash | 0.74x (0.97x at 85% cache, 0.71x at 99%) | 38 B |
| Cursor Ultra | USD 200 | Opus 5.5 | 0.62x | 0.37 B |
| Warp Max | USD 200 | Kimi K3 | 0.52x (0.33x at 85% cache, 0.56x at 99%) | 0.52 B |
| NanoGPT Pro | USD 12 | DeepSeek V4.1 Flash | 0.13x (0.4x at 85% cache, 0.098x at 99%) | 0.26 B |
For most plans the cache rate barely changes this ranking. They meter usage in API dollars, so caching makes plan and API cheaper alike. It matters for plans that count raw tokens. MiniMax's lead shrinks from 6.4x at 85% cache to 4.2x at 99%. NanoGPT falls from 0.4x to 0.1x.
Step 3: the finder
The finder picks the cheapest single option, plan or API, for a monthly token volume (rows) and a minimum TB4 score (columns). Each cell holds one option. Combining several plans is not modelled.
Any plan:
| Tokens per month | TB4 ≥ 30 | TB4 ≥ 40 | TB4 ≥ 50 | TB4 ≥ 55 | TB4 ≥ 60 | TB4 ≥ 64 |
|---|---|---|---|---|---|---|
| 0.1 B | API Cloudflare, USD 1 (DeepSeek V4.1 Flash) | API Relace, USD 9 (GLM 5.3) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) |
| 0.3 B | Command Code Go, USD 1 (DeepSeek V4.1 Flash) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) |
| 1 B | Command Code Go, USD 1 (DeepSeek V4.1 Flash) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * [t], USD 20 (Opus 5.5) |
| 3 B | API Cloudflare, USD 18 (DeepSeek V4.1 Flash) | Anthropic Claude Pro * ? [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * ? [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * ? [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * ? [t], USD 20 (Opus 5.5) | Anthropic Claude Pro * ? [t], USD 20 (Opus 5.5) |
| 10 B | API Cloudflare, USD 60 (DeepSeek V4.1 Flash) | Anthropic Claude Max 5x * ? [t], USD 100 (Opus 5.5) | Anthropic Claude Max 5x * ? [t], USD 100 (Opus 5.5) | Anthropic Claude Max 5x * ? [t], USD 100 (Opus 5.5) | Anthropic Claude Max 5x * ? [t], USD 100 (Opus 5.5) | Anthropic Claude Max 5x * ? [t], USD 100 (Opus 5.5) |
| 37.23 B (our use) | Anthropic Claude Max 20x * [t], USD 200 (Sonnet 5.5) | Anthropic Claude Max 20x * [t], USD 200 (Sonnet 5.5) | Anthropic Claude Max 20x * [t], USD 200 (Sonnet 5.5) | Anthropic Claude Max 20x * [t], USD 200 (Sonnet 5.5) | Anthropic Claude Max 20x * [t], USD 200 (Sonnet 5.5) | API Anthropic, USD 12,446 (Opus 5.5) |
Only plans that allow your own agent and automation:
| Tokens per month | TB4 ≥ 30 | TB4 ≥ 40 | TB4 ≥ 50 | TB4 ≥ 55 | TB4 ≥ 60 | TB4 ≥ 64 |
|---|---|---|---|---|---|---|
| 0.1 B | API Cloudflare, USD 1 (DeepSeek V4.1 Flash) | API Relace, USD 9 (GLM 5.3) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | API Anthropic, USD 33 (Opus 5.5) |
| 0.3 B | API Cloudflare, USD 2 (DeepSeek V4.1 Flash) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code GOAT, USD 10 (Sonnet 5.5) | Command Code Max 10×, USD 100 (Opus 5.5) |
| 1 B | API Cloudflare, USD 6 (DeepSeek V4.1 Flash) | API Relace, USD 93 (GLM 5.3) | API Google AI Studio [%], USD 157 (Gemini 4 Argon) | API Google AI Studio [%], USD 157 (Gemini 4 Argon) | API Anthropic, USD 167 (Sonnet 5.5) | API Anthropic, USD 334 (Opus 5.5) |
| 3 B | API Cloudflare, USD 18 (DeepSeek V4.1 Flash) | API Relace, USD 279 (GLM 5.3) | API Google AI Studio [%], USD 470 (Gemini 4 Argon) | API Google AI Studio [%], USD 470 (Gemini 4 Argon) | API Anthropic, USD 501 (Sonnet 5.5) | API Anthropic, USD 1,003 (Opus 5.5) |
| 10 B | API Cloudflare, USD 60 (DeepSeek V4.1 Flash) | API Relace, USD 931 (GLM 5.3) | API Google AI Studio [%], USD 1,567 (Gemini 4 Argon) | API Google AI Studio [%], USD 1,567 (Gemini 4 Argon) | API Anthropic, USD 1,671 (Sonnet 5.5) | API Anthropic, USD 3,343 (Opus 5.5) |
| 37.23 B (our use) | API Cloudflare, USD 225 (DeepSeek V4.1 Flash) | API Relace, USD 3,466 (GLM 5.3) | API Google AI Studio [%], USD 5,833 (Gemini 4 Argon) | API Google AI Studio [%], USD 5,833 (Gemini 4 Argon) | API Anthropic, USD 6,223 (Sonnet 5.5) | API Anthropic, USD 12,446 (Opus 5.5) |
Marks: * = limit measured by a tracker or analyst. ? = another reading of the same plan falls short of this volume. [t] = trains on your data, or opt-out only. [s] = hard stop at the limit. [%] = promotional price (Gemini 4 Argon, half price until 30 November 2026). API = cheapest standard offer with at least 250k context, at a price the hoster's own site does not contradict. The row for our own use (37.23 B) counts only offers with about 1M context, because our requests reach 971k.
Compare the two tables. With any plan allowed, Claude covers 1 to 10 billion tokens a month on Opus 5.5 for USD 20 to 100. Our 37 billion fit Max 20x (USD 200) with Sonnet 5.5. With your own agent and automation, the same volumes at a score of 60% or more cost USD 167 to 12,446 a month on the API. Only one subscription wins cells in the second table: Command Code's GOAT plan (USD 10), for small volumes on Sonnet 5.5.
Pay-per-use: which hoster for which model
Pay-per-use means you buy tokens from a hoster. That can be the model maker's own API, a cloud such as Bedrock or Vertex, or a gateway that resells many hosters through one API. For closed models the choice is short. Every cloud and gateway charges the maker's list price. For open-weight models, dozens of hosters compete, and prices really differ.
Hoster against maker
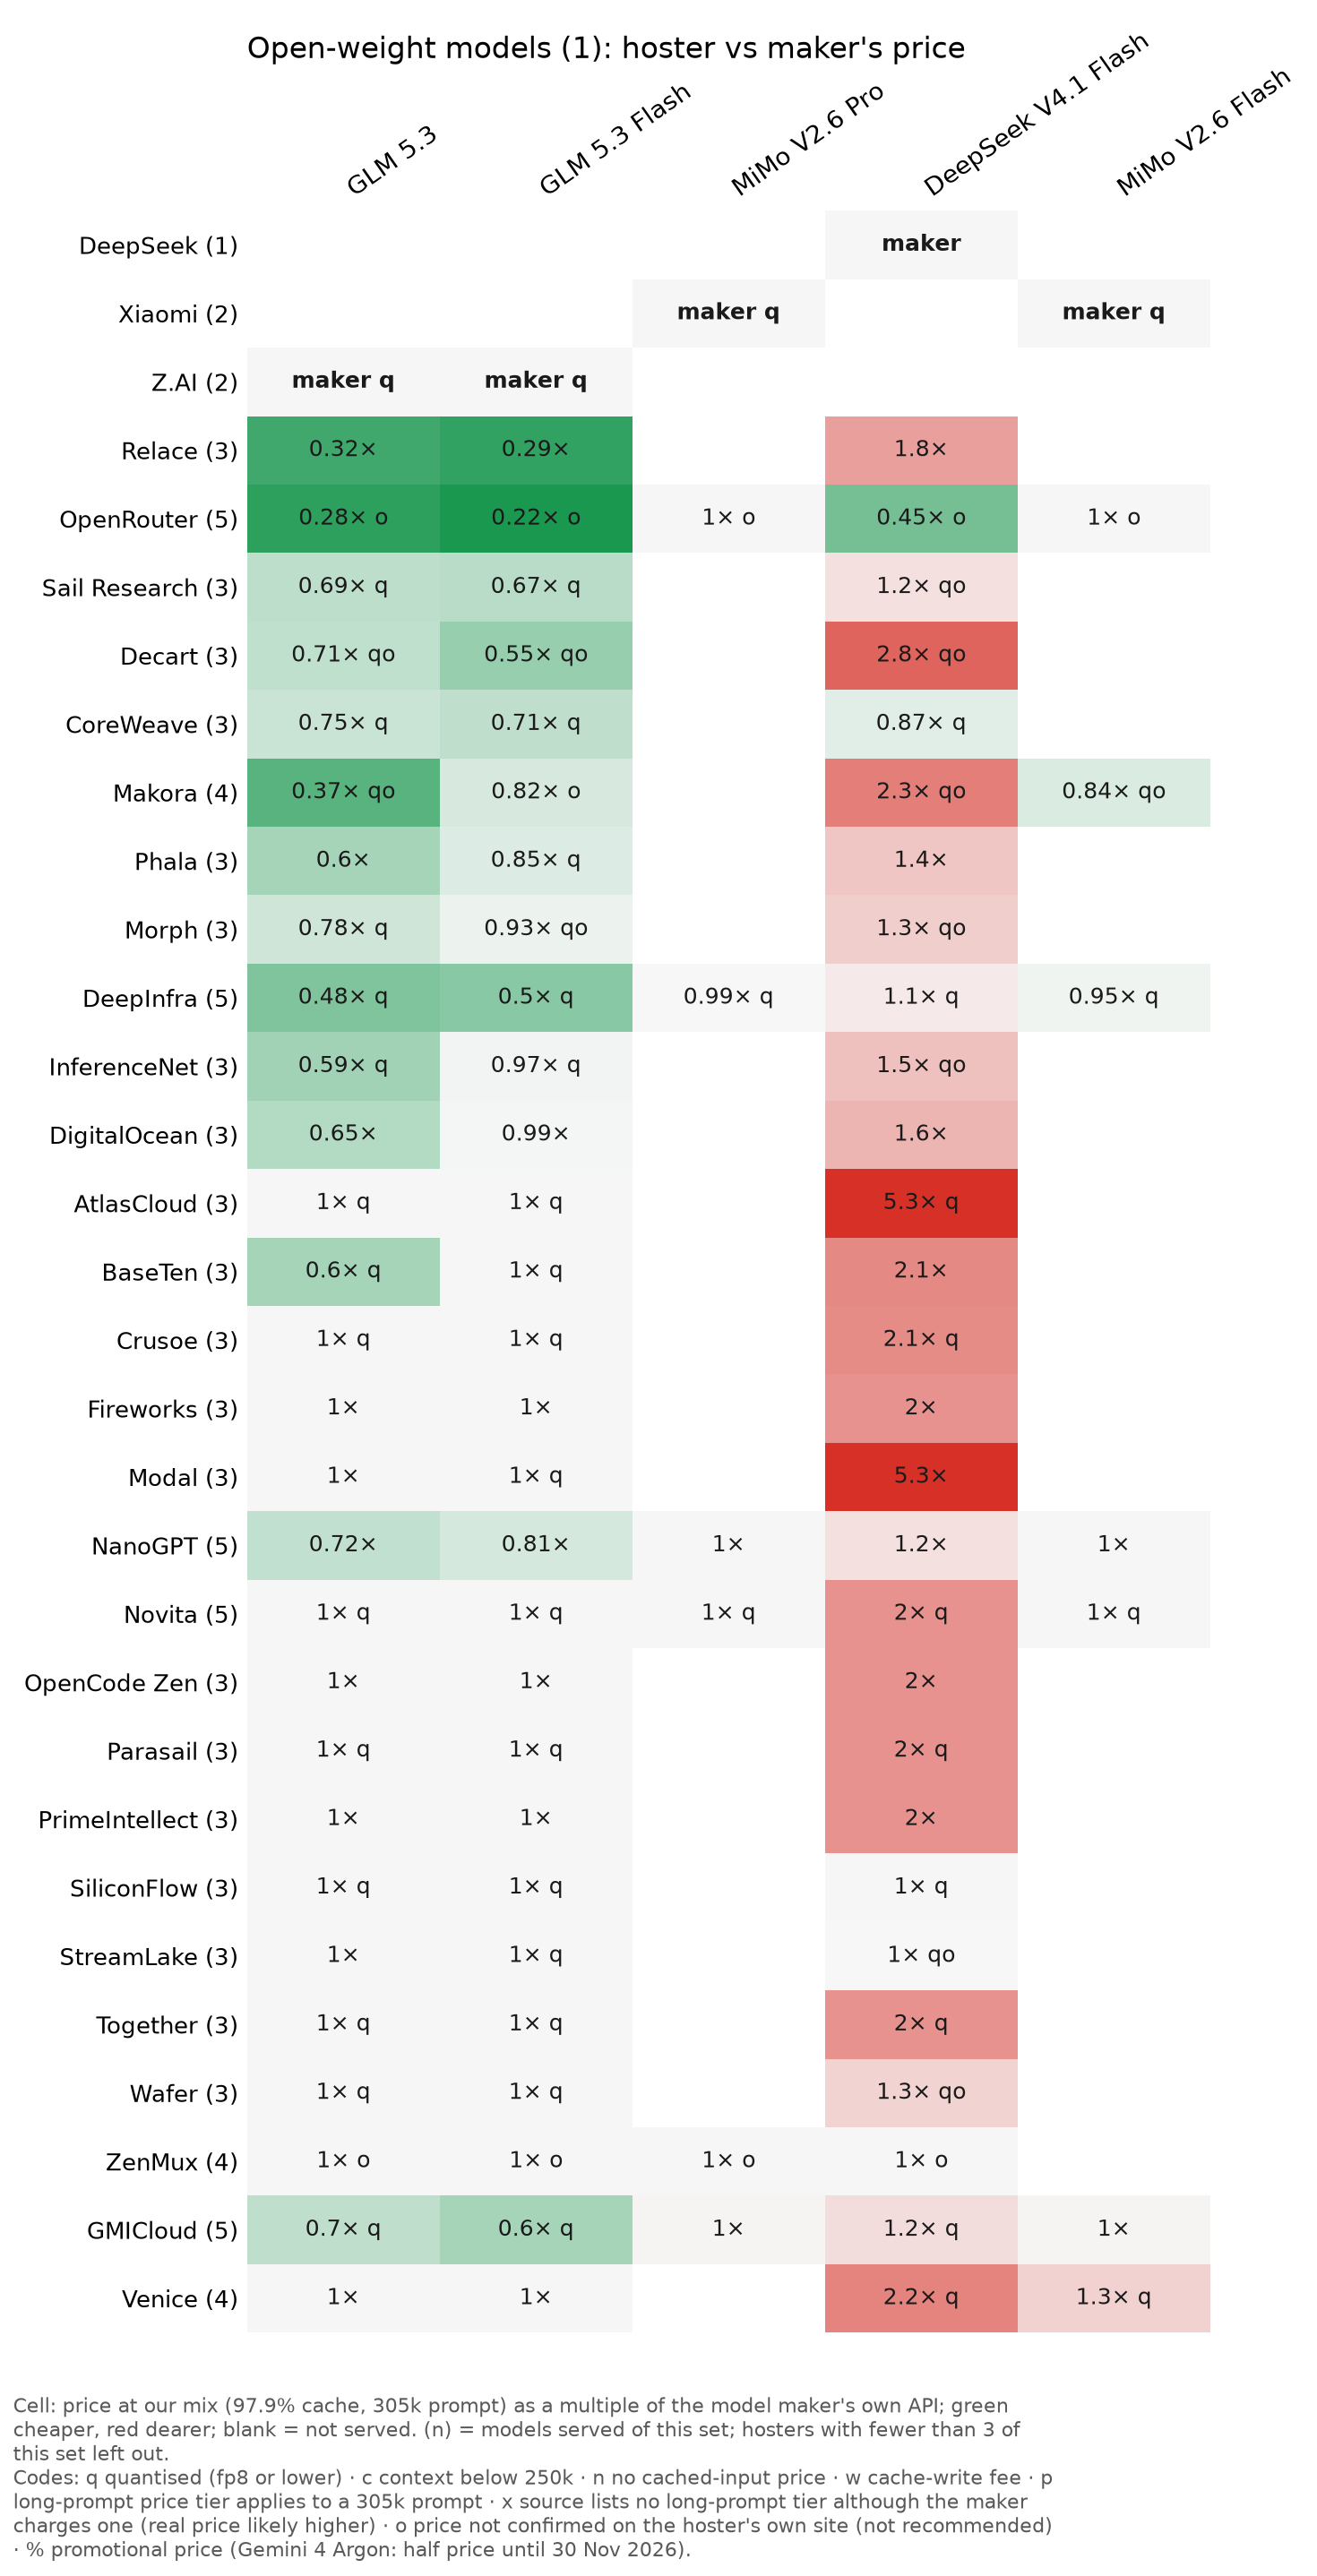
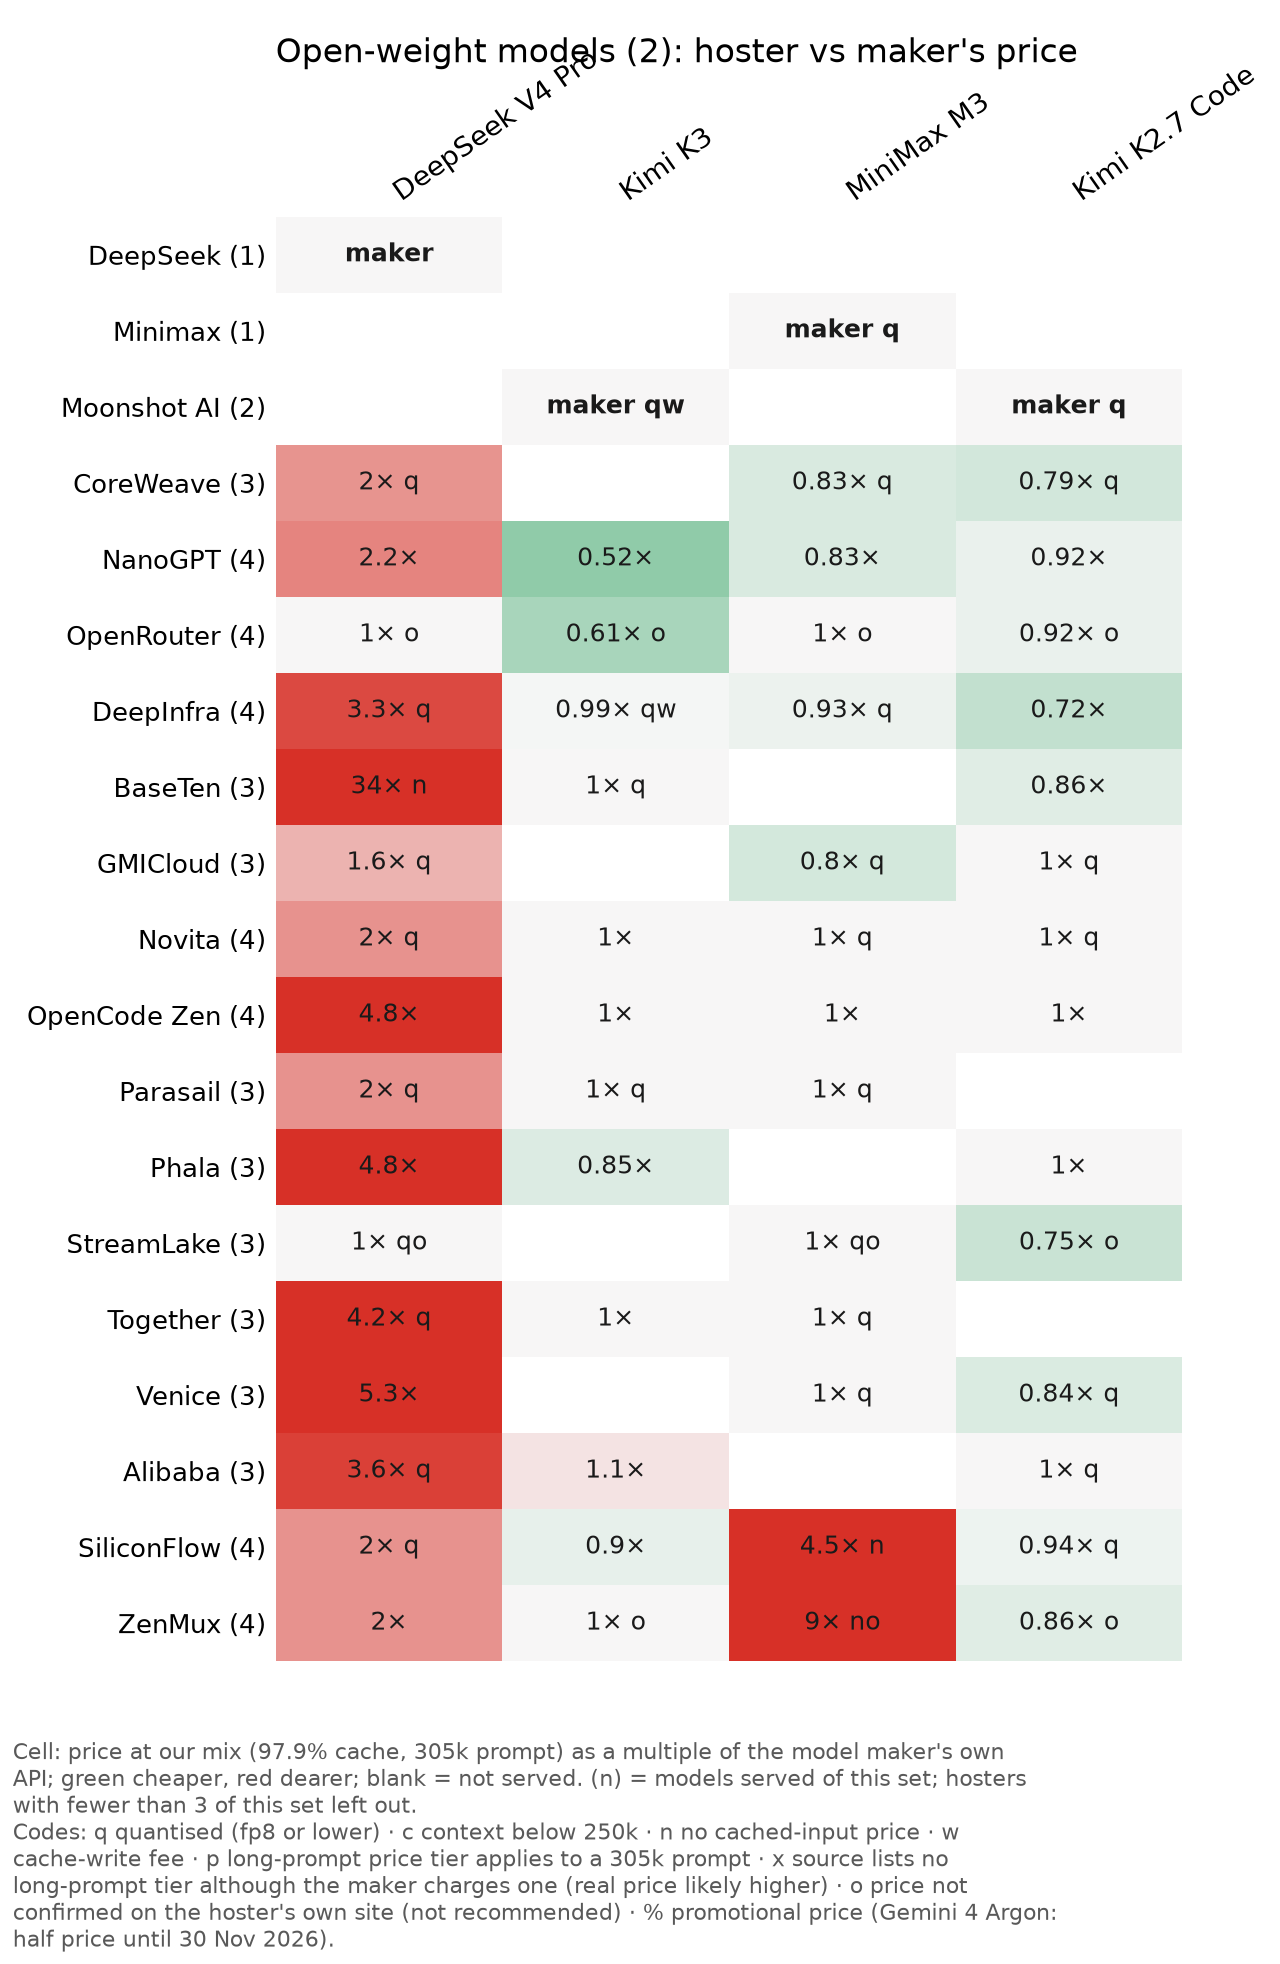
Each cell: the hoster's price at our mix as a multiple of the model maker's own API. Codes: q = quantised, the hoster runs the model at reduced numeric precision (8-bit floating point, fp8, or lower) to cut serving cost. c = context below 250k. n = no cached-input price. w = cache-write fee. p = long-prompt tier. x = the source lists no long-prompt tier although the maker charges one. o = price not confirmed on the hoster's own site.
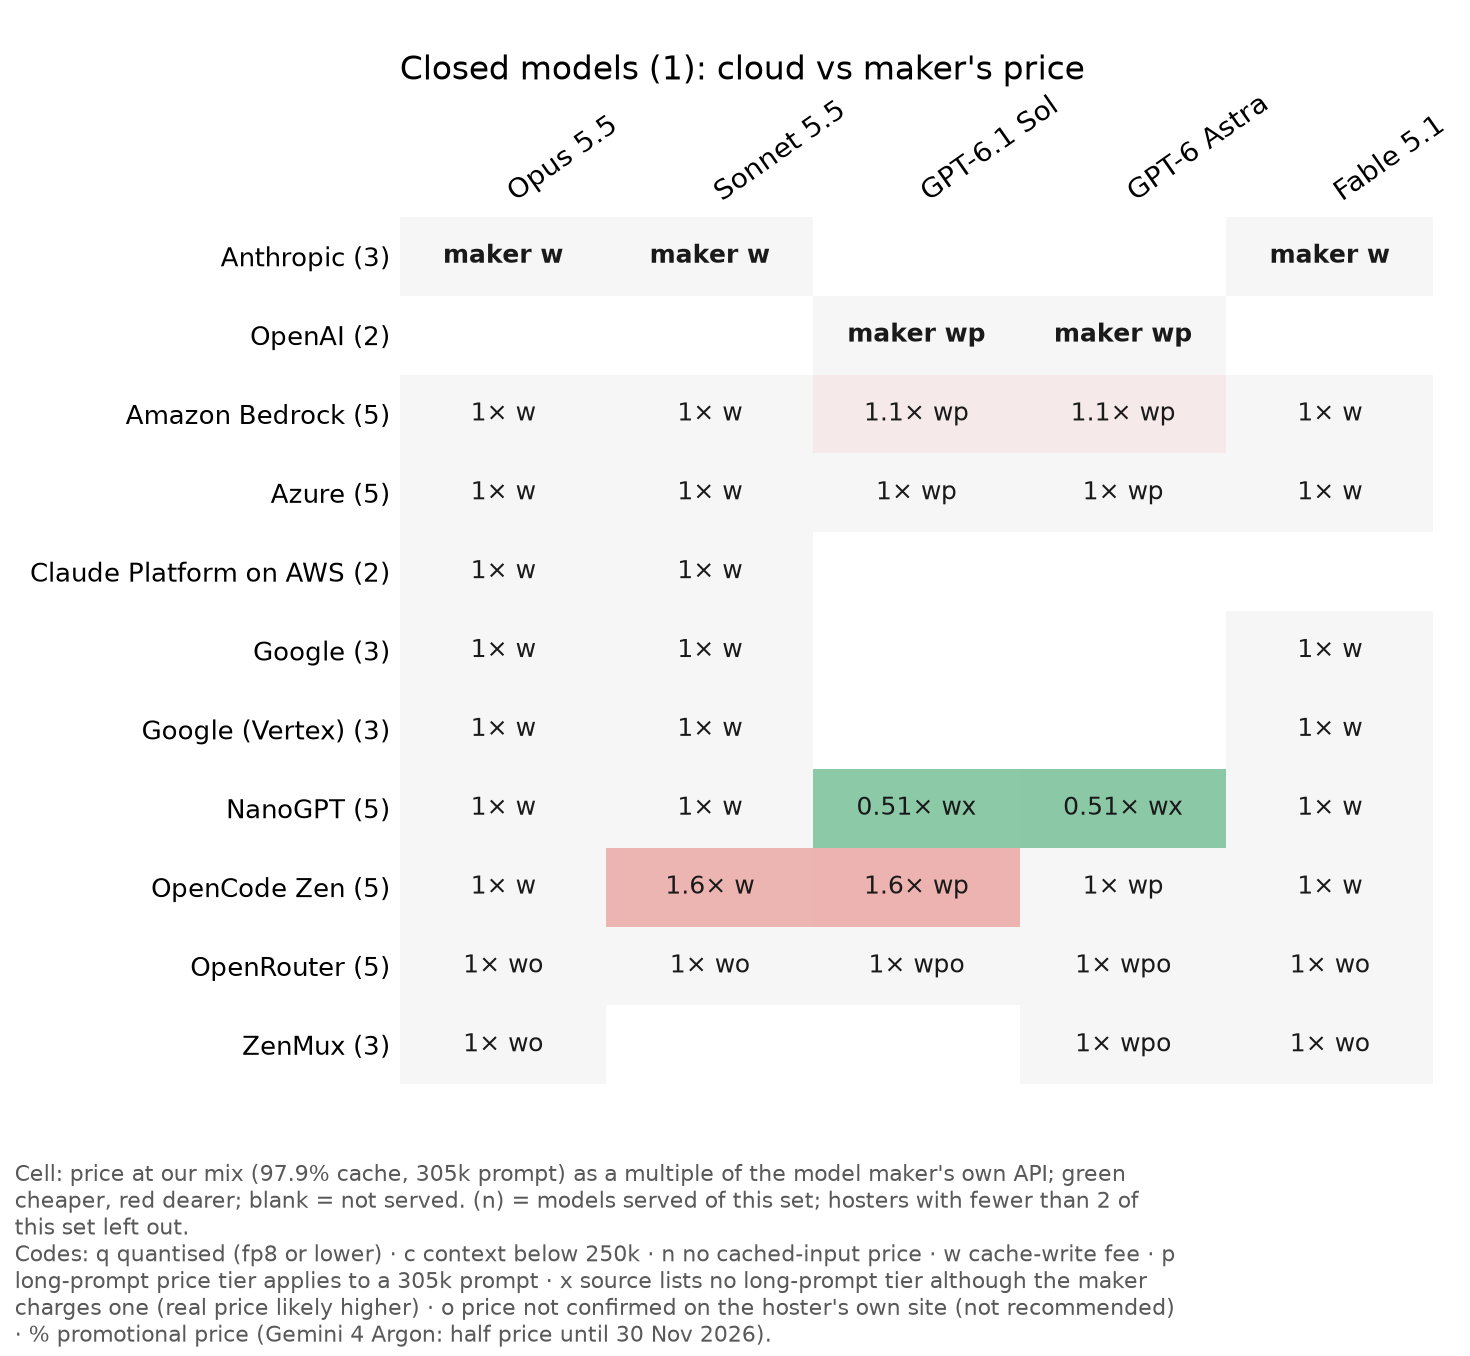
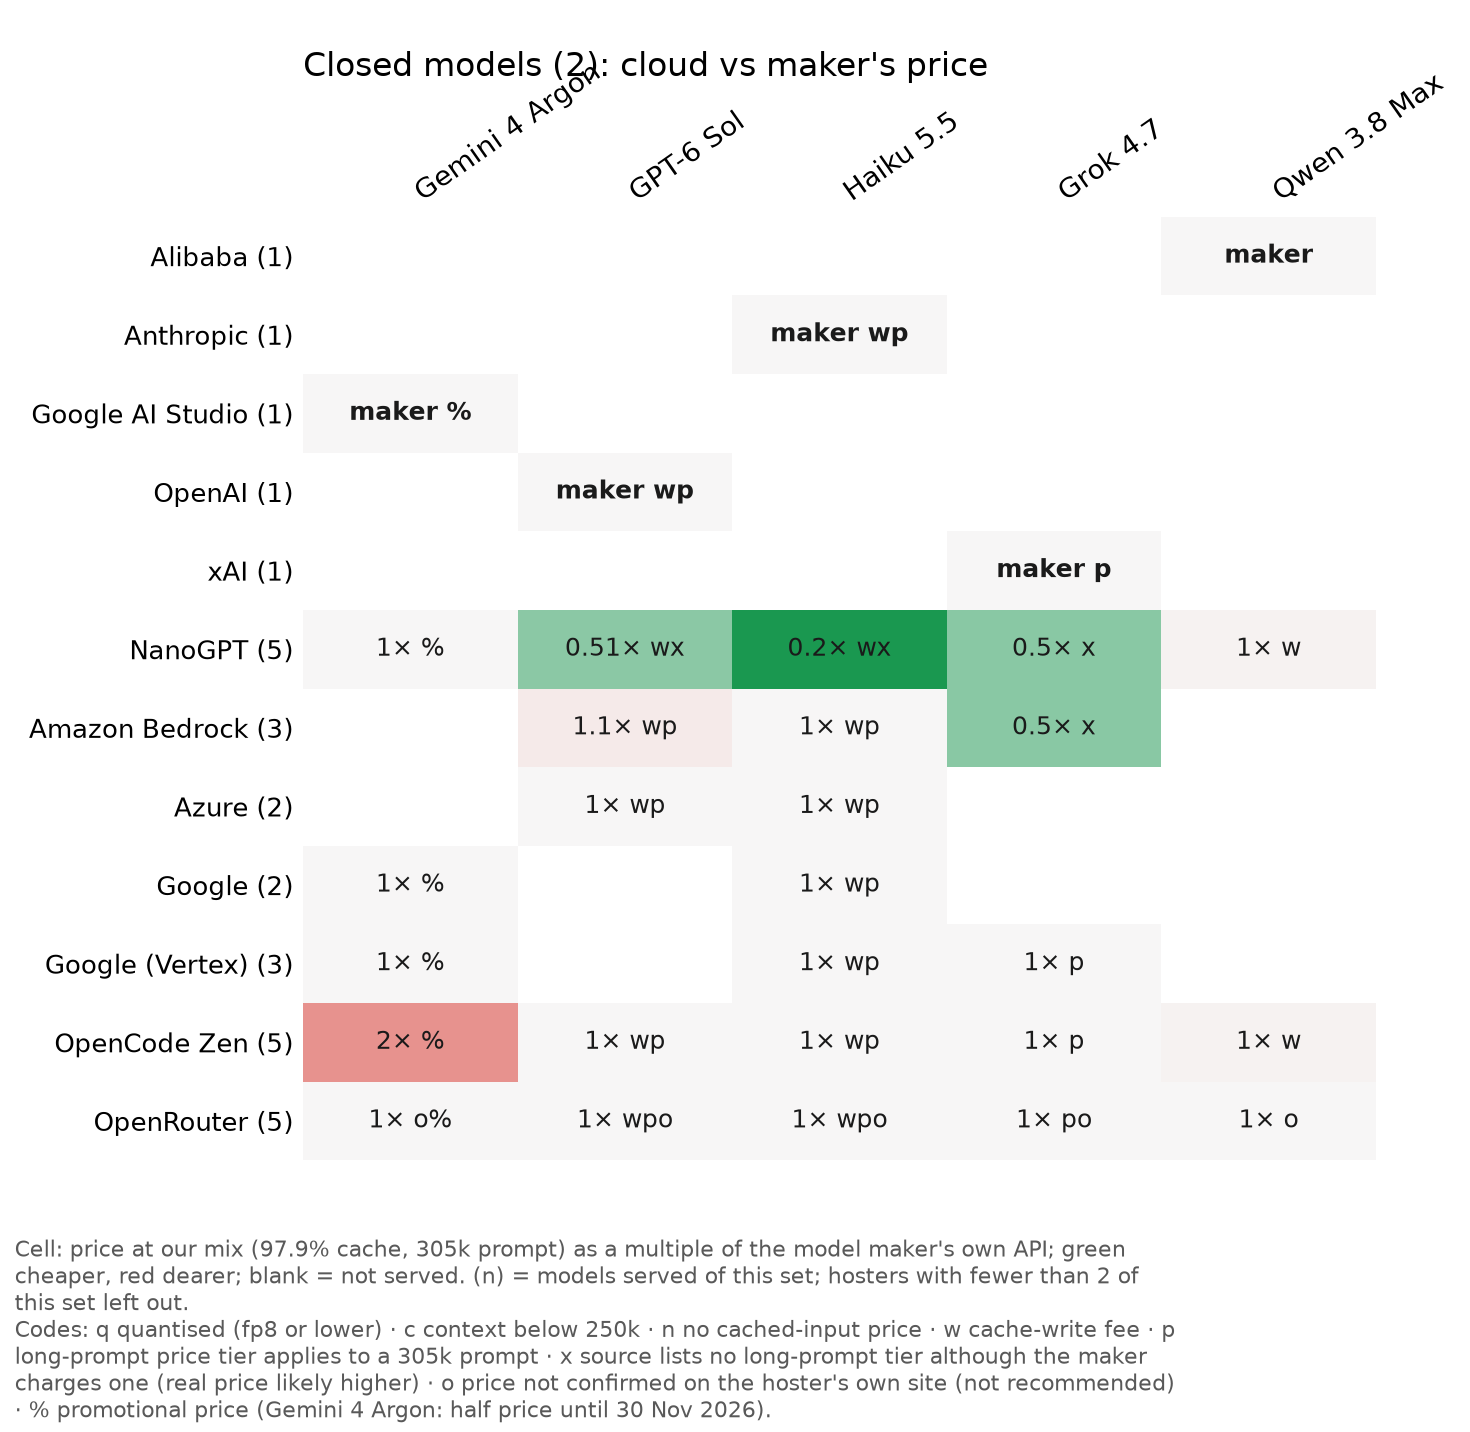
The data problem behind these charts. Most hoster prices in public datasets come from OpenRouter's endpoint list or from models.dev. Both are aggregators that collect prices from many hosters. We took 19 hosters that looked at least 40% cheaper than the maker and checked their own websites:
| Result | Hosters |
|---|---|
| Own site matches | BaseTen, Mistral, Amazon Bedrock (Grok 4.7), Near AI (input and output) |
| Own site shows a higher price | Baidu, InferenceNet, Morph, Reka, Sail Research, StreamLake, Wafer, Relace, ZenMux, Crusoe (cached input) |
| Model not on the hoster's own price list | Decart, DekaLLM, Makora, OpenInference |
| Page not reachable | Tenstorrent (login only) |
Most differences follow one pattern: the input price on OpenRouter is about a tenth of the hoster's own. Baidu lists DeepSeek V4 Pro input at USD 1.69 per 1M tokens on its own page, against USD 0.177 on OpenRouter. Morph lists GLM 5.3 at USD 1.19 against USD 0.086. The charts use the hosters' own prices. Prices the hoster's own site contradicts, or that we could not confirm for a hoster caught with a wrong price, carry the code o. This article never recommends them.
After that correction, these are the cheapest verified offers at our mix. A multiple below 1x means cheaper than the maker's own API:
| Model | Cheapest verified | Next | Maker's own API, USD per 1M at our mix |
|---|---|---|---|
| GLM 5.3 | Relace 0.32x | DeepInfra 0.48x (q) | 0.291 |
| GLM 5.3 Flash | Relace 0.29x | DeepInfra 0.5x (q) | 0.0333 |
| DeepSeek V4.1 Flash | Cloudflare 0.85x, aggregator data only | CoreWeave 0.87x (q), aggregator data only | 0.0071 |
| DeepSeek V4 Pro | the maker, 1x (cheapest reseller GMICloud 1.6x (q), aggregator data only) | Relace 1.6x (q) | 0.0387 |
| Kimi K3 | NanoGPT 0.52x, aggregator data only | Chutes 0.62x (q), aggregator data only | 0.382 |
| Kimi K2.7 Code | DeepInfra 0.72x, aggregator data only | CoreWeave 0.79x (q), aggregator data only | 0.212 |
| MiniMax M3 | GMICloud 0.8x (q), aggregator data only | CoreWeave 0.83x (q), aggregator data only | 0.067 |
| Qwen 3.8 Max | DeepInfra 0.82x | Fireworks 1x | 0.296 |
Rows marked "aggregator data only" come from OpenRouter or models.dev and are not confirmed on the hoster's own page. They sit within 40% of the maker's price. Our check covered offers more than 40% below it, so these are not checked against the hoster's site.
DeepSeek is the exception worth knowing. Its own API is the cheapest, or close to it, for both of its models. Almost every reseller charges more, up to 5.5 times as much.
Hosters ranked
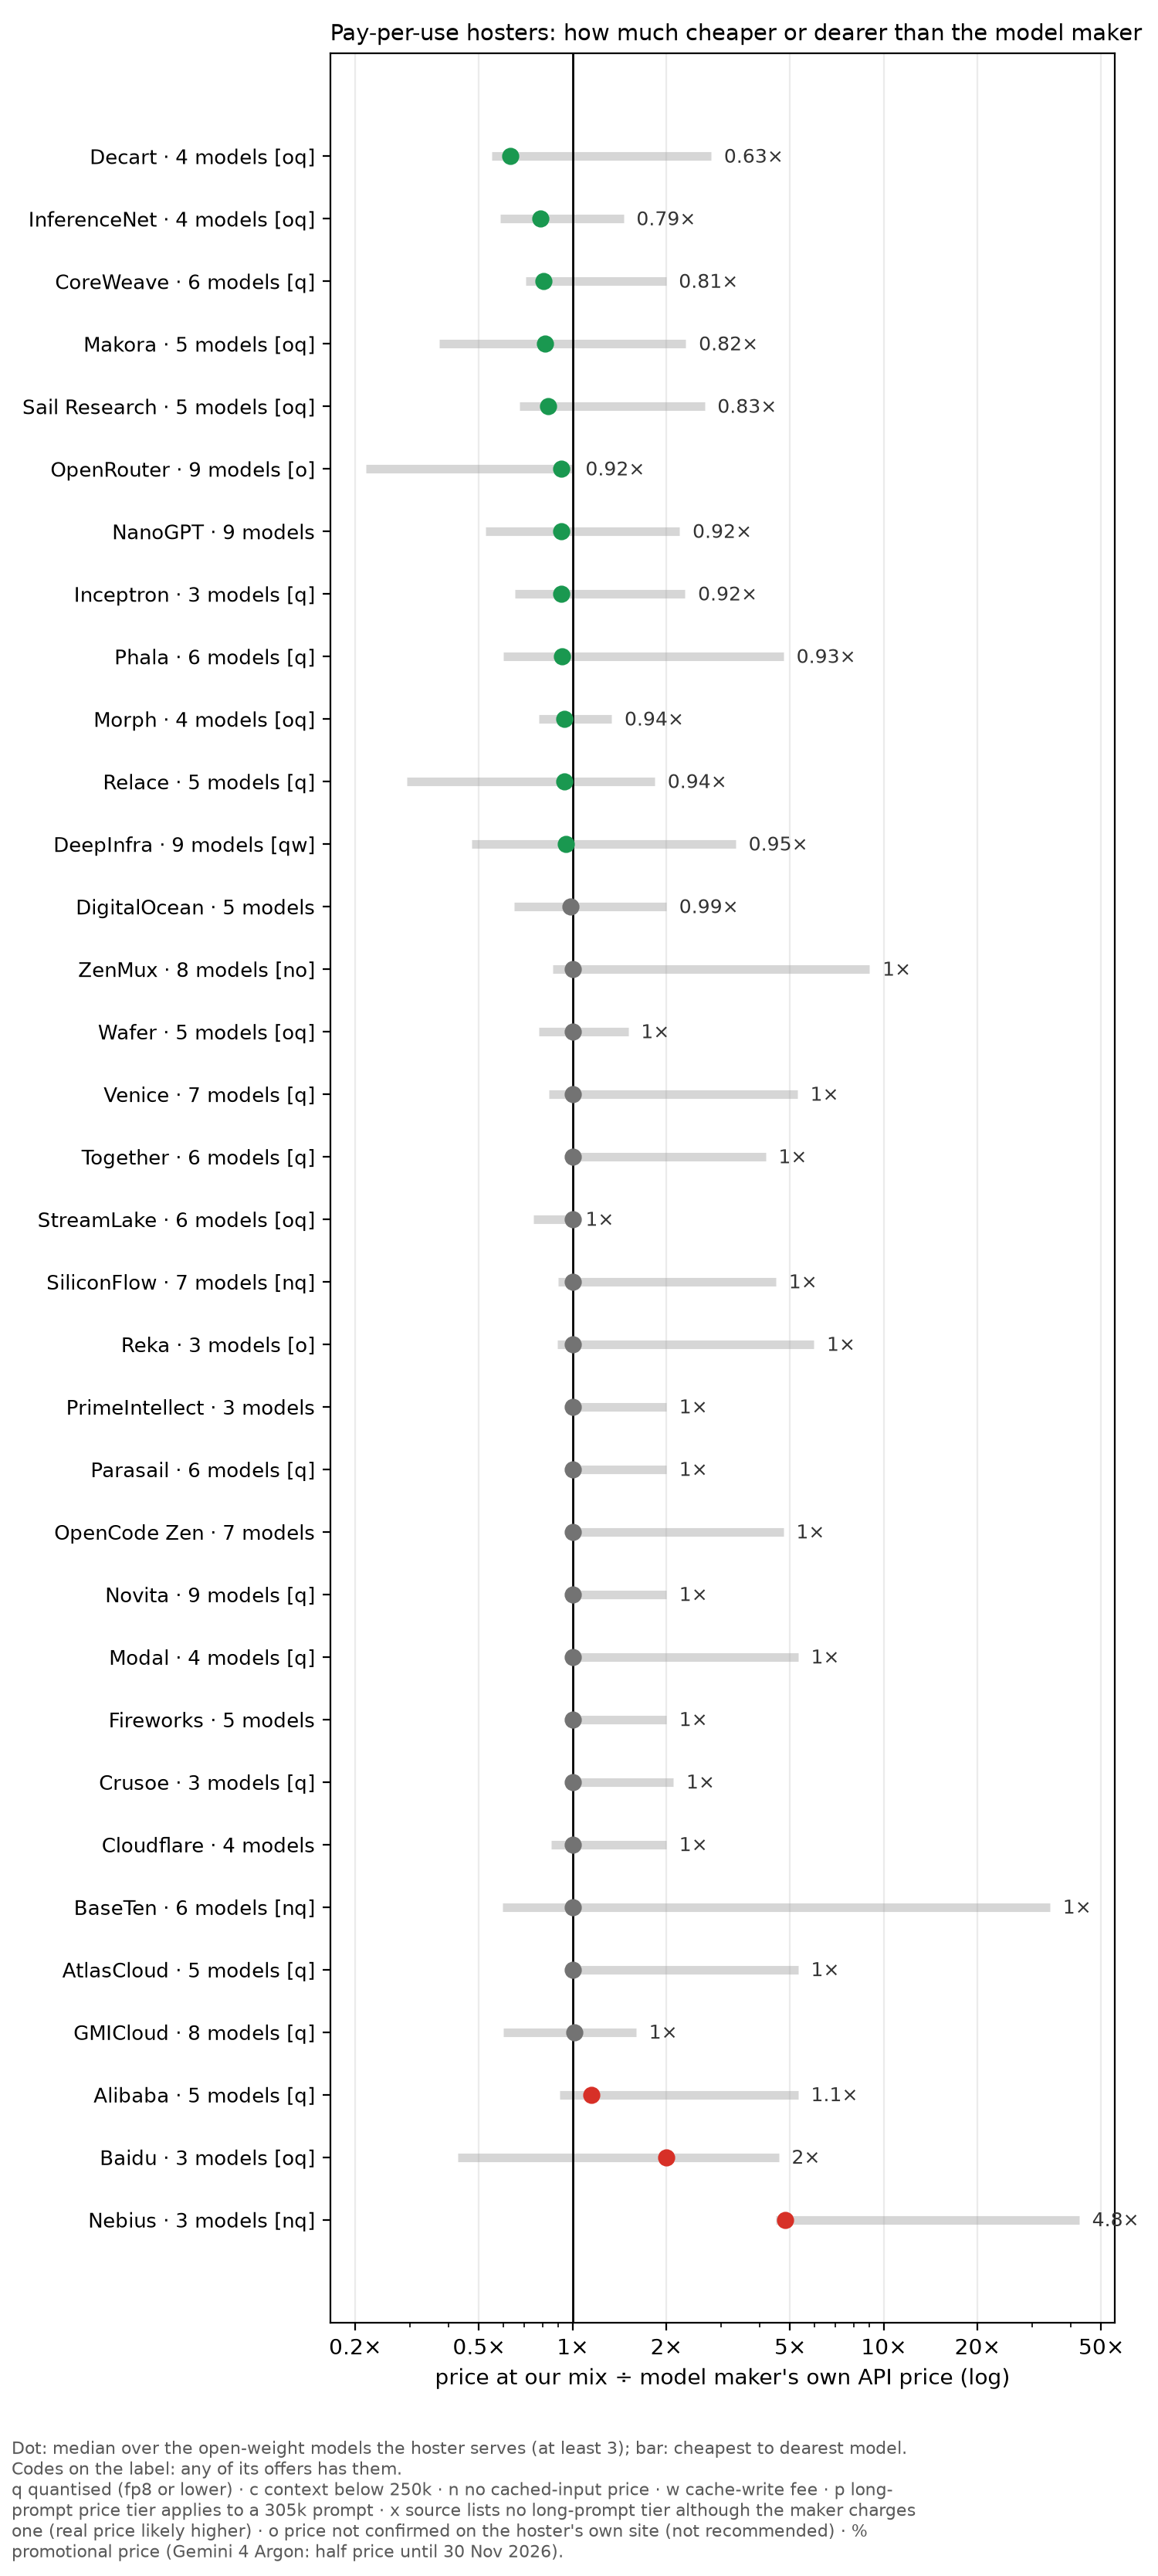
Dot: the hoster's median multiple across the open-weight models it serves (at least 3). Bar: its cheapest to its dearest model.
Cache rate changes the winner
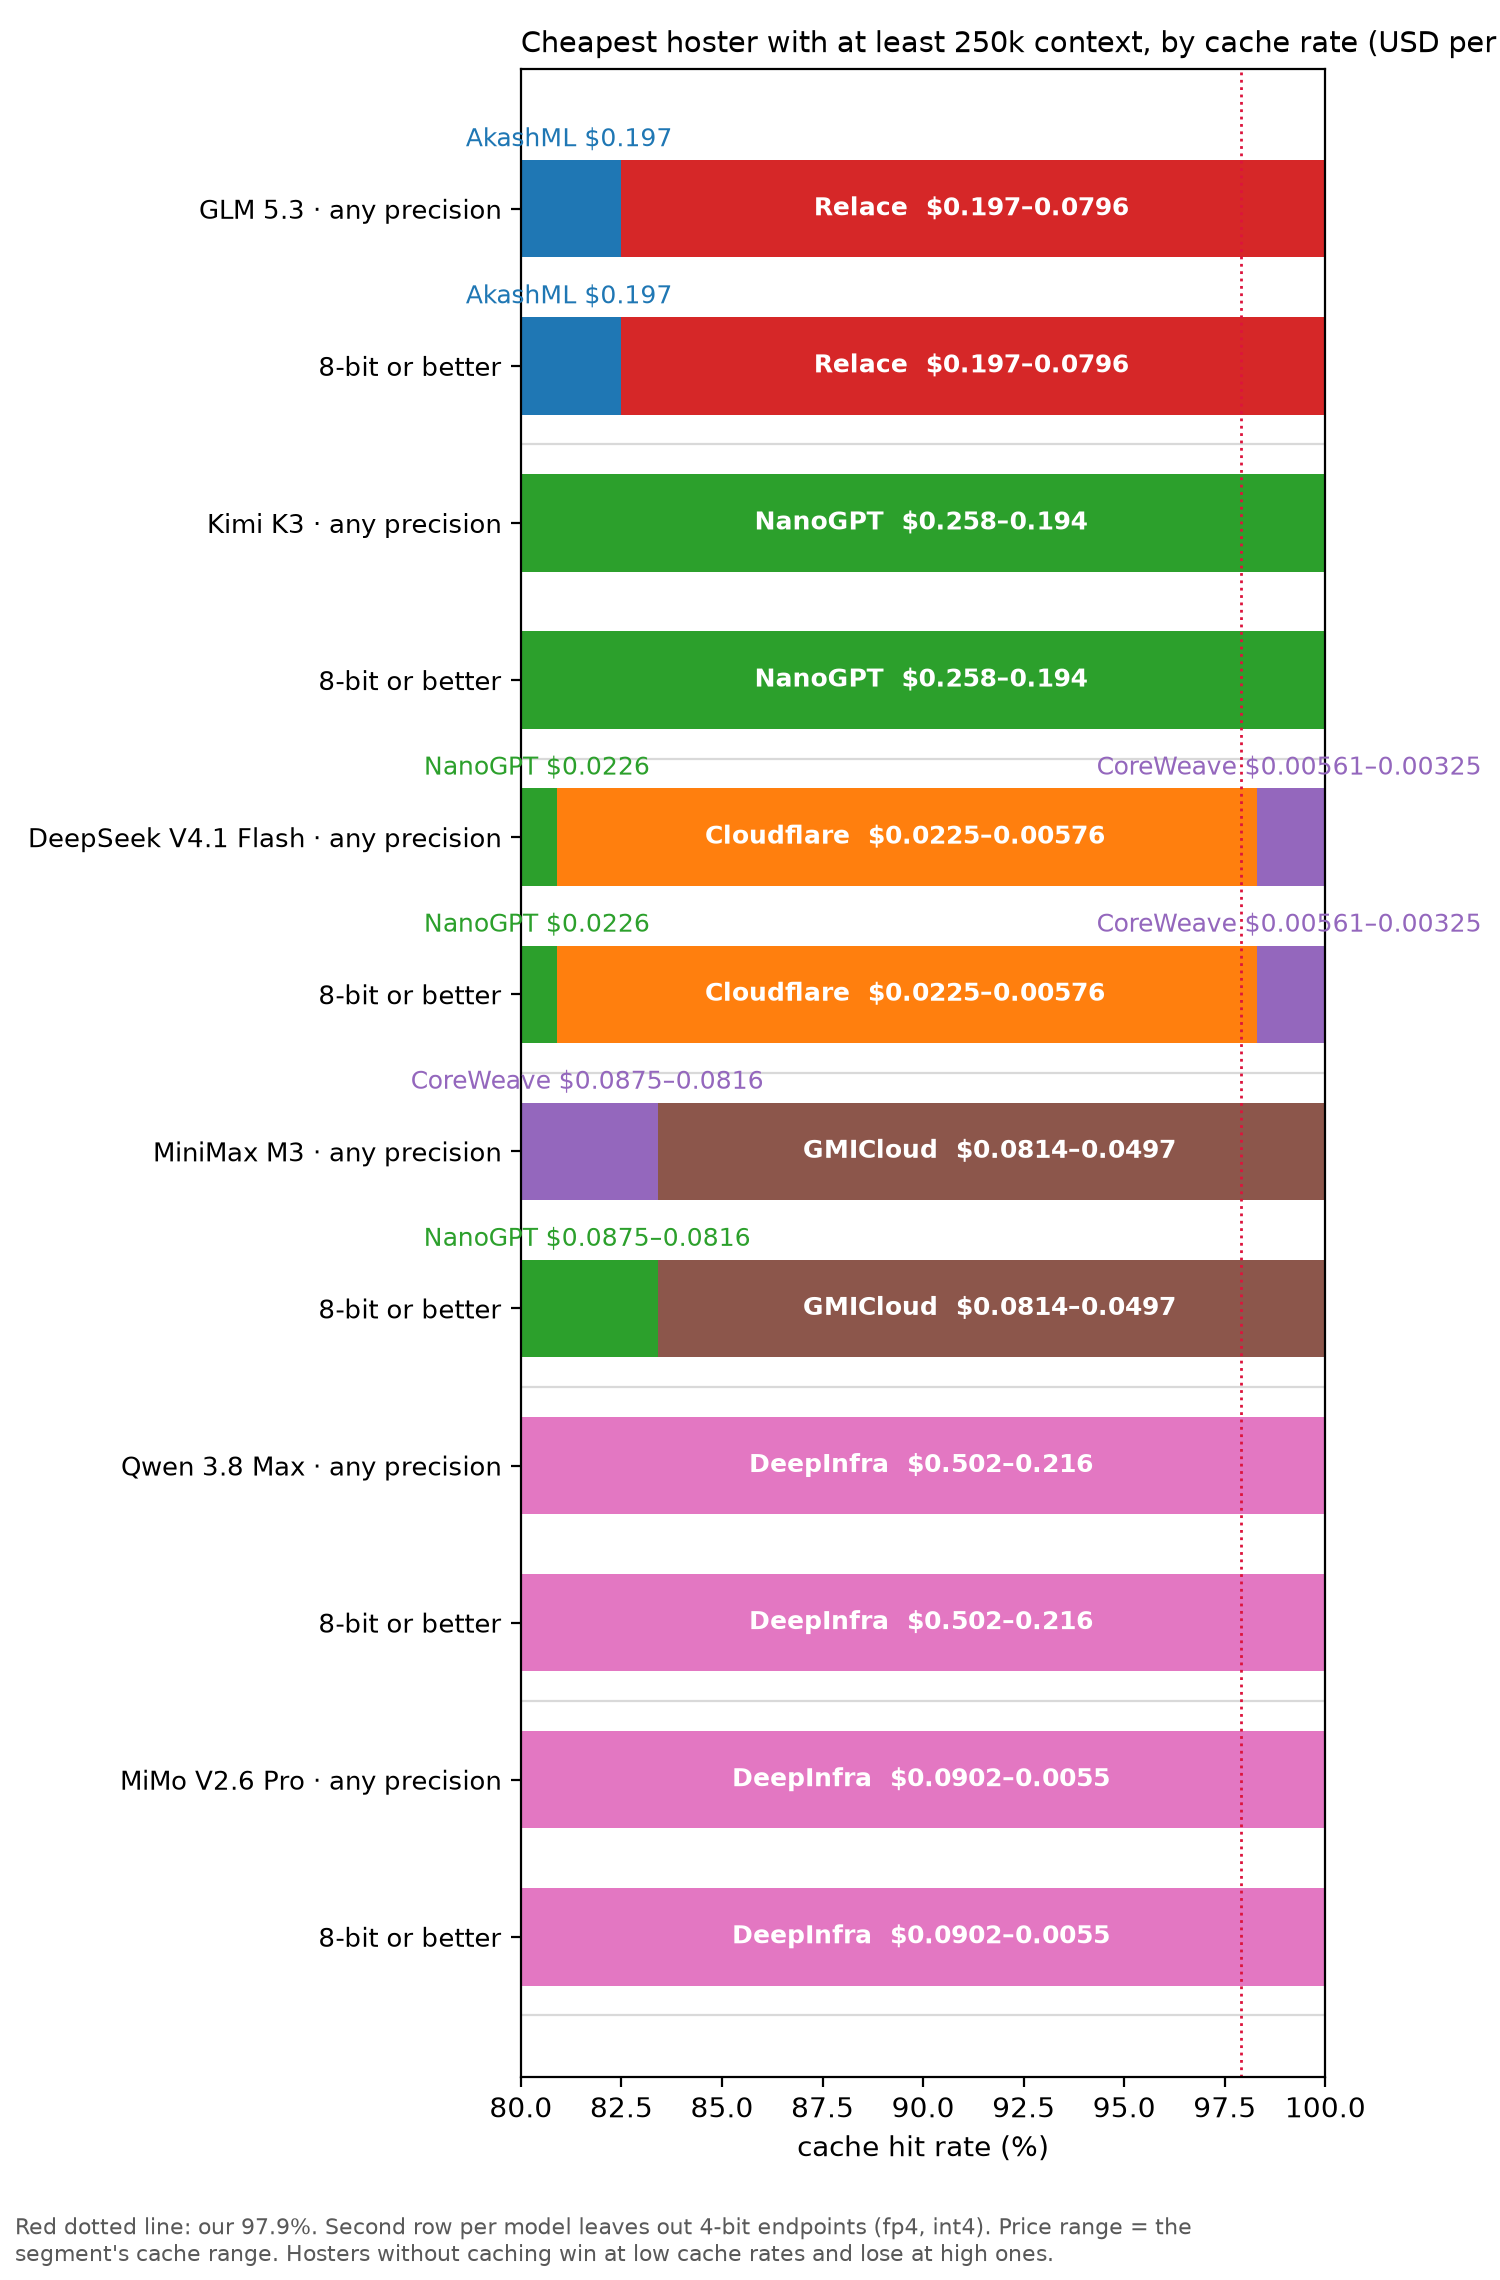
Two rows per model: one for any precision, one for 8-bit or better only. Segment label: hoster and USD per 1M tokens at our mix.
Hosters without a cached-input price win at low cache rates and lose at high ones. With long sessions and a cache rate above 95%, the cached-input price dominates. Below 85%, the input price comes back into play.
Plans and hosters, model by model
Some models are sold both ways, as a plan and per token. The charts below put both on one axis: tokens per dollar, relative to the model maker's own API. A plan's included usage ends at its monthly limit, so each plan also shows that ceiling.
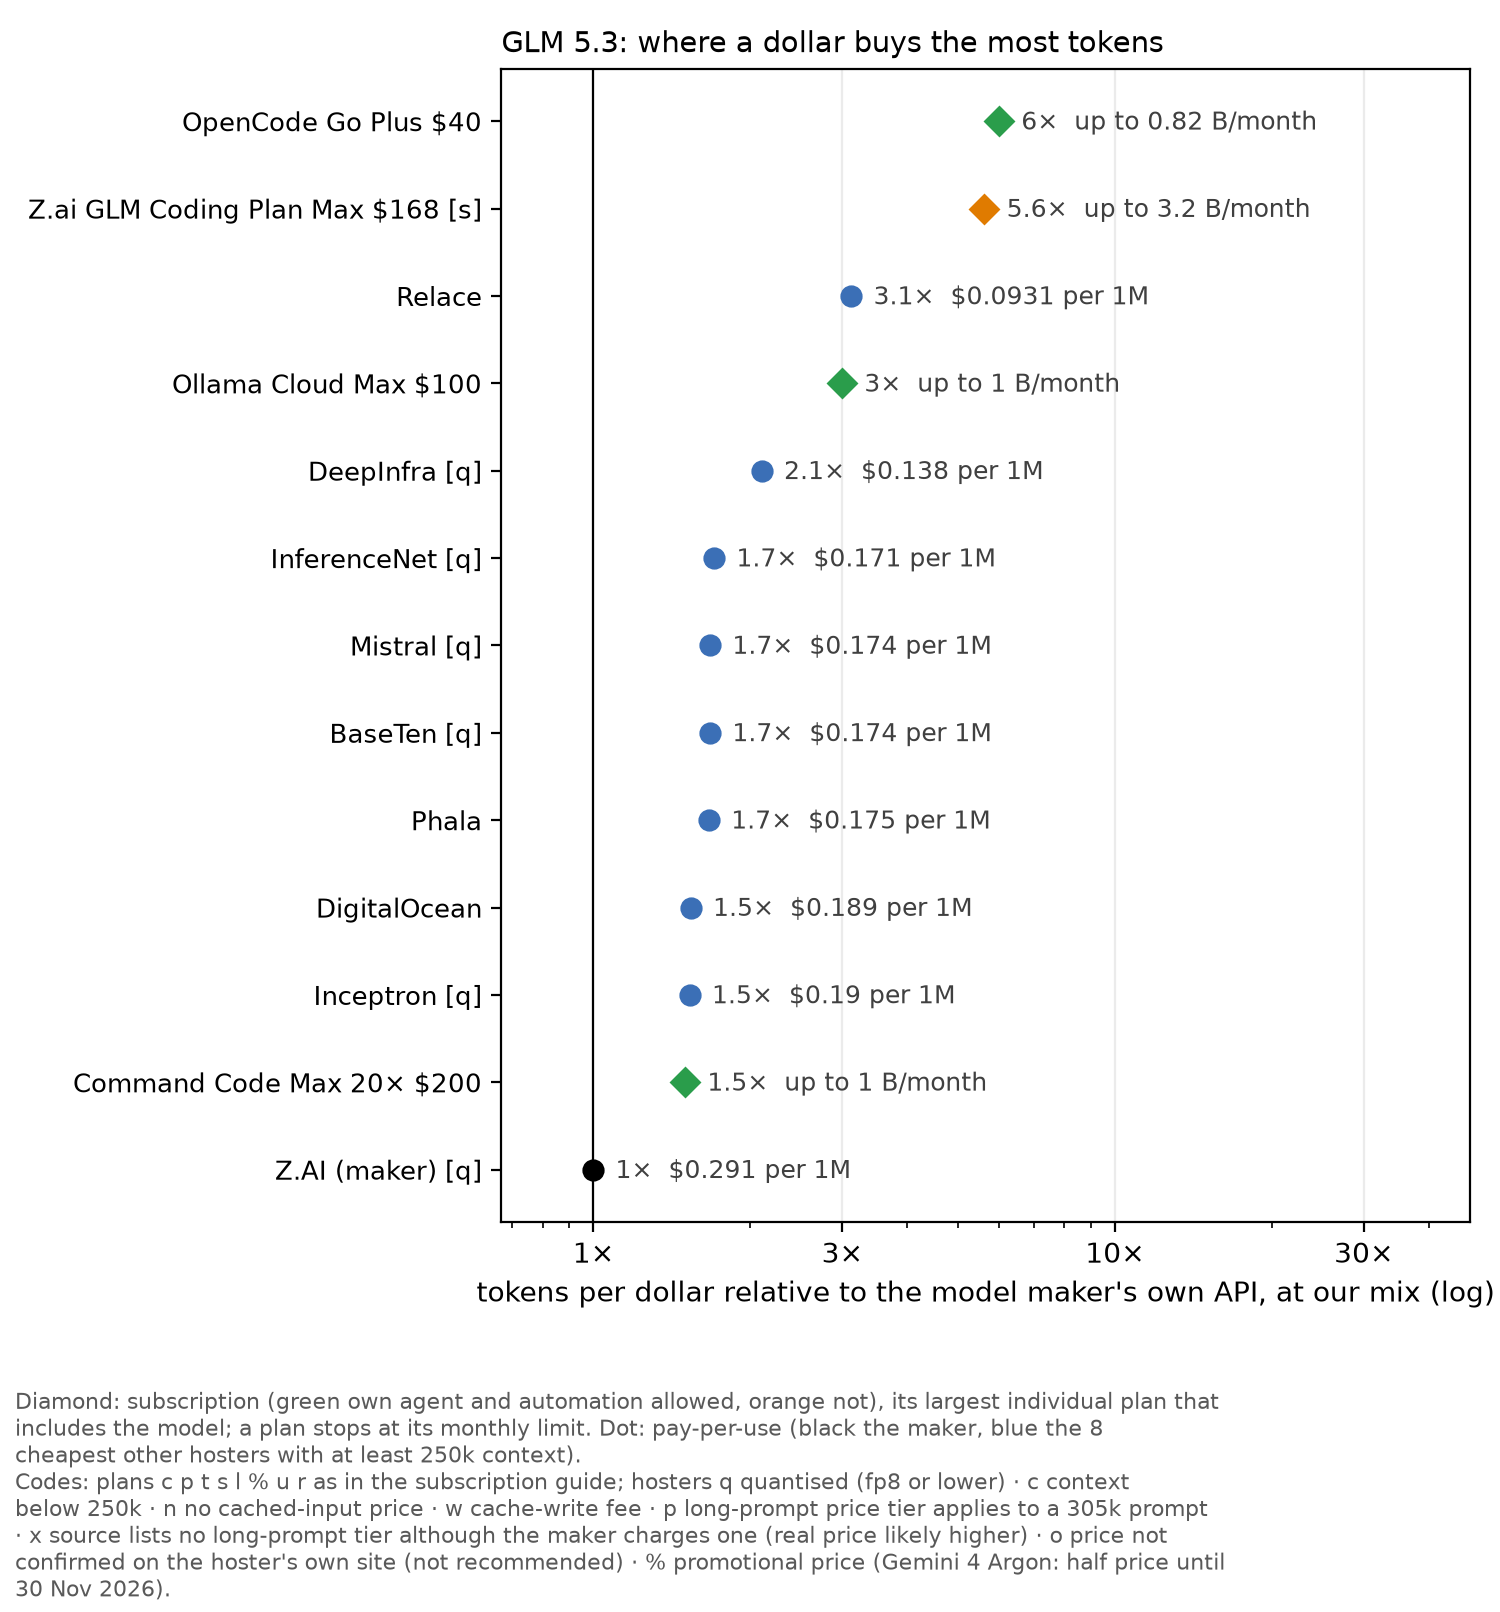
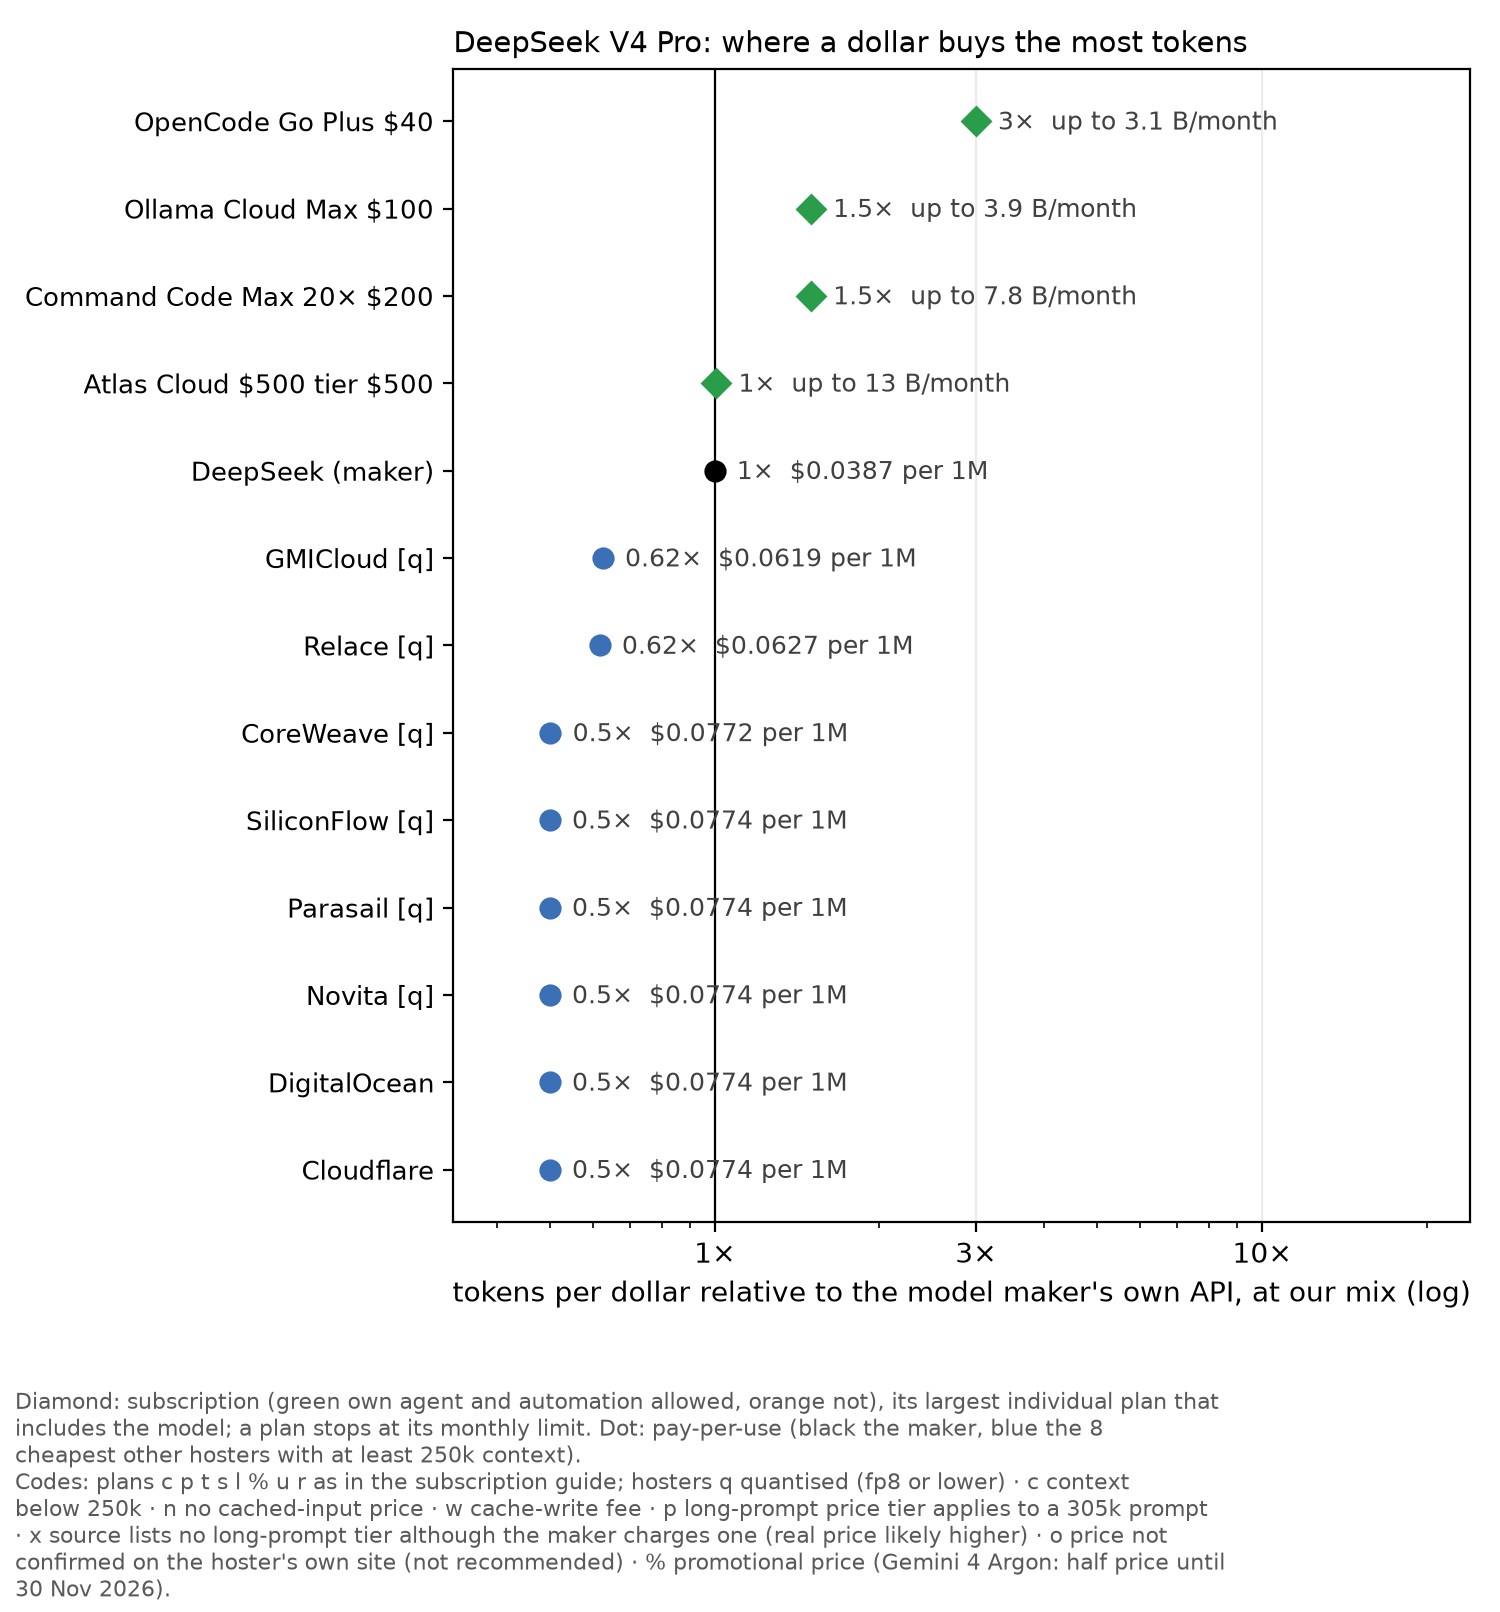
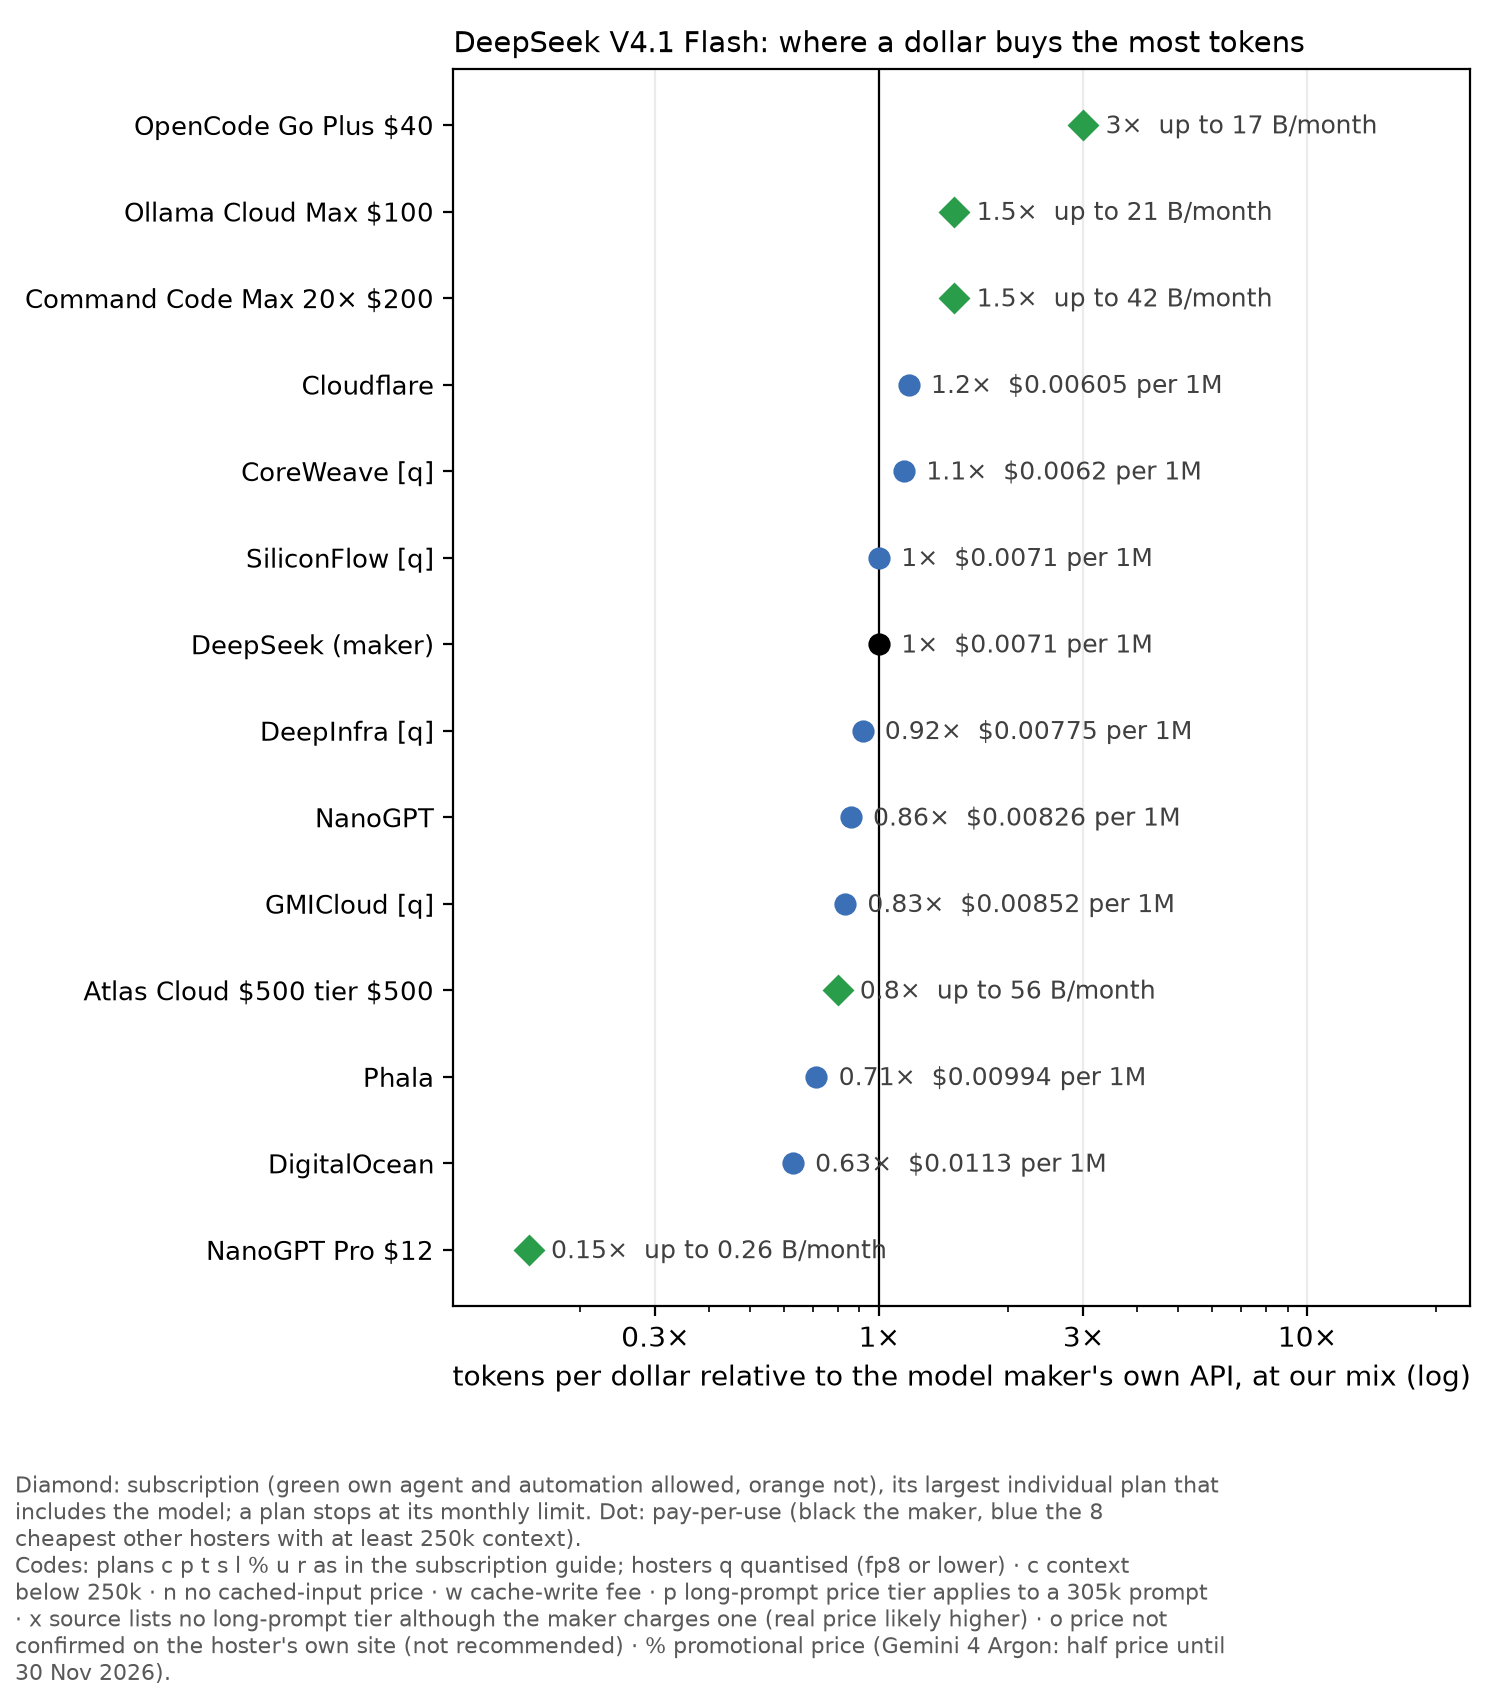
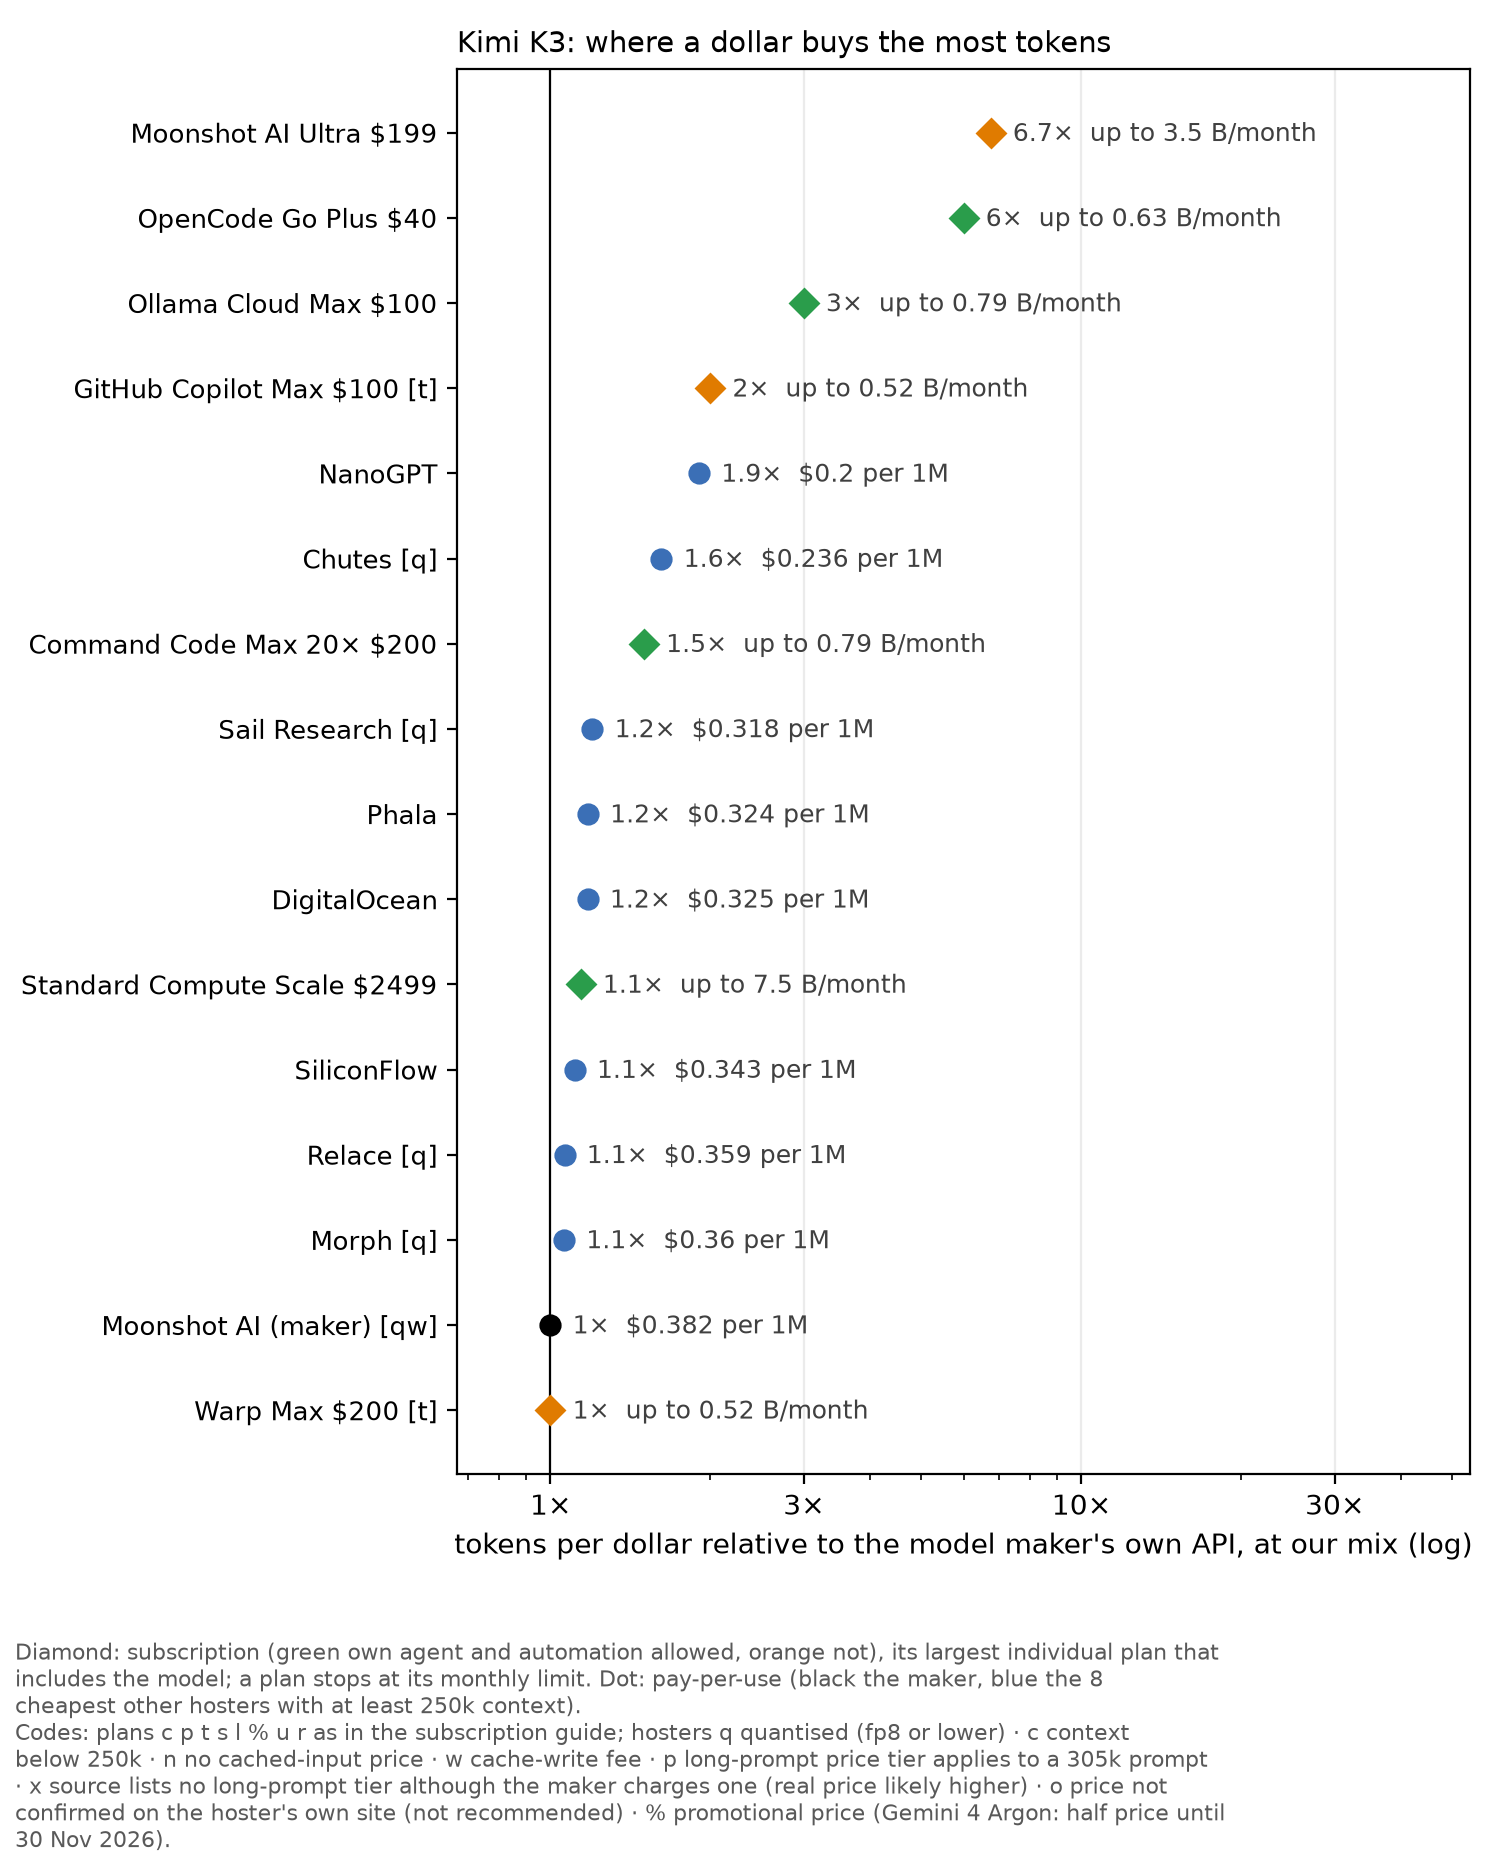
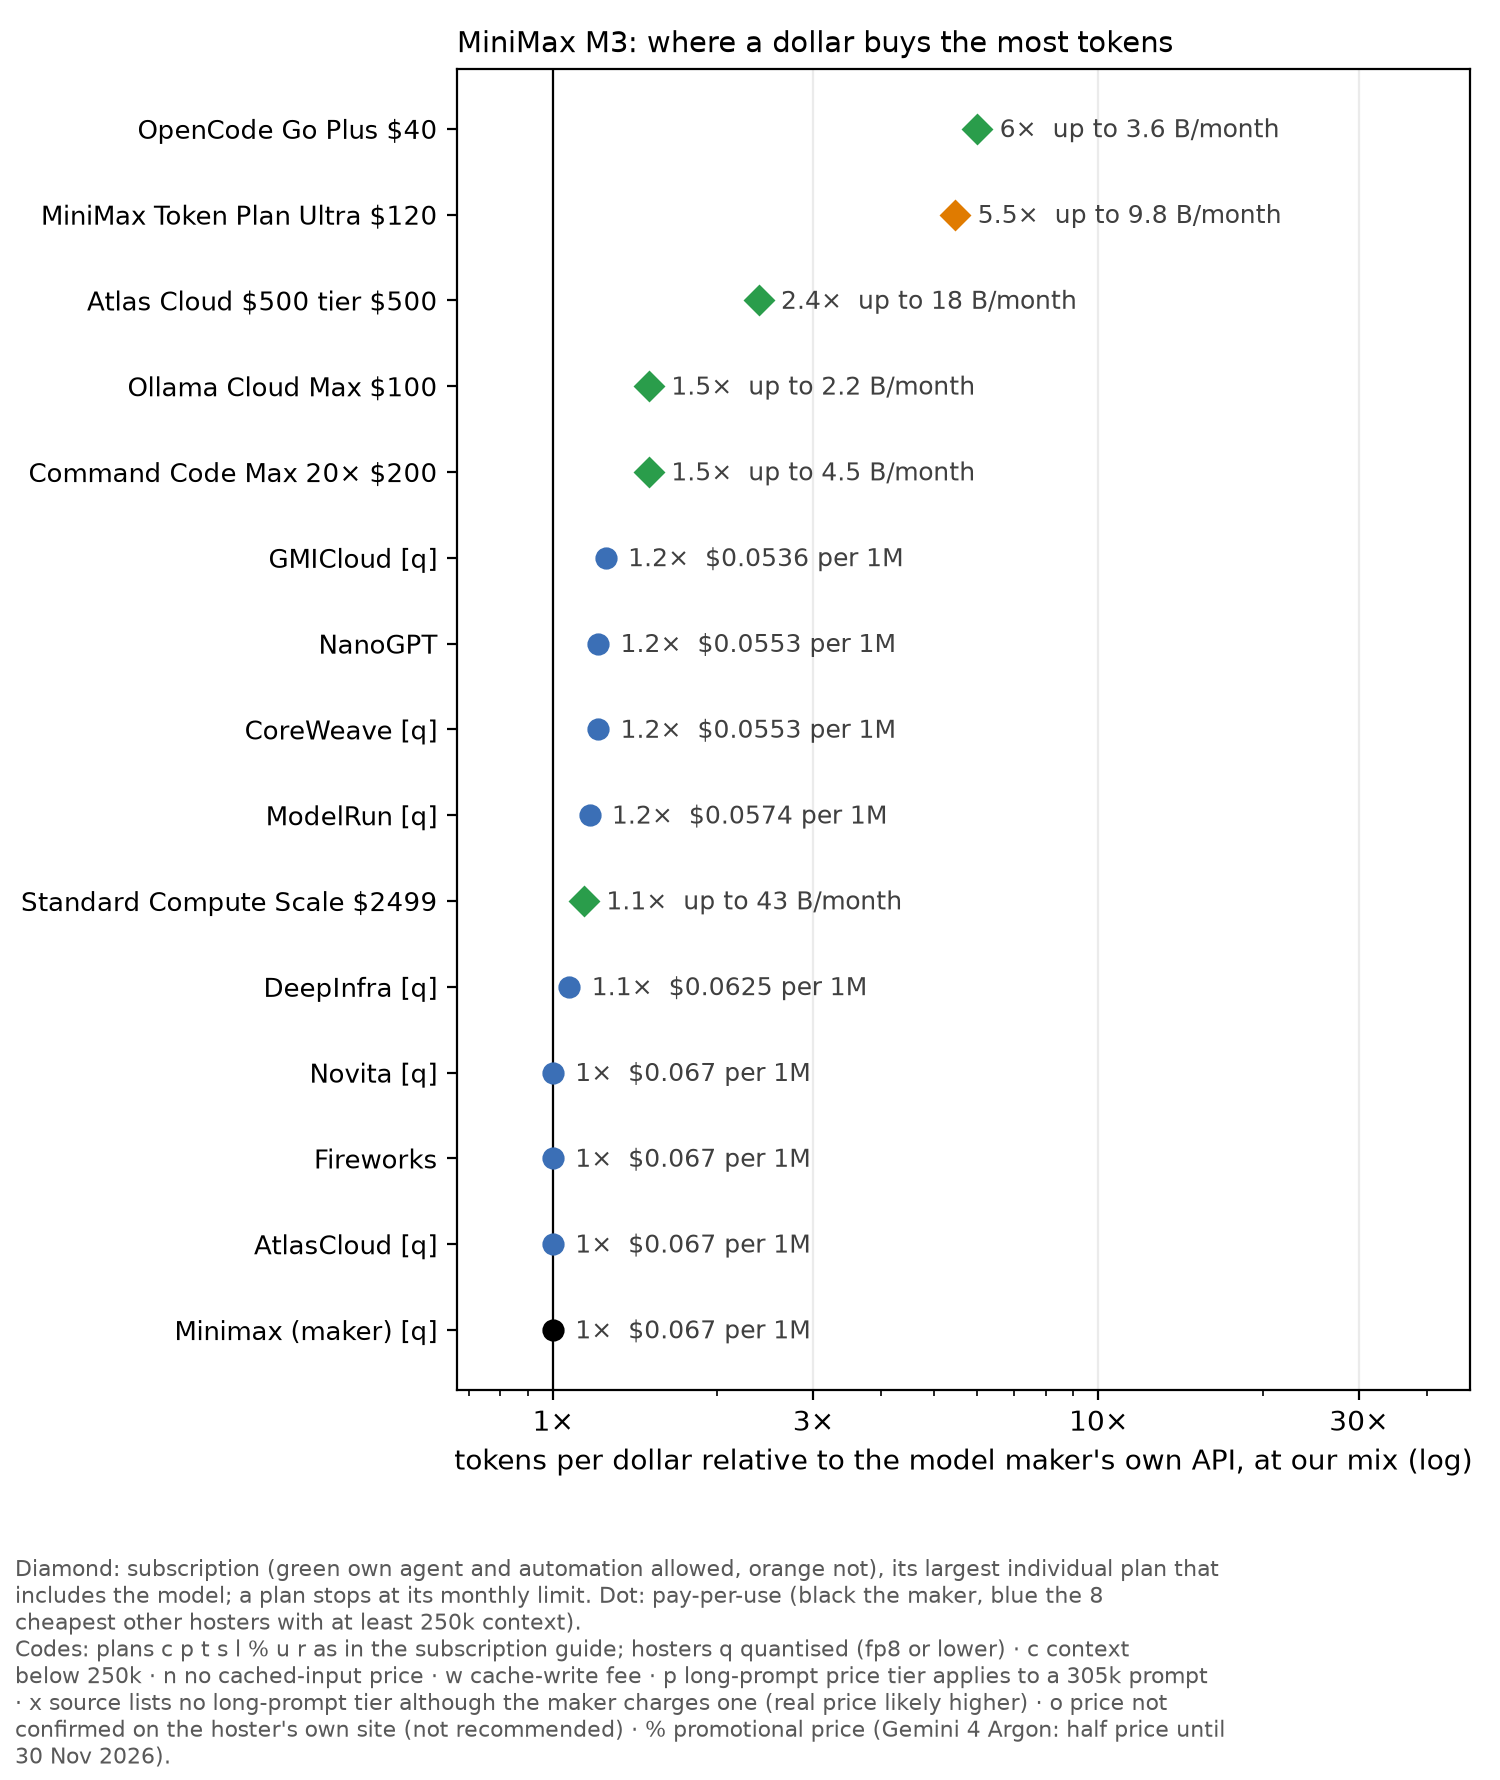
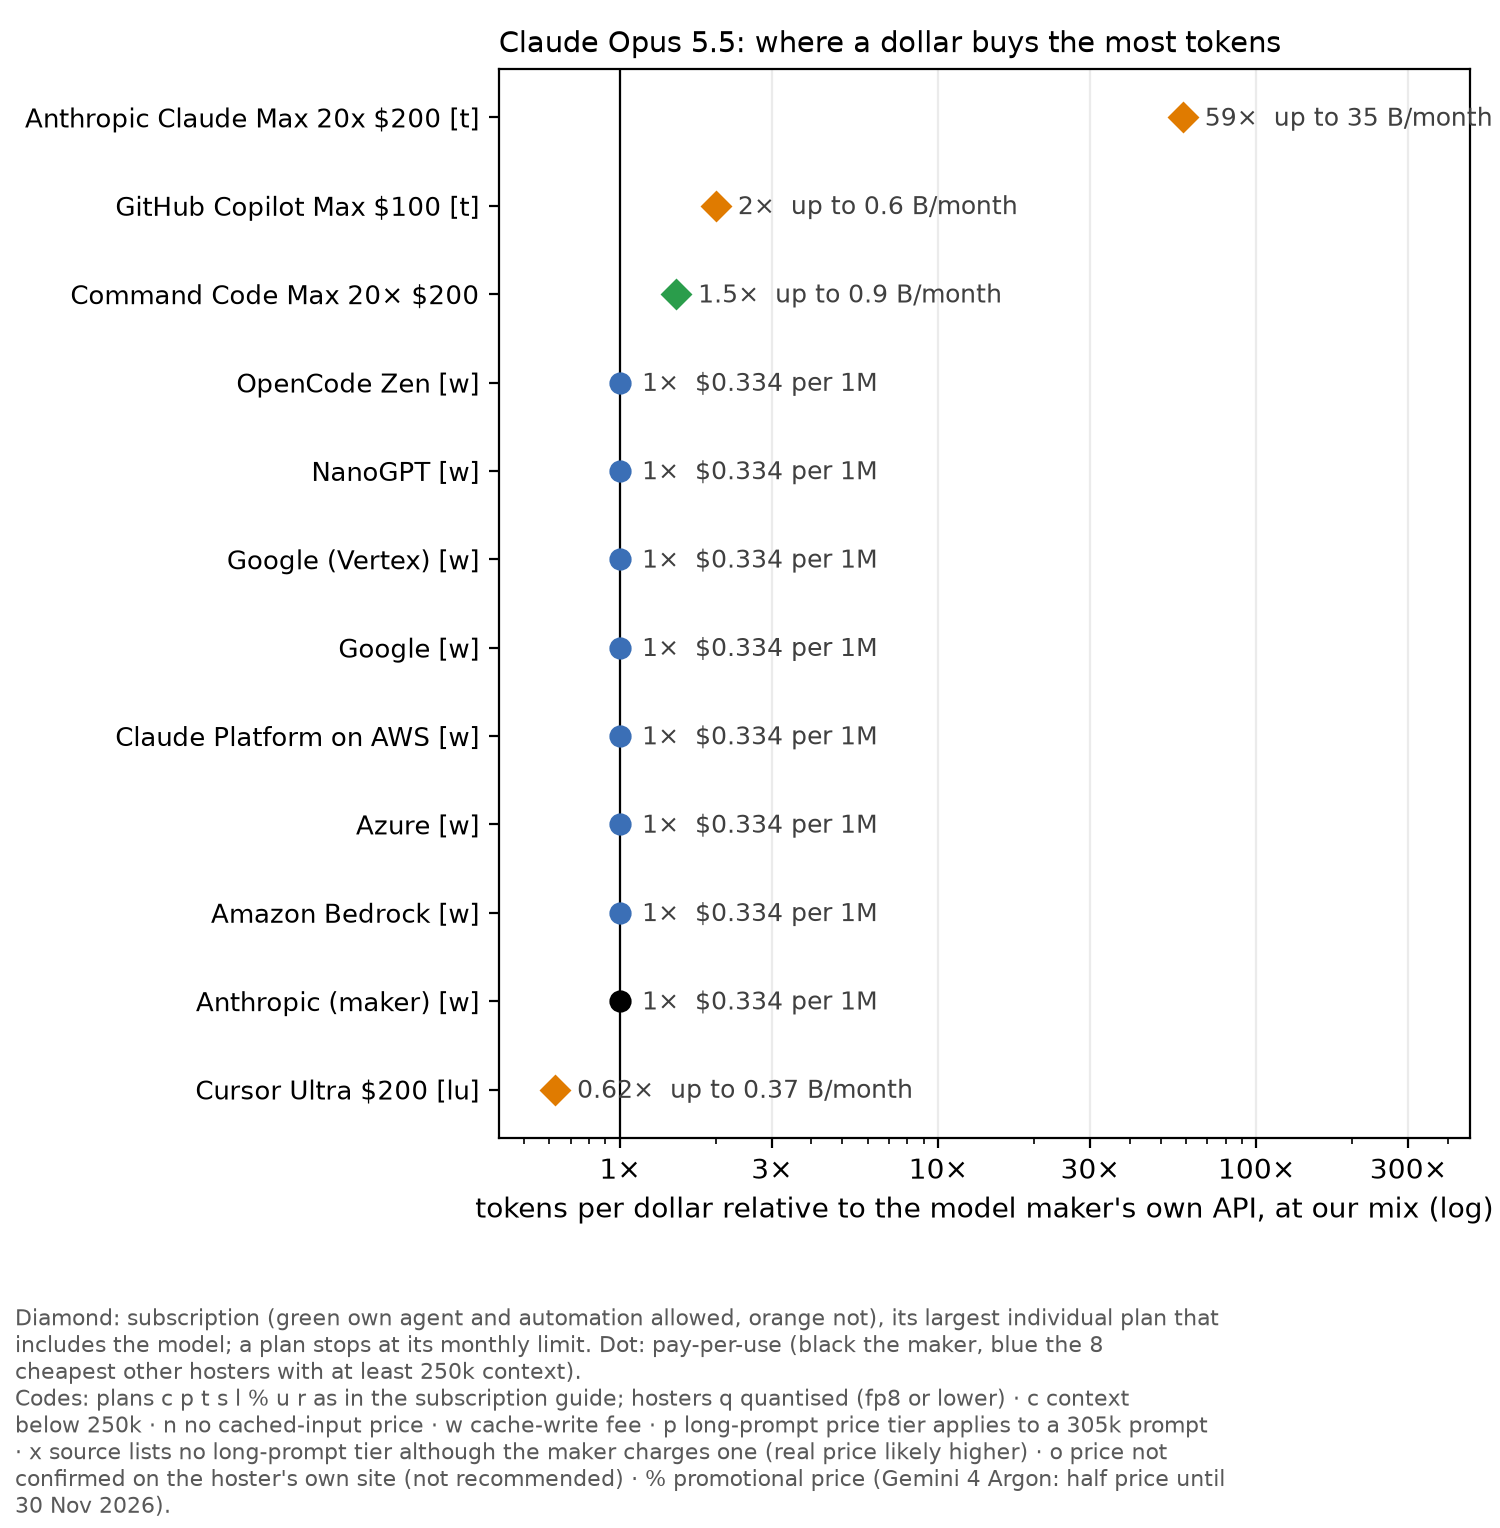
For GLM 5.3, the best plans (OpenCode Go Plus, Z.ai's GLM Coding Plan) and the best hosters are close on price. So the ceiling decides. A plan's included usage ends at 0.8 to 3.3 billion tokens a month. A hoster has no ceiling. For Opus 5.5, every reseller charges list price, and only the subscriptions differ. They range from Claude Max 20x at 59x down to Cursor Ultra at 0.62x.
Teams and startups
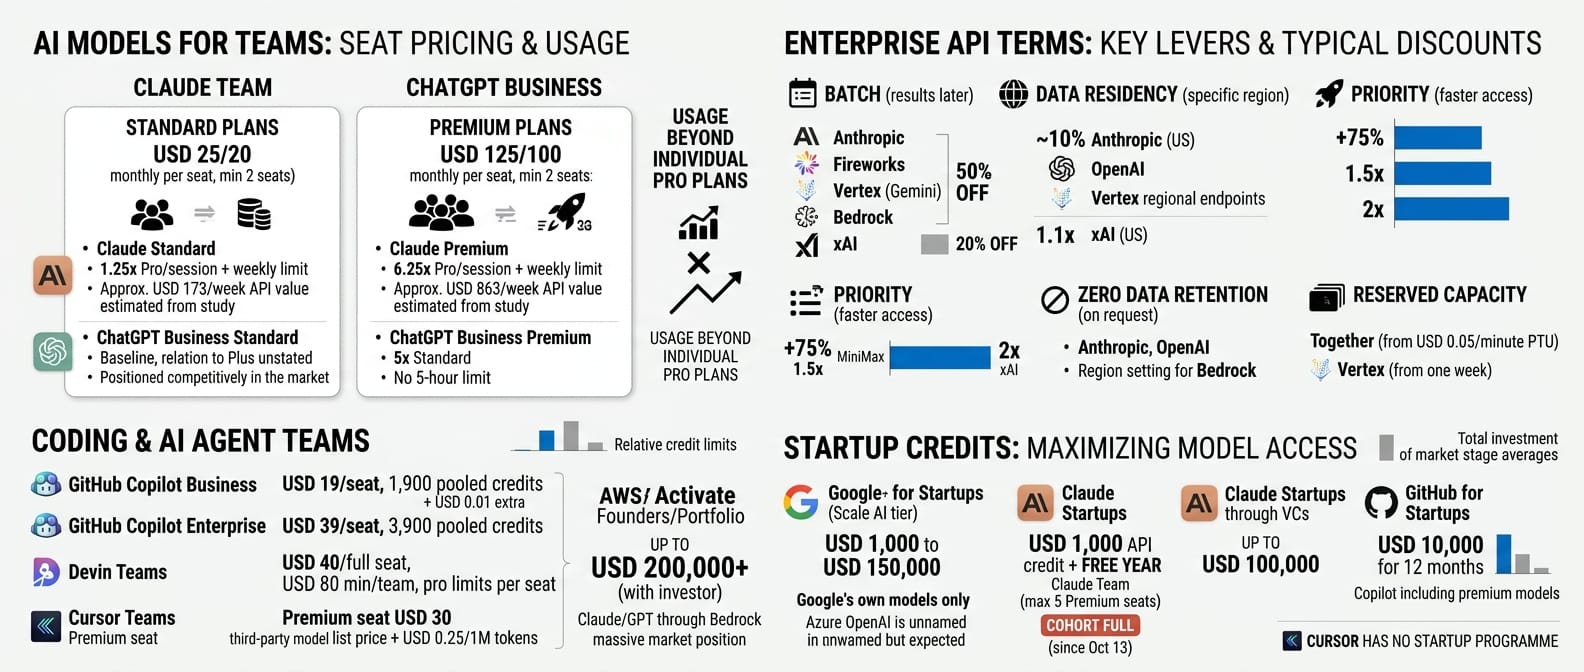
Team seats for Claude and ChatGPT have settled at the same two prices:
| Plan | USD per seat a month (monthly billing) | Usage | Minimum seats |
|---|---|---|---|
| Claude Team Standard | 25 (20) | 1.25x Pro per session, plus a weekly limit | 2 |
| Claude Team Premium | 125 (100) | 6.25x Pro per session, plus a weekly limit | 2 |
| ChatGPT Business Standard | 25 (20) | baseline, relation to Plus not stated | 2 |
| ChatGPT Business Premium | 125 (100) | 5x Standard, no five-hour limit | 2 |
| GitHub Copilot Business | 19 | 1,900 credits per seat, pooled; USD 0.01 per credit beyond | 1 |
| GitHub Copilot Enterprise | 39 | 3,900 credits per seat, pooled | 1 |
| Cursor Teams (The X Subscription), Premium seat | 30 | same as the individual plan; third-party models at list price plus USD 0.25 per 1M tokens | not stated |
| Devin (formerly Windsurf) Teams | 40 per full seat | same as Pro per seat; USD 80 minimum per team | – |
| Factory Teams | 40 | Pro rate limits per seat; plus USD 60 per team | – |
| Z.ai GLM Coding Team Plan | 88 Standard, 188 Premium | 66,000 and 155,000 credits a week per seat | 2 |
Wokey measured Claude Team Standard across 8 accounts and Premium across 97. Standard gives about USD 173 of API value a week, Premium about USD 863. That is roughly the level of Pro and Max 5x.
Enterprise API terms follow a common pattern:
| Lever | Typical terms |
|---|---|
| Batch (results later, not in real time) | 50% off at Anthropic, Fireworks, Vertex (Gemini) and Bedrock; 20% at xAI |
| Data residency | about 10% extra at Anthropic (US only), OpenAI and Vertex regional endpoints; xAI's US endpoint 1.1x |
| Priority | Bedrock +75%, MiniMax 1.5x, xAI 2x |
| Reserved capacity | Together from USD 0.05 per provisioned throughput unit per minute (one-month minimum); Vertex from one week |
| Zero data retention | on request at Anthropic and OpenAI; a per-Region setting at Bedrock |
Startup credits matter more than seat prices for a young company. What they cover differs:
| Programme | Credits | Covers Claude or GPT? |
|---|---|---|
| AWS Activate Founders / Portfolio | USD 1,000 (up to 5,000) self-funded; up to USD 200,000 with an investor or accelerator | yes, through Bedrock |
| Google for Startups, Scale AI tier | up to USD 350,000 over two years | no: Google's own models only |
| Microsoft for Startups | USD 1,000, then 4,000; up to 150,000 with an investor | Azure OpenAI not named |
| Claude Startups | USD 1,000 API credit plus a free year of Claude Team (up to 5 Premium seats) | yes, Anthropic's own API only; cohort full since 13 October |
| Claude Startups through your venture capital investor | up to USD 100,000 | yes |
| GitHub for Startups | USD 10,000 for 12 months | Copilot, including premium models |
| Fireworks, Together, xAI | amounts per application | their own platforms |
Cursor has no startup programme.
Open weights or frontier models
The thesis tested here: open-weight models trail the best closed models by a few months. That lag pays off only if they are much cheaper.
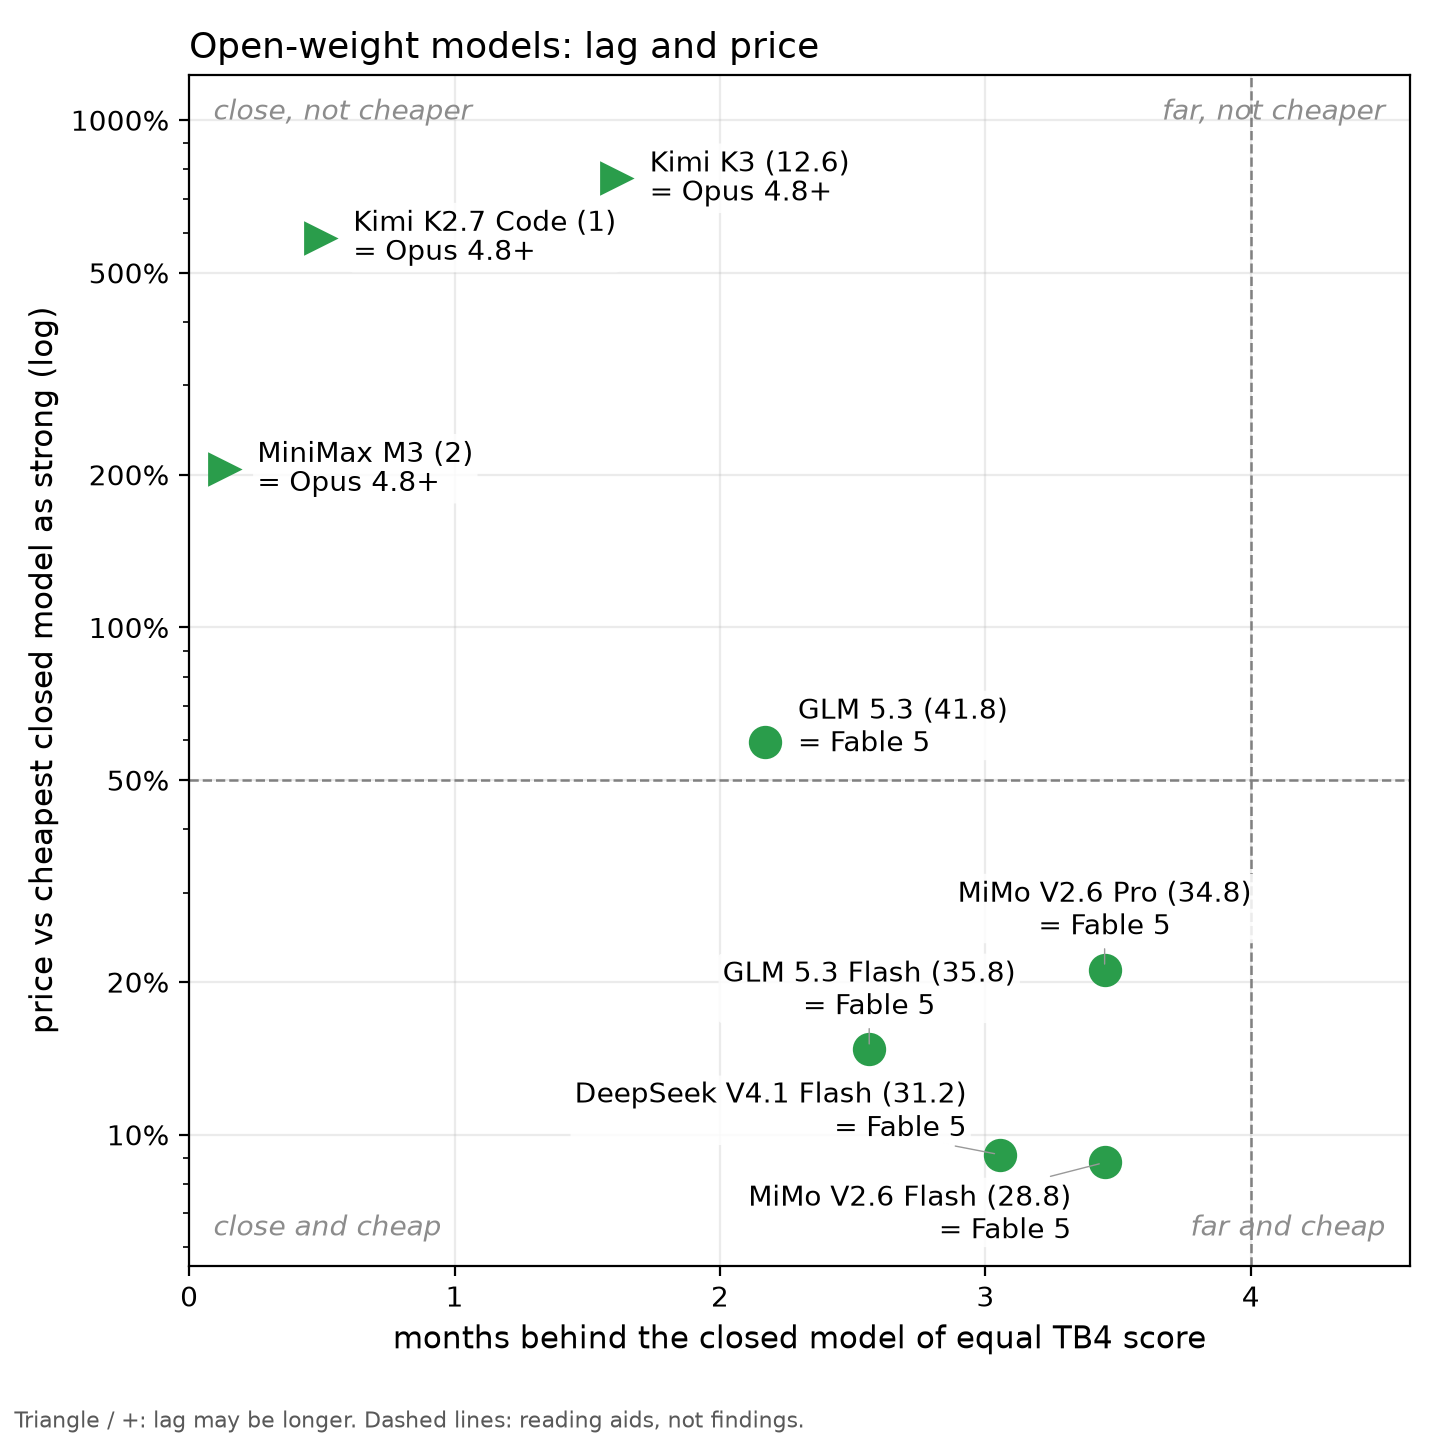
Months behind: time from the release of the first closed model with at least the same Terminal-Bench 4.0 score to the open model's release. Dates are leaderboard release dates where listed, otherwise OpenRouter's listing date. Closed scores start with Claude Opus 4.8 on 28 May 2026, so a triangle marks a lag that may be longer. Price: cheapest offer at our mix that the hoster's own site does not contradict, per token, as a share of the cheapest current closed model at least as strong. The 4-month and 50% lines are reading aids.
| Open model (TB4) | First closed model as strong | Months behind | Price vs cheapest closed model as strong |
|---|---|---|---|
| GLM 5.3 (41.8%) | Claude Fable 5 | 2.2 | 59% of Gemini 4 Argon |
| GLM 5.3 Flash (35.8%) | Claude Fable 5 | 2.6 | 15% of Claude Haiku 5.5 |
| MiMo V2.6 Pro (34.8%) | Claude Fable 5 | 3.4 | 21% of Claude Haiku 5.5 |
| DeepSeek V4.1 Flash (31.2%, vendor) | Claude Fable 5 | 3.1 | 9% of Claude Haiku 5.5 |
| MiMo V2.6 Flash (28.8%, vendor) | Claude Fable 5 | 3.4 | 9% of Claude Haiku 5.5 |
| Kimi K3 (12.6%) | Claude Opus 4.8 or earlier | 1.6 or more | 768% of GPT-6 Luna |
| MiniMax M3 (2%) | Claude Opus 4.8 or earlier | 0.1 or more | 206% of GPT-6 Luna |
| Kimi K2.7 Code (1%) | Claude Opus 4.8 or earlier | 0.5 or more | 587% of GPT-6 Luna |
The strong open models trail by two to three and a half months. GLM 5.3 is the only one that reaches 40%. The cheapest closed model that strong is Gemini 4 Argon (57.1%), and GLM 5.3 costs 59% as much. But Gemini's price is a promotion until 30 November. At Gemini's list price from 1 December, GLM 5.3 would cost about a third of it. The Flash-class models save 80% to 90% against Claude Haiku 5.5.
Kimi K3 and MiniMax M3 sit in the wrong corner: behind and more expensive. Judged by their independent TB4 scores, a cheap closed model such as GPT-6 Luna is already stronger and cheaper per token.
So the lag pays off through cheap channels: a verified cheap hoster, or a plan that buys many times what the API buys. At the maker's list price, two things close most of the price gap: cache discounts on closed models, and how few tokens GPT-6.1 Sol used in its benchmark run.
Where this is going
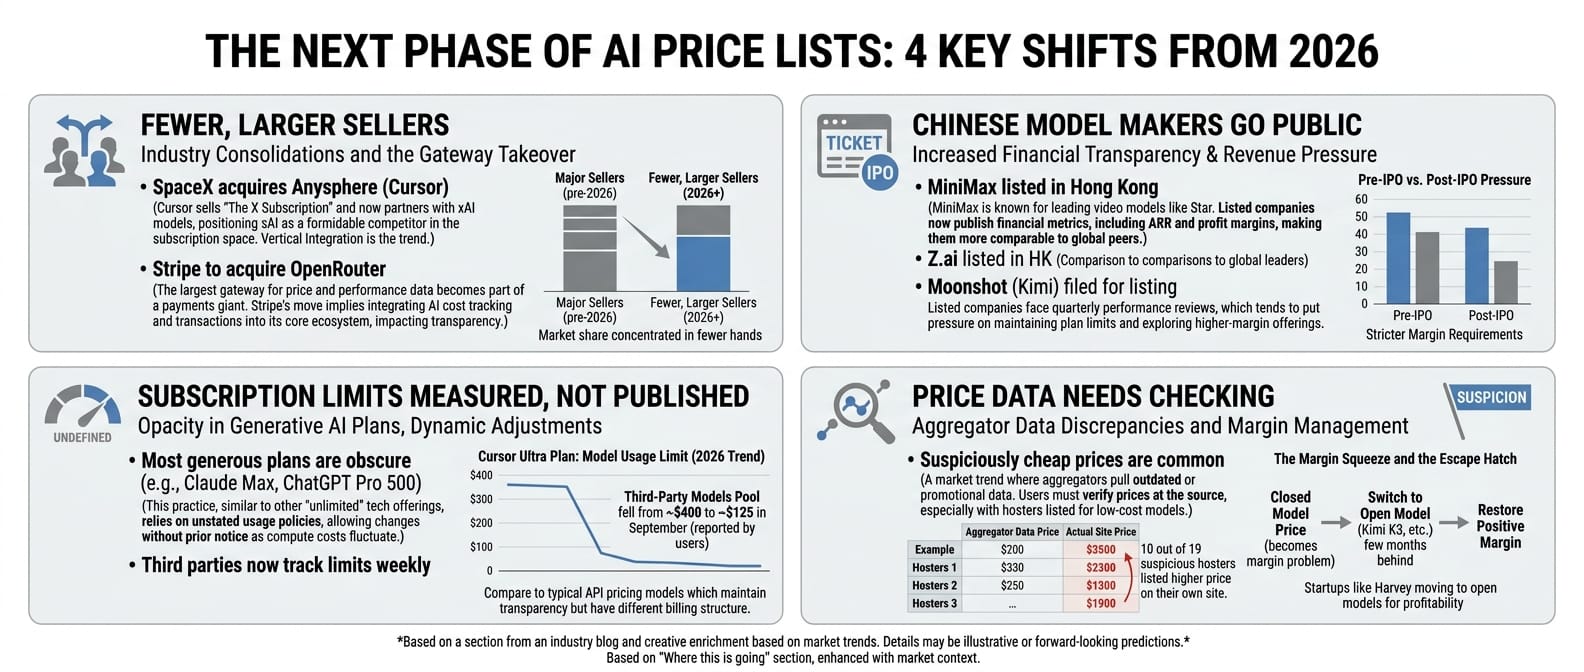
Four changes from 2026 will shape the next price lists.
- Fewer, larger sellers. On 14 August SpaceX completed its acquisition of Anysphere, the company behind Cursor. Cursor now sells The X Subscription. Stripe agreed on 19 August to acquire OpenRouter. The gateway most price data comes from is about to belong to a payments company.
- Chinese model makers go public. Z.ai listed in Hong Kong in January, MiniMax on 9 January. Moonshot filed confidentially for a Hong Kong listing. Listed companies publish revenue. Revenue pressure tends to show up in plan limits.
- Subscription limits are measured, not published. The most generous plans publish no absolute limits. Claude Max states a multiple of Pro, and ChatGPT Pro 500 only says it has the highest usage. Third parties now track them weekly. Expect the limits to move without notice. Cursor users report that the Ultra plan's pool for third-party models fell from USD 400 to about USD 125 in September.
- Price data needs checking. Of 19 hosters with suspiciously cheap prices, 10 list a higher price on their own site than in the aggregator data the market uses. A comparison built only on aggregator data recommends offers that do not exist at that price.
Harvey's swing back to a positive margin is the pattern to watch. It came after a move to a model built on Kimi K3. When a closed model's price becomes a margin problem, the open model a few months behind is the obvious way out.
Vendor by vendor
Every vendor in the catalogue, generated from the same data as the charts above. Subscriptions first, then pay-per-use.
Subscriptions
Anthropic: Claude Pro and Max
Anthropic, based in San Francisco, builds the Claude models and Claude Code, its coding agent. Claude Code passed USD 2.5 billion in annualised revenue in February 2026, and Menlo Ventures put Anthropic at 54% of enterprise spending on AI coding at the end of 2025.
What to know:
- Most tokens per dollar: Claude Max 20x (USD 200) buys 59x the tokens of Anthropic's API for the same money at our mix: 35 B Opus 5.5 tokens a month, just under our 37.23 B.
- Measured, not published: Anthropic publishes only multiples of Pro. The limits come from Wokey (USD 1,751 of API value a week, 36 accounts) and SemiAnalysis (28.6 B tokens a month on Max 20x).
- No automation, limited tools: Automated or non-human access needs an API key or explicit permission; third-party tools run only at Anthropic's discretion. Your own agent or CI pipeline belongs on the API.
- Training is opt-out: Plan data trains Claude unless you opt out, with 5-year retention if allowed and 30 days if not. Switch it off before you open a client repository.
- Pro covers mid volumes: At USD 20, Claude Pro is the finder's pick from 1 B to 3 B tokens a month at any minimum score from 40 up; SemiAnalysis measured 2.9 B a month.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Claude Pro | 20 | not published | 5h+week (not published) |
| Claude Max 5x | 100 | 5x Pro (per session) | 5h+week |
| Claude Max 20x | 200 | 20x Pro (per session) | 5h+week |
- Models: Claude Opus; Claude Sonnet; Claude Haiku; Claude Fable (50% of weekly limits); Claude Code
- Context: Claude Pro: Up to 1M (newest models; others 500K or 200K); Claude Max 5x: Up to 1M; Claude Max 20x: Up to 1M
- Third-party tools: API key preferred; subscription via third-party tools only at Anthropic discretion, drawn from usage credits
- Automation: No automated or non-human access except API key or explicit permission; limits assume ordinary individual use
- Training on your data: Yes unless opted out (5-year retention if allowed, 30 days if not)
- At the limit: Wait, upgrade, use limit reset, or continue on usage credits
Measured and stated limits (60 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Claude Pro | 170 (159–181) USD of API value | week | tracker | wokey.ai |
| Claude Pro | 26.1 M tokens | week | tracker | wokey.ai |
| Claude Pro | 157 M tokens | week | tracker | wokey.ai |
| Claude Pro | 15 USD of API value | 5h | tracker | wokey.ai |
| Claude Pro | 1,178 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Pro | 2.9 B tokens | month | analyst | newsletter.semianalysis.com |
| Claude Max 5x | 5,725 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 5x | 14 B tokens | month | analyst | newsletter.semianalysis.com |
| Claude Max 5x | 1,273 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 5x | 761 (658–873) USD of API value | week | user | finopsllm.com |
| Claude Max 5x | 420 USD of API value | week | user | danubelabs.net |
| Claude Max 5x | 978 M tokens | week | user | danubelabs.net |
| Claude Max 5x | 840,000 tokens | week | user | github.com |
| Claude Max 5x | 7.9 USD of API value | week | user | github.com |
| Claude Max 5x | 2.97 USD of API value | week | user | github.com |
| Claude Max 20x | 1,751 (1,683–1,825) USD of API value | week | tracker | wokey.ai |
| Claude Max 20x | 231 M tokens | week | tracker | wokey.ai |
| Claude Max 20x | 2 B tokens | week | tracker | wokey.ai |
| Claude Max 20x | 278 USD of API value | 5h | tracker | wokey.ai |
| Claude Max 20x | 11,726 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 20x | 9,200 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 20x | 12,529 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 20x | 2,485 USD of API value | month | analyst | newsletter.semianalysis.com |
| Claude Max 20x | 28.6 B tokens | month | analyst | newsletter.semianalysis.com |
| Claude Max 20x | 1.13 B weighted units = Haiku 4.5… | week | user | zenn.dev |
| Claude Max 20x | 3.3 M Opus 5 uncached input tokens | week | user | zenn.dev |
| Claude Team Standard | 173 (165–188) USD of API value | week | tracker | wokey.ai |
| Claude Team Standard | 23.4 M tokens | week | tracker | wokey.ai |
| Claude Team Standard | 20 USD of API value | 5h | tracker | wokey.ai |
| Claude Team Standard | 239 M tokens | week | tracker | wokey.ai |
| Claude Team Premium | 863 (830–906) USD of API value | week | tracker | wokey.ai |
| Claude Team Premium | 111 M tokens | week | tracker | wokey.ai |
| Claude Team Premium | 91 USD of API value | 5h | tracker | wokey.ai |
| Claude Team Premium | 1.07 B tokens | week | tracker | wokey.ai |
| Claude Max 20x | 300 M Haiku-4.5-input-equivalent… | 5h | user | zenn.dev |
| Claude Max 20x | 1.13 B Haiku-4.5-input-equivalent… | week | user | zenn.dev |
| Claude Max 20x | 544,000 Opus 5 uncached input tokens | 5h | user | zenn.dev |
| Claude Max 20x | 2.66 M output tokens | 5h | user | rhombus.so |
| Claude Max 20x | 66 USD of API value | 5h | user | rhombus.so |
| Claude Max 20x | 19.7 M output tokens | week | user | rhombus.so |
| Claude Max 20x | 492 USD of API value | week | user | rhombus.so |
| Claude Max 20x | 1,860 (1,740–2,200) USD of API value | week | user | finopsllm.com |
| Claude Max 20x (during 150% summer promo… | (2,085–2,379) USD of API value | week | user | finopsllm.com |
| Claude Max 5x | 1,217 USD of API value | week | user | finopsllm.com |
| Claude Max 5x | 37 USD of API value | 5h | user | finopsllm.com |
| Claude Max 20x | 2 B tokens | week | user | finopsllm.com |
| Claude Max 5x | (50–200) Claude Code prompts | 5h | vendor | github.com |
| Claude Max 5x | (15–35) hours of Opus 4 | week | vendor | github.com |
| Claude Max 20x | (200–800) Claude Code prompts | 5h | vendor | github.com |
| Claude Max 20x | (24–40) hours of Opus 4 | week | vendor | github.com |
| Claude Max 20x (incl. +50% weekly promo) | 1.41 B (1.41 B–1.42 B) TV | week | user | github.com |
| Claude Max 20x (incl. +50% weekly promo) | 7,059 USD of API value | week | user | github.com |
| Claude Max 5x (incl. +50% weekly promo) | 628 M (600 M–637 M) TV | week | user | github.com |
| Claude Max 5x (incl. +50% weekly promo) | 3,138 USD of API value | week | user | github.com |
| Claude Max 20x (user claims 20x not appl… | 1.25 B tokens | week | user | github.com |
| Claude Max 20x | 8,000 USD of API value | month | analyst | github.com |
| Claude Pro | 397 M tokens | week | tracker | github.com |
| Claude Pro | 1.59 B tokens | month | tracker | github.com |
| Claude Max 20x | 1.03 B raw tokens | 5h | user | github.com |
| Claude Max 20x | 31.5 B tokens | month | tracker | github.com |
OpenAI: ChatGPT plans for Codex
OpenAI, based in San Francisco, builds the GPT models and Codex, its coding agent. In June 2026 OpenAI reported more than 5 million weekly active Codex users. GPT-6 Astra and GPT-6.1 Sol need 1.5 B tokens per Terminal-Bench run, the fewest of any leading model.
What to know:
- Second-best multiple: ChatGPT Pro 500 buys 11x the tokens the same USD 500 buys on OpenAI's API at our mix, about 32 B a month on GPT-6.1 Sol (58.2%).
- Fewer tokens per task: GPT-6.1 Sol needs 1.5 B tokens per Terminal-Bench run against 8.0 B for Opus 5.5, so each plan token does more work than on Claude.
- Limits move without notice: SemiAnalysis measured Pro 200 at USD 5,904 of API value a month on the grandfathered 20x level and USD 2,084 on the new 10x level from 29 September 2026.
- Automation partly allowed: OpenAI recommends an API key for CI, but cached ChatGPT sign-in can be copied to headless or trusted CI runners. Training terms for Pro are not in sources; Plus is opt-out.
- Long-prompt metering open: SemiAnalysis totals match API value only at short-prompt prices, so it is open whether Codex meters prompts above 272k at the doubled rate. Our 305k average prompt sits there.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| ChatGPT Go | USD price not stated; INR 399/month … | not published | not stated (not published) |
| ChatGPT Plus | 20 | Est. per 5h: GPT-6 Astra 5-45; GPT-6.1 Sol 15-160; GPT-6 Sol 15-150; GPT-6 Luna 350-3,000 | 5h+week |
| ChatGPT Pro 100 | 100 | 5x Plus (up to 10x Plus for a limited time at launch, Apr 2026) | no 5h limit; other window not stated |
| ChatGPT Pro 200 | 200 | Included allowances are changing; amount not published | no 5h limit; other window not stated (not published) |
| ChatGPT Pro 500 | 500 | Highest included usage of Pro plans; amount not published | no 5h limit; other window not stated (not published) |
| Codex (via ChatGPT plan or API key) | No separate price; included in ChatGPT p… | Shares ChatGPT plan allowance; credit rates per 1M tokens published; typical GPT-5.6 Sol task 2-15 credits | as ChatGPT plan (not published) |
- Models: ChatGPT Go: GPT-6 Luna (Chat); Codex for lightweight coding tasks (Codex model list not stated); ChatGPT Plus, Codex (via ChatGPT plan or API key): GPT-6 Astra; GPT-6.1 Sol; GPT-6 Sol; GPT-6 Luna; GPT-5.6 Sol; GPT-5.6 Terra; GPT-5.6 Luna; ChatGPT Pro 100, ChatGPT Pro 200: GPT-6 Pro (ChatGPT); GPT-6 Astra (full allowance); GPT-6.1 Sol; no Ultrafast; ChatGPT Pro 500: GPT-6 Astra; GPT-6.1 Sol; incl. Ultrafast (8x Standard rate from included usage)
- Context: GPT-6.1 Sol 500K in Work and Codex (not per plan)
- Third-party tools: ChatGPT Go, ChatGPT Plus, ChatGPT Pro 100, ChatGPT Pro 200, ChatGPT Pro 500: Sign in with ChatGPT lets participating apps use plan allowance; supported open-source tools for all users; Codex (via ChatGPT plan or API key): Custom model providers supported (LLM proxy with OpenAI auth, env-key providers, local models)
- Automation: ChatGPT Go: Event-triggered Work tasks not available on Go; other rules not stated; ChatGPT Plus, ChatGPT Pro 100, ChatGPT Pro 200, ChatGPT Pro 500: API key recommended for CI/automation; cached ChatGPT auth can be copied to headless or trusted CI runners; Codex (via ChatGPT plan or API key): API key for CI; device-code login for headless; Codex SDK for programmatic control
- Training on your data: ChatGPT Plus: Yes unless opted out; ChatGPT Pro 100, ChatGPT Pro 200, ChatGPT Pro 500: not stated for Pro (Plus page: opt-out); Codex (via ChatGPT plan or API key): Depends on sign-in method; API key follows API org data-sharing settings
- At the limit: ChatGPT Go: Credits referenced for Free/Go; details not stated; ChatGPT Plus: Active turn finishes; buy credits; or extra local chats via API key at API rates; ChatGPT Pro 100, ChatGPT Pro 200: Buy additional credits (does not unlock Ultrafast); ChatGPT Pro 500: Buy credits; Ultrafast then draws credits at 6x Standard credit rate; Codex (via ChatGPT plan or API key): Buy credits (Plus/Pro) or use API key
Measured and stated limits (36 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| ChatGPT Plus | 92 (77–107) USD of API value | week | tracker | wokey.ai |
| ChatGPT Plus | 16 M tokens | week | tracker | wokey.ai |
| ChatGPT Plus | 222 M tokens | week | tracker | wokey.ai |
| ChatGPT Plus | 211 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Plus | 162 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Plus | 1 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 100 | 1,055 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 100 | 1,322 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 100 | 5.1 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 100 | 179 (103–237) USD of API value | week | user | finopsllm.com |
| ChatGPT Pro 100 | (3.31–3.77) USD of API value | week | user | inventivehq.com |
| ChatGPT Pro 200 (new 10x) | 650 (641–670) USD of API value | week | user | inventivehq.com |
| ChatGPT Pro 200 (new 10x) | 92 M counted tokens | week | user | inventivehq.com |
| ChatGPT Pro 200 (new 10x) | 2,084 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (new 10x) | 2,897 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (new 10x) | 10.2 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (new 10x) | 1.9 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (grandfathered 20x, unti… | 5,904 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (grandfathered 20x, unti… | 5,734 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 200 (grandfathered 20x, unti… | 19.6 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 500 | 6,955 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 500 | 5,386 USD of API value | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 500 | 26.3 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Pro 500 | 4.6 B tokens | month | analyst | newsletter.semianalysis.com |
| ChatGPT Plus | (5–45) local Codex messages | 5h | vendor | learn.chatgpt.com |
| ChatGPT Plus | (15–160) local Codex messages | 5h | vendor | learn.chatgpt.com |
| ChatGPT Plus | (15–150) local Codex messages | 5h | vendor | learn.chatgpt.com |
| ChatGPT Plus | (350–3,000) local Codex messages | 5h | vendor | learn.chatgpt.com |
| ChatGPT Plus | (15–90) local Codex messages | 5h | vendor | kingy.ai |
| ChatGPT Plus | (50–280) local Codex messages | 5h | vendor | kingy.ai |
| ChatGPT Plus | 15 USD of API value | 5h | tracker | wokey.ai |
| ChatGPT Plus | 154 M tokens | week | tracker | github.com |
| ChatGPT Plus | 616 M tokens | month | tracker | github.com |
| ChatGPT Pro 200 (20x, before 2026-09-29 … | 21,000 USD of GPT-5.6 Sol API lis… | month | analyst | github.com |
| ChatGPT Pro 200 | 500 USD of API value | week | user | community.openai.com |
| ChatGPT Pro 200 (earlier period) | 3,500 USD of API value | week | user | community.openai.com |
- No measurement found: ChatGPT Go.
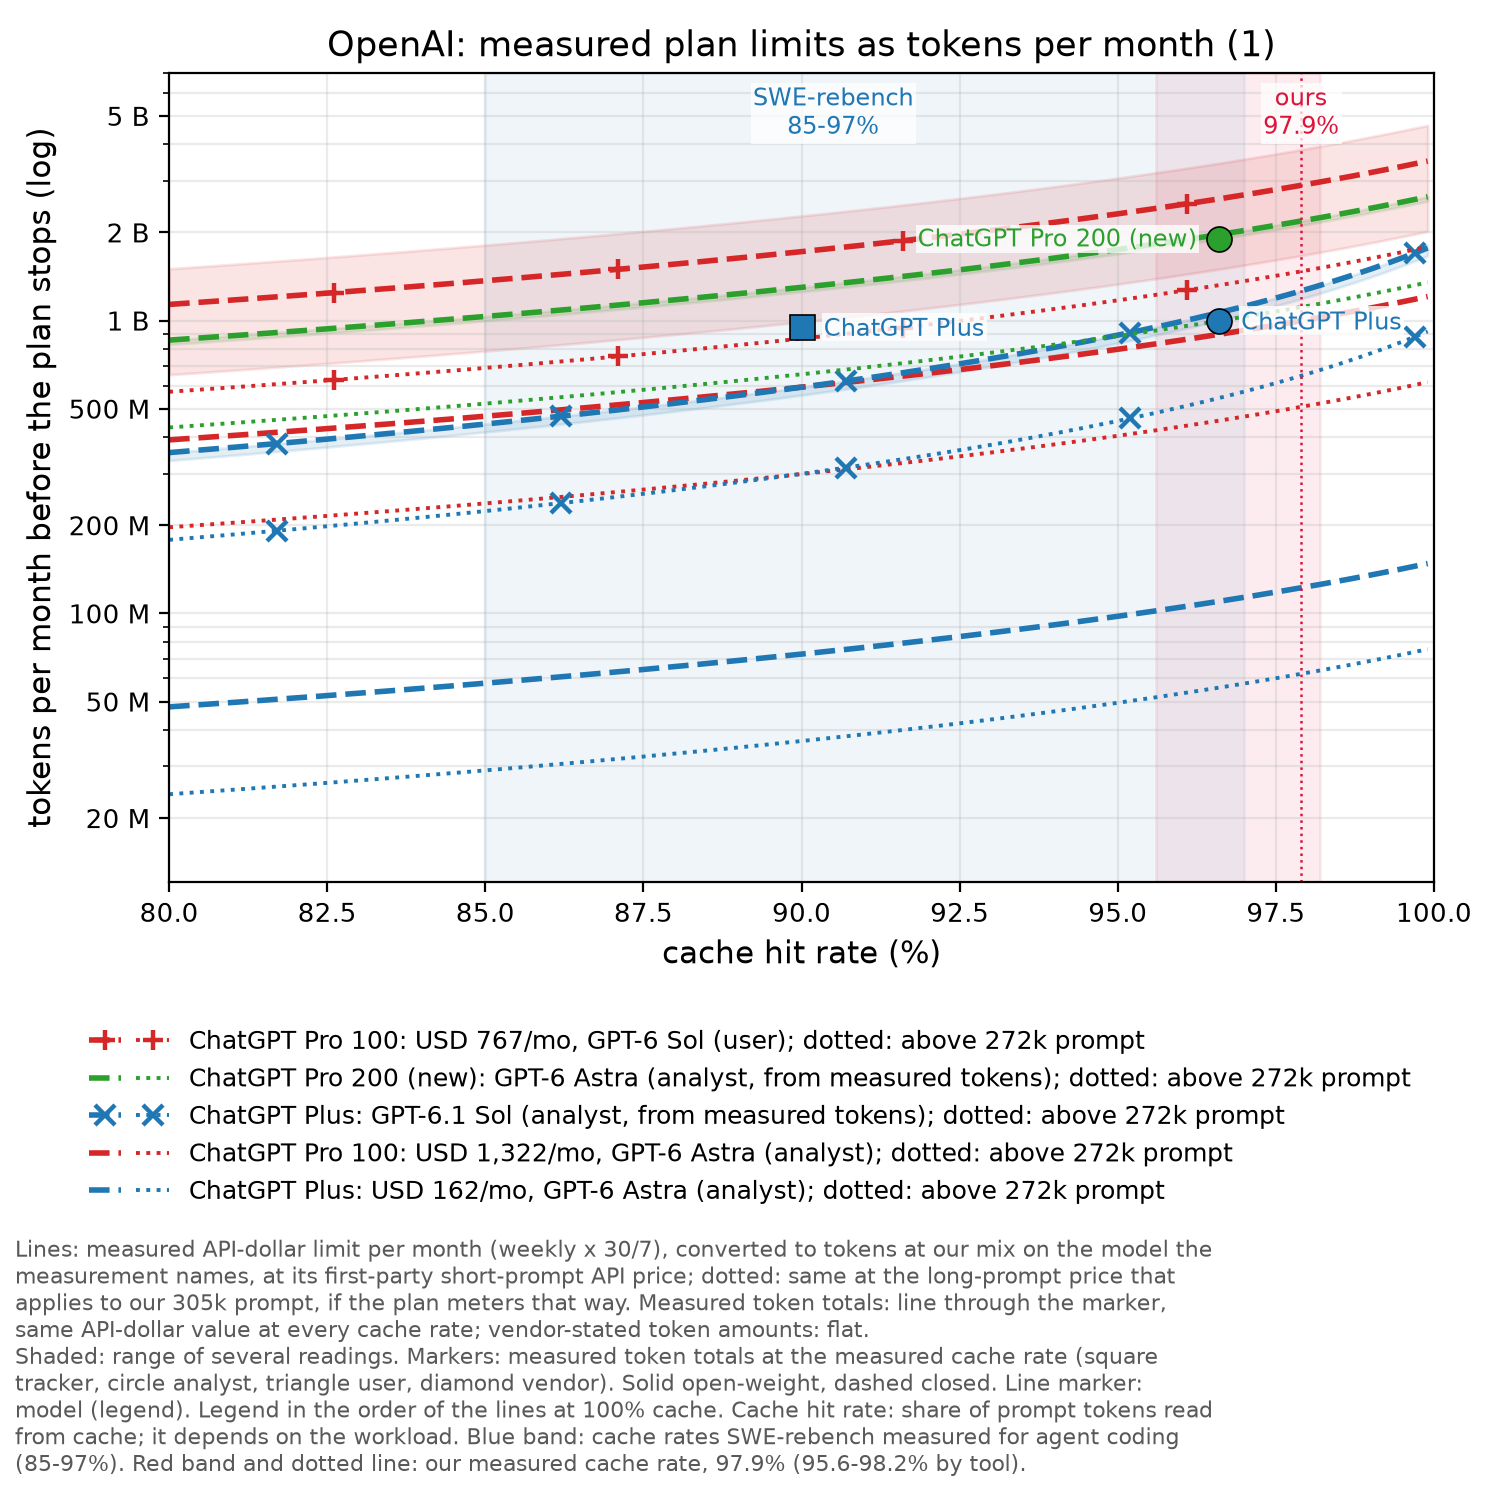
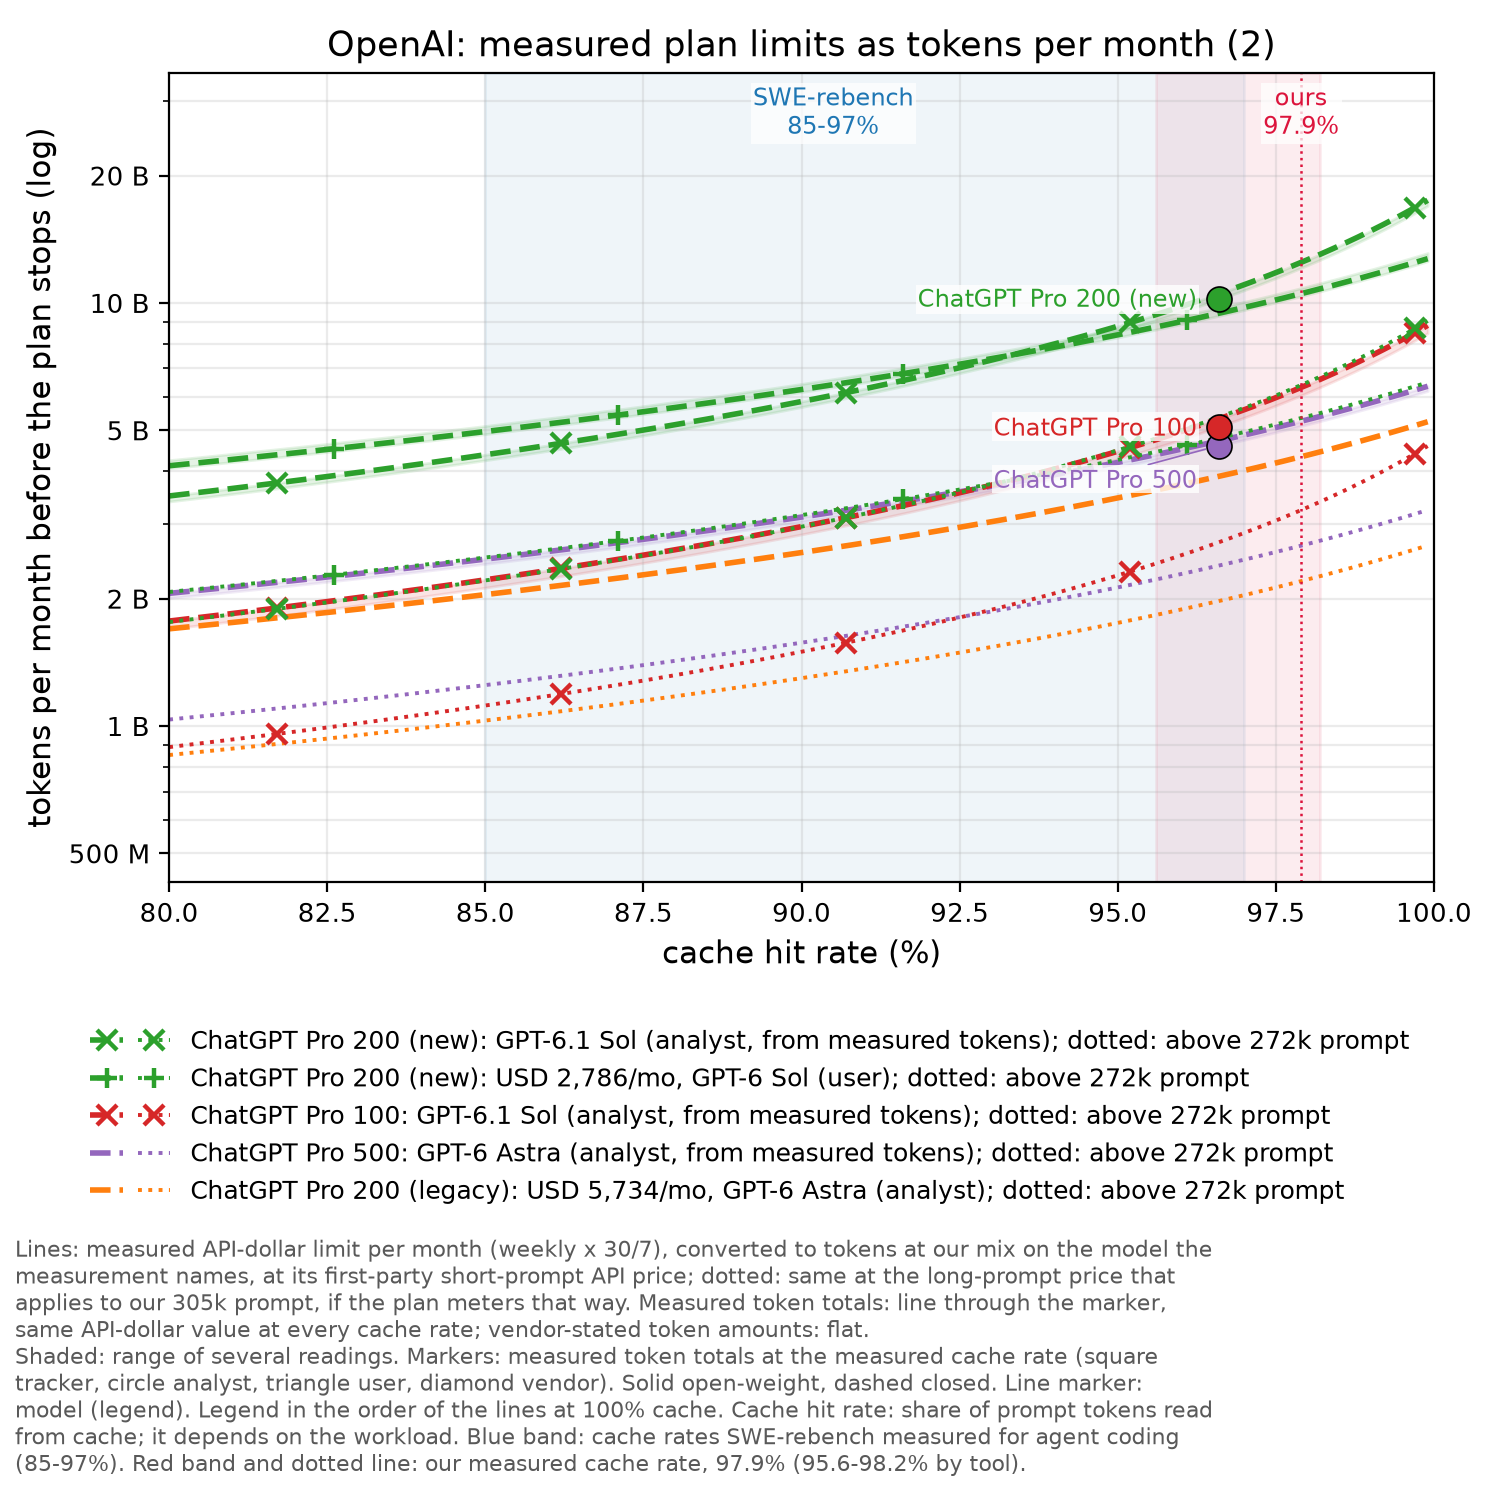
One analyst reading puts ChatGPT Pro 200 (legacy) at 19.6 B tokens a month (GPT-6 Sol only, agentic, 96.6% cache). One analyst reading puts ChatGPT Pro 500 at 26.3 B tokens a month (GPT-6.1 Sol only, agentic, 96.6% cache).
MiniMax: coding plans
MiniMax is a Chinese model developer founded in 2022. It sells its M-series models by the token, describes its current M3 model as open-weight with a full release on Hugging Face and GitHub announced, and offers a Token Plan from $22 a month that covers third-party coding tools and its own MiniMax Code agent. It listed in Hong Kong on 9 January 2026 after raising about HK$4.8 billion ($620 million).
What to know:
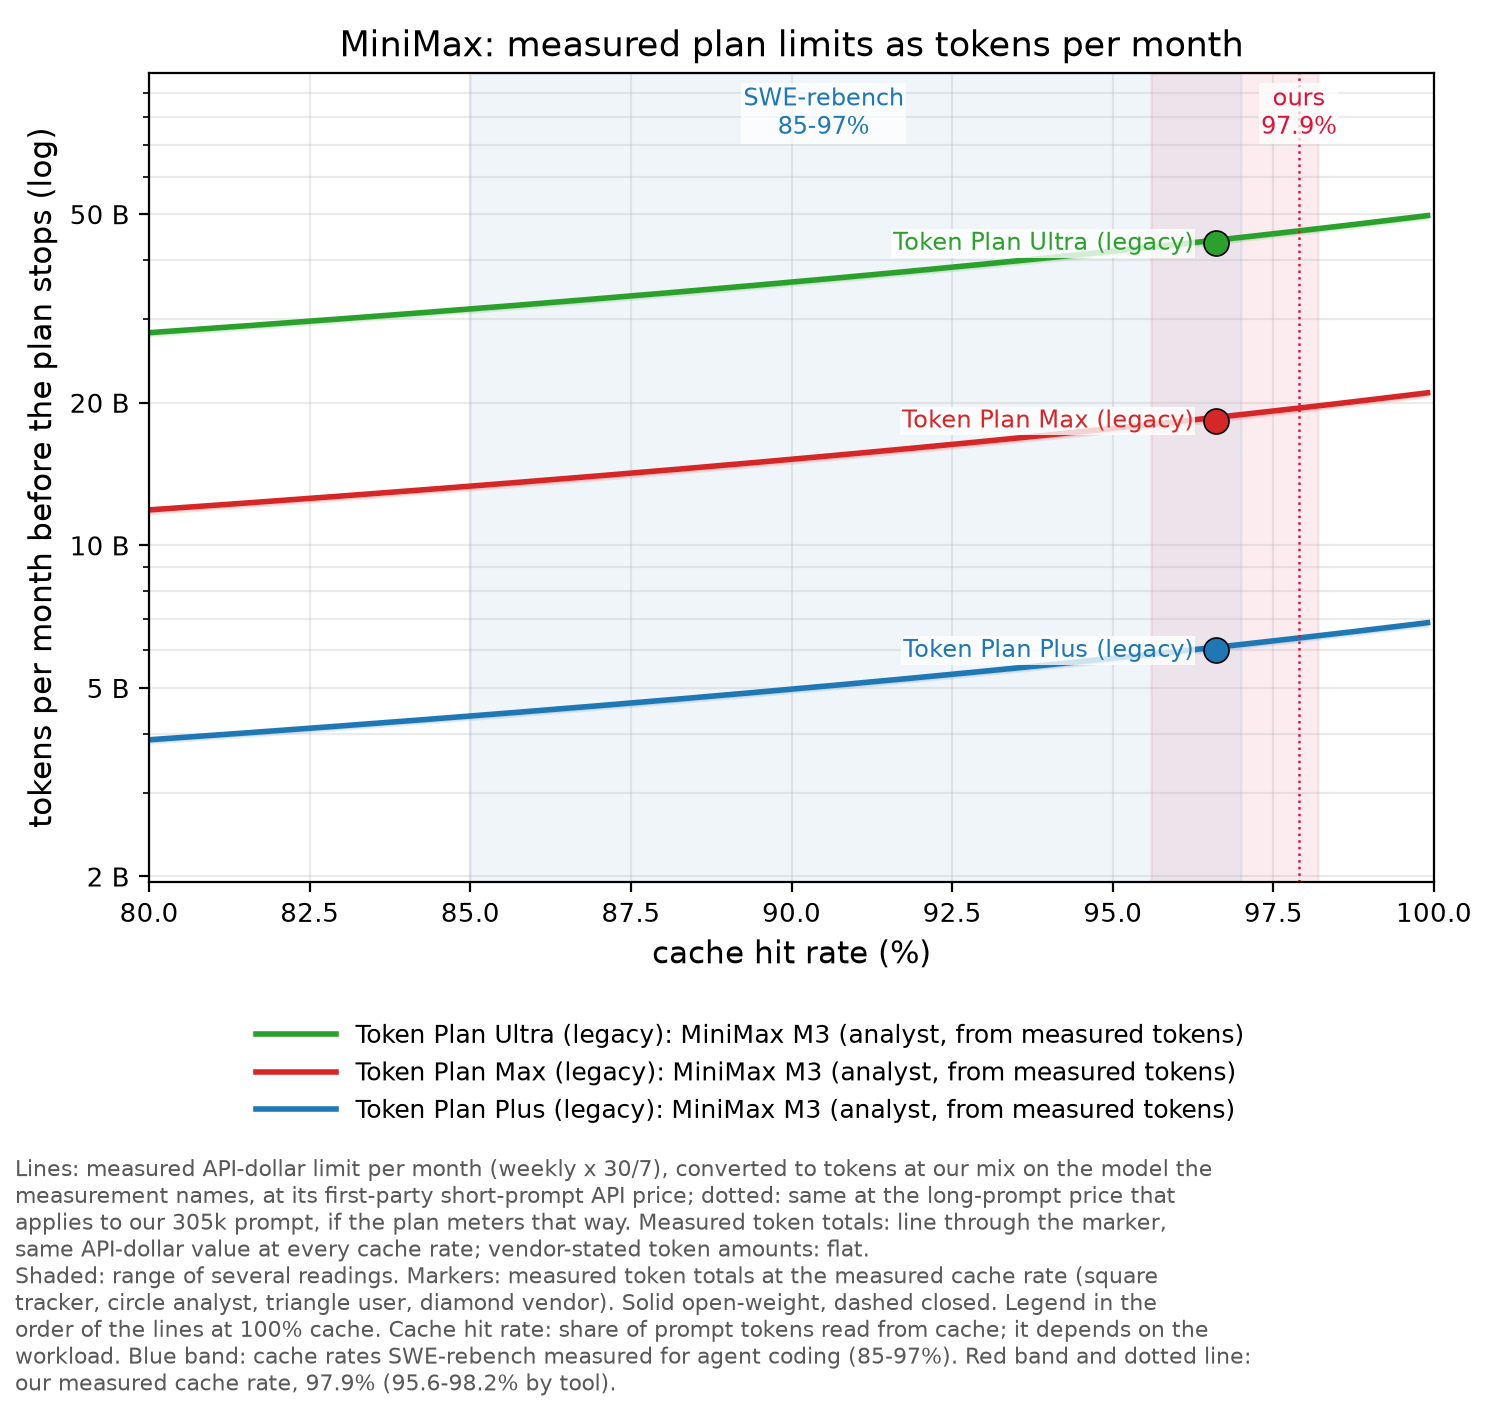
- Largest open-model multiple: Token Plan Ultra (USD 120) buys 4.4x the tokens of the cheapest MiniMax M3 API offer at our mix, about 9.8 B a month, a vendor-published figure.
- Cheap tokens, weak model: MiniMax M3 scores 2% on Terminal-Bench 4.0 against 66.0 its maker reports on version 2.1. GPT-6 Luna is stronger and cheaper per token.
- Counts raw tokens: The plan meters tokens, not API dollars, so its lead grows at lower cache: 6.4x at 85%, 4.2x at 99%.
- Analyst reads higher: SemiAnalysis measured 43.4 B tokens a month on legacy Ultra (USD 132), against the vendor's 9.8 B. Plan on the vendor figure.
- Terms mostly unstated: Token Plan rules on third-party tools, training and the limit are not in sources. The new M Plan publishes only multiples of Go (3x, 7.5x).
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| M Plan Go | price not stated; yearly: pay 10 mon… | 1x (baseline); absolute not published | 5h+week (not published) |
| M Plan Explore | price not stated; yearly: pay 10 mon… | 3x Go; absolute not published | 5h+week (not published) |
| M Plan Build | price not stated; yearly: pay 10 mon… | 7.5x Go; absolute not published | 5h+week (not published) |
| Token Plan Plus | 20 | ~1.7B per month (M3) | month |
| Token Plan Max | 50 | ~5.1B per month (M3) | month |
| Token Plan Ultra | 120 | ~9.8B per month (M3) | month |
- Models: M Plan Go, M Plan Explore, M Plan Build: M3.1 Flash Preview (text); no video model; Token Plan Plus: M3; Token Plan Max: M3; Token Plan Ultra: M3
- Context: not stated (M3 model up to 1M, not stated as plan limit)
- Third-party tools: M Plan Go, M Plan Explore, M Plan Build: yes: any OpenAI/Anthropic-compatible tool, e.g. Claude Code, Codex, Cursor, OpenCode, Hermes Agent, OpenClaw; MiniMax Code included; Token Plan Plus, Token Plan Max, Token Plan Ultra: not stated (MiniMax Code usable)
- Automation: individual interactive developer use; pay-as-you-go recommended for production; RPM/TPM throttling
- At the limit: M Plan Go, M Plan Explore, M Plan Build: credit packs used next (1,000 Credits = $1); else upgrade, wait for reset or PAYG key; no balance charge; no carry-over; Token Plan Plus, Token Plan Max, Token Plan Ultra: not stated; can upgrade to M Plan with unused value credited
Measured and stated limits (17 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| M Plan Go (CN ¥49) | 24 M tokens consumed while 5h m… | 5h | tracker | github.com |
| M Plan Go | – same text usage as legacy… | month | vendor | platform.minimax.io |
| M Plan Explore | 3 x Go usage | – | vendor | platform.minimax.io |
| M Plan Build (global) | 7.5 x Go usage | – | vendor | platform.minimax.io |
| M Plan Build (CN) | 12 x Go usage | – | vendor | platform.minimax.cn |
| Token Plan Plus (legacy, $22) | 427 USD of API value | month | analyst | newsletter.semianalysis.com |
| Token Plan Plus (legacy, $22) | 6 B tokens | month | analyst | newsletter.semianalysis.com |
| Token Plan Plus (legacy, $22) | 1.7 B tokens | month | vendor | platform.minimax.io |
| Token Plan Max (legacy, $55) | 1,305 USD of API value | month | analyst | newsletter.semianalysis.com |
| Token Plan Max (legacy, $55) | 18.3 B tokens | month | analyst | newsletter.semianalysis.com |
| Token Plan Max (legacy, $55) | 5.1 B tokens | month | vendor | platform.minimax.io |
| Token Plan Ultra (legacy, $132) | 3,088 USD of API value | month | analyst | newsletter.semianalysis.com |
| Token Plan Ultra (legacy, $132) | 43.4 B tokens | month | analyst | newsletter.semianalysis.com |
| Token Plan Ultra (legacy, $132) | 9.8 B tokens | month | vendor | platform.minimax.io |
| Token Plan Starter (legacy, $10) | 3 M tokens | 5h | user | reddit.com |
| Token Plan Plus (legacy) | 4,500 requests | 5h | user | reddit.com |
| Token Plan Max (legacy) | 260 M tokens | 5h | user | reddit.com |
- No measurement found: M Plan Go/Explore/Build; Token Plan Plus/Max/Ultra.
Moonshot AI: Kimi Code plans
Moonshot AI is a Beijing-based model developer founded in spring 2023. It releases the Kimi models, including the open-weight Kimi K3 (July 2026), sells access through its developer platform, and includes the Kimi Code desktop app, command-line tool and VS Code extension in its Kimi membership. In September 2026 it filed confidentially for a Hong Kong listing.
What to know:
- Cheap plan, weak model: Ultra (USD 199) buys 3.5x the tokens of the cheapest Kimi K3 API offer, but K3 scores 12.6% on Terminal-Bench 4.0, below GPT-6 Luna (16.4%).
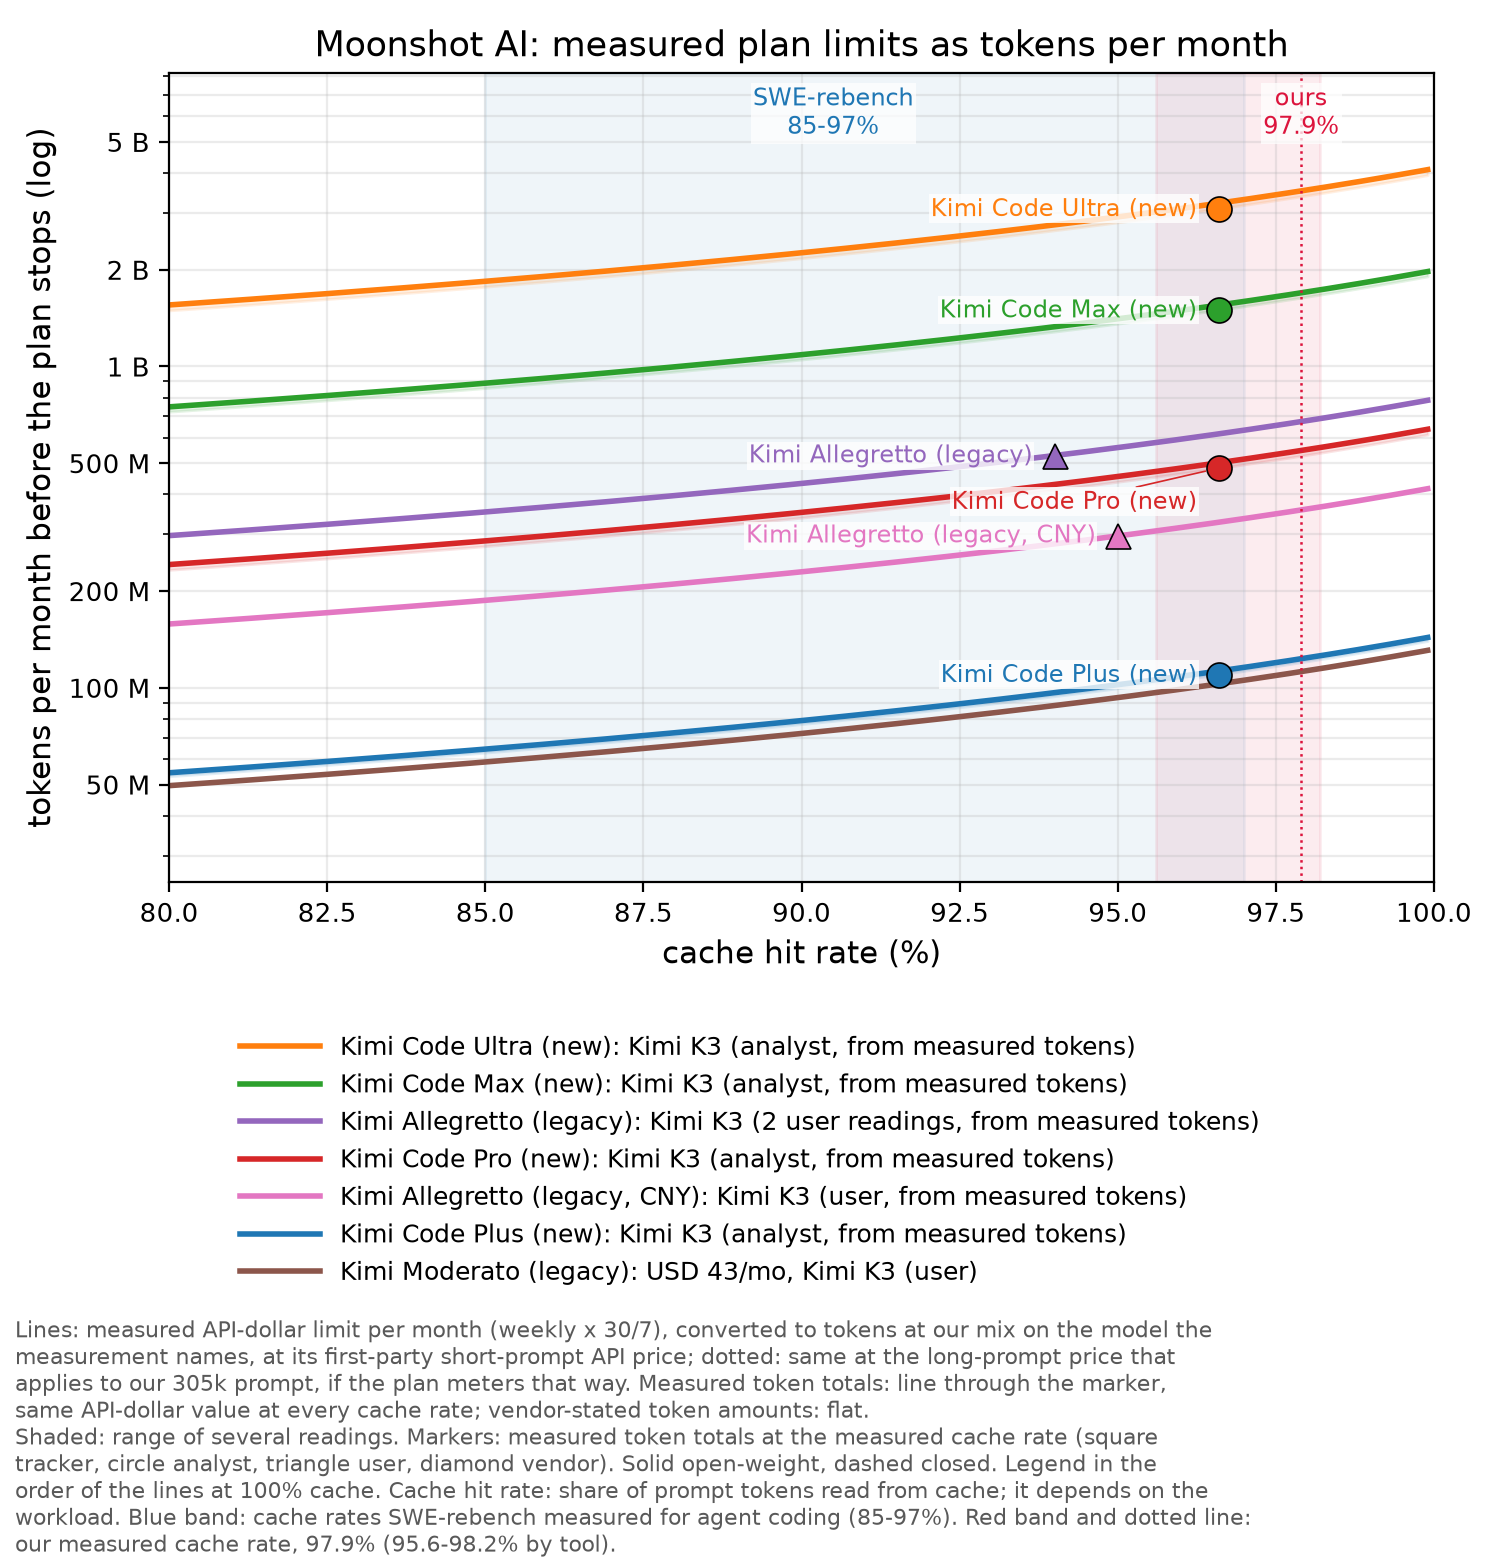
- Measured, tiers just changed: Moonshot publishes no limits. SemiAnalysis measured Ultra at 3.1 B tokens a month after the October change; most other readings cover the legacy Allegretto and Allegro tiers.
- Interactive only: Claude Code, OpenCode and Codex are allowed, but scripted batch use, pipelines, resale and User-Agent spoofing are not. Up to 5 API keys.
- Cache-sensitive lead: The multiple falls to 2.2x at 85% cache and rises to 3.8x at 99%, so short sessions erode most of the advantage.
- Soft stop in CNY: Kimi Code freezes at the monthly total; optional Extra Usage bills pay as you go in CNY, from a CNY 25 top-up.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Adagio (USD, free) | 0 | not published | none (not published) |
| Plus (USD) | 19 | not published | mixed (not published) |
| Pro (USD) | 39 | not published | mixed (not published) |
| Max (USD) | 99 | not published | mixed (not published) |
| Ultra (USD) | 199 | not published | mixed (not published) |
| Go (CNY) | CNY 49/month; CNY 468/year (CNY 39/month… | not published | none (not published) |
| Plus (CNY) | CNY 99/month; CNY 948/year (CNY 79/month… | not published | mixed (not published) |
| Pro (CNY) | CNY 199/month; CNY 1,908/year (CNY 159/m… | not published | mixed (not published) |
| Max (CNY) | CNY 699/month; CNY 6,708/year (CNY 559/m… | not published | mixed (not published) |
| Andante (legacy) | price not stated; legacy plan, exist… | not published | mixed (not published) |
| Moderato (legacy) | price not stated; legacy plan | not published | mixed (not published) |
| Allegretto (legacy) | price not stated; legacy plan | not published | mixed (not published) |
| Allegro (legacy) | price not stated; legacy plan | not published | mixed (not published) |
- Models: k3; k3-256k; kimi-for-coding; kimi-for-coding-highspeed (K2.7 Code HighSpeed) (Ultra not named in docs; 'Pro and above')
- Context: Plus (USD), Pro (USD), Max (USD), Plus (CNY), Pro (CNY), Max (CNY), Andante (legacy), Moderato (legacy), Allegretto (legacy), Allegro (legacy): k3 and kimi-for-coding 1,048,576 per Kimi Code docs; pricing page lists 1M only for Max/Ultra (conflict); Ultra (USD): 1M
- Third-party tools: Plus (USD), Pro (USD), Max (USD), Ultra (USD), Plus (CNY), Pro (CNY), Max (CNY), Andante (legacy), Moderato (legacy), Allegretto (legacy), Allegro (legacy): yes: Kimi CLI, VS Code, Claude Code, OpenCode, OpenClaw, Codex etc.; no User-Agent spoofing; Go (CNY): not applicable (no Kimi Code)
- Automation: interactive use only; no scripted batch or annotation pipelines; no resale; up to 5 API keys
- At the limit: Kimi Code frozen at monthly total; 5h window rate-limits then recovers; optional Extra Usage (pay as you go, RMB); no rollover; Extra Usage min CNY 25 top-up, CNY 10,000 balance cap
Measured and stated limits (56 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Kimi Code Plus (USD, new plan) | 47 USD of API value | month | analyst | newsletter.semianalysis.com |
| Kimi Code Plus (USD, new plan) | 110 M tokens | month | analyst | newsletter.semianalysis.com |
| Kimi Code Pro (USD, new plan) | 209 USD of API value | month | analyst | newsletter.semianalysis.com |
| Kimi Code Pro (USD, new plan) | 483 M tokens | month | analyst | newsletter.semianalysis.com |
| Kimi Code Max (USD, new plan) | 647 USD of API value | month | analyst | newsletter.semianalysis.com |
| Kimi Code Max (USD, new plan) | 1.5 B tokens | month | analyst | newsletter.semianalysis.com |
| Kimi Code Ultra (USD, new plan) | 1,343 USD of API value | month | analyst | newsletter.semianalysis.com |
| Kimi Code Ultra (USD, new plan) | 3.1 B tokens | month | analyst | newsletter.semianalysis.com |
| Kimi Go (CNY, new plan) | 0 Kimi Code quota | month | vendor | kimi.com |
| Kimi Plus (CNY ¥99, new plan) | 3 M tokens | 5h | user | linux.do |
| Kimi Plus (CNY ¥99, new plan) | 2.2 M tokens = 61% of one 5h win… | 5h | user | blog.margrop.net |
| Kimi Pro (CNY ¥199, new plan) | 2.5 M tokens | 5h | user | blog.margrop.net |
| Kimi Pro (CNY ¥199, new plan) | 26 M tokens | month | user | blog.margrop.net |
| Kimi Max (CNY ¥699, new plan) | 8 M tokens | 5h | user | blog.margrop.net |
| Kimi Max (CNY ¥699, new plan) | 1 single task exhausts the 5… | 5h | user | reddit.com |
| Kimi Allegretto (legacy, CNY ¥199) | 13.8 M tokens | 5h | user | linux.do |
| Kimi Allegretto (legacy, CNY ¥199) | 69.3 M tokens | week | user | linux.do |
| Kimi Allegretto (legacy, CNY ¥199) | 10 USD of API value | 5h | user | linux.do |
| Kimi Allegretto (legacy, CNY ¥199) | 340 M tokens | week | user | linux.do |
| Kimi Allegretto (legacy, CNY ¥199) | 63.7 M tokens | 5h | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 22.6 M tokens consumed = 34.07% o… | 5h | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 37 M tokens | 5h | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 9.17 M tokens consumed = 10% of w… | week | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 29 (28–30) USD of API value | 5h | user | forum.moonshot.ai |
| Kimi Allegretto (legacy, CNY ¥199) | 4 M input tokens | 5h | user | forum.moonshot.ai |
| Kimi Allegretto (legacy, CNY ¥199) | 5 M uncached input tokens | week | user | forum.moonshot.ai |
| Kimi Allegretto (legacy, international U… | 60 USD of API value | week | user | reddit.com |
| Kimi Allegretto (legacy, international U… | 123 M tokens | week | user | reddit.com |
| Kimi Allegretto (legacy, CNY ¥199) | 33 M tokens | 5h | user | linux.do |
| Kimi Allegretto (legacy, CNY ¥199) | 290 M tokens | week | tracker | github.com |
| Kimi Allegretto (legacy, CNY ¥199) | 30 M tokens | 5h | tracker | github.com |
| Kimi Allegro (legacy, CNY ¥699) | 46.3 M tokens | 5h | user | forum.moonshot.ai |
| Kimi Allegro (legacy, CNY ¥699) | 80 M tokens | 5h | tracker | github.com |
| Kimi Allegro (legacy, CNY ¥699) | 169 M tokens | week | analyst | v2ex.com |
| Kimi Allegro (legacy, CNY ¥699) | 1.94 B tokens used in 30 days | month | user | v2ex.com |
| Kimi Allegro (legacy, international USD) | – Kimi Code 15x | month | vendor | reddit.com |
| Kimi Moderato (legacy, CNY ¥99) | 133,922 tokens consumed = 22% of o… | 5h | user | v2ex.com |
| Kimi Moderato (legacy, international USD… | 10 USD of API value | week | user | reddit.com |
| Kimi Allegretto (legacy, CNY ¥199) | 32 M tokens | 5h | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 164 M tokens | week | user | v2ex.com |
| Kimi Allegretto (legacy, CNY ¥199) | 660 M tokens | month | user | v2ex.com |
| Kimi Moderato (legacy, CNY ¥99) | 3 architecture questions exh… | 5h | user | v2ex.com |
| Kimi Andante (legacy, CNY ¥49) | 3.8 M tokens | 5h | user | owent.net |
| Kimi Andante (legacy, CNY ¥49) | 86 requests | 5h | user | owent.net |
| Kimi Andante (legacy, CNY ¥49) | 18 M tokens | week | user | owent.net |
| Kimi Andante (legacy, CNY ¥49) | 411 requests | week | user | owent.net |
| Kimi Moderato (legacy, CNY ¥99) | 34 M tokens | 5h | user | owent.net |
| Kimi Moderato (legacy, CNY ¥99) | 600 requests | 5h | user | owent.net |
| Kimi Moderato (legacy, CNY ¥99) | 158 M tokens | week | user | owent.net |
| Kimi Moderato (legacy, CNY ¥99) | 2,820 requests | week | user | owent.net |
| Kimi Allegretto (legacy, CNY ¥199) | 101 M tokens | 5h | user | owent.net |
| Kimi Allegretto (legacy, CNY ¥199) | 1,100 requests | 5h | user | owent.net |
| Kimi Allegretto (legacy, CNY ¥199) | 466 M tokens | week | user | owent.net |
| Kimi Allegretto (legacy, CNY ¥199) | 5,020 requests | week | user | owent.net |
| Kimi Code (legacy tiers, no per-tier map… | (300–1,200) requests | 5h | vendor | kingy.ai |
| Kimi Moderato (legacy, international USD… | 60 agent credits | – | vendor | threatfrontier.com |
- No measurement found: Kimi Adagio (free).
GitHub Copilot
GitHub Copilot is the AI coding assistant of GitHub, the Microsoft-owned code-hosting platform. It covers code completion, chat, a command-line interface (CLI) and a cloud agent. Since 1 June 2026 every plan, from Pro at $10 to Max at $100 a month, is billed in GitHub AI Credits at each model's application programming interface (API) token rates. Microsoft reported 50 million Copilot users on 29 July 2026.
What to know:
- Credits at API rates: Since 1 June 2026 credits bill at each model's API rate. Max (USD 100) gives 20,000 credits worth USD 200, so 2x the API on Opus 5.5.
- Small absolute volume: Copilot Max converts to 0.6 B Opus 5.5 tokens a month at our mix, against 35 B on Claude Max 20x for USD 200.
- Agents and automation included: Copilot CLI and cloud agent are included, Claude and Codex agents run on the subscription, and machine accounts are permitted.
- Training is opt-out: Individual subscribers' data trains unless you opt out. Business (USD 19) and Enterprise (USD 39) seats pool 1,900 and 3,900 credits per seat.
- Startup credit: GitHub for Startups gives USD 10,000 for 12 months, premium models included.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Copilot Pro | 10 | 1500 (1,000 base + 500 flex); 1 credit = USD 0.01 | month |
| Copilot Pro+ | 39 | 7000 (3,900 base + 3,100 flex); 1 credit = USD 0.01 | month |
| Copilot Max | 100 | 20000 (10,000 base + 10,000 flex); 1 credit = USD 0.01 | month |
- Models: Copilot Pro: A selection of models (per-tier list not stated); Copilot Pro+: Premium models incl. Opus; GPT-5.4 nano (Codex VS Code extension only); Copilot Max: Priority access to premium models
- Third-party tools: Third-party agents (Claude agent, Codex agent) powered by subscription; Sign in with Copilot in Codex VS Code is Pro+/Max only
- Automation: Copilot Pro, Copilot Pro+: Copilot CLI and cloud agent included; ToS bans bot-registered accounts, permits machine accounts; Copilot Max: Built for sustained agent-driven workflows; ToS machine-account rules
- Training on your data: Yes for individual subscribers unless opted out (conflict: one FAQ line names only Free, Pro, Pro+)
- At the limit: Upgrade, set additional-usage budget (may be capped), or wait for monthly reset
Tokens per month at our mix; one credit pool shared by all models (1 credit = USD 0.01): each line assumes all use on that model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Copilot Pro (USD 10) | Copilot Pro+ (USD 39) | Copilot Max (USD 100) |
|---|---|---|---|---|---|---|---|
| Claude Opus 5.5 | no | 400 / 20 / 2,000 | 1M | 64.8 | 0.04 B | 0.21 B | 0.60 B |
| Claude Sonnet 5.5 | no | 200 / 10 / 1,000 | 1M | 61.8 | 0.09 B | 0.42 B | 1.20 B |
| GPT-6.1 Sol (above 272k prompt) | no | 400 / 20 / 1,500 | 1.1M | 58.2 | 0.05 B | 0.21 B | 0.61 B |
| GPT-6 Astra (above 272k prompt) | no | 2,000 / 200 / 7,500 | 1.1M | 58.2 | 0.01 B | 0.03 B | 0.08 B |
| Claude Fable 5.1 | no | 1,000 / 25 / 5,000 | 1M | 57.9 | 0.03 B | 0.12 B | 0.34 B |
| Gemini 4 Argon | no | 200 / 10 / 1,000 | 1M | 57.1 | 0.10 B | 0.45 B | 1.28 B |
| GPT-6 Sol (above 272k prompt) | no | 400 / 40 / 1,500 | 1.1M | 49.4 | 0.03 B | 0.13 B | 0.38 B |
| Claude Haiku 5.5 (above 100k prompt) | no | 50 / 5 / 250 | 1M | 39.2 (vendor) | 0.23 B | 1.06 B | 3.02 B |
| Grok 4.7 (above 200k prompt) | no | 400 / 100 / 1,200 | 500k | 37.6 | 0.01 B | 0.06 B | 0.18 B |
| Gemini 3.8 Flash | no | 75 / 7.5 / 375 | 1M | 19.1 | 0.16 B | 0.73 B | 2.10 B |
| GPT-6 Luna (above 272k prompt) | no | 20 / 2 / 75 | 1.1M | 16.4 | 0.58 B | 2.69 B | 7.67 B |
| Kimi K3 | yes | 300 / 30 / 1,500 | 1M | 12.6 | 0.04 B | 0.18 B | 0.52 B |
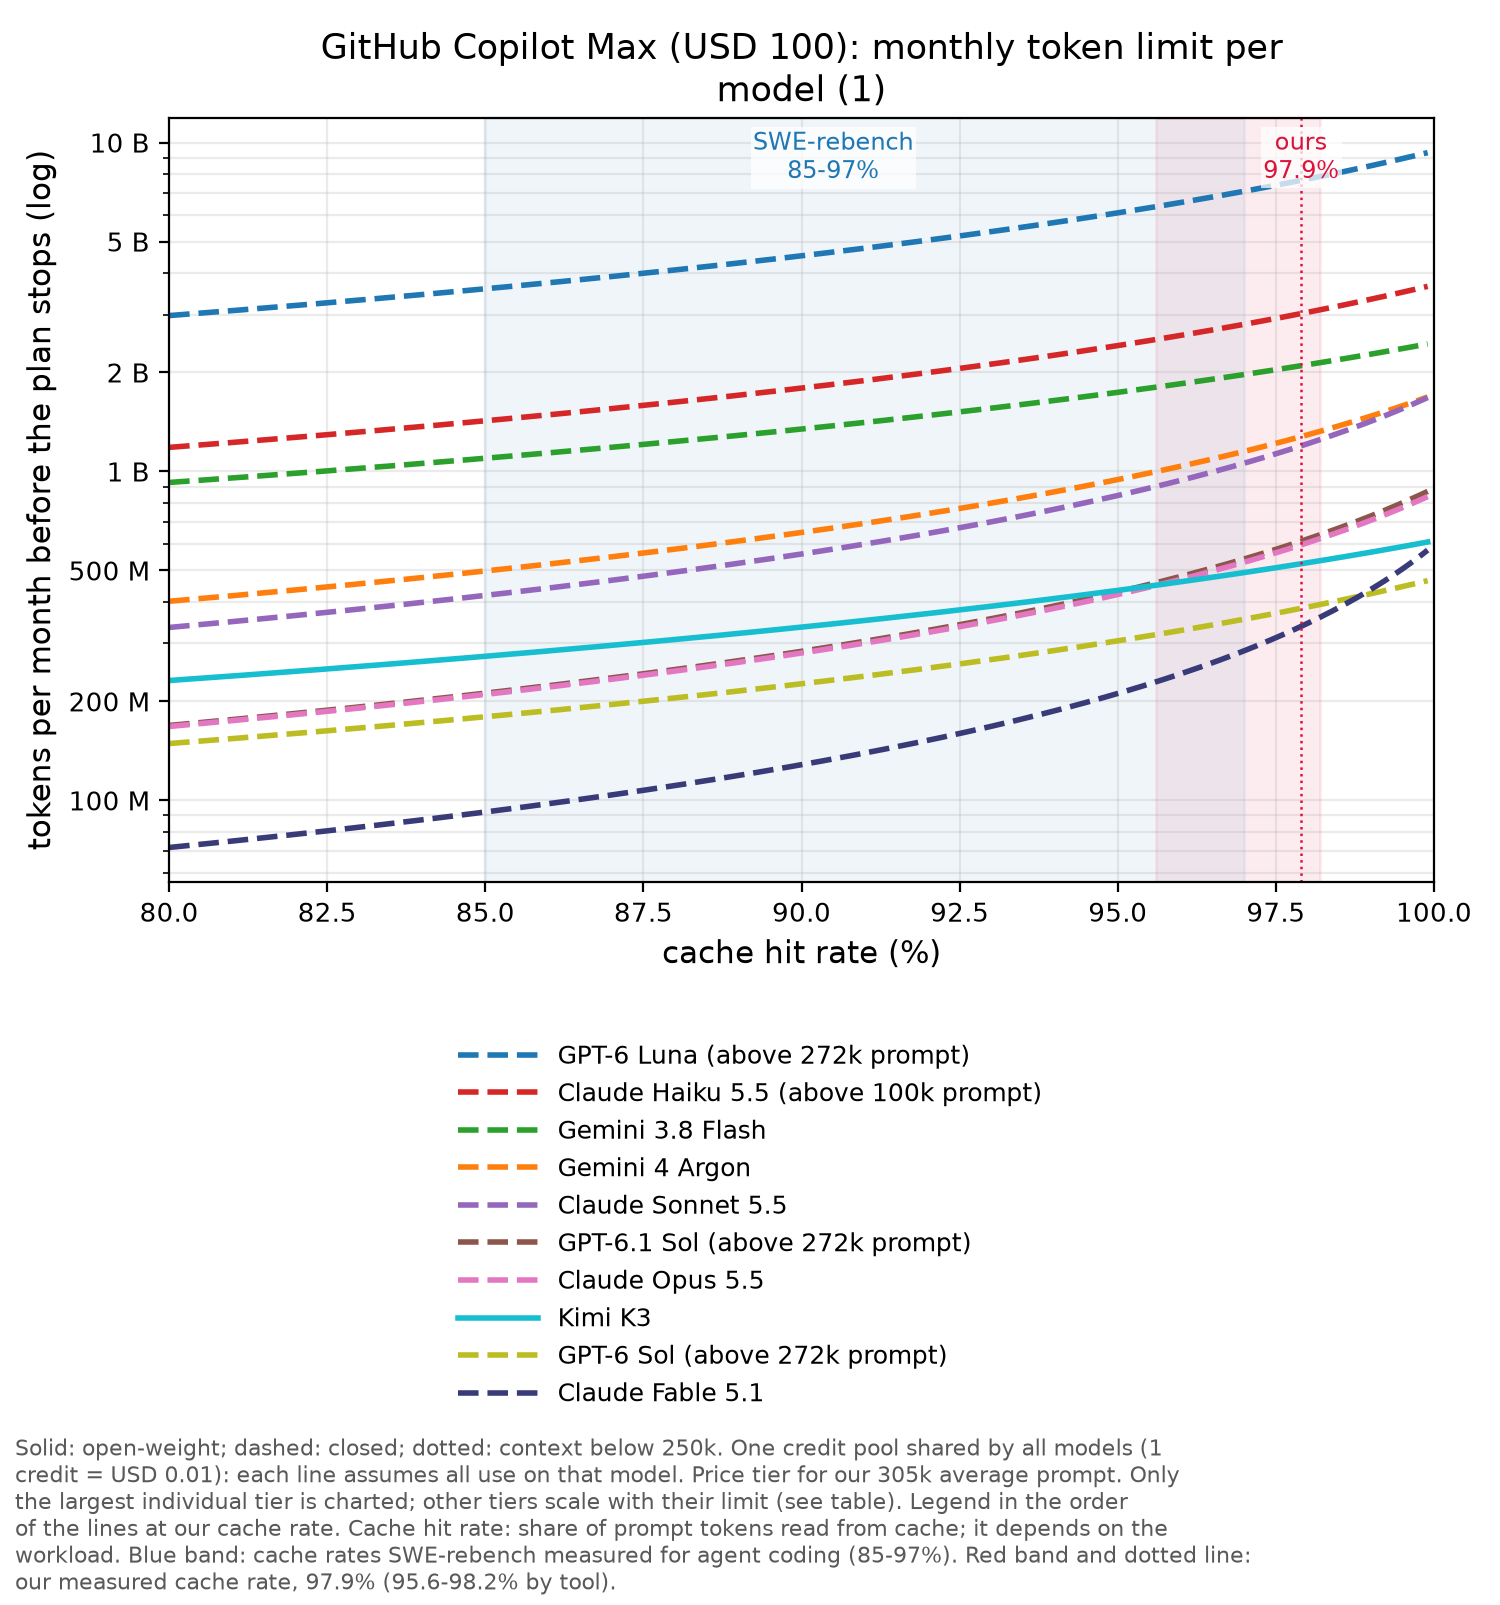
At our mix Copilot Max (USD 100) allows 0.18 B tokens a month on Grok 4.7 (above 200k prompt) (0.14 to 0.19 B at 85-99% cache). At our mix Copilot Max (USD 100) allows 0.08 B tokens a month on GPT-6 Astra (above 272k prompt) (0.04 to 0.08 B at 85-99% cache).
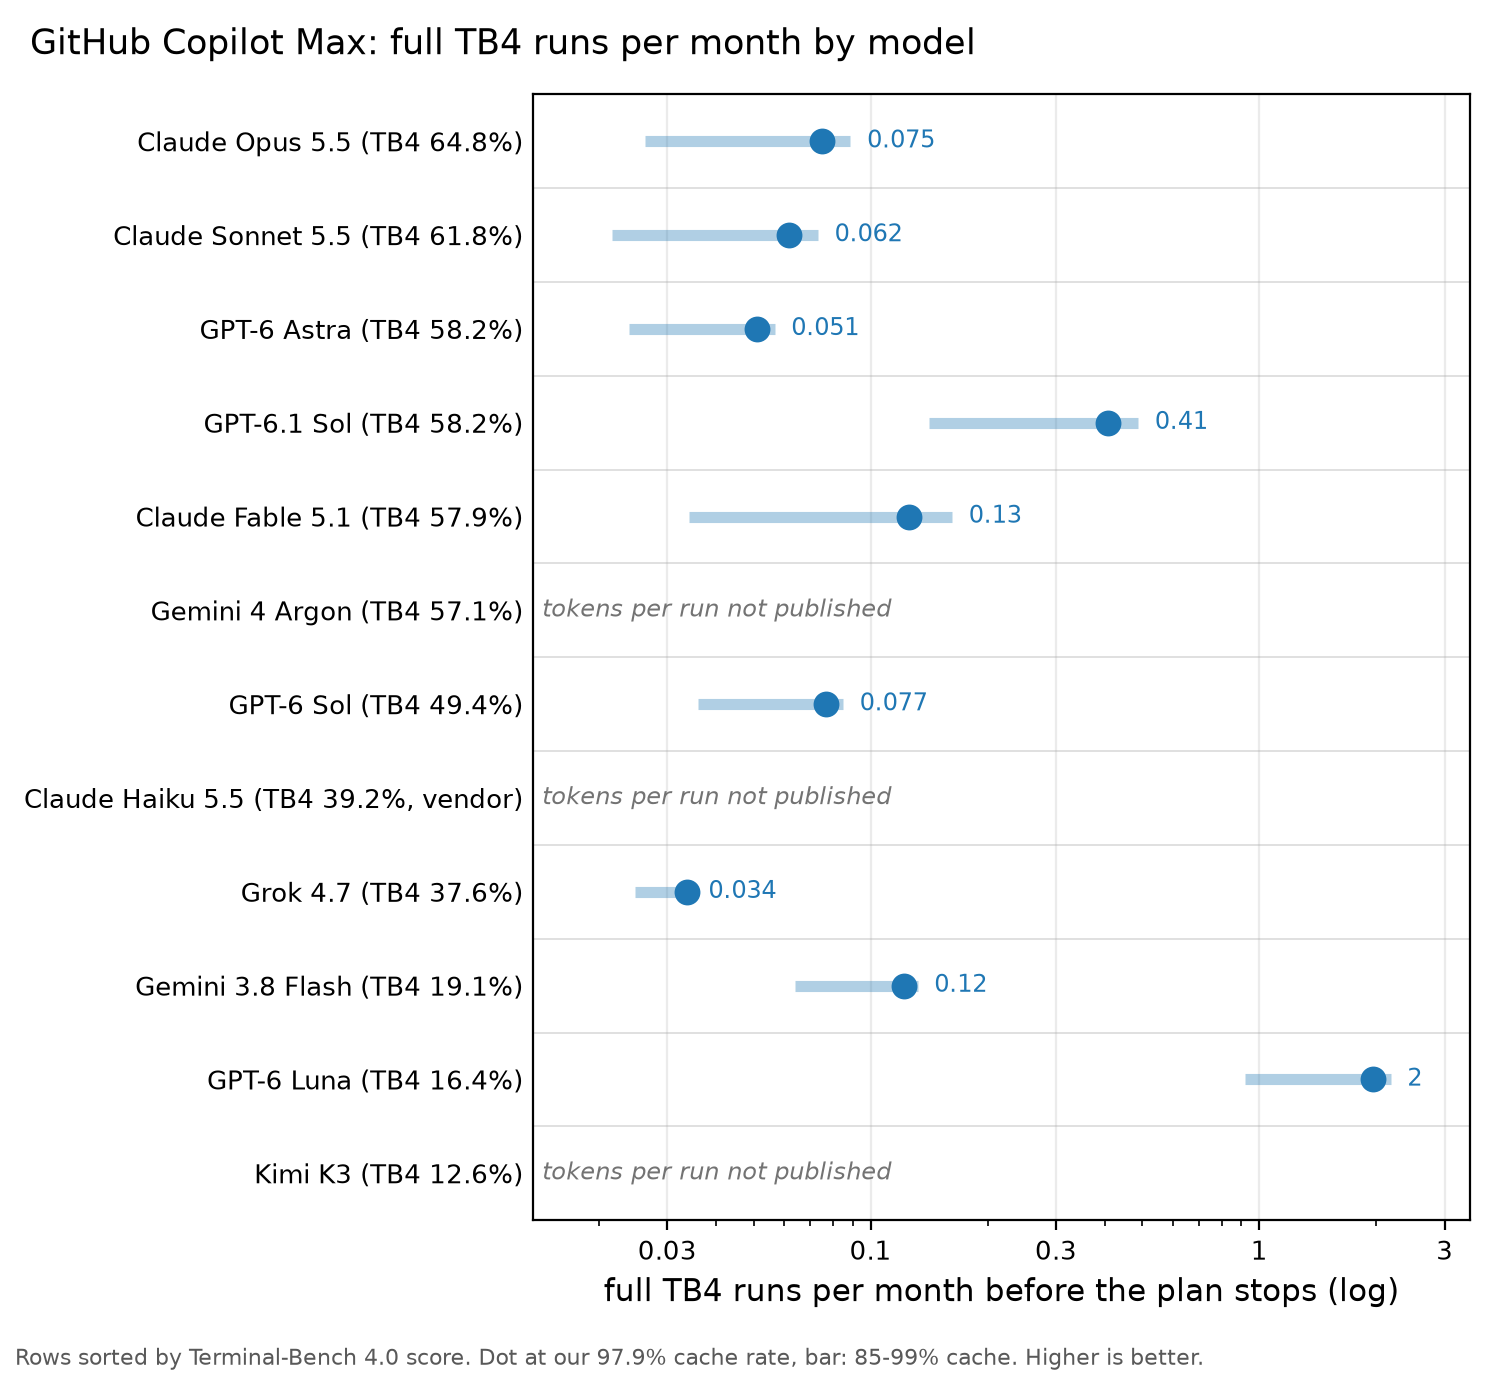
Measured and stated limits (14 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Copilot Pro | 1,500 AI credits | month | vendor | threatfrontier.com |
| Copilot Pro | 15 USD | month | vendor | threatfrontier.com |
| Copilot Pro+ | 7,000 AI credits | month | vendor | threatfrontier.com |
| Copilot Pro+ | 70 USD | month | vendor | threatfrontier.com |
| Copilot Max | 20,000 AI credits | month | vendor | threatfrontier.com |
| Copilot Max | 200 USD | month | vendor | threatfrontier.com |
| Copilot Business | 1,900 AI credits | month | vendor | threatfrontier.com |
| Copilot Enterprise | 3,900 AI credits | month | vendor | threatfrontier.com |
| Copilot Pro (legacy annual, request-base… | 300 premium requests | month | vendor | threatfrontier.com |
| Copilot Pro+ (legacy annual, request-bas… | 1,500 premium requests | month | vendor | threatfrontier.com |
| Copilot Business (before 2026-09-01) | 3,000 AI credits | month | vendor | ston.is |
| Copilot Enterprise (before 2026-09-01) | 7,000 AI credits | month | vendor | ston.is |
| Copilot Pro+ | (400–1,000) AI credits consumed | – | user | reddit.com |
| Copilot (plan not stated) | (2,700–6,400) AI credits consumed | month | user | reddit.com |
Z.ai: GLM Coding Plan
Z.ai, until 2025 known internationally as Zhipu AI, is a Beijing company spun out of Tsinghua University in 2019. In January 2026 it became the first large-language-model company to list on a stock exchange (Hong Kong, ticker 2513). Its GLM family is the strongest open-weight line on Terminal-Bench 4.0: GLM 5.3 came out on 14 August 2026, with weights published two weeks later.
What to know:
- Strongest open model: GLM 5.3 (41.8%, best open-weight score) with 1M context. Max (USD 168) buys 1.8x the tokens of the cheapest API offer at our mix, about 3.25 B a month.
- Published credit formula: Credits per model are published (Pro: 60,000 a week), so tokens convert without a tracker. SemiAnalysis measured 6.3 B tokens a month on Max, above the 3.25 B conversion.
- Work off-peak: Off-peak use counts half. Threatfrontier puts Lite at 48 M GLM 5.3 tokens a week peak-only and 97 M off-peak-only; our figures assume peak.
- Hard stop, listed tools: Individual plans block until the next 5-hour cycle with no overage. No API, SDK or own-app use; only 20+ listed tools such as Claude Code, OpenCode and Cline.
- Team seats for clients: Team seats (USD 88 and 188) exclude your data from training by default and allow admin-enabled overage at 10% off API list price. Individual training terms are not in sources.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| GLM Coding Plan Lite | 18 | 5h: not published; week: 10,000 | 5h+week |
| GLM Coding Plan Pro | 80 | 6x Lite (Lite week: 10,000 credits); 5h amount not published | 5h+week |
| GLM Coding Plan Max | 168 | 14x Lite (Lite week: 10,000 credits); 5h amount not published | 5h+week |
| GLM Coding Team Plan Standard Seat | 88 | 5h: not published; week: 66,000 per seat | 5h+week |
| GLM Coding Team Plan Premium Seat | 188 | 5h: not published; week: 155,000 per seat | 5h+week |
- Models: GLM-5.3; GLM-5.3-Flash
- Context: 1M (glm-5.2 1,000,000; other models 200,000 per Cline config); not stated per tier
- Third-party tools: officially supported tools only: ZCode, Claude Code, Codex, OpenCode, Cursor, Cline, Kilo Code, Roo Code, Droid, Crush, Goose and others (20+)
- Automation: GLM Coding Plan Lite, GLM Coding Plan Pro, GLM Coding Plan Max: no general-purpose API access, own apps/bots/SaaS, SDK access, resale or proxy; supported tools only; Lite: 1 project at a time; GLM Coding Team Plan Standard Seat, GLM Coding Team Plan Premium Seat: Team Plan Key per member; supported tools only; risk control on abnormally high-frequency calls; 2+ projects; peak priority
- Training on your data: GLM Coding Plan Lite, GLM Coding Plan Pro, GLM Coding Plan Max: not stated (card: 'Default data privacy'); GLM Coding Team Plan Standard Seat, GLM Coding Team Plan Premium Seat: no (excluded from training by default)
- At the limit: GLM Coding Plan Lite, GLM Coding Plan Pro, GLM Coding Plan Max: blocked until next 5h cycle; no deduction from account balance; no overage for individual plans in sources; GLM Coding Team Plan Standard Seat, GLM Coding Team Plan Premium Seat: seat blocked until reset unless admin enables on-demand overage (promo: 10% off API list price)
Tokens per month at our mix; one credit pool shared by GLM models; all use at peak hours (off-peak counts half).
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | GLM Coding Plan Lite (USD 18) | GLM Coding Plan Pro (USD 80) | GLM Coding Team Plan Standard Seat (USD 88) | GLM Coding Plan Max (USD 168) | GLM Coding Team Plan Premium Seat (USD 188) |
|---|---|---|---|---|---|---|---|---|---|
| GLM 5.3 | yes | 6.9 / 1.7 / 24 | 1M | 41.8 | 0.23 B | 1.39 B | 1.53 B | 3.25 B | 3.60 B |
| GLM 5.3 Flash | yes | 2.3 / 0.56 / 8 | 1M | 35.8 | 0.70 B | 4.22 B | 4.64 B | 9.85 B | 10.91 B |
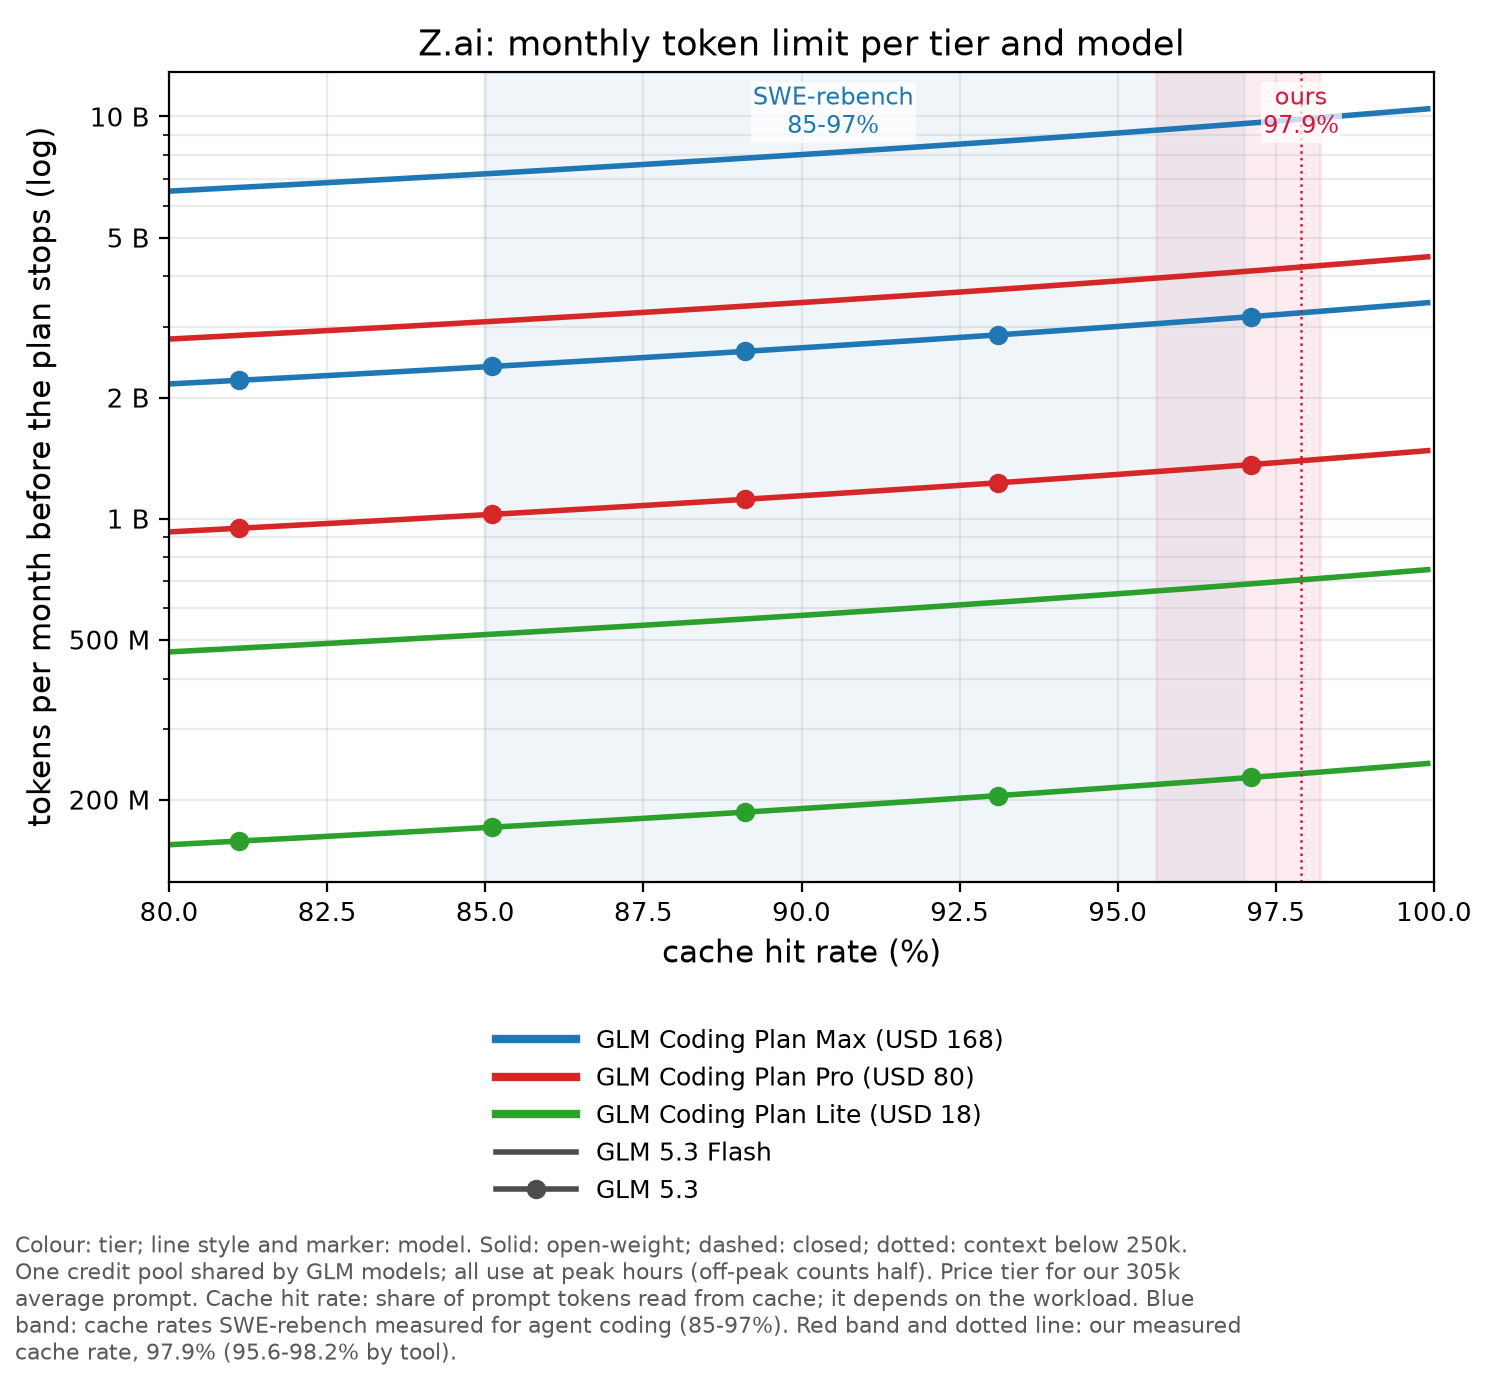
At our mix GLM 5.3 (TB4 41.8%) gets 0.37 full Terminal-Bench 4.0 runs a month on GLM Coding Plan Max, 0.16 on GLM Coding Plan Pro, 0.027 on GLM Coding Plan Lite. At our mix GLM 5.3 Flash (TB4 35.8%) gets 3.4 full Terminal-Bench 4.0 runs a month on GLM Coding Plan Max, 1.5 on GLM Coding Plan Pro, 0.24 on GLM Coding Plan Lite.
Measured and stated limits (40 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| GLM Coding Plan Pro | 12,000 credits | 5h | vendor | docs.z.ai |
| GLM Coding Plan Pro | 60,000 credits | week | vendor | docs.z.ai |
| GLM Coding Plan Pro | (290 M–580 M) M tokens | week | vendor | docs.z.ai |
| GLM Coding Plan Max | 28,000 credits | 5h | vendor | docs.z.ai |
| GLM Coding Plan Max | 140,000 credits | week | vendor | docs.z.ai |
| GLM Coding Plan Max | (676 M–1.35 B) M tokens | week | vendor | docs.z.ai |
| GLM Coding Plan Pro | 830 USD of API value | month | analyst | newsletter.semianalysis.com |
| GLM Coding Plan Pro | 2.7 B tokens | month | analyst | newsletter.semianalysis.com |
| GLM Coding Plan Max | 1,942 USD of API value | month | analyst | newsletter.semianalysis.com |
| GLM Coding Plan Max | 6.3 B tokens | month | analyst | newsletter.semianalysis.com |
| GLM Coding Plan Max (CN, bigmodel.cn v3 … | 1.8 B (900 M–1.8 B) tokens | week | user | linux.do |
| GLM Coding Plan Max | 1.1 B tokens used in 7 days | week | user | reddit.com |
| GLM Coding Plan Pro (CN, bigmodel.cn, le… | 90 M tokens | 5h | user | linux.do |
| GLM Coding Plan Lite (comparison) | 64 M tokens | 5h | user | reddit.com |
| GLM Coding Plan Lite | 2,000 plan credits | 5h | vendor | kingy.ai |
| GLM Coding Plan Lite | 10,000 plan credits | week | vendor | kingy.ai |
| GLM Coding Plan Lite | (48 M–97 M) tokens | week | vendor | threatfrontier.com |
| GLM Coding Plan Lite | (146 M–292 M) tokens | week | vendor | threatfrontier.com |
| GLM Coding Plan Pro (CN, bigmodel.cn v3 … | (877 M–1.75 B) tokens | week | vendor | github.com |
| GLM Coding Plan Max (CN, bigmodel.cn v3 … | (2.05 B–4.09 B) tokens | week | vendor | github.com |
| GLM Coding Plan Lite (legacy V2) | 80 prompts | 5h | vendor | developersdigest.tech |
| GLM Coding Plan Lite (legacy V2) | 400 prompts | week | vendor | developersdigest.tech |
| GLM Coding Plan Pro (legacy V2) | 400 prompts | 5h | vendor | developersdigest.tech |
| GLM Coding Plan Pro (legacy V2) | 2,000 prompts | week | vendor | developersdigest.tech |
| GLM Coding Plan Max (legacy V2) | 1,600 prompts | 5h | vendor | developersdigest.tech |
| GLM Coding Plan Max (legacy V2) | 8,000 prompts | week | vendor | developersdigest.tech |
| GLM Coding Team Plan Premium Seat | 35,000 plan credits | 5h | vendor | developersdigest.tech |
| GLM Coding Team Plan Premium Seat | 155,000 plan credits | week | vendor | developersdigest.tech |
| GLM Coding Team Plan Premium Seat | (749 M–1.5 B) tokens | week | vendor | developersdigest.tech |
| GLM Coding Team Plan Standard Seat (lega… | 60 M tokens | 5h | vendor | docs.z.ai |
| GLM Coding Team Plan Standard Seat (lega… | 300 M tokens | week | vendor | docs.z.ai |
| GLM Coding Team Plan Premium Seat (legac… | 160 M tokens | 5h | vendor | docs.z.ai |
| GLM Coding Team Plan Premium Seat (legac… | 800 M tokens | week | vendor | docs.z.ai |
| ZCode trial plan (BigModel, first 5 days… | 8 M tokens | day | vendor | zcode.z.ai |
| GLM Coding Plan Pro (CN, early subscript… | 30 M tokens | 5h | user | owent.net |
| GLM Coding Plan Pro (CN, early subscript… | 763 requests | 5h | user | owent.net |
| GLM Coding Plan Pro (CN, early subscript… | 200 M tokens | week | user | owent.net |
| GLM Coding Plan Pro (CN, early subscript… | 4,200 requests | week | user | owent.net |
| GLM Coding Plan Pro (CN, legacy V1; plan… | 1.1 B tokens | month | user | v2ex.com |
| GLM Coding Plan Lite (CN, legacy V1; pla… | 900 M tokens | – | user | v2ex.com |
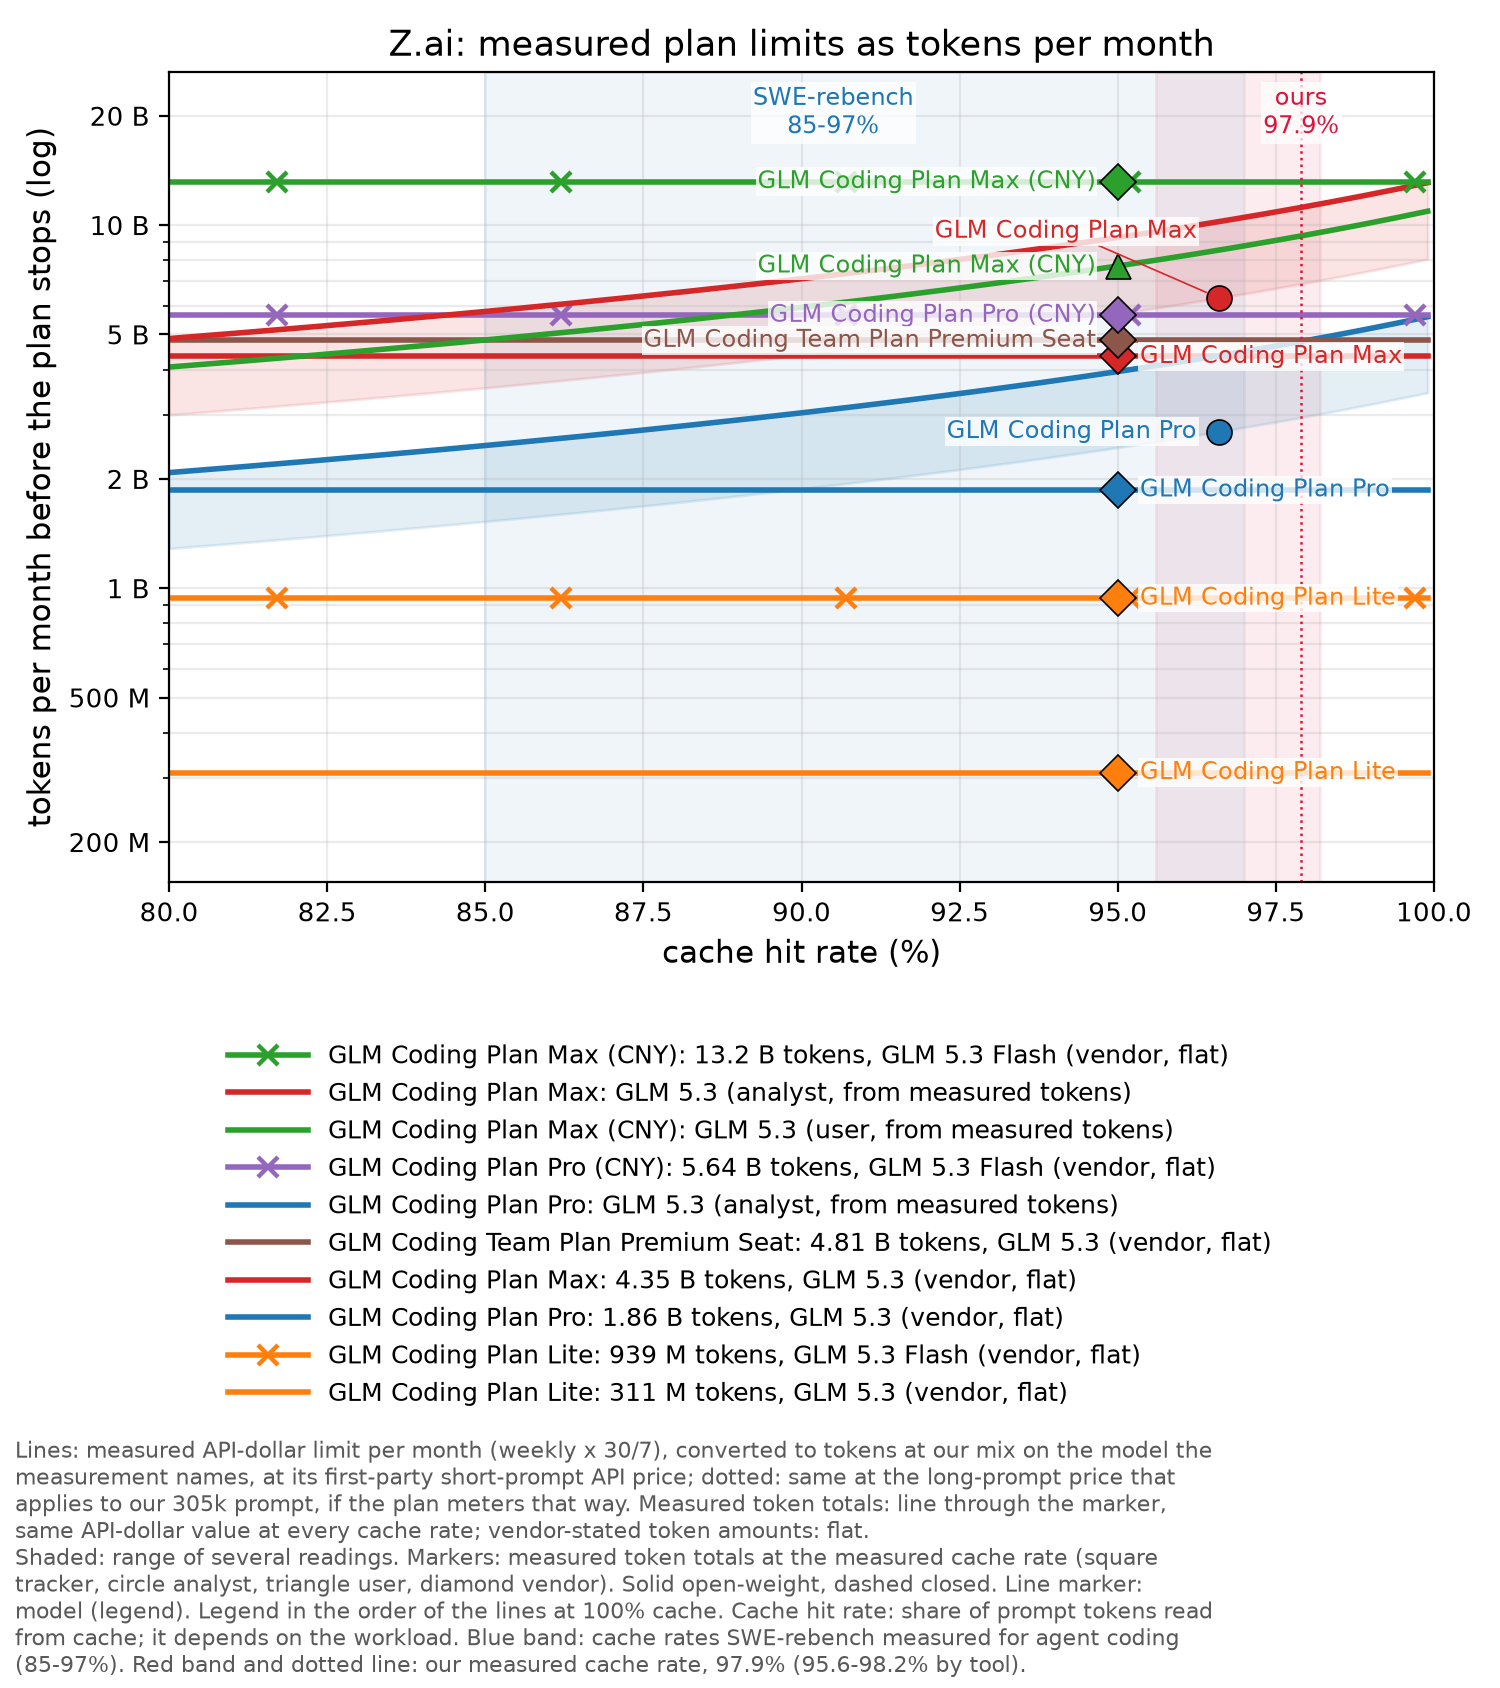
The measured GLM Coding Plan Lite limit buys 0.036 full Terminal-Bench 4.0 runs of GLM 5.3 a month at our mix (1 vendor reading). The measured GLM Coding Plan Max limit buys 0.5 to 1.3 full Terminal-Bench 4.0 runs of GLM 5.3 a month at our mix (3 analyst/vendor readings). The measured GLM Coding Plan Max (CNY) limit buys 1.1 full Terminal-Bench 4.0 runs of GLM 5.3 a month at our mix (1 user reading). The measured GLM Coding Plan Pro limit buys 0.21 to 0.55 full Terminal-Bench 4.0 runs of GLM 5.3 a month at our mix (3 analyst/vendor readings). The measured GLM Coding Team Plan Premium Seat limit buys 0.55 full Terminal-Bench 4.0 runs of GLM 5.3 a month at our mix (1 vendor reading). The measured GLM Coding Plan Lite limit buys 0.32 full Terminal-Bench 4.0 runs of GLM 5.3 Flash a month at our mix (1 vendor reading). The measured GLM Coding Plan Max (CNY) limit buys 4.5 full Terminal-Bench 4.0 runs of GLM 5.3 Flash a month at our mix (1 vendor reading). The measured GLM Coding Plan Pro (CNY) limit buys 1.9 full Terminal-Bench 4.0 runs of GLM 5.3 Flash a month at our mix (1 vendor reading).
Command Code
Command Code is a terminal coding agent from Langbase, Inc., a San Francisco company that began as a serverless platform for building AI agents. The agent adapts to a developer's coding style through its own taste-1 model. Langbase sells usage plans for open and premium models, and the Go plan's first month costs $1. Command Code launched on 25 February 2026 with a $5 million seed round led by Preston-Werner Ventures.
What to know:
- Wins own-agent finder cells: GOAT (USD 10) is the cheapest option for 0.1 to 0.3 B tokens a month at a 50 to 60 minimum score with your own agent and automation, on Sonnet 5.5.
- Modest top multiple: Max 20× (USD 200) buys 1.5x the API on Opus 5.5, 0.9 B tokens a month at our mix, with a separate USD limit per model.
- Pages disagree on amounts: GOAT lists USD 70 on the plan table and USD 80 on its own page; Go's 5-hour and weekly caps differ between pages too.
- API and no training: GOAT and up include a Provider API for any agent and headless use; Command Code never trains on code, and CMD_ZDR=1 enforces zero data retention. Go has no API access.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Go | 1 | $10/mo (~9K req); $2/5h + $5/week (plan table) vs $3/$6 (usage-limits page) | mixed |
| GOAT | 10 | $70/mo (plan table; GOAT page says $80); $14/5h; $35/week; per-model allowances | mixed |
| Pro | 20 | $80/mo (~100K req); $16/5h; $40/week; Claude/GPT/Gemini up to $20/model, Haiku 5.5 $30 | mixed |
| Max 10× | 100 | $150 standard + $100 premium limit (~230K req); $45/5h; $90/week | mixed |
| Max 20× | 200 | $300 standard + $200 premium limit (~370K req); $90/5h; $180/week | mixed |
- Models: Go: GLM-5.2;Tencent Hy3;Qwen 3.8 27B;Qwen 3.7 Max;Qwen 3.7 Plus;DeepSeek V4.1 Flash;+19 more;GPT-5.6 Luna;Grok 4.5; GOAT: GLM-5.2/5.3/5.3 Flash;Kimi K2.7 Code;Kimi K3;DeepSeek V4/V4.1 Flash;DeepSeek V4 Pro;Qwen 3.6/3.7/3.8;MiniMax M3;MiMo V2.5/V2.5 Pro/V2.6;Claude Sonnet 5.5;Claude…; Pro, Max 10×, Max 20×: Everything in GOAT + Claude, GPT, Gemini (45+ models); no Claude Opus, Claude Fable, Fugu Ultra
- Context: Up to 1M plan-wide; models 32K-1.1M
- Third-party tools: Go: not stated (no API access on Go); GOAT, Pro, Max 10×, Max 20×: Yes, via Provider API (OpenAI/Anthropic-compatible) with any agent
- Automation: Go: No API access on Go; GOAT, Pro, Max 10×, Max 20×: API included; Jev headless (cmd -p) and Provider API only
- Training on your data: Never trains on or stores code; CMD_ZDR=1 enforces ZDR; some free stealth models may train (blocked under ZDR)
- At the limit: Go: On-demand credits used; else stops until reset, renewal or top-up (top-ups never expire); GOAT, Pro: Extra credits; else paid models pause until reset, free models keep working; Max 10×, Max 20×: Uncapped pay-as-you-go extra credits; else declined until window resets
Tokens per month at our mix; a separate USD limit per model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Go (USD 1) | GOAT (USD 10) | Pro (USD 20) | Max 10× (USD 100) | Max 20× (USD 200) |
|---|---|---|---|---|---|---|---|---|---|
| Claude Opus 5.5 | no | 4 / 0.2 / 20 | – | 64.8 | – | – | – | 0.45 B | 0.90 B |
| Claude Sonnet 5.5 | no | 2 / 0.1 / 10 | – | 61.8 | – | 0.42 B | 0.48 B | 0.90 B | 1.79 B |
| GPT-6 Astra | no | 10 / 1 / 50 | – | 58.2 | – | – | – | 0.11 B | 0.23 B |
| GPT-6.1 Sol | no | 2 / 0.1 / 10 | – | 58.2 | – | – | – | 0.90 B | 1.79 B |
| Claude Fable 5.1 | no | 10 / 0.25 / 50 | – | 57.9 | – | – | – | 0.25 B | 0.51 B |
| Gemini 4 Argon | no | 2 / 0.1 / 10 | – | 57.1 | – | – | 0.51 B | 0.96 B | 1.91 B |
| GPT-6 Sol | no | 2 / 0.2 / 10 | – | 49.4 | – | – | – | 0.57 B | 1.13 B |
| GLM 5.3 | yes | 1.4 / 0.26 / 4.4 | – | 41.8 | – | 0.24 B | 0.27 B | 0.52 B | 1.03 B |
| Claude Haiku 5.5 | no | 0.1 / 0.01 / 0.5 | – | 39.2 (vendor) | – | – | – | 11.33 B | 22.65 B |
| Grok 4.7 | no | 2 / 0.5 / 6 | – | 37.6 | – | – | – | 0.28 B | 0.55 B |
| GLM 5.3 Flash | yes | 0.15 / 0.03 / 0.5 | – | 35.8 | – | 2.10 B | 2.40 B | 4.50 B | 9.01 B |
| MiMo V2.6 Pro | yes | 0.435 / 0.0036 / 0.87 | – | 34.8 | – | 4.96 B | 5.67 B | 10.63 B | 21.25 B |
| Step 5 Preview | yes | 1 / 0.05 / 2.7 | – | 33.3 | – | 0.94 B | 1.07 B | 2.02 B | 4.03 B |
| DeepSeek V4.1 Flash | yes | 0.15 / 0.003 / 0.6 | – | 31.2 (vendor) | 1.41 B | – | – | 21.14 B | 42.27 B |
| MiMo V2.6 Flash | yes | 0.14 / 0.0028 / 0.28 | – | 28.8 (vendor) | – | 11.39 B | 13.01 B | 24.40 B | 48.80 B |
| Qwen 3.8 Max | no | 2 / 0.25 / 6 | – | 27 | – | 0.23 B | 0.26 B | 0.51 B | 1.01 B |
| Gemini 3.8 Flash | no | 1.5 / 0.15 / 7.5 | – | 19.1 | – | 0.37 B | 0.42 B | 0.79 B | 1.57 B |
| GPT-6 Luna | no | 0.1 / 0.01 / 0.5 | – | 16.4 | – | – | – | 11.33 B | 22.65 B |
| Muse Spark 1.3 | no | 1.25 / 0.15 / 4.25 | – | 14.5 | – | 0.39 B | 0.44 B | 0.83 B | 1.67 B |
| DeepSeek V4 Pro | yes | 0.66 / 0.022 / 1.98 | – | 14 | – | – | – | 3.88 B | 7.75 B |
| Kimi K3 | yes | 3 / 0.3 / 15 | – | 12.6 | – | 0.18 B | 0.21 B | 0.39 B | 0.79 B |
| MiniMax M3 | yes | 0.3 / 0.06 / 1.2 | – | 2 | – | – | – | 2.24 B | 4.48 B |
| Kimi K2.7 Code | yes | 0.95 / 0.19 / 4 | – | 1 | – | 0.33 B | 0.38 B | 0.71 B | 1.41 B |
| GLM 5.2 | yes | 1.4 / 0.26 / 4.4 | – | – | 0.03 B | 0.24 B | 0.27 B | 0.52 B | 1.03 B |
| GLM 5.3 FlashX | no | 0.37 / 0.075 / 1.25 | – | – | – | 0.84 B | 0.96 B | 1.80 B | 3.61 B |
| Qwen 3.8 Flash | yes | 0.16 / 0.016 / 0.47 | – | – | – | 3.54 B | 4.04 B | 7.58 B | 15.16 B |
| Qwen 3.8 27B | yes | 0.4 / 0.04 / 3 | – | – | 0.19 B | 1.33 B | 1.52 B | 2.85 B | 5.71 B |
| Mistral Large 4 | no | 1.36 / 0.14 / 4.18 | – | – | – | 0.41 B | 0.46 B | 0.87 B | 1.74 B |
| Nemotron 3 Ultra | yes | 0.6 / 0.12 / 2.4 | – | – | – | 0.52 B | 0.60 B | 1.12 B | 2.24 B |
| Muse Spark Open | yes | 1.25 / 0.15 / 4.25 | – | – | – | 0.39 B | 0.44 B | 0.83 B | 1.67 B |
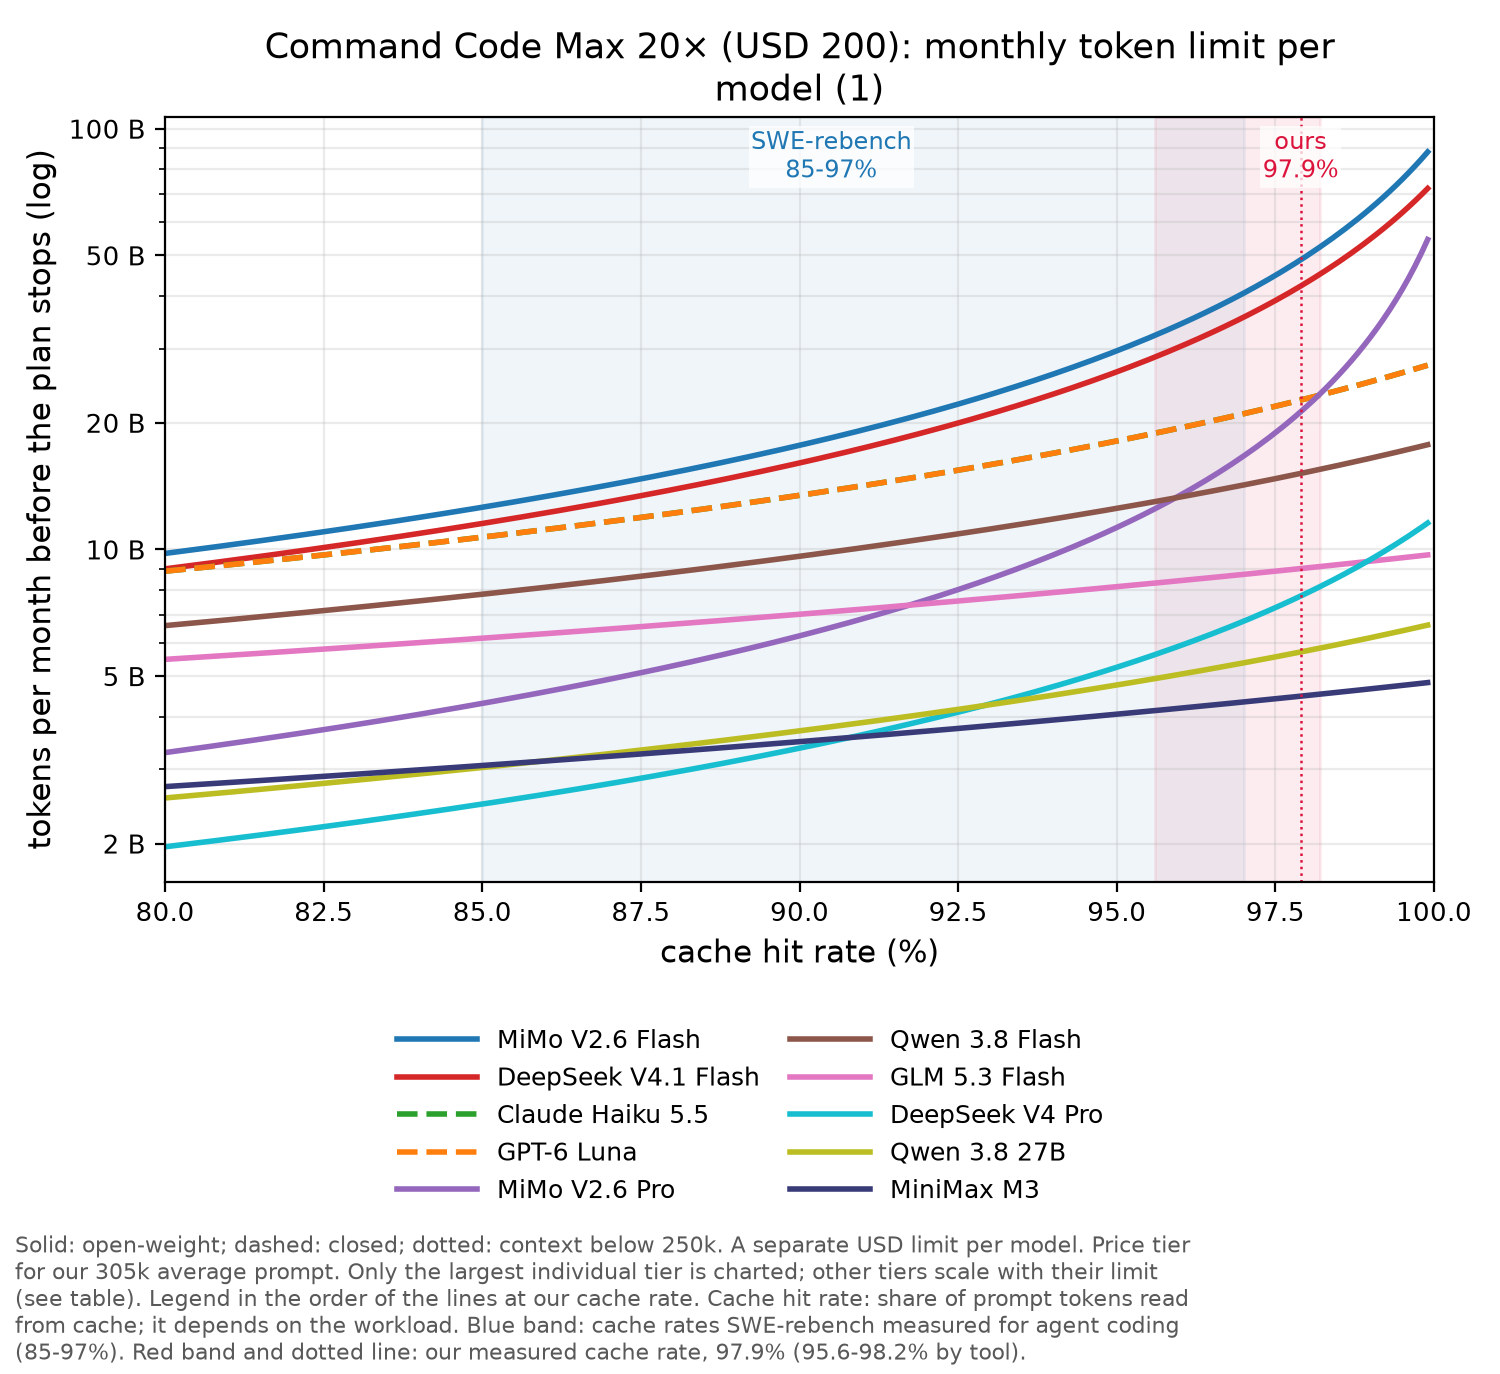
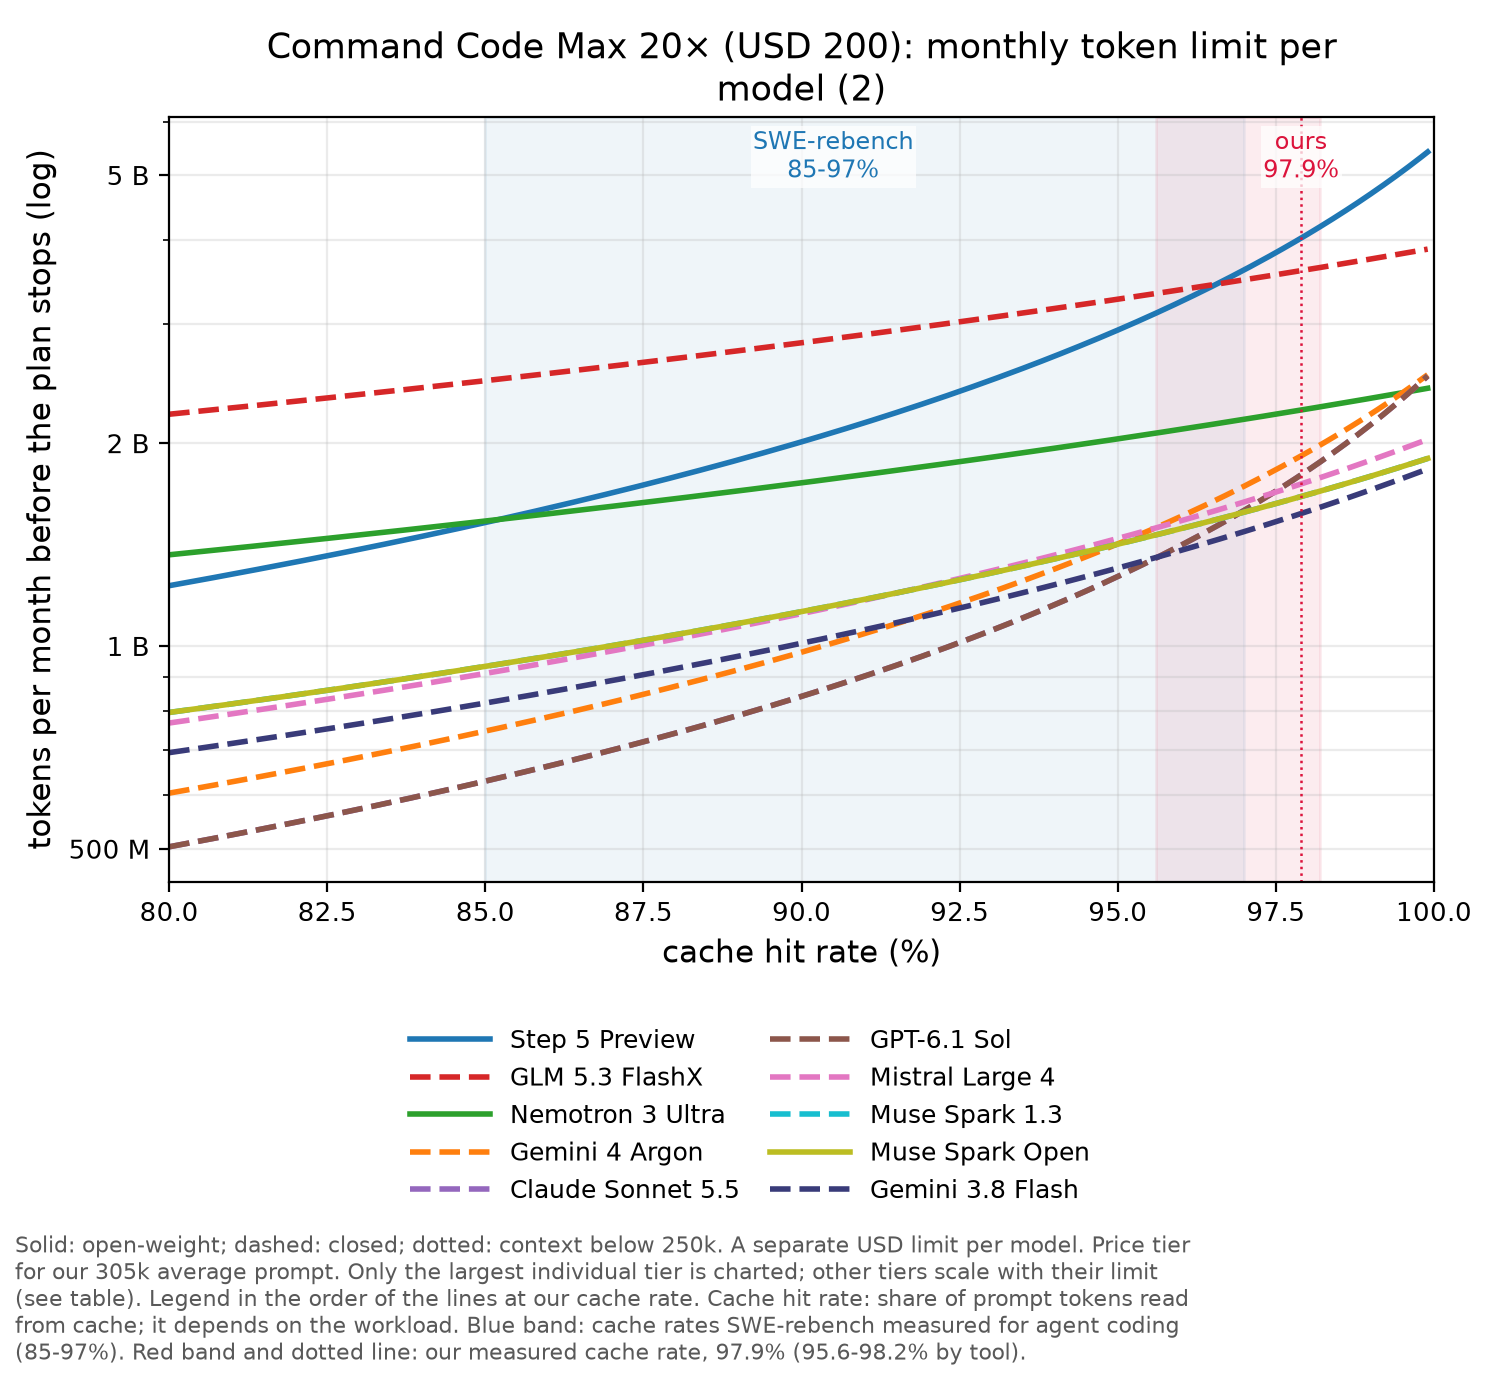
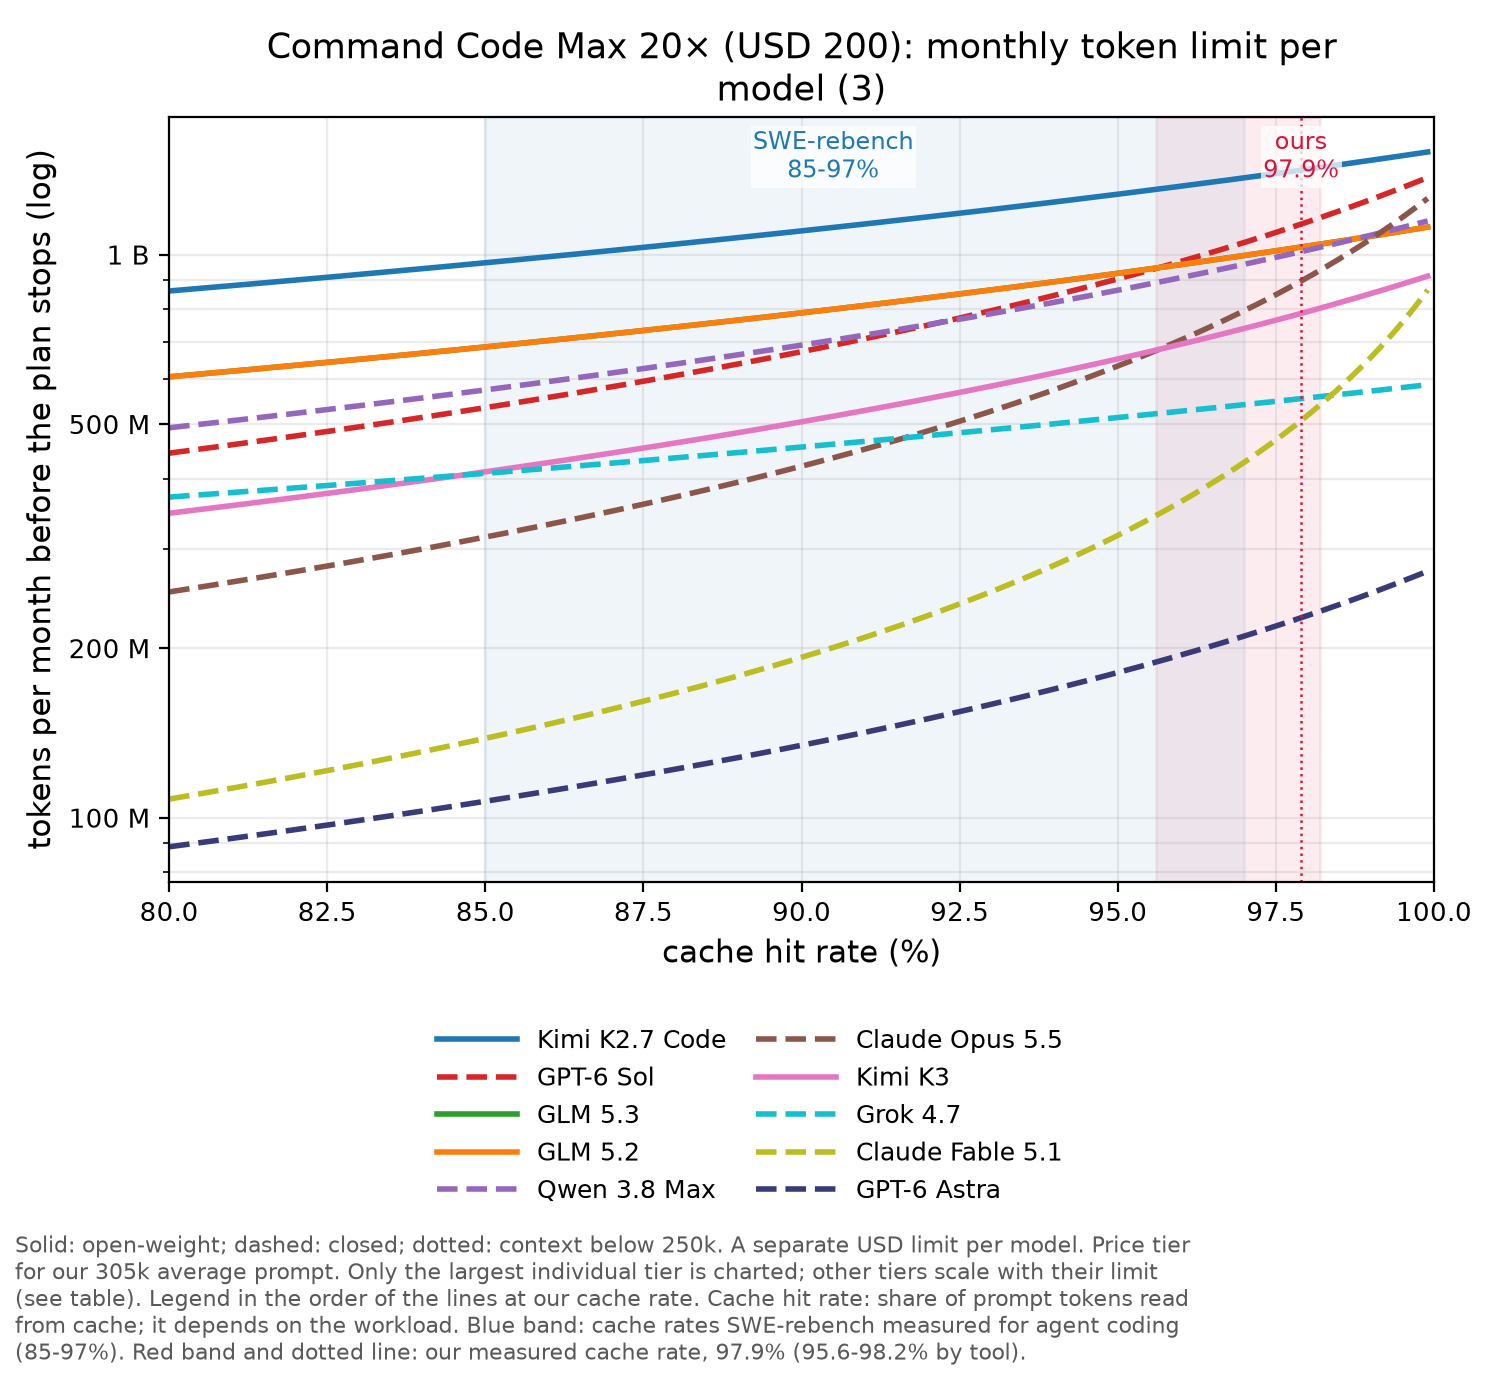
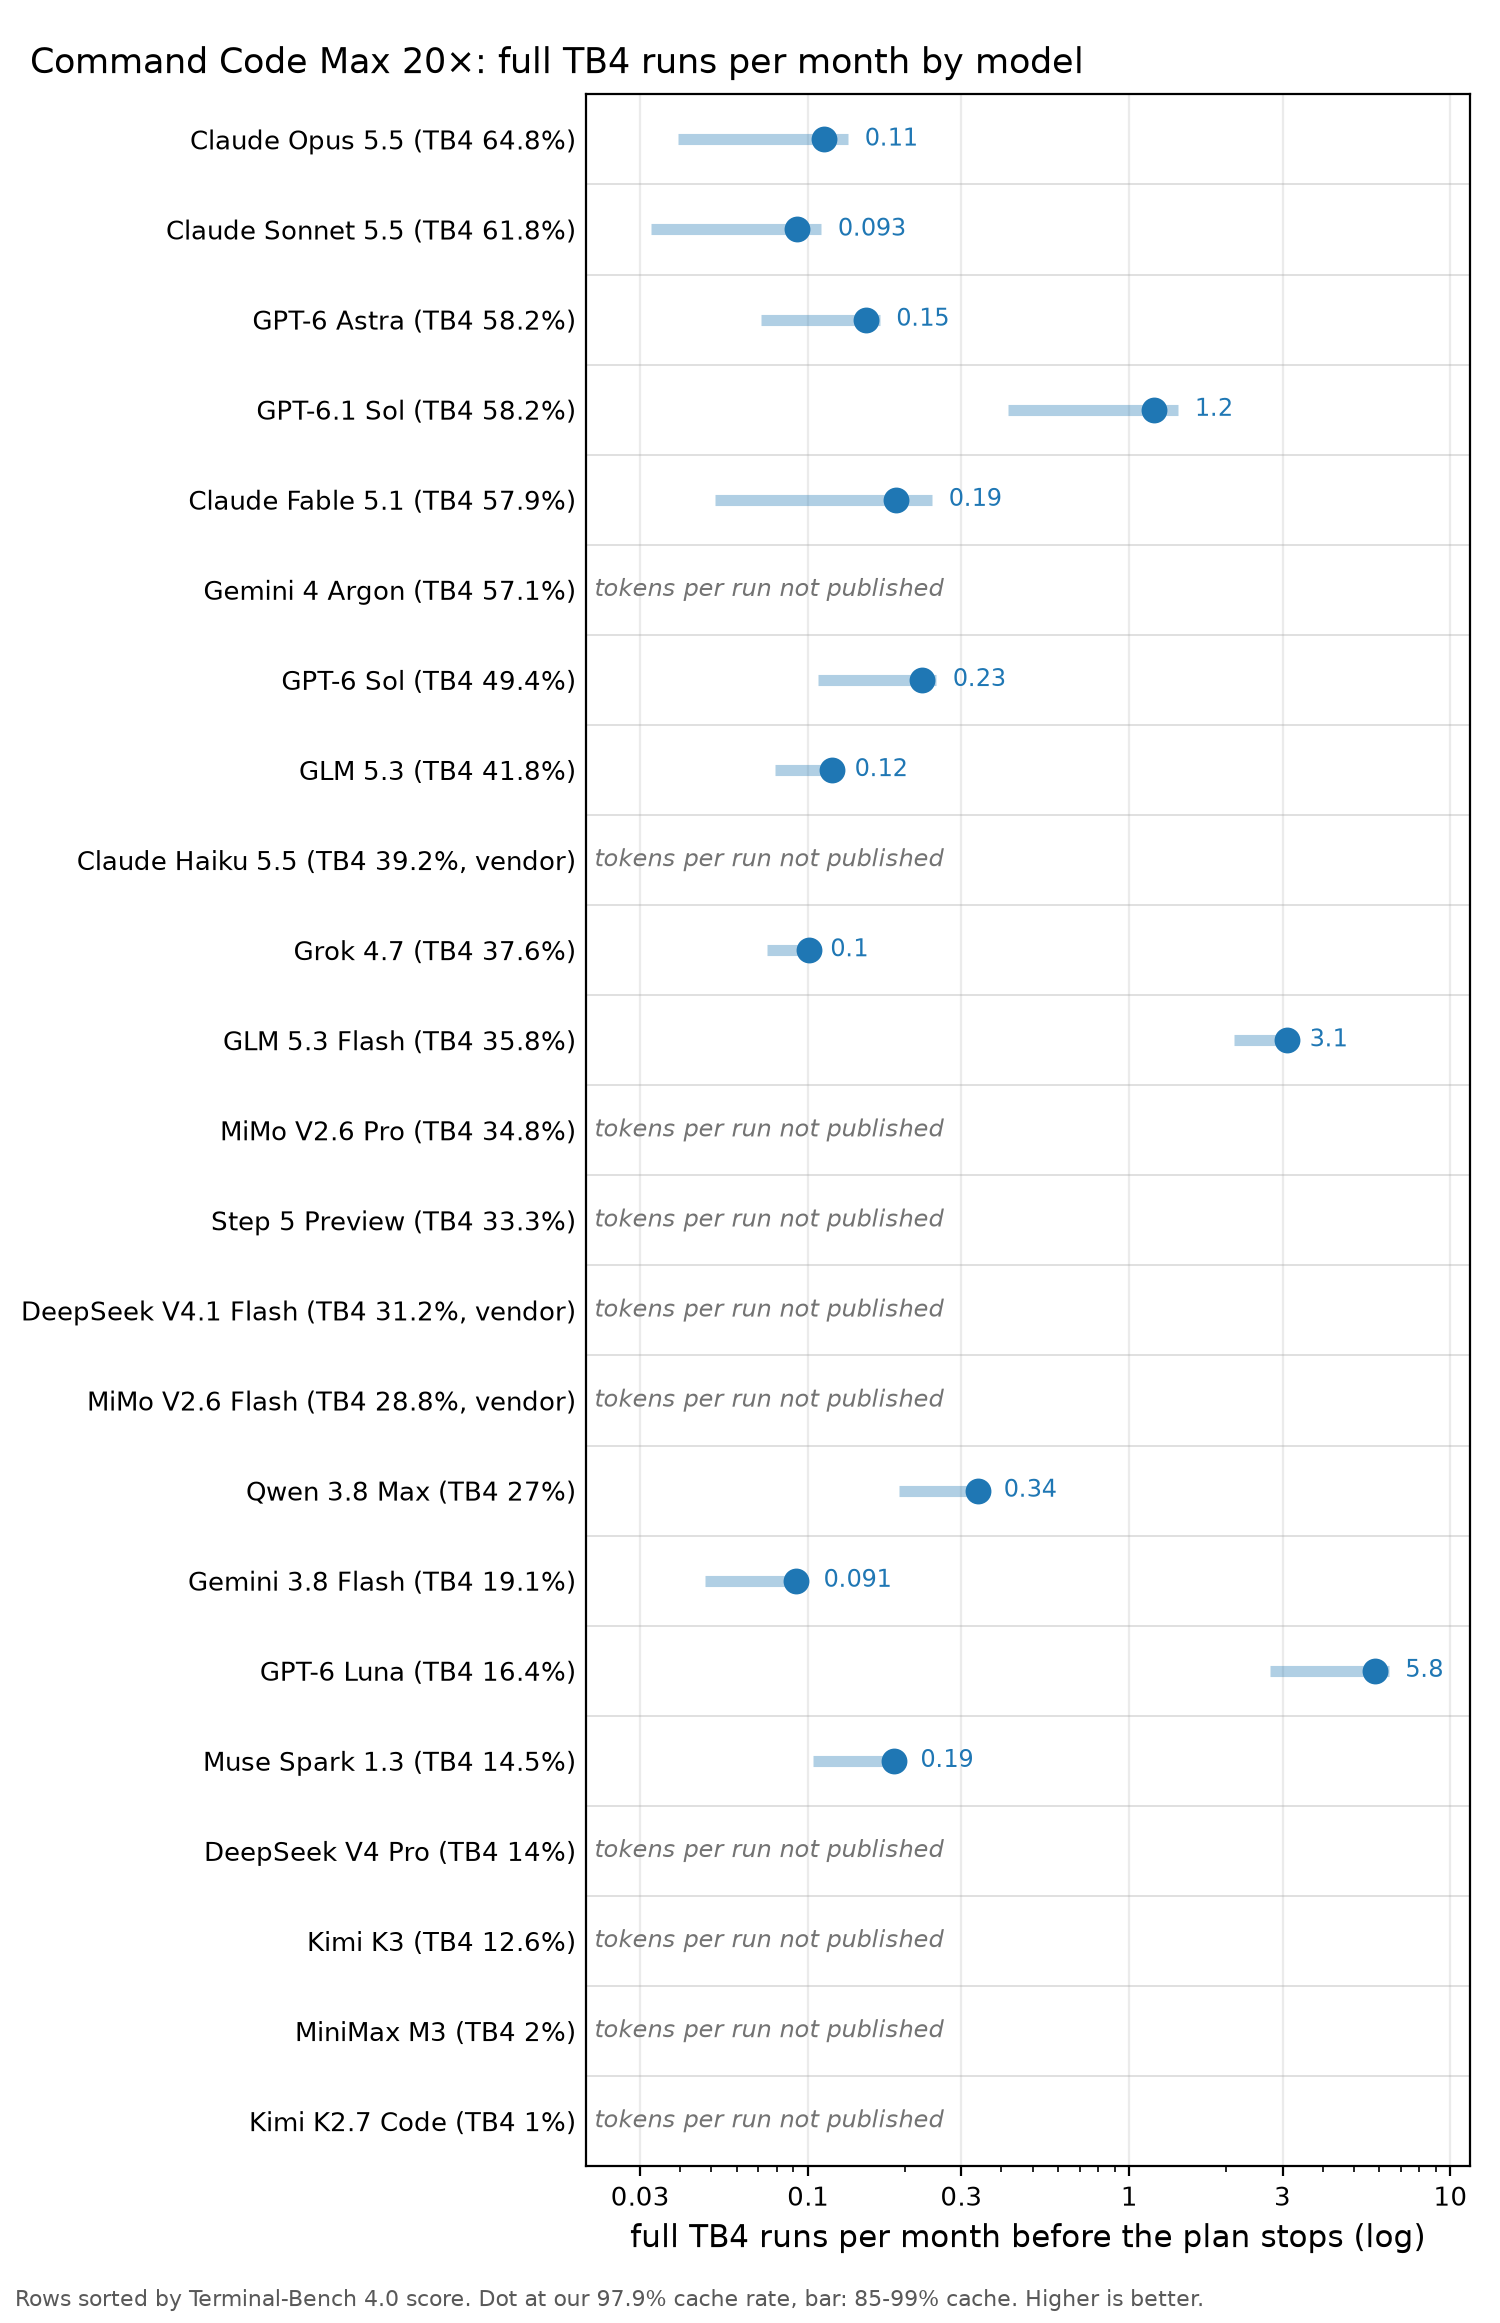
Xiaomi: MiMo Token Plan
Xiaomi, the Beijing-based phone and electric-vehicle maker founded in 2010, builds the MiMo models through a team led by former DeepSeek researcher Luo Fuli. It publishes MiMo weights under the MIT licence, most recently MiMo-V2.6 Pro and Flash (22 September 2026), and sells access through its own platform and the MiMo Code app. In March 2026 it pledged at least 60 billion yuan ($8.7 billion) for AI over three years.
What to know:
- Volume, modest score: Max (USD 100) converts to 8.4 B MiMo V2.6 Pro tokens a month at our mix, 1.2x what the same money buys on the API. V2.6 Pro scores 34.8%.
- API already cheap: MiMo V2.6 Pro costs USD 0.014 per 1M at our mix on Xiaomi's API, so the plan adds little over pay-per-use and adds a hard stop.
- Published formula: Credit rates are published (V2.6 Pro: 300 input, 2.5 cached, 600 output per 1M), so the conversion needs no tracker.
- Coding tools only: Scripts and custom backends lead to suspension. At the limit service stops without balance deduction; no refunds.
- Older models leave: mimo-v2.5-pro and mimo-v2.5 leave the plan on 21 October 2026.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Token Plan Individual Lite | 6 | 4.1 billion per month | month |
| Token Plan Individual Standard | 16 | 11 billion per month | month |
| Token Plan Individual Pro | 50 | 38 billion per month | month |
| Token Plan Individual Max | 100 | 82 billion per month | month |
| Token Plan Team Standard | 16 | 11 billion per seat per month | month |
| Token Plan Team Pro | 50 | 38 billion per seat per month | month |
| Token Plan Team Max | 100 | 82 billion per seat per month | month |
- Models: mimo-v2.6-pro; mimo-v2.6-flash; mimo-v2.5-pro and mimo-v2.5 until 2026-10-21
- Context: not stated (for V2.6 models)
- Third-party tools: yes: OpenCode, OpenClaw, Claude Code, Codex, Kilo Code, Cline, Qwen Code, CodeBuddy, Hermes Agent and others; shared quota
- Automation: programming tools only; no automated scripts or custom backends; suspension and key block
- At the limit: Token Plan Individual Lite, Token Plan Individual Standard, Token Plan Individual Pro, Token Plan Individual Max: service suspended, no balance deduction; upgrade (pay difference) or switch to per-token API; no refunds; Token Plan Team Standard, Token Plan Team Pro, Token Plan Team Max: seat suspended, other seats unaffected; buy extra seats or switch to PAYG API; no refunds
Tokens per month at our mix; one credit pool per month shared by all models: each line assumes all use on that model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Token Plan Individual Lite (USD 6) | Token Plan Individual Standard (USD 16) | Token Plan Team Standard (USD 16) | Token Plan Individual Pro (USD 50) | Token Plan Team Pro (USD 50) | Token Plan Individual Max (USD 100) | Token Plan Team Max (USD 100) |
|---|---|---|---|---|---|---|---|---|---|---|---|
| MiMo V2.6 Pro | yes | 300 / 2.5 / 600 | 1M | 34.8 | 0.42 B | 1.13 B | 1.13 B | 3.90 B | 3.90 B | 8.41 B | 8.41 B |
| MiMo V2.6 Flash | yes | 100 / 2 / 200 | 1M | 28.8 (vendor) | 0.93 B | 2.51 B | 2.51 B | 8.65 B | 8.65 B | 18.67 B | 18.67 B |
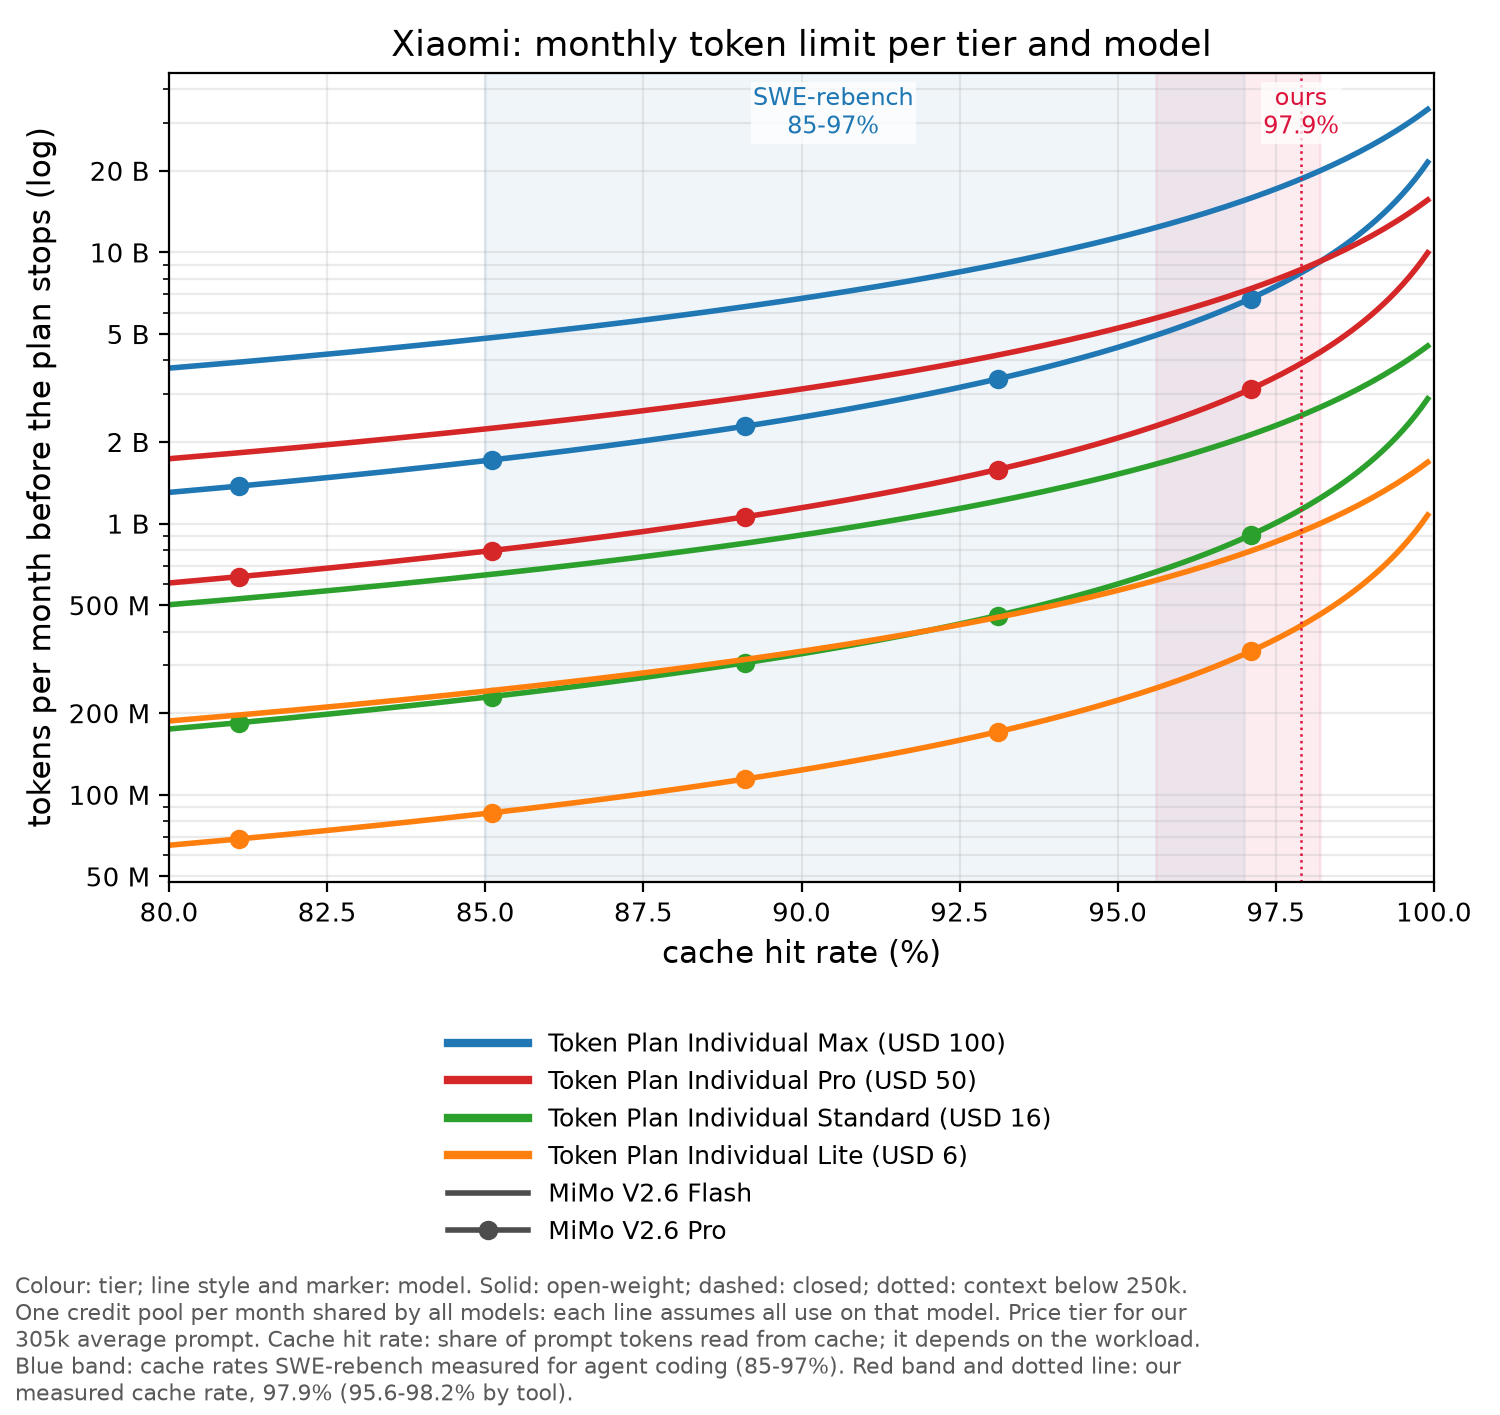
Measured and stated limits (9 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| MiMo Token Plan Lite ($6) | 4.1 B Credits | month | vendor | mimo.mi.com |
| MiMo Token Plan Lite ($6) | 200 rounds of medium-to-comple… | month | vendor | mimo.mi.com |
| MiMo Token Plan Standard ($16) | 11 B Credits | month | vendor | mimo.mi.com |
| MiMo Token Plan Standard ($16) | 1,600 rounds of medium-to-comple… | month | vendor | mimo.mi.com |
| MiMo Token Plan Pro ($50) | 38 B Credits | month | vendor | mimo.mi.com |
| MiMo Token Plan Pro ($50) | 5,600 rounds of medium-to-comple… | month | vendor | mimo.mi.com |
| MiMo Token Plan Max ($100) | 82 B Credits | month | vendor | mimo.mi.com |
| MiMo Token Plan Max ($100) | 12,800 rounds of medium-to-comple… | month | vendor | mimo.mi.com |
| MiMo Token Plan (launch post, v2 models) | 60 M credits | month | vendor | threatfrontier.com |
Standard Compute
Standard Compute AS is a Norwegian private limited company in Oslo that sells a large language model (LLM) gateway for coding agents. One application programming interface (API), compatible with both the OpenAI and Anthropic formats, sends each request to a frontier or open model. Customers pay a flat monthly plan from $19 that comes with a fixed compute budget. In October 2026 its site claimed more than 3,500 developers and businesses in 33 countries.
What to know:
- Built for unattended agents: 24/7 unattended agents and batch jobs are allowed, and prompts and outputs are not used for training.
- About API parity: Scale (USD 2,499) carries a USD 2,849 compute budget, 1.1x the API on Gemini 4 Argon at its promotion price and 18 B tokens a month at our mix.
- Routing default: Providers run anywhere by default; EU or US zero-retention routing is opt-in. Set it if your data has a residency rule.
- Clean stop: At the budget calls return HTTP 402 until renewal, or continue on prepaid pay-as-you-go at the usage rate plus 15%.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Starter | 19 | $20/mo compute budget; one agent at a time; 1 API key | month |
| Economy | 39 | $41/mo compute budget; parallel agents; 1 API key | month |
| Standard | 89 | $95/mo compute budget; priority scheduling; 1 API key | month |
| Pro | 249 | $269/mo compute budget; highest priority; 1 API key | month |
| Pro Plus | 499 | $549/mo compute budget; unlimited API keys | month |
| Growth | 999 | $1,119/mo compute budget; unlimited API keys | month |
| Scale | 2499 | $2,849/mo compute budget; dedicated execution | month |
| Business | Let's talk (custom); flat price for whol… | custom (compute sized to volume) | month (not published) |
- Models: GLM 5.2/5.3;Kimi K3;DeepSeek V4/V4.1/V4 Pro;Qwen 3.7/3.8;MiniMax M3;MiMo V2.6;Claude Fable/Opus/Sonnet/Haiku 5.x;GPT-6.x/5.6;Gemini 4 Argon/3.8 Flash;Grok 4.3;Mistral Large 4
- Third-party tools: Claude Code, Codex CLI, OpenCode, OpenClaw, Hermes, Cline, Kilo Code, Pi, Aider, any OpenAI-compatible
- Automation: 24/7 unattended agents, batch jobs, own-pipeline scrapers allowed; resale/external customers at scale = enterprise; route for resale
- Training on your data: No training on prompts/outputs; providers run anywhere by default; EU/US ZDR rule opt-in (conflict)
- At the limit: HTTP 402 budget_exhausted until renewal/upgrade, or optional prepaid PAYG at usage rate +15%
Ollama Cloud
Ollama launched in 2023 and makes an open-source tool for running open-weight models on a developer's own computer. Ollama Cloud runs larger models on hosted graphics processing units (GPUs), with tiers from free to $100 a month and usage measured in GPU time. In July 2026 Ollama raised a $65 million Series B and reported nearly 8.9 million monthly developers.
What to know:
- About API parity: Max (USD 100) buys 0.96x the GLM 5.3 tokens of the cheapest API offer, 1.03 B a month at our mix.
- Automation grey zone: The API serves your own tools, but the terms ban automated access without permission. Ask before running CI on it.
- Clean data terms: No prompt or response logging or training, providers must run zero retention, hosting in the US with EU for extra capacity.
- Soft stop: Past the limit you continue on purchased credits at the same per-token rate, valid one year, with an email at 90%.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Pro | 20 | $60/mo usage credits; 3 concurrent requests; no rollover | month |
| Max | 100 | $300/mo usage credits; 10 concurrent requests | month |
| Team | 500 | $1,000/mo usage credits shared across team; 10 concurrent requests | month |
- Models: deepseek-v4.1-flash;deepseek-v4-pro;glm-5.3;glm-5.3-flash;glm-5.2;kimi-k3;kimi-k2.7-code;kimi-k2.6;minimax-m3;minimax-m2.7;gpt-oss;mistral-large-4;early access to newest models
- Context: Model maximum by default (no number given)
- Third-party tools: Claude Code, Codex, OpenCode, Cline, plus API
- Automation: API for own tools; ToS bans automated access without permission; Claude Code --yes flag for scripts/CI
- Training on your data: No prompt/response logging or training; providers must run ZDR; US hosting, EU for extra capacity
- At the limit: Pro, Max: Continue on purchased credits at same per-token rate (expire after 1 year); email at 90%; Team: Draws from shared team balance billed as you go; auto billing can be turned off
Tokens per month at our mix; one USD pool shared by all models: each line assumes all use on that model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Pro (USD 20) | Max (USD 100) | Team (USD 500) |
|---|---|---|---|---|---|---|---|
| GLM 5.3 | yes | 1.4 / 0.26 / 4.4 | 1M | 41.8 | 0.21 B | 1.03 B | 3.44 B |
| GLM 5.3 Flash | yes | 0.15 / 0.03 / 0.5 | 1M | 35.8 | 1.80 B | 9.01 B | 30.02 B |
| DeepSeek V4.1 Flash | yes | 0.3 / 0.006 / 1.2 | 1M | 31.2 (vendor) | 4.23 B | 21.14 B | 70.46 B |
| DeepSeek V4 Pro | yes | 1.32 / 0.044 / 3.96 | 1M | 14 | 0.78 B | 3.88 B | 12.92 B |
| Kimi K3 | yes | 3 / 0.3 / 15 | 1M | 12.6 | 0.16 B | 0.79 B | 2.62 B |
| MiniMax M3 | yes | 0.6 / 0.12 / 2.4 | 512k | 2 | 0.45 B | 2.24 B | 7.47 B |
| Kimi K2.7 Code | yes | 0.95 / 0.19 / 4 | 262k | 1 | 0.28 B | 1.41 B | 4.71 B |
| Muse Spark Open | yes | 1.25 / 0.15 / 4.25 | 1M | – | 0.33 B | 1.67 B | 5.55 B |
| gpt-oss-120b | yes | 0.15 / 0.014 / 0.6 | 131k (below 250k) | – | 3.36 B | 16.81 B | 56.03 B |
| Mistral Large 4 | no | 0.68 / 0.07 / 2.09 | 1M | – | 0.70 B | 3.48 B | 11.60 B |
| GLM 5.2 | yes | 1.4 / 0.26 / 4.4 | 976k | – | 0.21 B | 1.03 B | 3.44 B |
| Nemotron 3 Ultra | yes | 0.1 / 0.1 / 3 | 262k | – | 0.57 B | 2.86 B | 9.53 B |
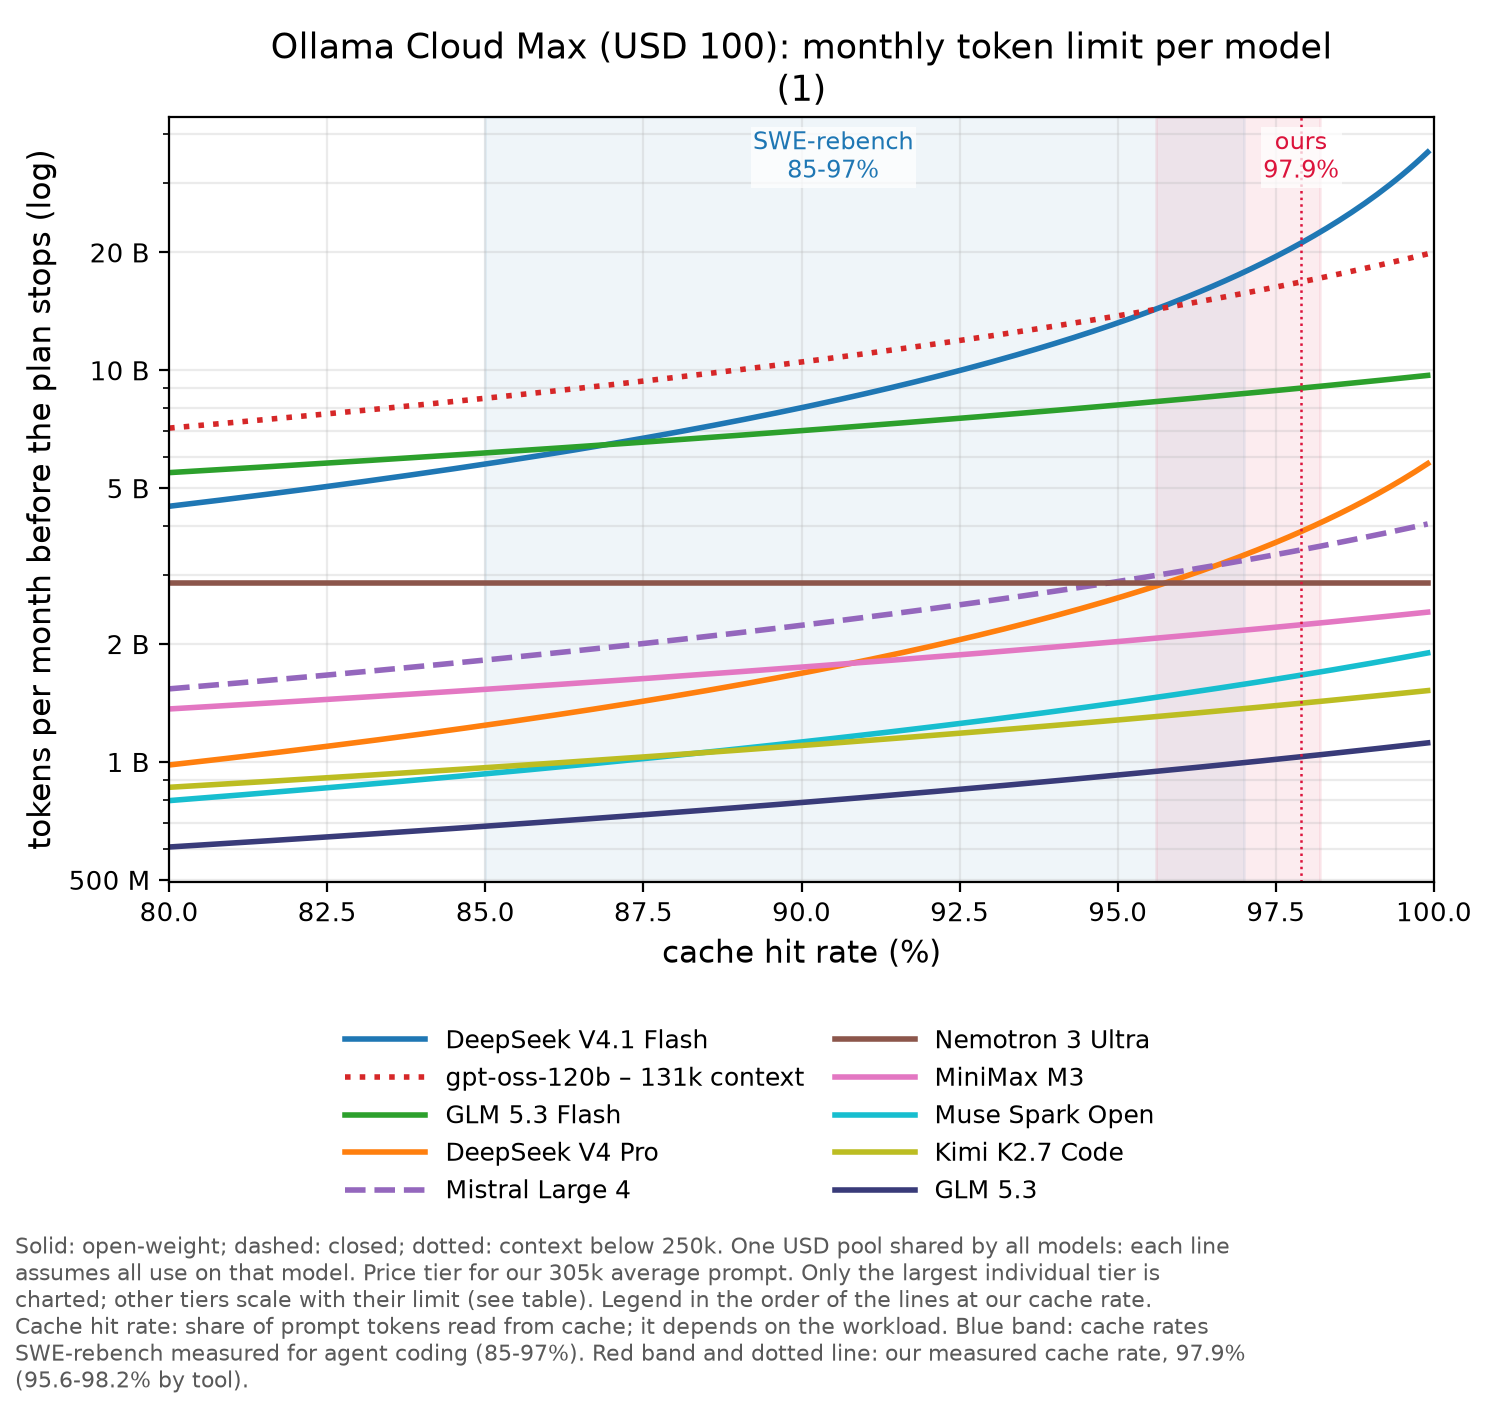
At our mix Max (USD 100) allows 1.03 B tokens a month on GLM 5.2 (0.69 to 1.08 B at 85-99% cache). At our mix Max (USD 100) allows 0.79 B tokens a month on Kimi K3 (0.41 to 0.85 B at 85-99% cache).
At our mix GLM 5.3 (TB4 41.8%) gets 0.12 full Terminal-Bench 4.0 runs a month on Max. At our mix GLM 5.3 Flash (TB4 35.8%) gets 3.1 full Terminal-Bench 4.0 runs a month on Max.
Atlas Cloud: Coding Plan
Atlas Cloud is a US company that runs AI inference and a graphics processing unit (GPU) cloud. Sources differ on whether its headquarters are in New York or Menlo Park, California. Its Coding Plan sells monthly subscriptions from $10 to $500 that give coding agents access to open-weight models such as DeepSeek, GLM, Kimi and MiniMax. In June 2026 Inc. reported $50 million in revenue in four months, with no outside funding.
What to know:
- Most volume, below API: The USD 500 tier converts to 38 B GLM 5.3 Flash tokens a month, but at 0.74x the tokens per dollar of the cheapest API offer.
- No GLM 5.3: The list has GLM 5.3 Flash, DeepSeek V4.1 Flash and Kimi K2.7 Code, not GLM 5.3.
- Conflicting limits: Starter lists 16.5M points a week on the plan page and 800K a day on the blog. Plan on the lower figure.
- Automation and privacy clear: Full API access is allowed, no training without written consent. Use pauses until the Monday 00:00 UTC reset.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Starter | 10 | 16.5M points/week (plan page); blog: 800K/day (conflict) | week |
| Lite | 20 | 33M points/week (plan page); blog: 2.2M/day; quick-start implies 660K (conflict) | week |
| Plus | 50 | 82.5M points/week (plan page); blog: 4.8M/day (conflict) | week |
| Max | 100 | 165M points/week (plan page); blog: 9.8M/day (conflict) | week |
| $200 tier (unnamed) | 200 | 330M points/week (plan page) | week |
| $500 tier (unnamed) | 500 | 825M points/week (plan page) | week |
- Models: DeepSeek V4.1 Flash/V4 Pro/V4 Flash/V3.2;GLM 5.3-flash/5.2/5.1/5;Kimi K2.7 Code/K2.6/K2.5;MiniMax M3/M2.7/M2.5;Qwen3.8-max;Qwen3.6-plus;Doubao Seed 2.1 turbo/pro
- Third-party tools: Claude Code, Cursor, Cline, Codex CLI, Kilo Code, Roo Code, OpenCode, OpenClaw, Trae, raw API
- Automation: Full API access; plan keys call plan models only; no exposing APIs to end users, no thin-wrapper resale
- Training on your data: No training/eval/benchmark on content without written consent; request content kept briefly
- At the limit: Pauses until weekly reset (Mon 00:00 UTC) unless PAYG pack held ($99=280M points, 90 days); no carry-over
Tokens per month at our mix; one points pool per week shared by all models: each line assumes all use on that model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Starter (USD 10) | Lite (USD 20) | Plus (USD 50) | Max (USD 100) | $200 tier (unnamed) (USD 200) | $500 tier (unnamed) (USD 500) |
|---|---|---|---|---|---|---|---|---|---|---|
| GLM 5.3 Flash | yes | 0.4 / 0.08 / 3.96 | – | 35.8 | 0.76 B | 1.52 B | 3.79 B | 7.58 B | 15.16 B | 37.89 B |
| DeepSeek V4.1 Flash | yes | 0.5 / 0.05 / 1.98 | – | 31.2 (vendor) | 1.13 B | 2.26 B | 5.64 B | 11.28 B | 22.55 B | 56.38 B |
| Qwen 3.8 Max | no | 3.96 / 0.5 / 11.88 | – | 27 | 0.12 B | 0.23 B | 0.58 B | 1.15 B | 2.31 B | 5.77 B |
| DeepSeek V4 Pro | yes | 2.18 / 0.22 / 6.53 | – | 14 | 0.26 B | 0.52 B | 1.30 B | 2.60 B | 5.20 B | 13.01 B |
| MiniMax M3 | yes | 0.89 / 0.178 / 3.56 | – | 2 | 0.36 B | 0.71 B | 1.78 B | 3.56 B | 7.12 B | 17.80 B |
| Kimi K2.7 Code | yes | 1.72 / 0.345 / 7.26 | – | 1 | 0.18 B | 0.37 B | 0.92 B | 1.83 B | 3.67 B | 9.17 B |
| GLM 5.2 | yes | 3.7 / 0.686 / 11.62 | – | – | 0.09 B | 0.18 B | 0.46 B | 0.92 B | 1.84 B | 4.61 B |
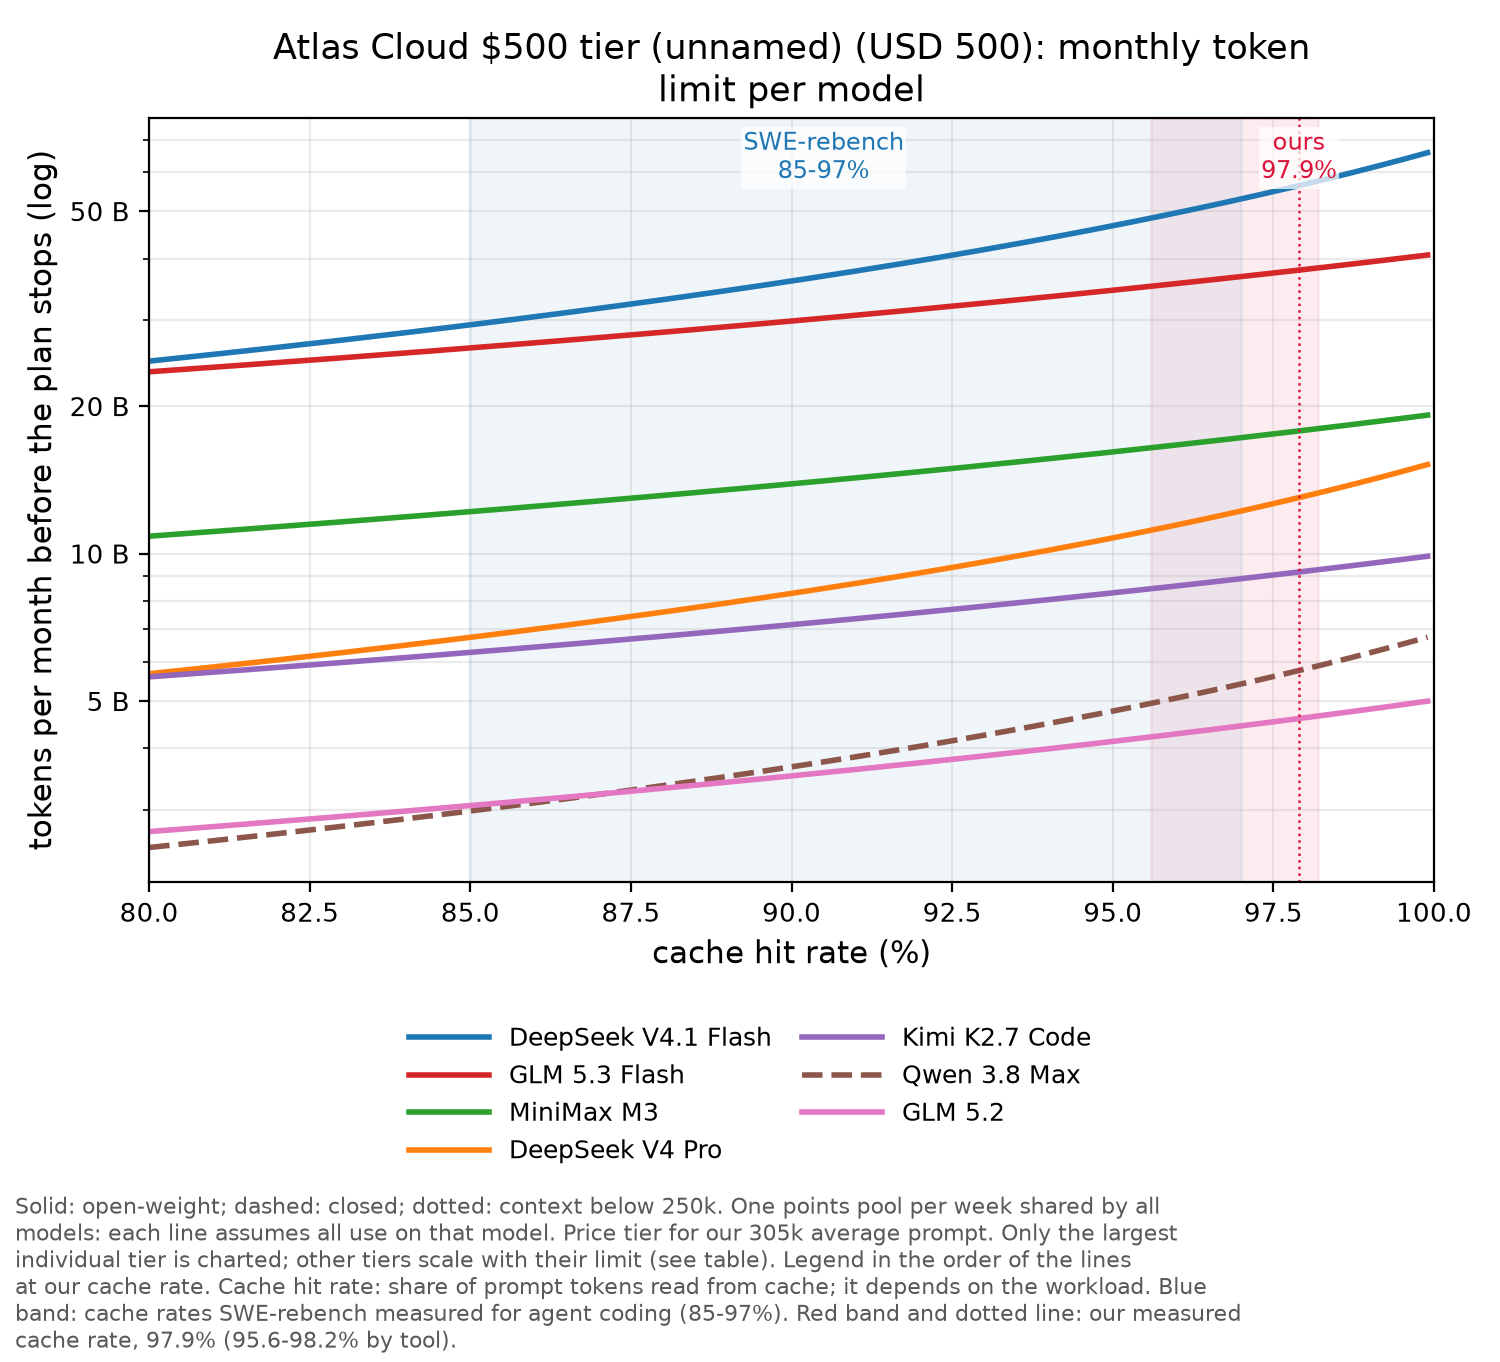
At our mix GLM 5.3 Flash (TB4 35.8%) gets 13 full Terminal-Bench 4.0 runs a month on $500 tier (unnamed). At our mix Qwen 3.8 Max (TB4 27%) gets 1.9 full Terminal-Bench 4.0 runs a month on $500 tier (unnamed).
Cursor
Anysphere, a San Francisco company founded in 2022, makes Cursor, an AI code editor and coding agent, and trains its own Composer models. SpaceX completed its acquisition of Anysphere on 14 August 2026 at an implied equity value of $60.0 billion. Since October 2026 new customers buy Cursor through xAI's X Subscription ($0–$200 a month), which pools Grok usage and bills third-party models at application programming interface (API) list prices.
What to know:
- Below the API: Cursor Ultra (legacy, USD 200) buys 0.62x the Opus 5.5 tokens the same money buys on Anthropic's API, about 0.37 B a month.
- Pool cut quietly: Users report the Ultra pool for third-party models fell from USD 400 to about USD 125 in September; most single-user readings sit between USD 122 and 127.
- No automation: The acceptable use policy bans access by bots or scripts.
- New buyers: X Subscription: Since October 2026 new customers buy The X Subscription; legacy plans continue for existing subscribers. Third-party models bill at API list price.
- No startup programme: Cursor has no open startup credit application.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Cursor Pro (legacy) | 20 | Two monthly pools (Cursor Models, Other Models); blog: at least USD 20 of inference at API prices | month |
| Cursor Pro+ (legacy) | 60 | usd_usage | month (not published) |
| Cursor Ultra (legacy) | 200 | 20x Pro (blog) | month |
- Models: Grok 4.7; Grok 4.6; Grok 4.5; Composer 2.5; third-party models at API list price
- Context: Max Mode extends context on legacy request-based plans at API rate +20%
- Third-party tools: not stated (BYOK inbound: own-key requests do not count toward usage)
- Automation: AUP bans access by automated or non-human means (bot, script)
- At the limit: Enable on-demand usage or upgrade
Measured and stated limits (39 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Pro (legacy) | (442 M–558 M) tokens | month | user | forum.cursor.com |
| Pro (legacy) | 923 USD | – | user | forum.cursor.com |
| Pro (legacy) | 20 USD Other Models pool | month | vendor | forum.cursor.com |
| Pro+ (legacy) | 1.5 B tokens | month | user | forum.cursor.com |
| Pro+ (legacy) | 2.5 B tokens | month | user | forum.cursor.com |
| Pro+ (legacy) | 1,472 USD | – | user | forum.cursor.com |
| Pro+ (legacy) | – USD Other Models | month | user | forum.cursor.com |
| Pro+ (legacy) | 70 USD Other Models pool | month | vendor | forum.cursor.com |
| Ultra (legacy) | 125 USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 3,000 USD Cursor Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 125 USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 125 USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 393 USD Other Models consumed | month | user | forum.cursor.com |
| Ultra (legacy) | 125.37 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | (123–125) USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | (122–126) USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 124 USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy) | 400 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | 500 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | (125–250) USD Other Models allowance… | month | user | forum.cursor.com |
| Ultra (legacy, SuperGrok-linked) | 100 USD Other Models pool | month | user | forum.cursor.com |
| Ultra (legacy, SuperGrok Heavy-linked) | 97.68 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | 260 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | 127 USD Other Models | month | user | forum.cursor.com |
| Ultra (legacy) | 2,019 USD | – | user | forum.cursor.com |
| Ultra (legacy) | 400 USD Other Models pool | month | vendor | forum.cursor.com |
| Pro | 100 USD of Cursor-model usage | month | user | reddit.com |
| Pro+ | 350 USD of Cursor-model usage | month | user | reddit.com |
| Ultra | 2,000 USD of Cursor-model usage | month | user | reddit.com |
| Pro | 360 USD total usage | month | user | reddit.com |
| Pro | 350 USD of Cursor-model usage… | month | user | reddit.com |
| Pro | 678 M tokens | month | user | reddit.com |
| Pro | 772 M tokens in 31-day period | month | user | reddit.com |
| Pro+ | 2.1 B tokens | month | user | reddit.com |
| Pro+ | 128 M tokens on Other Models pool | month | user | reddit.com |
| Pro | 87.1 M raw total tokens | month | user | github.com |
| Pro | 304 M raw total tokens | month | user | github.com |
| Pro | 300 USD Cursor Models pool | month | analyst | github.com |
| Pro+ | 450 USD Cursor Models pool | month | analyst | github.com |
The measured Ultra (legacy) limit of USD 100 a month (3 user readings, USD 98 to 125) buys 299 M tokens of Claude Opus 5.5 a month at our mix. One user reading puts Pro (legacy) at 500 M tokens a month (cursor-grok-4.6-medium, 73% cache). One user reading puts Pro at 678 M tokens a month (Grok + Composer, 90% cache).
The measured Ultra (legacy) limit buys 0.037 to 0.047 full Terminal-Bench 4.0 runs of Claude Opus 5.5 a month at our mix (3 user readings).
Warp
Warp is a New York company founded by Zach Lloyd, a former engineering lead on Google Docs. It sells an agentic development environment that grew out of its terminal and has been open source under the GNU Affero General Public License (AGPL) since April 2026. Its Oz platform runs coding agents in parallel in the cloud. Warp reported nearly one million developers in April 2026.
What to know:
- Below the API: Warp Max (USD 200) buys 0.52x the Kimi K3 tokens of the cheapest API offer at our mix (0.33x at 85% cache, 0.56x at 99%).
- Plain pass-through: Build and Max include USD 20 and USD 200 of agent usage at API rates, with no rollover. You pay list price for convenience.
- Automation with conflicting terms: Cloud agents run from Slack, Linear, schedules, CI and API, yet the terms ban automated access. Get written confirmation before you depend on it.
- Training conflict: Warp claims zero data retention with providers, but full zero data retention needs "Help Improve Warp" off, and the terms allow training on licensee data.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Build | 20 | $20 agent usage/mo at API rates; no rollover | month |
| Max | 200 | $200 agent usage/mo (10× Build); no rollover | month |
- Models: Fable 5;Claude Opus 5;GPT-5.6;Gemini 3.1 Pro;GLM 5.2;Kimi K3
- Context: not stated (model-dependent)
- Third-party tools: Claude Code/Codex harnesses on own credentials; BYOK + custom endpoints for orgs <=10 staff (conflict w/ pricing page)
- Automation: Cloud agents via Slack/Linear/schedule/CI/API triggers; ToS bans automated access (conflict)
- Training on your data: ZDR with providers; full ZDR needs 'Help Improve Warp' off; ToS allows training on Licensee Data (conflict)
- At the limit: Buy usage or auto-reload up to spend cap; purchased usage valid 12 months
NanoGPT
NanoGPT is run by NanoGPT LLC, a US limited liability company. Its co-founder and chief executive, Milan de Reede, is based in Amsterdam and dates the company to September 2024. It sells pay-as-you-go access to text, image and video models through a web app and an OpenAI-compatible application programming interface (API). A $12 monthly Pro subscription includes 60 million input tokens per week.
What to know:
- Worst multiple: Pro (USD 12) buys 0.13x the DeepSeek V4.1 Flash tokens of the cheapest API offer at our mix, because cached input counts in the 60M weekly allowance.
- Collapses at high cache: The multiple is 0.4x at 85% cache and 0.098x at 99%. Long sessions make it worse.
- Personal use only: API included, but only for personal non-commercial use, without serving multiple users.
- Cheapest Kimi K3: NanoGPT's pay-as-you-go Kimi K3 is 0.52x Moonshot's price, from aggregator data only and not confirmed on its own site.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Pro | 12 | 60M input-token units/week (2x models count double; cached input counts) + 100 images/day | week |
- Models: Text and image models per /api/subscription/v1/models; named: DeepSeek V4 Flash (latest)
- Context: 1,048,576 (DeepSeek V4 Flash latest only)
- Third-party tools: Yes, OpenAI-compatible; guides for OpenCode, Cline, Codex CLI, Claude Code, Cursor
- Automation: API included; personal non-commercial use only; no serving multiple users; no circumventing rate limits
- Training on your data: No training on input/output; no prompt/response logging by default; ZDR best-effort
- At the limit: Pauses (429) until Monday 00:00 UTC reset unless 'Use balance after limits' enabled
Factory: Droid
Factory is a company founded in 2023 by Matan Grinberg and Eno Reyes. It sells Droids, AI agents that enterprises use to build, test and maintain software. On 15 September 2026 it raised $200 million at a $5 billion valuation, up from $1.5 billion in April 2026, taking total funding above $400 million.
What to know:
- Multiples, hidden base: Plus is about 5x and Max about 10x Pro, and Pro's limits are not published. Per-model multipliers apply (Opus 5.5 1.6x, GPT-6.1 Sol 0.8x).
- One tracker reading: One tracker measured Max at USD 2,117 of Opus 5.5 API value a month (3.61 B raw tokens at 93.8% cache). Plus has no measurement.
- Built for automation: Droid CLI, SDK and cloud and local background agents are included; Missions need Extra Usage.
- Data used for product: Customer data feeds de-identified product improvement; zero data retention starts at Business.
- Soft landing: At the limit you drop to the Droid Core open-weight pool, then prepaid Extra Usage (USD 10 minimum, no expiry).
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Droid Pro | 20 | Rolling Rate Limits, numbers not published; per-model multipliers (e.g. Opus 5.5 1.6x, GPT-6.1 Sol 0.8x) | mixed (not published) |
| Droid Plus | 100 | ~5x Pro | mixed |
| Droid Max | 200 | ~10x Pro | mixed |
- Models: Claude Fable 5.1; Claude Opus 5.5; Claude Sonnet 5.5; GPT-6.1 Sol; GPT-6 Astra; Gemini; Grok
- Third-party tools: BYOK custom models free up to an allowance; outbound use of plan not stated
- Automation: Droid CLI and SDK; cloud and local background agents; Missions need Extra Usage; licence internal use only; adds Droid Computers and early feature access
- Training on your data: Customer Data used internally to make aggregated de-identified data for product improvement
- At the limit: Droid Core open-weight pool, then Extra Usage prepaid credits (USD 10 min, no expiry)
Measured and stated limits (10 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Pro | 1 hours of use = 6% of 5h wi… | 5h | user | linkedin.com |
| Max (earlier Pro) | 585 M tokens over 14 days withou… | – | user | x.com |
| Max | 902 M raw tokens | week | tracker | github.com |
| Max | 3.61 B raw tokens | month | tracker | github.com |
| Max | 2,116.91 USD of Opus 5.5 API list p… | month | tracker | github.com |
| Max | 5.05 B (4.49 B–5.77 B) tokens | month | tracker | github.com |
| Max (legacy token-metered, 2025-12) | 200 M Standard Tokens | month | vendor | usagepricing.com |
| Ultra (legacy token-metered, 2025-12) | 2 B Standard Tokens | month | vendor | usagepricing.com |
| Pro (legacy token-metered, 2025-12) | 20 M Standard Tokens | month | vendor | usagepricing.com |
| Pro (legacy token-metered, 2025-10) | 20 M Standard Tokens | month | vendor | usagepricing.com |
- No measurement found: Plus.
Two tracker readings put Max at 3.61 B to 3.87 B tokens a month (claude-opus-5-5, 93.82% cache).
Devin Desktop (formerly Windsurf)
Cognition is a United States company that builds the coding agent Devin. It acquired the Windsurf editor in July 2025. On 2 June 2026 it renamed Windsurf to Devin Desktop, an integrated development environment (IDE) that manages local and cloud agents, and kept plans and pricing unchanged. On 8 September 2026 Cognition raised $2 billion at a $48 billion valuation and reported run-rate revenue of nearly $900 million.
What to know:
- No price, no limit: Current Pro and Max prices are not in sources and limits are unpublished. The only readings are vendor message counts per day from March 2026.
- Own surfaces only: Desktop, CLI, sessions and the JetBrains plugin; use from other agents is not in sources. CI/CD needs service user keys.
- Credits that keep: At the limit on-demand credits bill at API list prices, roll over and never expire. Teams cost USD 40 per full seat, USD 80 minimum per team.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Pro | current price not stated; existing s… | not published | mixed (not published) |
| Max | price not stated | not published | week (not published) |
- Models: SWE-2;SWE-1.7;SWE-1.6;Fusion;Gemini 3.7 Flash/3.8 Flash/4 Argon;GPT-6 Astra;Claude Fable 5.1;Claude Opus 4.6 (no Max-specific list)
- Third-party tools: Devin's own surfaces (Desktop, CLI, sessions), JetBrains plugin; use from other agents not stated
- Automation: PATs for personal scripts/short-lived automation; CI/CD needs service user keys; Pro rules not stated
- At the limit: Pay-as-you-go on-demand credits at API list prices; roll over, never expire
Measured and stated limits (3 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Devin Desktop Pro | (7–27) messages | day | vendor | devin.ai |
| Devin Desktop Pro | (8–101) messages | day | vendor | devin.ai |
| Devin Desktop Max | (42–170) messages | day | vendor | devin.ai |
Google: AI Pro and Ultra
Google, part of Alphabet, sells its Gemini models through the Gemini API with Google AI Studio and through Vertex AI on Google Cloud. Google AI Pro and Ultra subscriptions raise AI Studio quotas; consumer sign-in to Gemini CLI, including for those subscribers, ended on 18 June 2026 and moved to Google's Antigravity tools. In July 2026 Alphabet said its model APIs processed about 22 billion tokens per minute.
What to know:
- No convertible limit: Ultra is published as 5x and 20x Pro, and Pro has no base amount. Neither Ultra tier has a measurement; AI Pro has one tracker and one user reading.
- Google tools only: Consumer sign-in to Gemini CLI ended on 18 June 2026; the plans work in Antigravity, Code Assist and Jules. Third-party tool use and headless use are not in sources.
- Own agent: AI Studio: Pro includes USD 10 a month of Gemini API credits, Ultra 20x USD 100. Beyond that, Gemini 4 Argon costs USD 0.157 per 1M at our mix, 0.313 from 1 December.
- Soft limit: At the limit the plans fall back to Flash-Lite or draw AI credits, and every tier offers 1M context, so long sessions do not hit a hard stop.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Google AI Pro | USD price not stated; GBP 18.99/mont… | 4x standard (Free) limits in Gemini app; Antigravity Entry rate limits; CLI numbers not stated | 5h+week |
| Google AI Ultra (5x) | 100 | 5x Pro | 5h+week |
| Google AI Ultra (20x) | 200 | 20x Pro; Antigravity agent requests Highest | 5h+week |
| Gemini CLI / Code Assist / Antigravity (in AI Pro and Ultra) | Included in AI Pro and Ultra; Developer … | Code Assist editions: 1500 (Standard) / 2000 (Enterprise) per user per day; Antigravity baseline quota and consumer CLI numbers not publishe… | day (not published) |
- Models: Gemini 4 Argon; Gemini 3.1 Pro; Gemini 3.5 Flash; Gemini 3 Pro (Antigravity); Claude 4.5 Sonnet (Antigravity); Jules (higher Argon access, priority Antigravity)
- Context: Google AI Pro: 1M (Gemini app); Google AI Ultra (5x): 1M; Google AI Ultra (20x): 1M; Gemini CLI / Code Assist / Antigravity (in AI Pro and Ultra): Code Assist local codebase awareness 1M
- Third-party tools: not stated (Google tools only: Gemini CLI, Code Assist, Antigravity, Jules)
- Automation: Code Assist on GitHub at least 100 PR reviews/day; nothing on headless subscription use
- Training on your data: Antigravity/CLI not stated; Android Studio code protected from training; AI Studio free tier used to improve products
- At the limit: Google AI Pro, Google AI Ultra (5x), Google AI Ultra (20x): Flash-Lite fallback; buy AI credits for Antigravity and Flow; Antigravity overage toggle; Gemini CLI / Code Assist / Antigravity (in AI Pro and Ultra): Antigravity: notify or auto-use AI credits; Code Assist: stops until quota resets
Measured and stated limits (18 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Google AI Pro | 80 agent tasks | week | tracker | electricitybench.com |
| Google AI Pro | 120 agent tasks | week | tracker | electricitybench.com |
| Google AI Pro | 214 USD of API value | week | user | discuss.ai.google.dev |
| Google AI Pro | 100 Jules tasks | day | vendor | developertoolkit.ai |
| Google AI Ultra 5x | 300 Jules tasks | day | vendor | developertoolkit.ai |
| Google AI Ultra 20x | 300 Jules tasks | day | vendor | developertoolkit.ai |
| Google AI Pro | 19.92 USD of API value | 5h | user | discuss.ai.google.dev |
| Google AI Pro | 100 Jules tasks | day | vendor | quotawire.com |
| Google AI Ultra (5x and 20x) | 300 Jules tasks | day | vendor | quotawire.com |
| Google AI Pro (Gemini CLI, discontinued … | 1,500 Gemini CLI requests | day | vendor | quotawire.com |
| Google AI Ultra (Gemini CLI, discontinue… | 2,000 Gemini CLI requests | day | vendor | quotawire.com |
| Google AI Pro | 10 USD Google Cloud / Gemini… | month | vendor | blog.laozhang.ai |
| Google AI Ultra 5x (20 TB tier, mapping … | 40 USD Google Cloud / Gemini… | month | vendor | blog.laozhang.ai |
| Google AI Ultra 20x (30 TB tier, mapping… | 100 USD Google Cloud / Gemini… | month | vendor | blog.laozhang.ai |
| Google AI Pro | 250 Antigravity units | 5h | user | github.com |
| Google AI Pro | 2,800 Antigravity units | week | user | github.com |
| Google AI Pro | 1,000 Google One AI credits | month | vendor | github.com |
| Google AI Ultra (tier not stated) | 25,000 Google One AI credits | month | vendor | github.com |
OpenCode: Go, Go Plus and Zen
OpenCode is an open-source coding agent built by Anomaly, the team behind SST. Its site reports more than 16 million developers a month and 208,000 GitHub stars. Next to the free agent, OpenCode sells model access: Zen per token and Go as a subscription.
What to know:
- Good for GLM 5.3: Go Plus (USD 40) covers 0.82 B GLM 5.3 tokens a month at our mix, billed at Z.ai's list rates. The ceiling stops below 1 B.
- Per-model caps: Go Plus allows USD 60 to 240 per model a month, with 20% of it per 5 hours and 50% per week.
- Any agent, coding only: Every agent is allowed, but traffic must be coding-agent use with its own user agent and session ID, and it is monitored.
- Training per model: Most open models run at zero retention; GPT, Claude and Grok keep 30 days; Gemini 4 Argon Contributor and Muse Spark Contributor train.
- Optional overflow: At the limit calls block unless "Use balance" is on, which falls back to the pay-as-you-go Zen balance.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Go | 10 | $15-$80 per model/mo; 5h = 20%, week = 50% of monthly | mixed |
| Go Plus | 40 | $60-$240 per model/mo; 5h = 20%, week = 50% of monthly | mixed |
- Models: GLM-5.3/5.3 Flash/5.2;Kimi K3/K2.7 Code;DeepSeek V4.1 Flash/V4 Pro;Qwen3.8 Max/Flash;Qwen3.7 Plus;MiniMax M3;MiMo V2.5/2.5 Pro/2.6 Flash/2.6 Pro;Claude Haiku 5.5;GPT 6/5.6 Luna;Gemini 4 Argon;Grok 4.7
- Third-party tools: Yes, any agent; validated: Hermes, Claude Code, Codex, ZCode, Pi, jcode, Kilo Code CLI
- Automation: Coding-agent traffic only, own user agent + session ID; monitored for abuse; API endpoints provided
- Training on your data: Per model: most open models not used, 0-day retention; GPT/Claude/Grok 30 days; Gemini 4 Argon & Muse Spark Contributor train, not ZDR
- At the limit: Blocked unless 'Use balance' enabled (falls back to pay-as-you-go Console balance)
Tokens per month at our mix; a separate USD limit per model.
| Model | Weights | Rate per 1M (input / cached / output, plan units) | Context in plan | TB4 | Go (USD 10) | Go Plus (USD 40) |
|---|---|---|---|---|---|---|
| Gemini 4 Argon Contributor | no | 4 / 0.2 / 20 | 1M | 57.1 | 0.19 B | 0.77 B |
| GLM 5.3 | yes | 1.4 / 0.26 / 4.4 | 1M | 41.8 | 0.21 B | 0.82 B |
| Claude Haiku 5.5 (above 100k prompt) | no | 0.5 / 0.05 / 2.5 | 1M | 39.2 (vendor) | 0.91 B | 3.62 B |
| Grok 4.7 (above 200k prompt) | no | 4 / 1 / 12 | 500k | 37.6 | 0.06 B | 0.22 B |
| GLM 5.3 Flash | yes | 0.15 / 0.03 / 0.5 | 1M | 35.8 | 1.80 B | 7.20 B |
| MiMo V2.6 Pro | yes | 0.435 / 0.0036 / 0.87 | 1M | 34.8 | 4.24 B | 16.97 B |
| Step 5 Preview | yes | 1 / 0.1 / 2.7 | 1M | 33.3 | 0.49 B | 1.95 B |
| DeepSeek V4.1 Flash | yes | 0.3 / 0.006 / 1.2 | 1M | 31.2 (vendor) | 4.23 B | 16.91 B |
| MiMo V2.6 Flash | yes | 0.14 / 0.0028 / 0.28 | 1M | 28.8 (vendor) | 9.76 B | 39.04 B |
| Qwen 3.8 Max | no | 2 / 0.25 / 6 | 1M | 27 | 0.20 B | 0.78 B |
| GPT-6 Luna (above 272k prompt) | no | 0.2 / 0.02 / 0.75 | 1.1M | 16.4 | 2.30 B | 9.21 B |
| DeepSeek V4 Pro | yes | 1.32 / 0.044 / 3.96 | 1M | 14 | 0.78 B | 3.10 B |
| Kimi K3 | yes | 3 / 0.3 / 15 | 1M | 12.6 | 0.16 B | 0.63 B |
| MiniMax M3 | yes | 0.3 / 0.06 / 1.2 | 1M | 2 | 0.90 B | 3.58 B |
| Kimi K2.7 Code | yes | 0.95 / 0.19 / 4 | 262k | 1 | 0.28 B | 1.13 B |
| Qwen 3.8 Flash | yes | 0.15 / 0.016 / 0.47 | 1M | – | 2.91 B | 11.63 B |
| GLM 5.2 | yes | 1.4 / 0.26 / 4.4 | 1M | – | 0.21 B | 0.82 B |
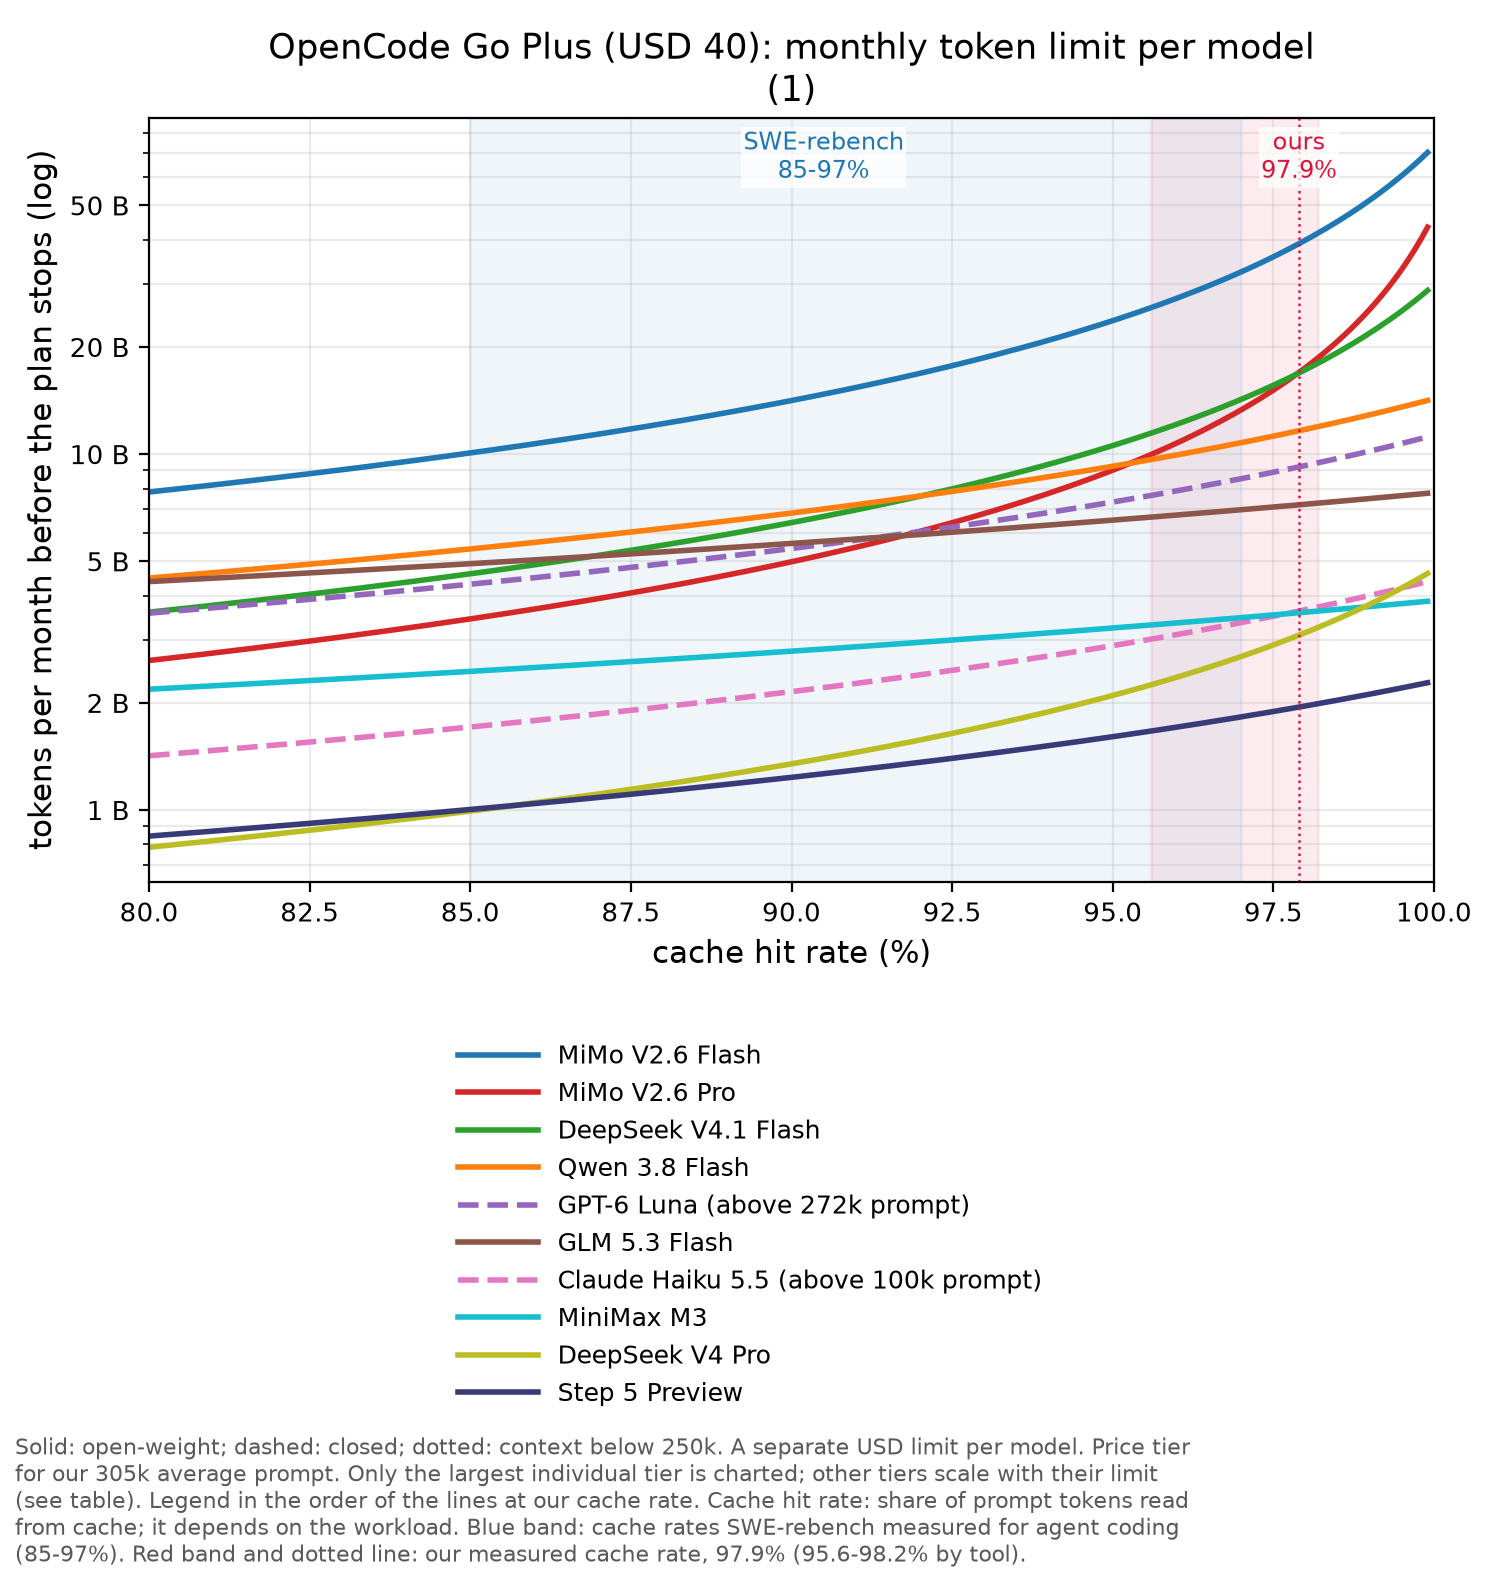
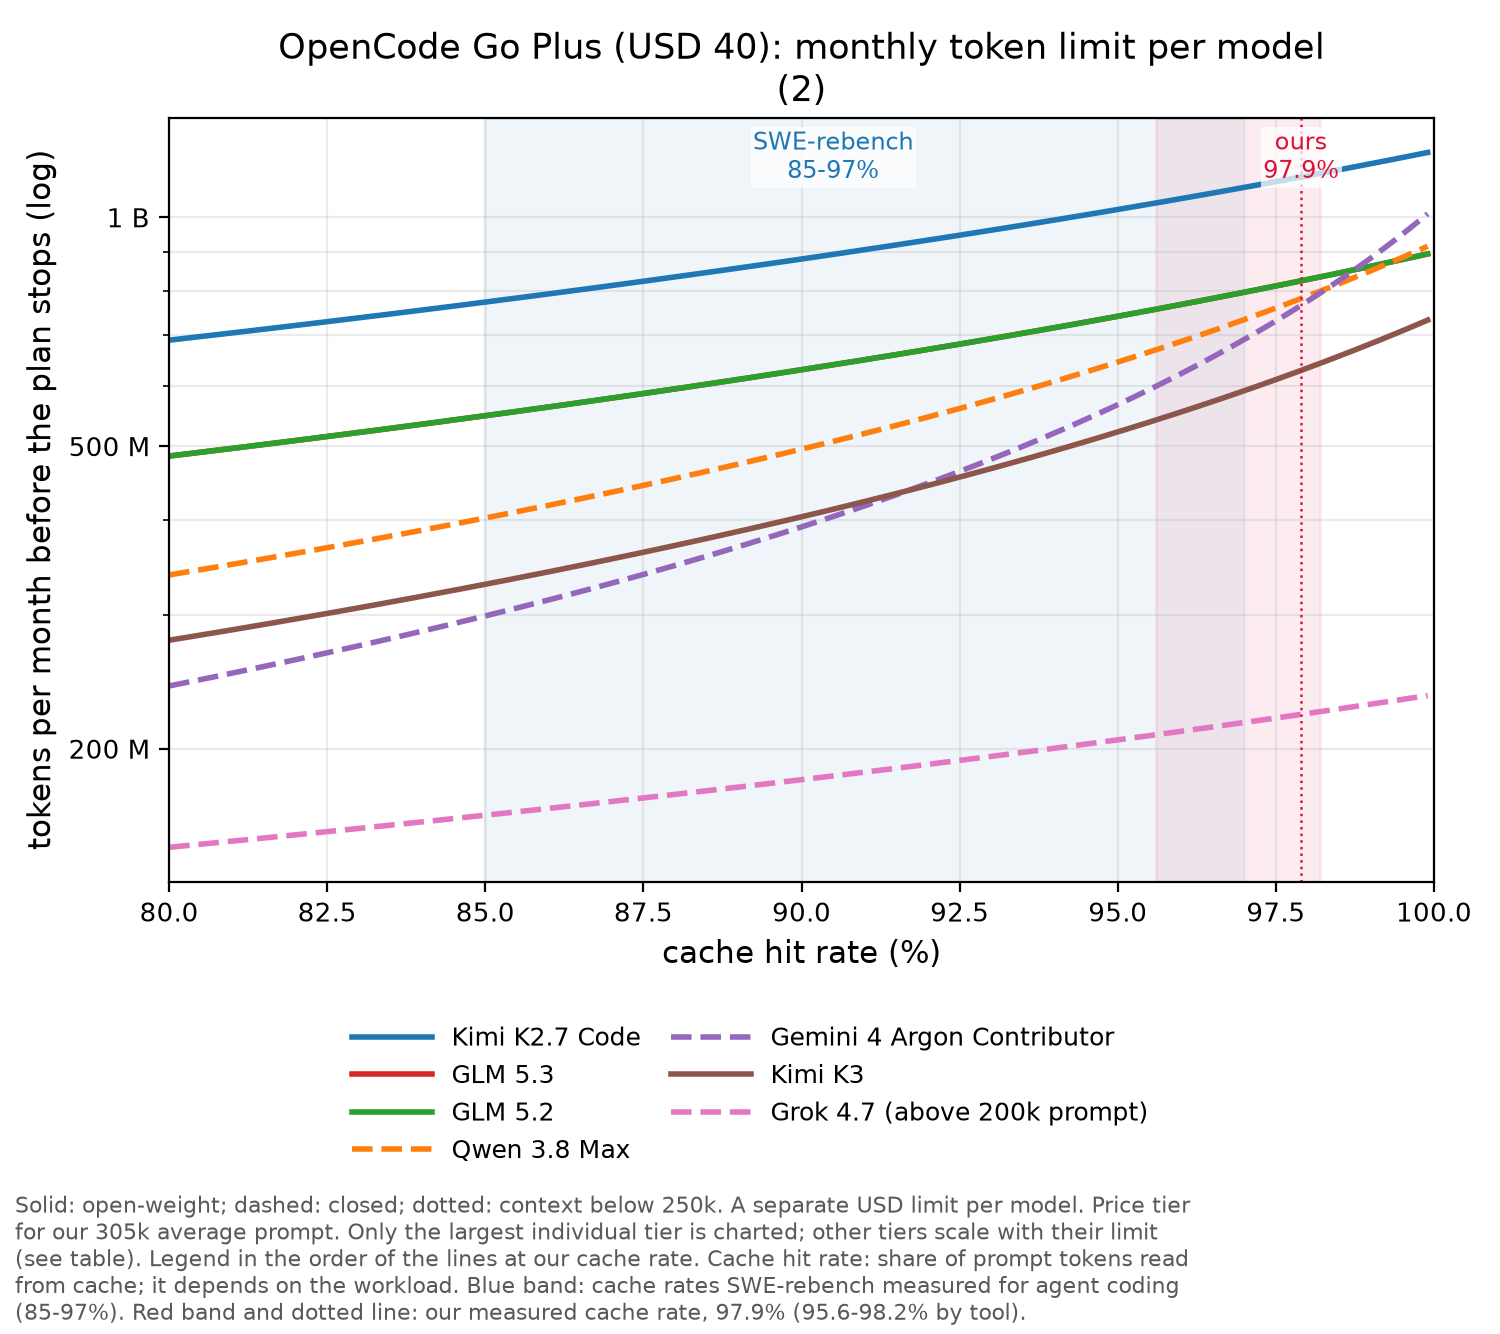
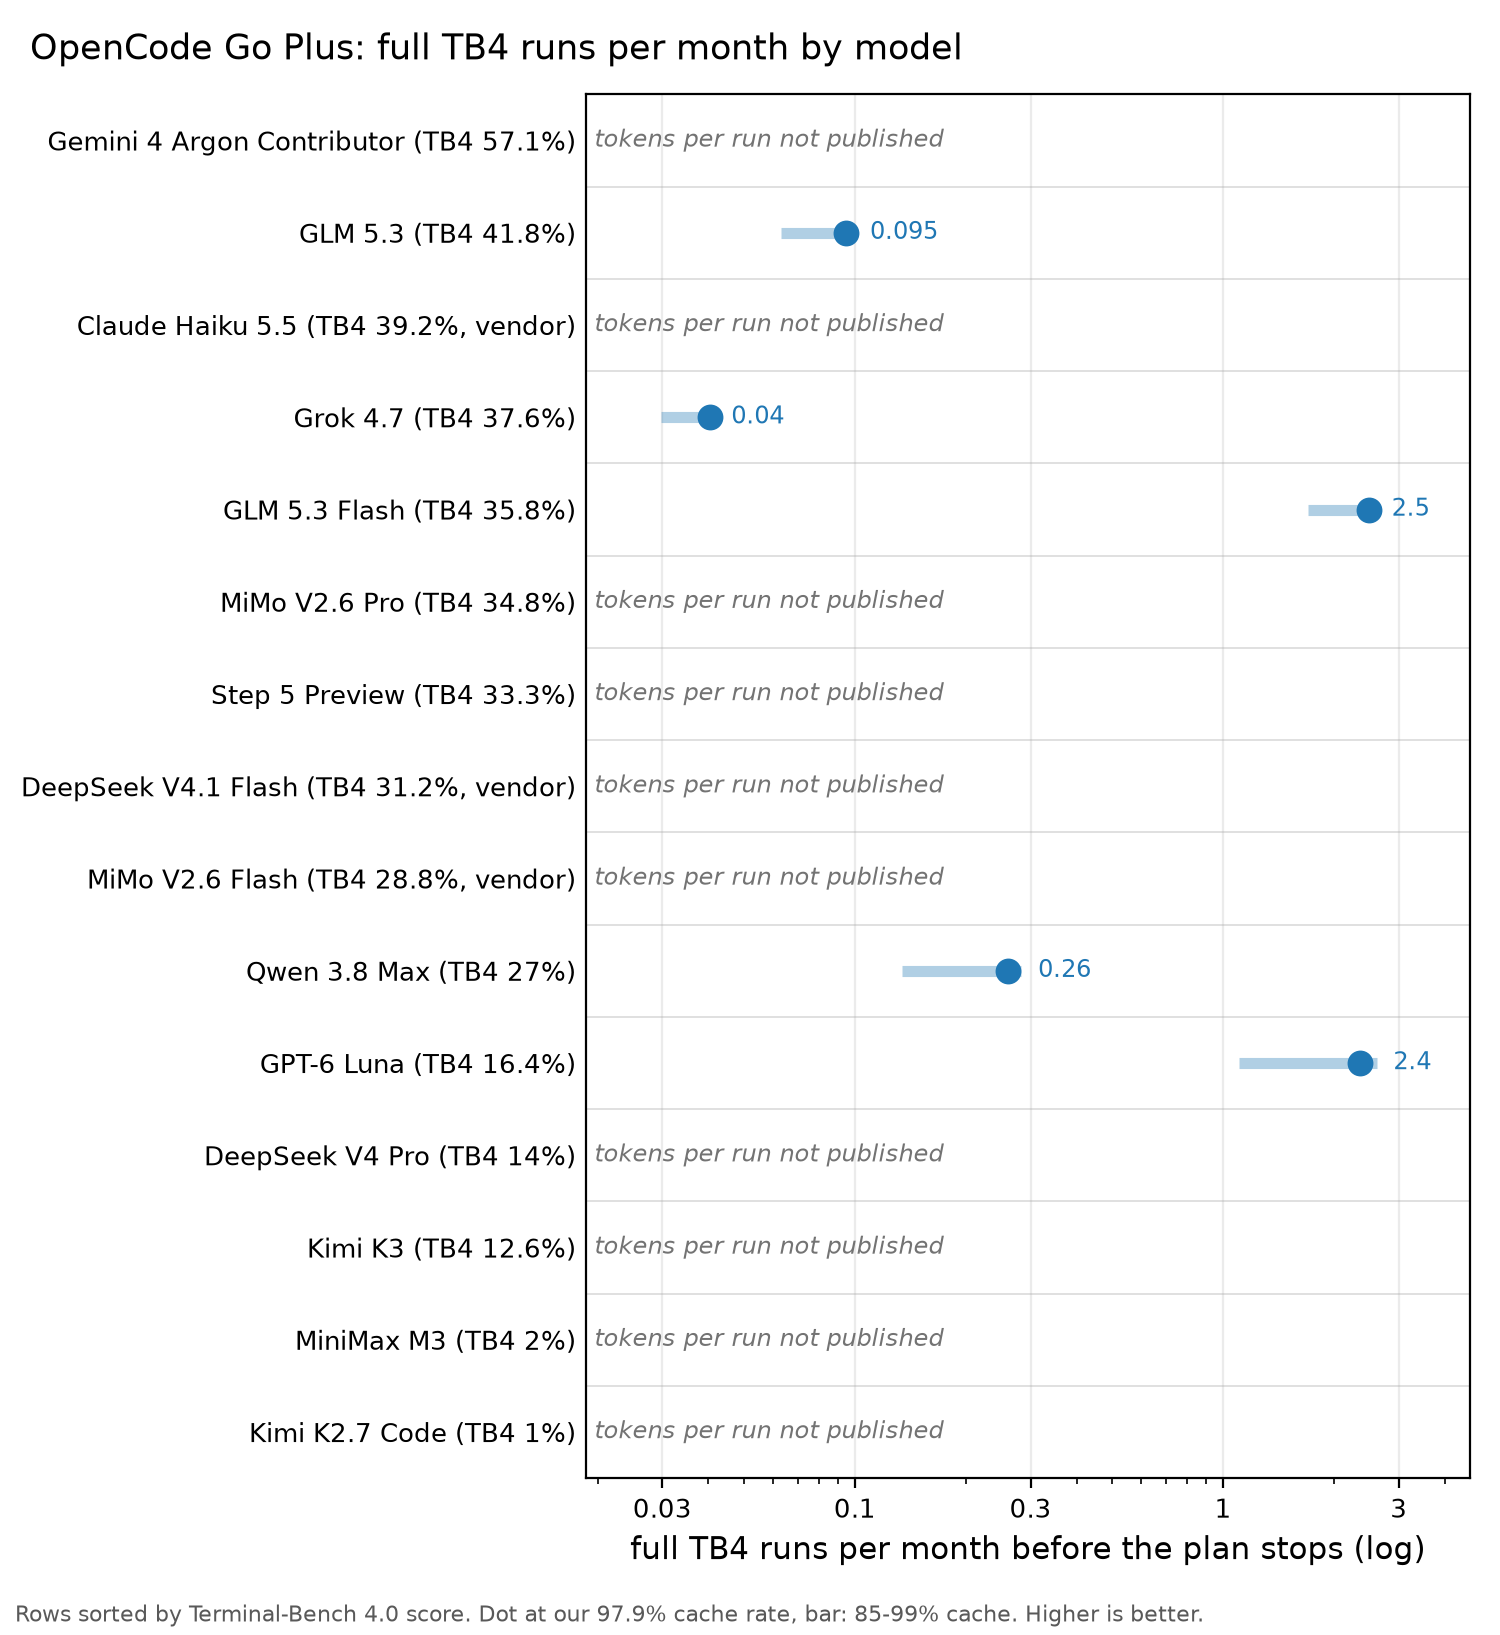
BytePlus / Volcengine: Coding Plan
ByteDance sells its models through two enterprise units: Volcengine in China and BytePlus, its Singapore-based international arm. Both run a model platform (Volcano Ark at home, ModelArk abroad) serving ByteDance's Seed models (Doubao in China, Dola-Seed abroad) plus DeepSeek, GLM and other open-weight models, and both sell a Coding Plan for third-party coding tools. Volcengine said on 2 April 2026 that Doubao usage passed 120 trillion tokens a day.
What to know:
- Two published limits: Lite (USD 10) lists about 1,900 requests per 5 hours on one page and about 1,200 in the FAQ; Pro 9,500 against 6,000. Plan on the lower figure.
- Compute, not requests: Support says quota is metered by compute. Single users on the China Pro plan report 770 M to 6 B tokens a month, so the limit is not known.
- 1M models included: GLM-5.3-Flash, DeepSeek V4.1 Flash and V4 Pro run at 1M context; Kimi-K2.5 (256k) passes the floor, GLM-5.1 (200k) does not. GLM 5.3 is not in the plan.
- Hard stop, no API: The plan works in Claude Code, OpenCode, Cursor and others, not for direct API calls, and stops until the next cycle.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Coding Plan Lite | 10 | 5h: ~1,900; week: ~12,000; month: ~24,000 (FAQ: ~1,200 / 9,000 / 18,000) | mixed |
| Coding Plan Pro | 50 | 5h: ~9,500; week: ~60,000; month: ~120,000 (FAQ: ~6,000 / 45,000 / 90,000) | mixed |
- Models: Auto; Dola-Seed-2.0-Pro; Dola-Seed-2.0-Lite; Dola-Seed-2.0-Code; ByteDance-Seed-Code; Kimi-K2.5; GLM-5.1; GLM-5.2; GLM-5.3-Flash; DeepSeek-V4-Flash; DeepSeek-V4-Pro; DeepSeek-V4.1-Flash; GPT-OSS-120b
- Context: 1M for glm-5.2, glm-5.3-flash, deepseek-v4.1-flash, deepseek-v4-flash, deepseek-v4-pro; Kimi-K2.5 256k; GLM-5.1 200k
- Third-party tools: yes: Claude Code, OpenCode, OpenClaw, TraeCode, Cline, Cursor, Codex, Roo Code, Kilo Code, Hermes Agent; shared quota
- Automation: AI coding tools only, not for API calls; misuse may deactivate subscription or suspend account
- At the limit: stops until next cycle; other packages and account balance not consumed
Measured and stated limits (11 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Volcengine Ark Coding Plan Pro (CN ¥200) | 770 M tokens | month | user | linux.do |
| Volcengine Ark Coding Plan Pro (CN ¥200) | 2 B (2 B–6 B) tokens | month | user | x.com |
| Volcengine Ark Coding Plan Lite (CN ¥40) | 10 M tokens | 5h | tracker | github.com |
| Volcengine Ark Coding Plan Lite (CN) | 200 model calls | 5h | user | linux.do |
| Volcengine Ark Coding Plan (flagship mod… | 50 CNY | month | analyst | 163.com |
| ModelArk Coding Plan Lite (intl $10) | 65 requests until 5h window e… | 5h | user | reddit.com |
| ModelArk Coding Plan Lite (intl $10) | – quota metered by compute | 5h | vendor | reddit.com |
| ModelArk Coding Plan Lite (intl $10) | 1,900 requests | 5h | vendor | docs.byteplus.com |
| ModelArk Coding Plan Lite (intl $10) | 1,200 requests | 5h | vendor | docs.byteplus.com |
| ModelArk Coding Plan Pro (intl $50) | 9,500 requests | 5h | vendor | docs.byteplus.com |
| ModelArk Coding Plan Pro (intl $50) | 6,000 requests | 5h | vendor | docs.byteplus.com |
One user reading puts Volcengine Ark Coding Plan Pro (CNY) at 770 M tokens a month (GLM-5.2, 93% cache).
Tencent Cloud: Coding Plan and Token Plan
Tencent, the Shenzhen-based internet group, sells models through TokenHub, an OpenAI- and Anthropic-compatible Tencent Cloud platform serving its own Hy (Hunyuan) models plus DeepSeek, Kimi, GLM, MiniMax and MiMo. It sells a Coding Plan in China and a Token Plan abroad from $7 a month, and builds CodeBuddy, a coding editor, plugin and command-line tool. Its capital expenditure rose 176% year on year to 52.8 billion yuan in the second quarter of 2026.
What to know:
- Low GLM volume: Tencent's China page estimates 399 M GLM-5.3 tokens a month on Personal Max. Z.ai's own Max converts to 3.25 B GLM 5.3 tokens for USD 168.
- Credits, no conversion: International Personal Max (USD 103) gives 15,900 credits a month; per-model deduction rules are not in the catalogue as token rates.
- API calls prohibited: Supported tools only (CodeBuddy Code, Claude Code, OpenCode, Cline and others); scripts and batch are banned, though the tier text names CI automation. Get that conflict resolved in writing.
- Check context per model: The plan states no context; models range from Kimi K3 at 1M to GLM-5.2 at 200K, below the 250k floor.
- Unused credits forfeited: Credits restore next cycle without touching other balances, unused ones expire, and downgrades are not refunded.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| TokenHub Token Plan Personal Lite (intl, Singapore) | 7 | 1000 per month; ~70 Q&A rounds (vendor); trial use | month |
| TokenHub Token Plan Personal Standard (intl, Singapore) | 17 | 2600 per month; ~200 Q&A rounds (vendor) | month |
| TokenHub Token Plan Personal Pro (intl, Singapore) | 51 | 7900 per month; ~600 Q&A rounds (vendor) | month |
| TokenHub Token Plan Personal Max (intl, Singapore) | 103 | 15900 per month; ~1,200 Q&A rounds (vendor) | month |
| TokenHub Coding Plan Lite (China site) | CNY 40/month list price; yearly not in s… | 5h: ~1,200; week: ~9,000; month: ~18,000 | mixed |
| TokenHub Coding Plan Pro (China site) | CNY 200/month list price; yearly not in … | 5h: ~6,000; week: ~45,000; month: ~90,000 | mixed |
| TokenHub Token Plan Enterprise Professional (China site) | not stated | not published | not stated (not published) |
| TokenHub Token Plan Enterprise Light (China site) | not stated | not published | not stated (not published) |
| CodeBuddy Free (intl) | 0 | 100 per month | month |
| CodeBuddy Pro (intl) | 10 | 2,000 per month (1,000 base + 1,000 bonus) | month |
| CodeBuddy Team (intl) | 40 | 1,000 per seat per month (team pool) | month |
- Models: TokenHub Token Plan Personal Lite (intl, Singapore), TokenHub Token Plan Personal Standard (intl, Singapore), TokenHub Token Plan Personal Pro (intl, Singapore), TokenHub Token Plan Personal Max (intl, Singapore), TokenHub Token Plan Enterprise Professional (China site), TokenHub Token Plan Enterprise Light (China site): Auto; GLM-5; GLM-5.1; GLM-5.2; GLM-5-Turbo; Kimi-K2.5; Kimi-K2.6; Kimi K2.7 Code; Kimi K2.7 Code HighSpeed; MiniMax-M2.5; MiniMax-M2.7; MiniMax-M3; DeepSeek-V4-…; TokenHub Coding Plan Lite (China site), TokenHub Coding Plan Pro (China site): Auto (tc-code-latest) only; CodeBuddy Free (intl): Auto scheduling only (model names not stated); CodeBuddy Pro (intl): all models selectable (names not stated); CodeBuddy Team (intl): not stated (Enterprise Model Configuration listed)
- Context: not stated (per-model only, e.g. Kimi K3 1M, GLM-5.2 200K)
- Third-party tools: TokenHub Token Plan Personal Lite (intl, Singapore), TokenHub Token Plan Personal Standard (intl, Singapore), TokenHub Token Plan Personal Pro (intl, Singapore), TokenHub Token Plan Personal Max (intl, Singapore), TokenHub Coding Plan Lite (China site), TokenHub Coding Plan Pro (China site): supported tools only: CodeBuddy Code, Claude Code, OpenCode, Cline, Cursor, Kilo Code, Roo Code, OpenClaw, WorkBuddy, Hermes Agent; TokenHub Token Plan Enterprise Professional (China site), TokenHub Token Plan Enterprise Light (China site), CodeBuddy Team (intl): CodeBuddy IDE and CLI documented; others not stated; CodeBuddy Free (intl), CodeBuddy Pro (intl): not stated (CodeBuddy Code can use third-party models via API key + base URL)
- Automation: TokenHub Token Plan Personal Lite (intl, Singapore), TokenHub Token Plan Personal Standard (intl, Singapore), TokenHub Token Plan Personal Pro (intl, Singapore), TokenHub Token Plan Personal Max (intl, Singapore): API calls strictly prohibited; no scripts, custom backends or non-interactive batch; suspension or key revocation (tier text names CI automation: conflict); TokenHub Coding Plan Lite (China site), TokenHub Coding Plan Pro (China site): API calls strictly prohibited; coding tools only; no scripts, backends or batch; personal development only; CodeBuddy Free (intl), CodeBuddy Pro (intl): 15 automated tasks; CI/CD token auth; ToS bans robots/data mining; CodeBuddy Team (intl): OpenAPI availability; OAuth client credentials for CI/CD (needs CodeBuddy Premium)
- Training on your data: CodeBuddy Free (intl), CodeBuddy Pro (intl): intl: no explicit training clause; China free edition: de-identified data used for optimization unless you object; CodeBuddy Team (intl): Enterprise agreement: no training without opt-in (applicability to Team not stated)
- At the limit: TokenHub Token Plan Personal Lite (intl, Singapore), TokenHub Token Plan Personal Standard (intl, Singapore), TokenHub Token Plan Personal Pro (intl, Singapore), TokenHub Token Plan Personal Max (intl, Singapore): restored next cycle; no other packages or balance consumed; unused credits forfeited; upgrade only, no refund; CodeBuddy Free (intl): not stated; credits do not roll over; CodeBuddy Pro (intl): top-up packs from 500 credits/$15; no rollover; non-refundable; CodeBuddy Team (intl): top-up packs (same table as Pro); non-refundable
Measured and stated limits (18 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Token Plan Personal Lite (CN, general) | 25.9 M tokens | month | vendor | cloud.tencent.com |
| Token Plan Personal Standard (CN, genera… | 65.9 M tokens | month | vendor | cloud.tencent.com |
| Token Plan Personal Pro (CN, general) | 199 M tokens | month | vendor | cloud.tencent.com |
| Token Plan Personal Max (CN, general) | 399 M tokens | month | vendor | cloud.tencent.com |
| TokenHub Coding Plan Lite (CN ¥40) | 1,200 model calls | 5h | vendor | cloud.tencent.com |
| TokenHub Coding Plan Lite (CN ¥40) | 9,000 model calls | week | vendor | cloud.tencent.com |
| TokenHub Coding Plan Lite (CN ¥40) | 18,000 model calls | month | vendor | cloud.tencent.com |
| TokenHub Coding Plan Pro (CN ¥200) | 6,000 model calls | 5h | vendor | cloud.tencent.com |
| TokenHub Coding Plan Pro (CN ¥200) | 45,000 model calls | week | vendor | cloud.tencent.com |
| TokenHub Coding Plan Pro (CN ¥200) | 90,000 model calls | month | vendor | cloud.tencent.com |
| Token Plan Personal Lite (intl USD 7) | 1,000 credits | month | vendor | intl.cloud.tencent.com |
| Token Plan Personal Standard (intl USD 1… | 2,600 credits | month | vendor | intl.cloud.tencent.com |
| Token Plan Personal Pro (intl USD 51) | 7,900 credits | month | vendor | intl.cloud.tencent.com |
| Token Plan Personal Max (intl USD 103) | 15,900 credits | month | vendor | intl.cloud.tencent.com |
| Token Plan Personal Lite (CN ¥39) | 35 M tokens | month | vendor | owent.net |
| Token Plan Personal Standard (CN ¥99) | 100 M tokens | month | vendor | owent.net |
| Token Plan Personal Pro (CN ¥299) | 320 M tokens | month | vendor | owent.net |
| Token Plan Personal Max (CN ¥599) | 650 M tokens | month | vendor | owent.net |
ClinePass
Cline Bot Inc. makes Cline, an open-source coding agent for VS Code, JetBrains editors and the terminal. In July 2025 it announced $32 million in seed and Series A funding, with a San Francisco dateline. ClinePass is its $9.99-a-month plan with quota-based access to open-weight coding models, which other coding agents can use through an application programming interface (API) key. In October 2026 its site claimed more than 11 million installs.
What to know:
- Cheap, size unknown: USD 9.99 a month for "2-5x usage vs standard API rate"; absolute amounts are not published.
- One user's numbers: One user measured USD 5 of Kimi K3 API value per 5-hour window, about 20% of the month by that user's reading.
- Automation allowed: Own scripts, apps and automation may use the ClinePass API key, rare in this price range. GLM 5.3 and Kimi K3 are in the plan; training terms are not in sources.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| ClinePass | 9.99 | 2-5x usage vs standard API rate; absolute amounts not published | mixed (not published) |
- Models: GLM 5.3 Flash;GLM 5.3;Kimi K3;DeepSeek V4 Pro;DeepSeek V4.1 Flash;MiniMax M3;MiMo V2.5 Pro;MiMo V2.5;Qwen3.7-Max;Qwen3.7-Plus;Qwen3.8-Max
- Third-party tools: Yes, with ClinePass API key (OpenAI-compatible Cline API)
- Automation: Allowed from own scripts, apps or automation via Cline API
Measured and stated limits (5 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| ClinePass | 5 USD of API value | 5h | user | linux.do |
| ClinePass | 25 USD of API value | month | user | linux.do |
| ClinePass | 400 USD | – | user | linux.do |
| ClinePass | 4.48 M tokens | 5h | user | github.com |
| ClinePass | (20–50) USD | month | analyst | standardcompute.com |
The measured ClinePass limit of USD 25 a month (1 user reading) buys 65.5 M tokens of Kimi K3 a month at our mix.
xAI: SuperGrok and X Subscription
xAI, Elon Musk's AI company, has been part of SpaceX since a February 2026 all-stock deal that valued xAI at $250 billion; its developer documentation now carries SpaceX branding. It sells Grok models by the token, including grok-4.7 and the coding model grok-build-0.1, and ships the Grok Build coding agent for the terminal. SpaceX raised $75 billion in its June 2026 Nasdaq initial public offering.
What to know:
- Pool shared with Cursor: The X Subscription (USD 8 to 200) pools Grok and Cursor usage per week as multiples of Plus (4x, 15x, 50x); Plus's own amount is not published.
- Single-user readings: New tiers have only single-user forum readings, such as 14 to 15 M tokens per 1% of the Super pool. Legacy SuperGrok measured USD 124 a week (one account).
- Weak for the money: Grok 4.7 scores 37.6% on Terminal-Bench 4.0 and costs USD 5,949 per run on xAI's API, the highest per-run cost in the benchmark table.
- Automation depends on product: Cloud agents, automations and headless Grok Build are included, but Cursor's acceptable use policy bans bot or script access. Check which product your automation runs through.
- Long context costs double: Premium and above reach 500K context on Grok 4.7 at 2x rates; Plus stops at 256K, just above the 250k floor.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| SuperGrok (legacy) | Price not stated; continues for exis… | One shared weekly pool across Grok products, shown as percentage | week (not published) |
| SuperGrok Heavy (legacy) | Price not stated; a yearly subscript… | not published | not stated (not published) |
| The X Subscription Plus | 8 | Base weekly pool shared across Grok and Cursor; amount not published | week (not published) |
| The X Subscription Premium | 30 | 4x Plus | week |
| The X Subscription Super | 100 | 15x Plus | week |
| The X Subscription Ultra | 200 | 50x Plus | week |
- Models: SuperGrok (legacy): not stated (Grok Build draws from the pool); The X Subscription Plus: Grok 4.7; Grok 4.6; Grok 4.5; Composer 2.5 (fixed settings: Fast off, medium effort); The X Subscription Premium, The X Subscription Super, The X Subscription Ultra: Grok 4.7; Grok 4.6; Grok 4.5; Composer 2.5; Grok Build; third-party models (Claude, GPT, Gemini) from prepaid credit; priority model access at peak times
- Context: The X Subscription Plus: Grok 4.7 256K; The X Subscription Premium, The X Subscription Super, The X Subscription Ultra: Grok 4.7 long context up to 500K at 2x rates
- Third-party tools: The X Subscription Plus: Grok API listed but billed separately; no own API keys in Cursor; The X Subscription Premium: not stated (BYOK inbound: own-key requests do not count toward usage)
- Automation: Cloud agents and automations included; Grok Build runs headless; Cursor AUP bans bot/script access (conflict); suited to several agents or Automations
- At the limit: SuperGrok (legacy): Paid features pause until reset; Extra Usage Credits (from USD 5, expire after 1 year), upgrade, or Auto Top Up; The X Subscription Plus, The X Subscription Premium, The X Subscription Super, The X Subscription Ultra: Prepaid credit, weekly reset, or upgrade; requests never downgraded
Measured and stated limits (17 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| The X Subscription Premium | 1 prompts | week | user | forum.cursor.com |
| The X Subscription Premium | – hours to exhaust weekly pool | week | user | forum.cursor.com |
| The X Subscription Super | 2.1 B tokens | – | user | forum.cursor.com |
| The X Subscription Super (Teams seat) | (14 M–15 M) tokens | week | user | forum.cursor.com |
| The X Subscription Ultra | 1 prompts | week | user | forum.cursor.com |
| The X Subscription Ultra | – hours to exhaust weekly pool | week | user | forum.cursor.com |
| SuperGrok (legacy, no X account linked) | 124 USD | week | tracker | github.com |
| SuperGrok (legacy, X Premium+ linked) | (11–15) USD | week | tracker | github.com |
| SuperGrok (legacy) | 112 M tokens | week | tracker | modeldial.com |
| SuperGrok (legacy) | 126 M tokens | week | user | v2ex.com |
| SuperGrok (legacy) | 240 M tokens | week | user | v2ex.com |
| SuperGrok (legacy) | 247 M tokens | week | user | linkedin.com |
| SuperGrok (legacy) | 10.9 M tokens input+output | week | user | bshp.io |
| SuperGrok Heavy (legacy) | 400.5 USD | week | tracker | remakebench.com |
| SuperGrok Heavy (legacy) | 917 M tokens | week | tracker | modeldial.com |
| SuperGrok Heavy (legacy) | 143 USD for 17 points of weekl… | week | user | unrollnow.com |
| SuperGrok Heavy (legacy) | 110 M tokens for >20% of weekly… | week | user | github.com |
- No measurement found: The X Subscription Plus, The X Subscription Plus/Premium/Super/Ultra.
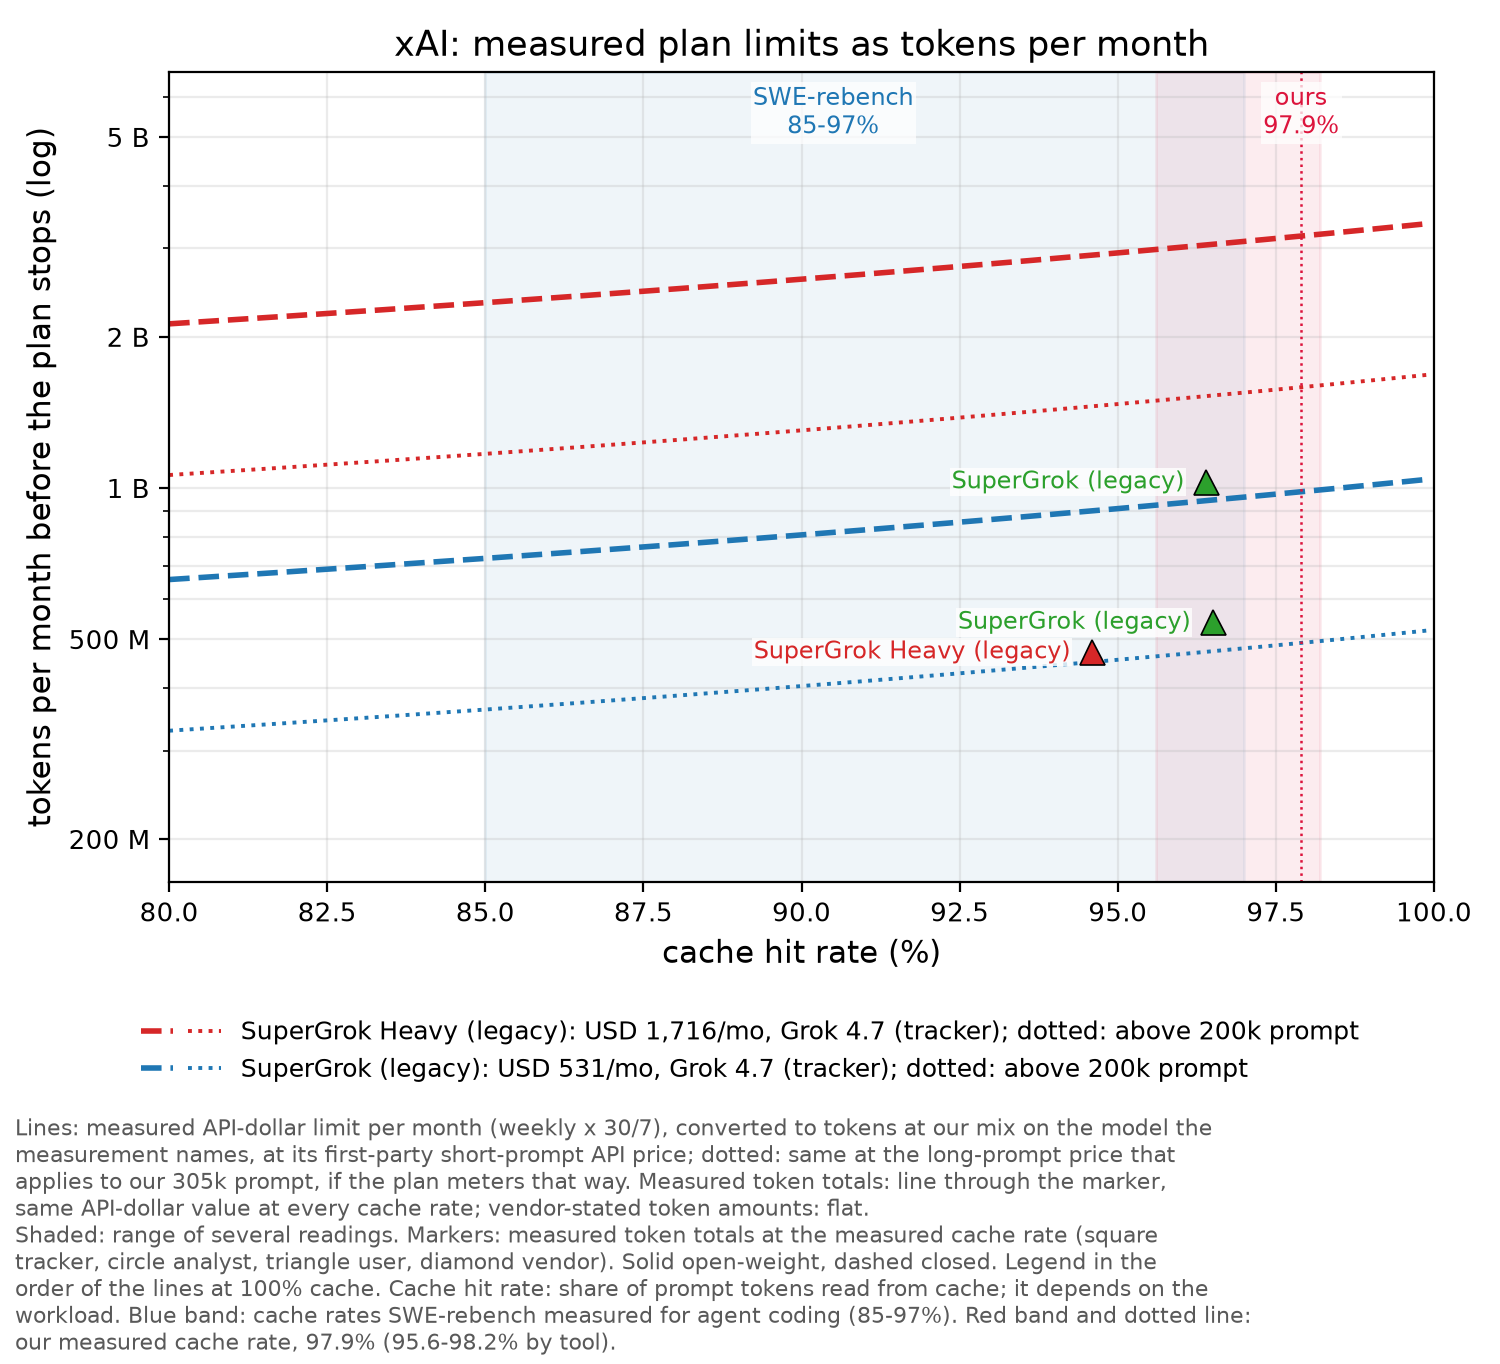
The measured SuperGrok (legacy) limit buys 0.18 full Terminal-Bench 4.0 runs of Grok 4.7 a month at our mix (1 tracker reading). The measured SuperGrok Heavy (legacy) limit buys 0.58 full Terminal-Bench 4.0 runs of Grok 4.7 a month at our mix (1 tracker reading).
Synthetic
Synthetic (synthetic.new) is run by Synthetic Lab, Co., which gives a mailing address in San Francisco. It hosts open-weight models without storing prompts and serves them through an OpenAI-compatible application programming interface (API). In August 2025 it began selling flat monthly subscriptions for coding agents, with $20 and $60 tiers at launch.
What to know:
- Price missing: Standard and Big prices are not in sources, so tokens per dollar cannot be placed. The vendor states up to USD 300 a month of API value on Standard.
- Vendor token figures: Standard covers 248 M GLM-5.3 or 2.7 B DeepSeek V4.1 Flash tokens a month; Big 744 M or 8.11 B. No independent measurement.
- Background agents on Big: Infinite mode runs DeepSeek V4.1 Flash for background agents without counting against the limit.
- No training: No training, fine-tuning or benchmarking on prompts or completions, with 512k context on the Always-On models.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Standard | price not stated | weekly credit limit, up to $300/mo vs API list prices; 2% regenerates every 202 min | week |
| Big | price not stated | credits | week (not published) |
- Models: Always-On: DeepSeek-V4.1-Flash;GLM-4.7-Flash;Kimi-K3
- Context: 512k (Always-On table)
- Third-party tools: Yes; OpenAI/Anthropic API; guides: Claude Code, Crush, Opencode, GitHub Copilot, OpenClaw, Xcode
- Automation: Standard: API is the product; ToS bans programmatic extraction of data/output; Infinite mode Big only; Big: Infinite mode (DeepSeek V4.1 Flash) built for background agents, needs streaming, never counts against limit
- Training on your data: No training, fine-tuning or benchmarking on prompts or completions
- At the limit: Buy tokens at usage rates or upgrade; credits regenerate continuously
Measured and stated limits (8 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Standard | 300 USD | month | vendor | synthetic.new |
| Standard | 248 M tokens | month | vendor | synthetic.new |
| Standard | 71.9 M tokens | month | vendor | synthetic.new |
| Standard | 2.7 B tokens | month | vendor | synthetic.new |
| Standard (pack) | 24 USD API credit | week | analyst | standardcompute.com |
| Big | 744 M tokens | month | vendor | synthetic.new |
| Big | 216 M tokens | month | vendor | synthetic.new |
| Big | 8.11 B tokens | month | vendor | synthetic.new |
Alibaba Cloud: Coding Plan
Alibaba Cloud Model Studio is the model platform of Alibaba Cloud, the cloud unit of China's Alibaba Group. It serves Alibaba's Qwen models, several of which the Qwen team also publishes as open weights, and sells a $50-a-month Coding Plan that runs Qwen, GLM, Kimi and MiniMax models inside third-party coding tools. Alibaba's cloud revenue rose 45% year on year to 48.4 billion yuan in the June 2026 quarter.
What to know:
- Older models only: The USD 50 plan runs qwen3.7-plus, kimi-k2.5, glm-5 and MiniMax-M2.5, none of them among the Terminal-Bench 4.0 models priced in this report.
- Two below the floor: Qwen3.x Plus has 1M context and kimi-k2.5 262k, but glm-5 (202,752) and MiniMax-M2.5 (196,608) fall below 250k.
- Requests, not tokens: The limit is 6,000 model calls per 5 hours, 45,000 a week and 90,000 a month. No measurement converts calls to tokens.
- Hard stop, no scripts: Calls fail until reset with no pay-as-you-go fallback; scripts, app backends and batch calls risk suspension. Model Studio states data is never used for training.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Coding Plan Pro | 50 | 5h: 6,000; week: 45,000; month: 90,000 | mixed |
| Coding Plan Lite (discontinued) | price not stated; no new subscriptio… | requests | mixed (not published) |
- Models: qwen3.7-plus; qwen3.6-plus; qwen3.5-plus; kimi-k2.5; glm-5; MiniMax-M2.5
- Context: per model: qwen3.x-plus 1,000,000; kimi-k2.5 262,144; glm-5 202,752; MiniMax-M2.5 196,608
- Third-party tools: yes: Claude Code, OpenCode, Cursor, Codex, Qwen Code, Cline, Kilo CLI, Qoder, Trae, OpenClaw and others; not curl/Postman/Dify/n8n
- Automation: interactive only; no scripts, app backends or batch calls; suspension or key revocation
- Training on your data: not stated for plan; Model Studio: never used for training
- At the limit: Coding Plan Pro: calls fail with error until 5h/week/month reset; no automatic pay-as-you-go; Coding Plan Lite (discontinued): wait for 5h/weekly reset or next cycle; no pay-as-you-go fallback
Measured and stated limits (5 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Bailian Token Plan ¥499 tier (comparison… | 115 M tokens | week | analyst | v2ex.com |
| Bailian Token Plan (flagship model, tier… | 101 CNY | month | analyst | 163.com |
| Model Studio Coding Plan Pro (intl $50) | 6,000 model calls | 5h | vendor | alibabacloud.com |
| Model Studio Coding Plan Pro (intl $50) | 45,000 model calls | week | vendor | alibabacloud.com |
| Model Studio Coding Plan Pro (intl $50) | 90,000 model calls | month | vendor | alibabacloud.com |
- No measurement found: Model Studio Coding Plan Lite (discontinued).
One analyst reading puts Bailian Token Plan ¥499 tier at 493 M tokens a month (Qwen3.8-Max, OpenCode, 90% cache).
The measured Bailian Token Plan ¥499 tier limit buys 0.24 full Terminal-Bench 4.0 runs of Qwen 3.8 Max a month at our mix (1 analyst reading).
Meta: Muse Code
Muse Code is Meta Platforms' first coding agent: a terminal agent that runs on Meta's own coding model, Muse Spark 1.2. It launched as a preview on 5 August 2026; the Muse Spark model costs $1.25 per million input tokens and $4.25 per million output tokens through the API, with a cheaper contributor tier that lets Meta train on prompts. It left the preview on 31 August 2026, adding monthly subscription plans.
What to know:
- Closed harness: The subscription works only in the Muse Code CLI, and the key may not be used outside it, so it cannot power your own agent.
- Weak model: Muse Spark 1.3 scores 14.5% on Terminal-Bench 4.0.
- Trains by default: Contributor mode is on by default and trains Meta models on your content. Turn it off before real work.
- Small measured value: One tracker measured High Usage (USD 15) at about USD 140 a month of Spark API list price. Maximum Usage (USD 200) has no measurement and no higher plan.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Muse Code Everyday Usage | 5 | 10-50 prompts (more in Contributor mode) | 5h |
| Muse Code High Usage | 15 | 5x Everyday | 5h |
| Muse Code Power Usage | 50 | 20x Everyday | 5h |
| Muse Code Maximum Usage | 200 | 80x Everyday | 5h |
- Models: Muse Spark; Muse Wonder (conflict: product page says Power/Maximum only)
- Context: 1,048,576 (model spec, not per plan)
- Third-party tools: No; subscription works only in Muse Code CLI; key may not be used outside the harness
- Automation: Muse Code for terminal and CI; key may not be used to circumvent subscription limits
- Training on your data: Contributor mode on by default (content trains Meta models); can be turned off
- At the limit: Wait for refresh (no higher plan)
Measured and stated limits (15 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Muse Code Everyday Usage | 3 prompts = 52% of 5h window… | 5h | user | news.ycombinator.com |
| Muse Code High Usage | 2 prompts = 4% of weekly | week | user | news.ycombinator.com |
| Muse Code High Usage | 0.32 (0.31–0.33) USD | week | tracker | github.com |
| Muse Code High Usage | 10 USD | 5h | tracker | github.com |
| Muse Code High Usage (Contributor mode) | (3.51–4.35) USD | week | tracker | github.com |
| Muse Code High Usage | 1.33 hours of use = 96% of 5h w… | 5h | user | linkedin.com |
| Muse Code Power Usage | 1 accepted job | 5h | analyst | kingy.ai |
| Muse Code High Usage | (2–4) hours of coding before the… | 5h | user | shipwithmuse.live |
| Muse Code High Usage | 25 hours of coding | week | user | shipwithmuse.live |
| Muse Code High Usage | 140 USD of Spark API list price | month | tracker | o-mega.ai |
| Muse Code High Usage | 32 USD of Spark API list price | week | tracker | o-mega.ai |
| Muse Code High Usage (Contributor mode) | 87 USD of Contributor API lis… | month | tracker | o-mega.ai |
| Muse Code Everyday Usage | (10–50) prompts | 5h | vendor | toolcolumn.com |
| Muse Power (agent app, not Muse Code) | 500 M Muse tokens | week | vendor | toolcolumn.com |
| Muse Maximum (agent app, not Muse Code) | 3 B Muse tokens | week | vendor | toolcolumn.com |
- No measurement found: Muse Code Maximum Usage.
Mistral: Vibe and Le Chat Pro
Mistral AI is a Paris-based model developer founded in 2023. It publishes the Devstral 2 coding models with open weights (modified MIT and Apache 2.0 licences), sells them by the token through Mistral Studio, and includes its Mistral Vibe terminal coding agent in the Le Chat Pro and Team plans. On 8 September 2026 it raised €3 billion at a valuation of more than €21 billion (about $24 billion).
What to know:
- No token limit published: Pro (USD 14.99) publishes multiples of Free and an API credit of USD 25.5 or 15 a month, depending on the page. No measurement converts it.
- Mistral tools only: Vibe CLI, VS Code extension and web; use from other agents is not in sources. Training on your data is opt-out.
- Context just above floor: The plan states no context; the API lists 256k for Devstral 2 and Mistral Medium 3.5. Neither model has a Terminal-Bench 4.0 score here.
- EU option: The API runs in EU data centres, which matters if your data must stay in the EU.
| Tier | USD per month | Limit as published | Window |
|---|---|---|---|
| Pro | 14.99 | messages up to 6× Free; web search 5×; images 40×; API credits $25.5 or $15/mo (conflict) | month (not published) |
| Education | 5.99 | same structure as Pro; API credits $15 or $25.5/mo (assignment unclear) | month (not published) |
| Team | 24.99 | 'Even higher limits'; same multiples as Pro in table; Flash answers 200/day | month (not published) |
- Models: Mistral Medium;Devstral 2;flagship Mistral models
- Context: Not in sources for plan; API: Devstral 2 256k, Mistral Medium 3.5 256k
- Third-party tools: Mistral tools only (Vibe CLI, VS Code extension, web); BYOK; use from other agents not stated
- Automation: Vibe plan keys draw on plan budget; API automation should use a pay-as-you-go key; unlimited task scheduling
- Training on your data: Training opt-out (used unless opted out); feedback used; API in EU data centers
- At the limit: Stops until next period unless prepaid PAYG at API rates enabled; ToS says suspended (conflict); org/workspace spend limits also cap
Measured and stated limits (6 readings; conflicting readings kept side by side):
| Plan | Measured | Per | By | Source |
|---|---|---|---|---|
| Vibe Pro | 25.5 USD API credits | month | vendor | mistral.ai |
| Vibe Pro | 30 USD API credits | month | analyst | aifreeapi.com |
| Vibe Education | 15 USD API credits | month | vendor | mistral.ai |
| Vibe Pro | 74 M tokens = 58% of monthly Vi… | month | user | reddit.com |
| Vibe Pro | 38 M tokens = 2.51% of monthly… | month | user | reddit.com |
| Vibe Pro | – USD | month | user | reddit.com |
- No measurement found: Vibe Team.
Pay-per-use
Anthropic API
Anthropic, based in San Francisco, builds the Claude models and Claude Code, its coding agent. Claude Code passed USD 2.5 billion in annualised revenue in February 2026, and Menlo Ventures put Anthropic at 54% of enterprise spending on AI coding at the end of 2025.
What to know:
- Opus, own agent: At a 64 minimum score with your own agent, the finder picks Anthropic's API: USD 334 a month at 1 B tokens, 12,446 at our 37.23 B.
- Opus beats Sonnet: Sonnet 5.5 is half Opus's price per token (0.167 against 0.334) but costs USD 3,243 per run against 2,674, because it uses 19.4 B tokens.
- Keep the cache warm: The cache lives 5 minutes or 1 hour, and writes cost 1.25x input (2x for 1 hour). Pauses longer than that cost you the cached-input discount.
- Resellers charge list: Bedrock, Vertex, Azure and OpenCode Zen charge the same USD 0.334 per 1M for Opus 5.5. Choose by credits and contract, not price.
- Startup credit closed: Claude Startups' USD 1,000 cohort is full since 13 October; VC-claimed credits go up to USD 100,000. Batch is 50% off.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Claude Opus 5.5 · TB4 64.8% | 4 / 0.2 / 20 + write 5 | 1M | 0.334 | USD 2,674 |
| Claude Sonnet 5.5 · TB4 61.8% | 2 / 0.1 / 10 + write 2.5 | 1M | 0.167 | USD 3,243 |
| Claude Fable 5.1 · TB4 57.9% | 10 / 0.25 / 50 + write 12.5 | 1M | 0.591 | USD 1,597 |
| Claude Haiku 5.5 · TB4 39.2% (vendor) | 0.1 / 0.01 / 0.5 + write 0.12 | 1M | 0.066 | – |
- Other tiers, Claude Opus 5.5: Fast/priority: 2x.
- Other tiers, Claude Haiku 5.5: above 100k prompt: 0.5 / 0.05 / 2.5 + write 0.62.
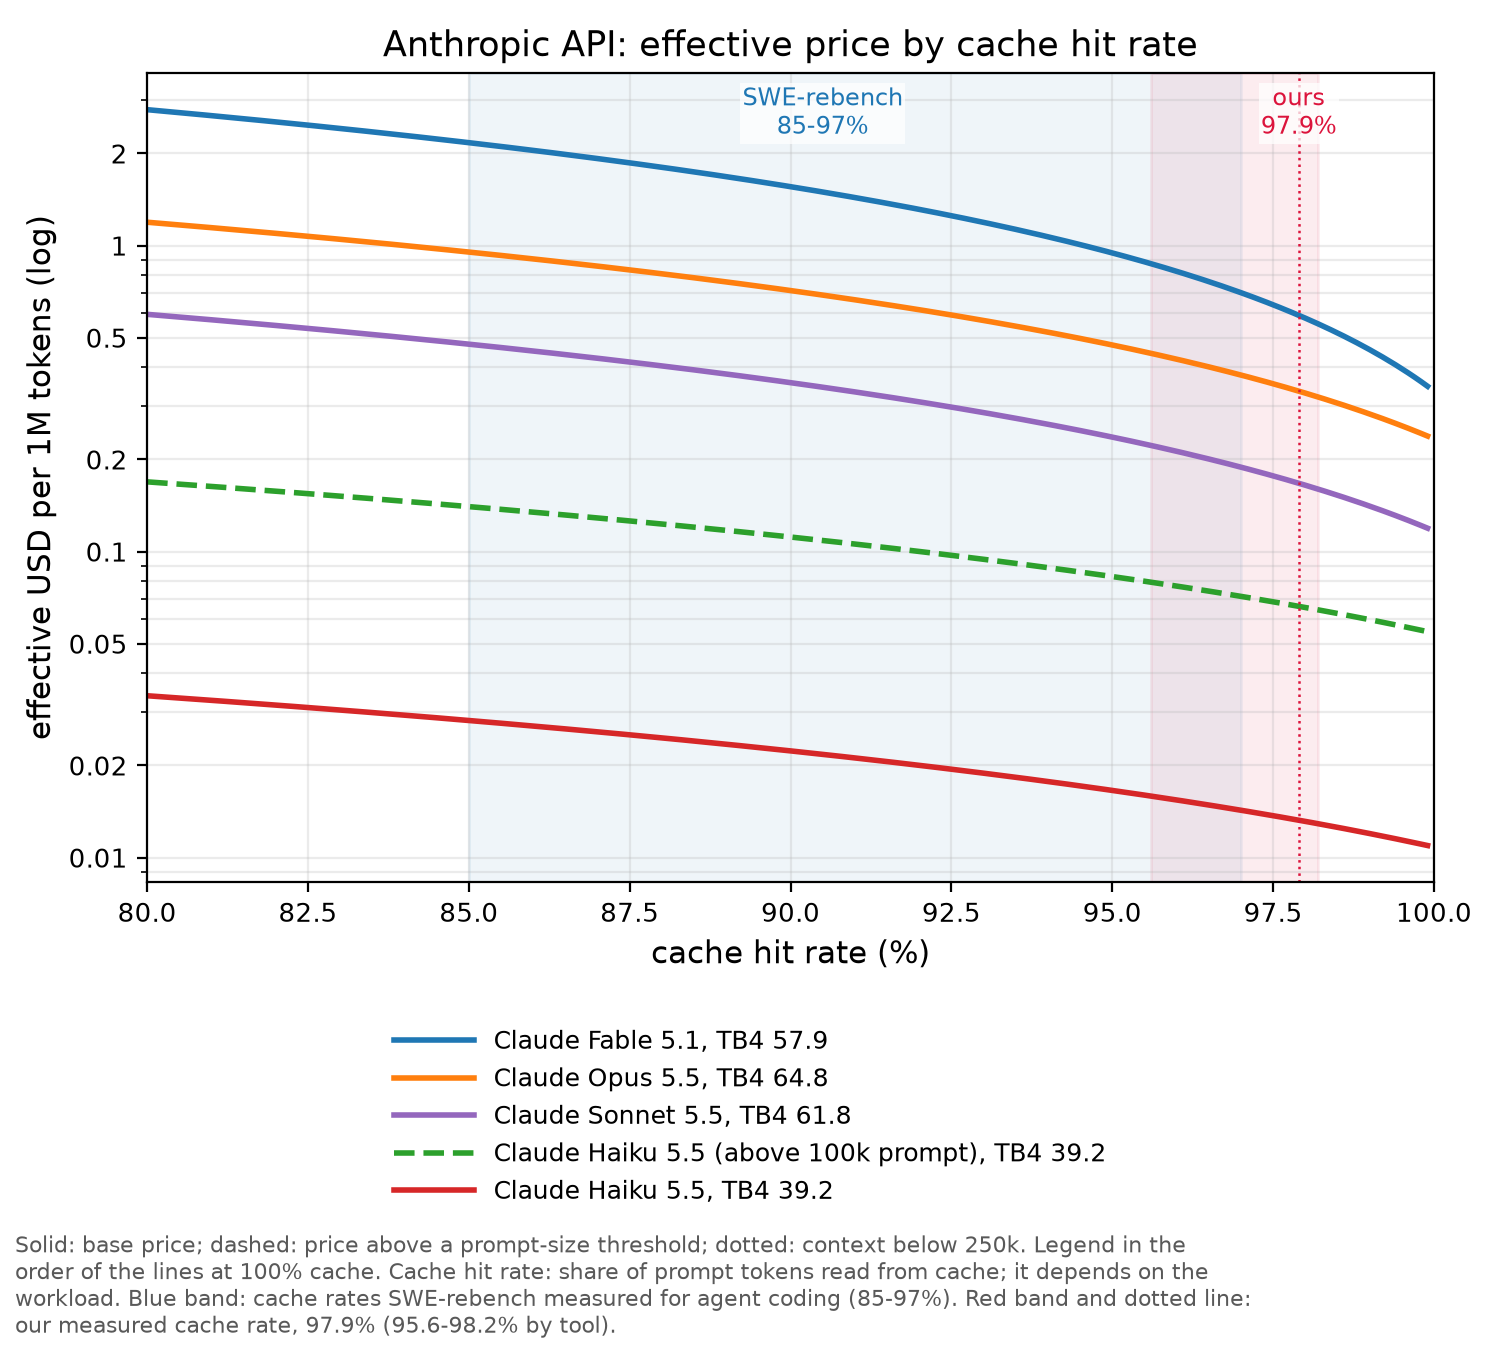
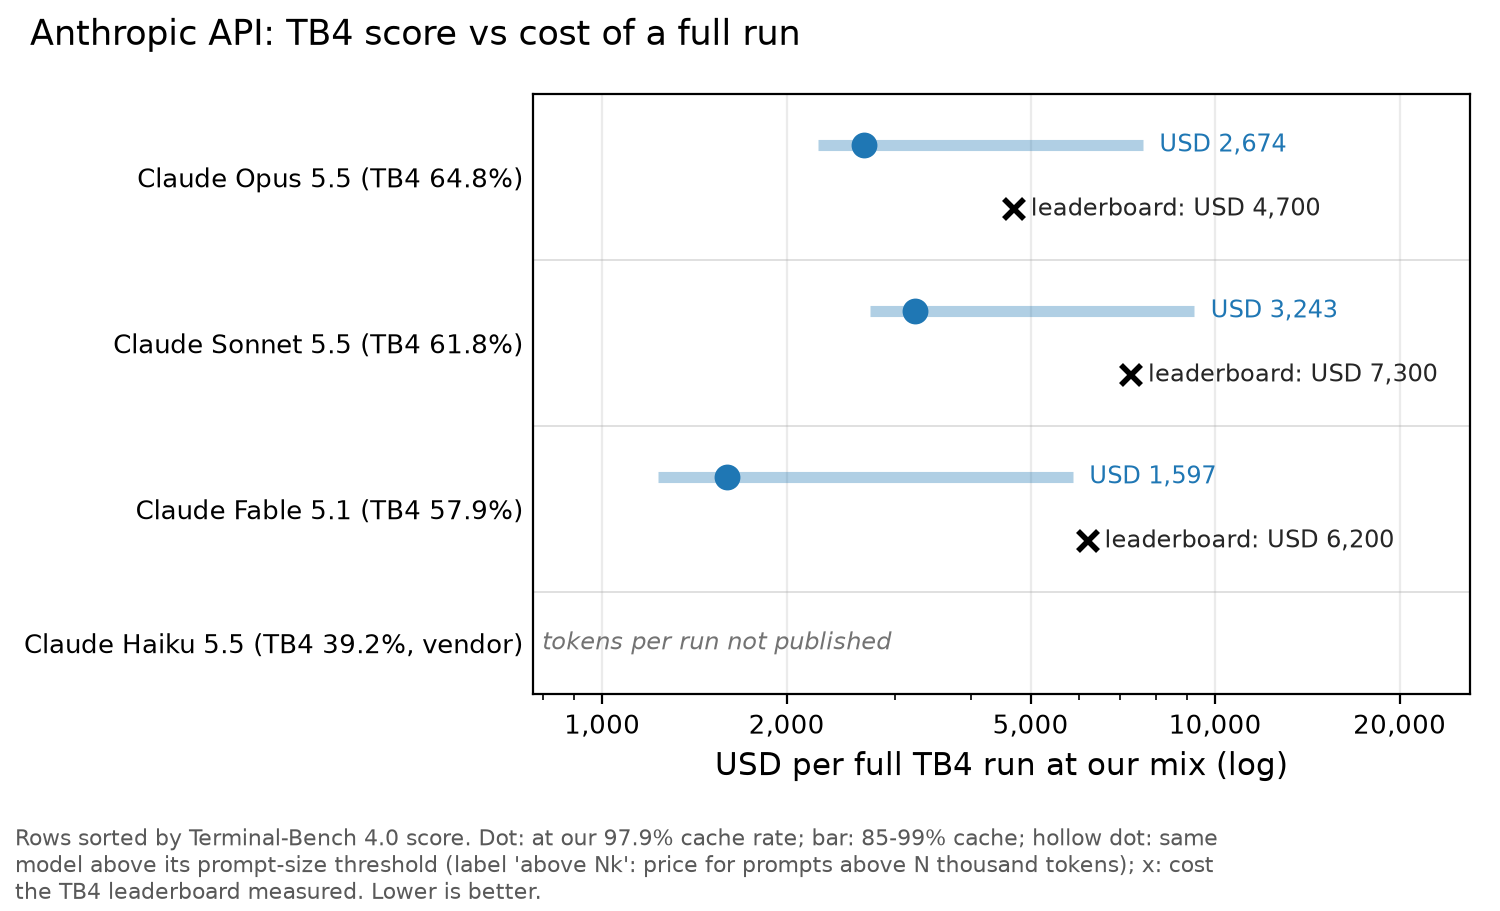
Google Vertex AI
Google, part of Alphabet, sells its Gemini models through the Gemini API with Google AI Studio and through Vertex AI on Google Cloud. Google AI Pro and Ultra subscriptions raise AI Studio quotas; consumer sign-in to Gemini CLI, including for those subscribers, ended on 18 June 2026 and moved to Google's Antigravity tools. In July 2026 Alphabet said its model APIs processed about 22 billion tokens per minute.
What to know:
- Price doubles in December: Gemini 4 Argon's global price is a promotion through 30 November 2026 and doubles from 1 December. Budget for 2x.
- Same as AI Studio: Gemini 4 Argon costs USD 0.157 per 1M at our mix on Vertex's global endpoint, as on AI Studio; non-global endpoints charge 1.1x.
- Claude at list price: Opus 5.5 and Sonnet 5.5 match Anthropic's own prices; regional batch cuts Opus to 0.62x. Useful if your credits are on Google Cloud.
- Long implicit cache: The implicit Gemini cache lives up to 24 hours, though most entries are evicted earlier. Cache writes bill at the normal input price, with no write fee.
- Startup credits exclude Claude: Google for Startups gives up to USD 350,000 over two years, for Google's own models only.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Claude Opus 5.5 · TB4 64.8% | 4 / 0.2 / 20 + write 5 | 1M | 0.334 | USD 2,674 |
| Claude Sonnet 5.5 · TB4 61.8% | 2 / 0.1 / 10 + write 2.5 | 1M | 0.167 | USD 3,243 |
| Claude Fable 5.1 · TB4 57.9% | 10 / 0.25 / 50 + write 12.5 | 1M | 0.591 | USD 1,597 |
| Gemini 4 Argon · TB4 57.1% | 2 / 0.1 / 10 | 1M | 0.157 | – |
| Claude Haiku 5.5 · TB4 39.2% (vendor) | 0.1 / 0.01 / 0.5 + write 0.12 | 1M | 0.066 | – |
| Grok 4.7 · TB4 37.6% | 2 / 0.5 / 6 | 524k | 1.082 | USD 5,949 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.03 / 1.2 | – | 0.038 | – |
| Gemini 3.8 Flash · TB4 19.1% | 0.75 / 0.075 / 3.75 | 1M | 0.095 | USD 1,641 |
| GLM 5.2 · open | 1.4 / 0.14 / 4.4 | 1M | 0.174 | – |
| gpt-oss-120b · open | 0.09 / – / 0.36 | 131k (below 250k) | 0.090 | – |
-
Other tiers, Claude Opus 5.5: regional: 1x; regional, batch: 0.62x.
-
Other tiers, Claude Sonnet 5.5: regional: 1x; regional, batch: 0.5x.
-
Other tiers, Claude Fable 5.1: regional: 1x; regional, batch: 0.5x.
-
Other tiers, Gemini 4 Argon: global; promo price through 2026-11-30: 1x; non-global; promo price through 2026-11-30: 1.1x; global; from 2026-12-01: 2x; non-global; from 2026-12-01: 2.2x.
-
Other tiers, Claude Haiku 5.5: above 100k prompt: 0.5 / 0.05 / 2.5 + write 0.62; regional: 1x; regional, batch: 0.5x; regional above 100k: 5x.
-
Other tiers, Grok 4.7: above 200k prompt: 4 / 1 / 12.
-
Other tiers, Gemini 3.8 Flash: global; intro price through 2026-12-31: 1x; non-global; intro price through 2026-12-31: 1.1x; global; from 2027-01-01: 2x; non-global; from 2027-01-01: 2.2x.
-
Caching (Gemini models): both; TTL implicit max 24 h, most evicted earlier; explicit default 60 min, min 1 min, no max; cached discount 90% on Gemini 2.5+, 75% on 2.0 | sources differ: older roundup: 75% (Gemini 1.5); write fee none (writes at standard input); explicit storage fee per token-hour ($0.0000045 Gemini 3.1 Pro); peak pricing: not stated (dated promotions only)
-
Caching (Claude (Opus 5.5, Sonnet 5.5)): not stated ("prompt caching", TTL up to 1 h); TTL 5 min or 1 h; cached discount 95% derived (Opus 5.5 $0.20 vs $4.00; Sonnet 5.5 $0.10 vs $2.00); write fee 1.25x input (5 min); 2x input (1 h) (Opus 5.5 $5.00 / $8.00)
-
Caching (open MaaS models (Kimi, DeepSeek, MiniMax, Qwen3-Coder, GLM)): automatic; TTL not stated; cached discount 90% (e.g. Qwen3-Coder-480B $0.022 vs $0.22); write fee not stated
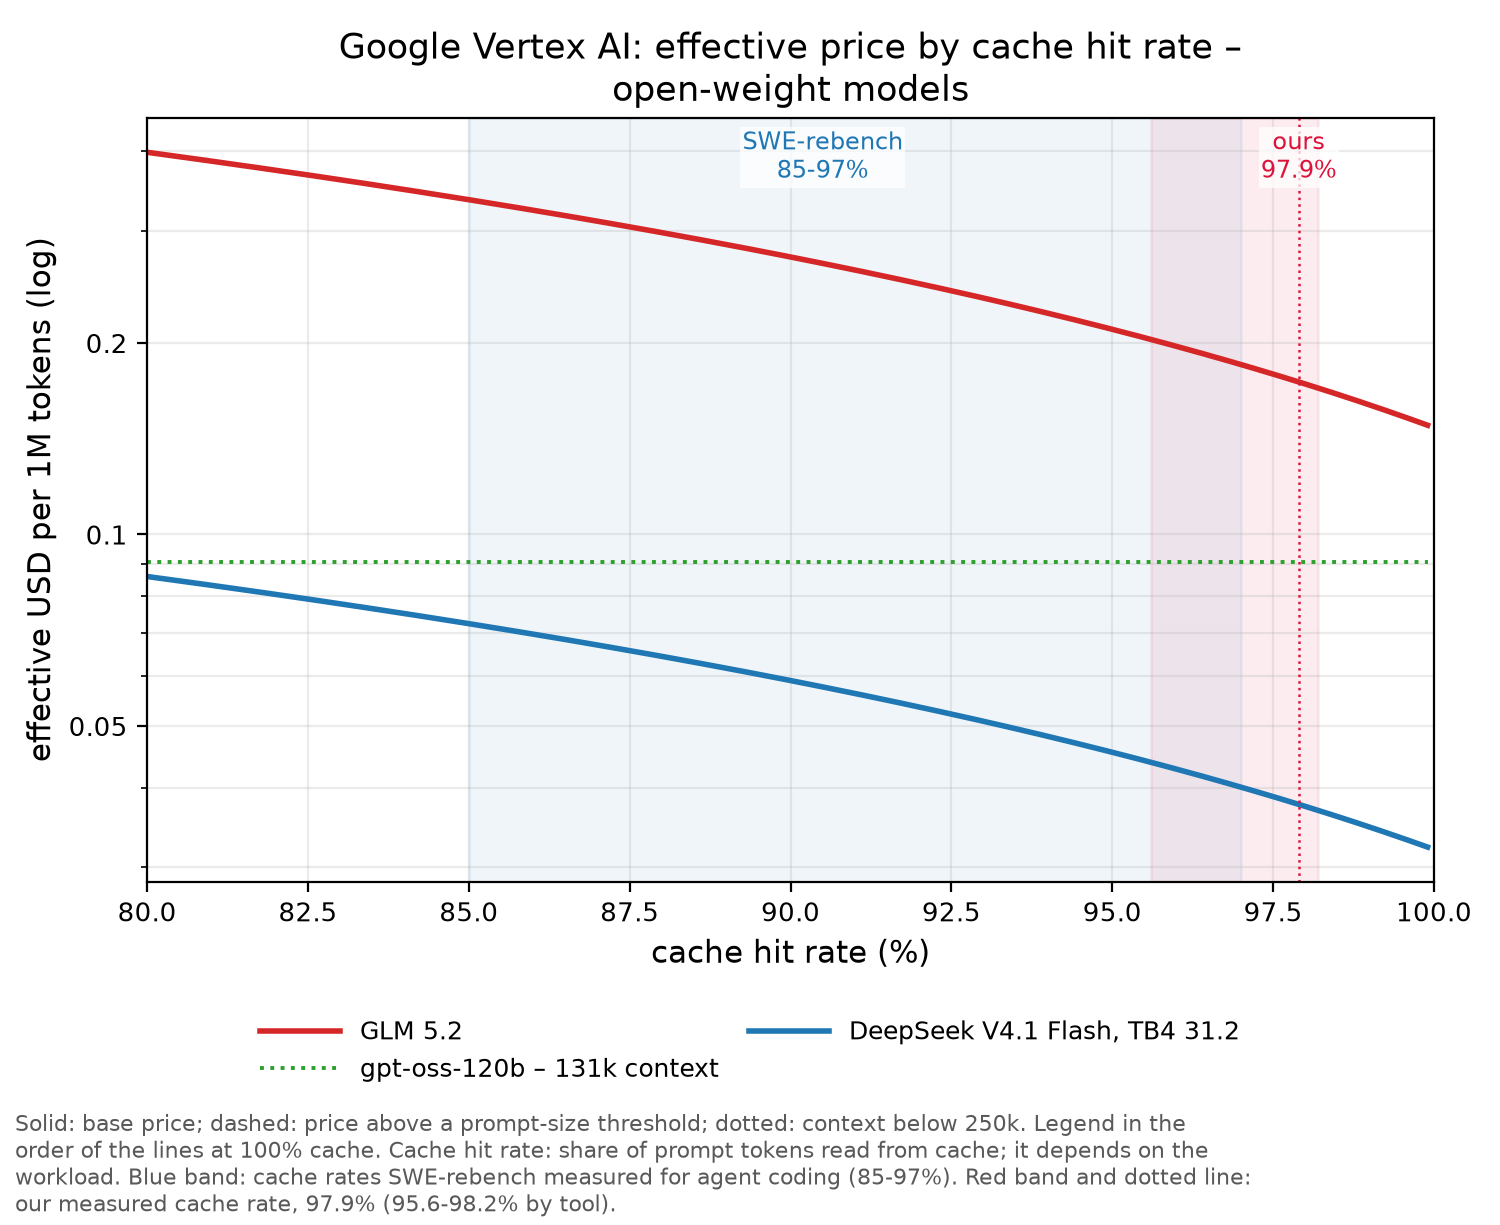
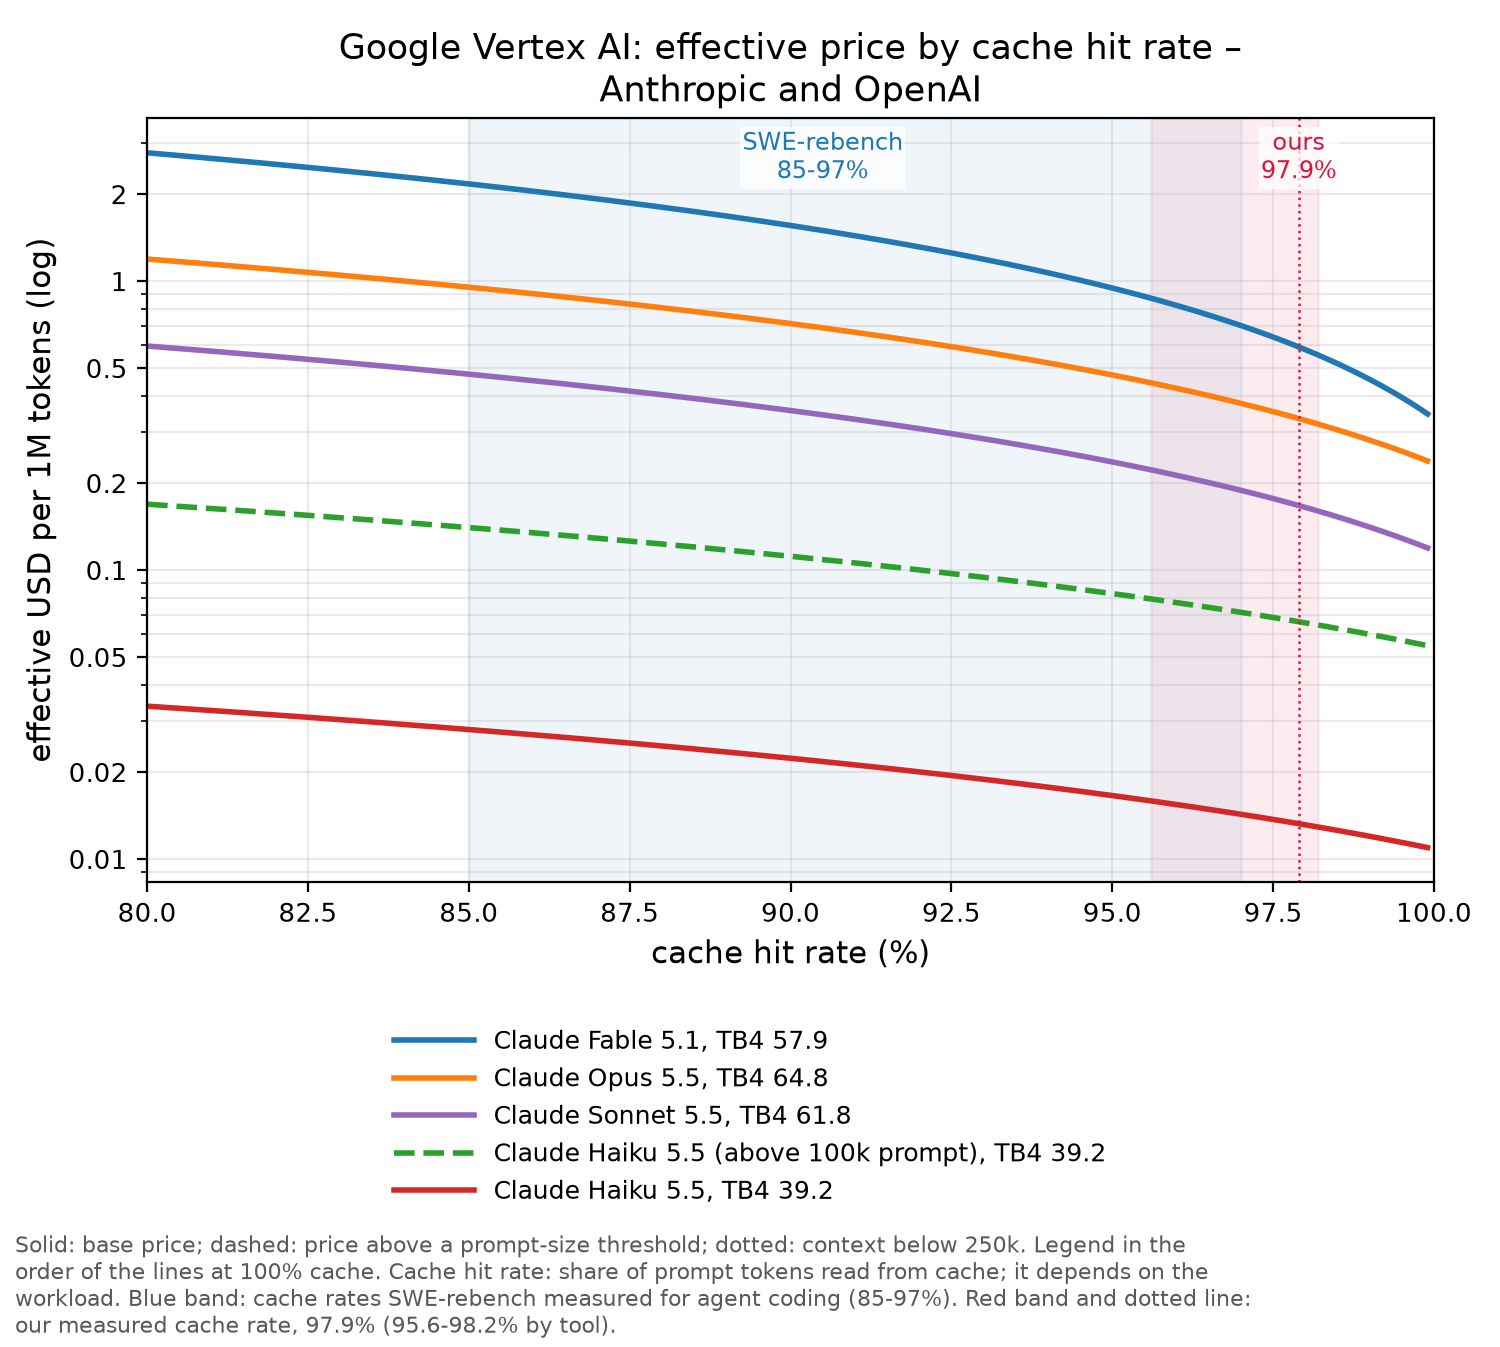
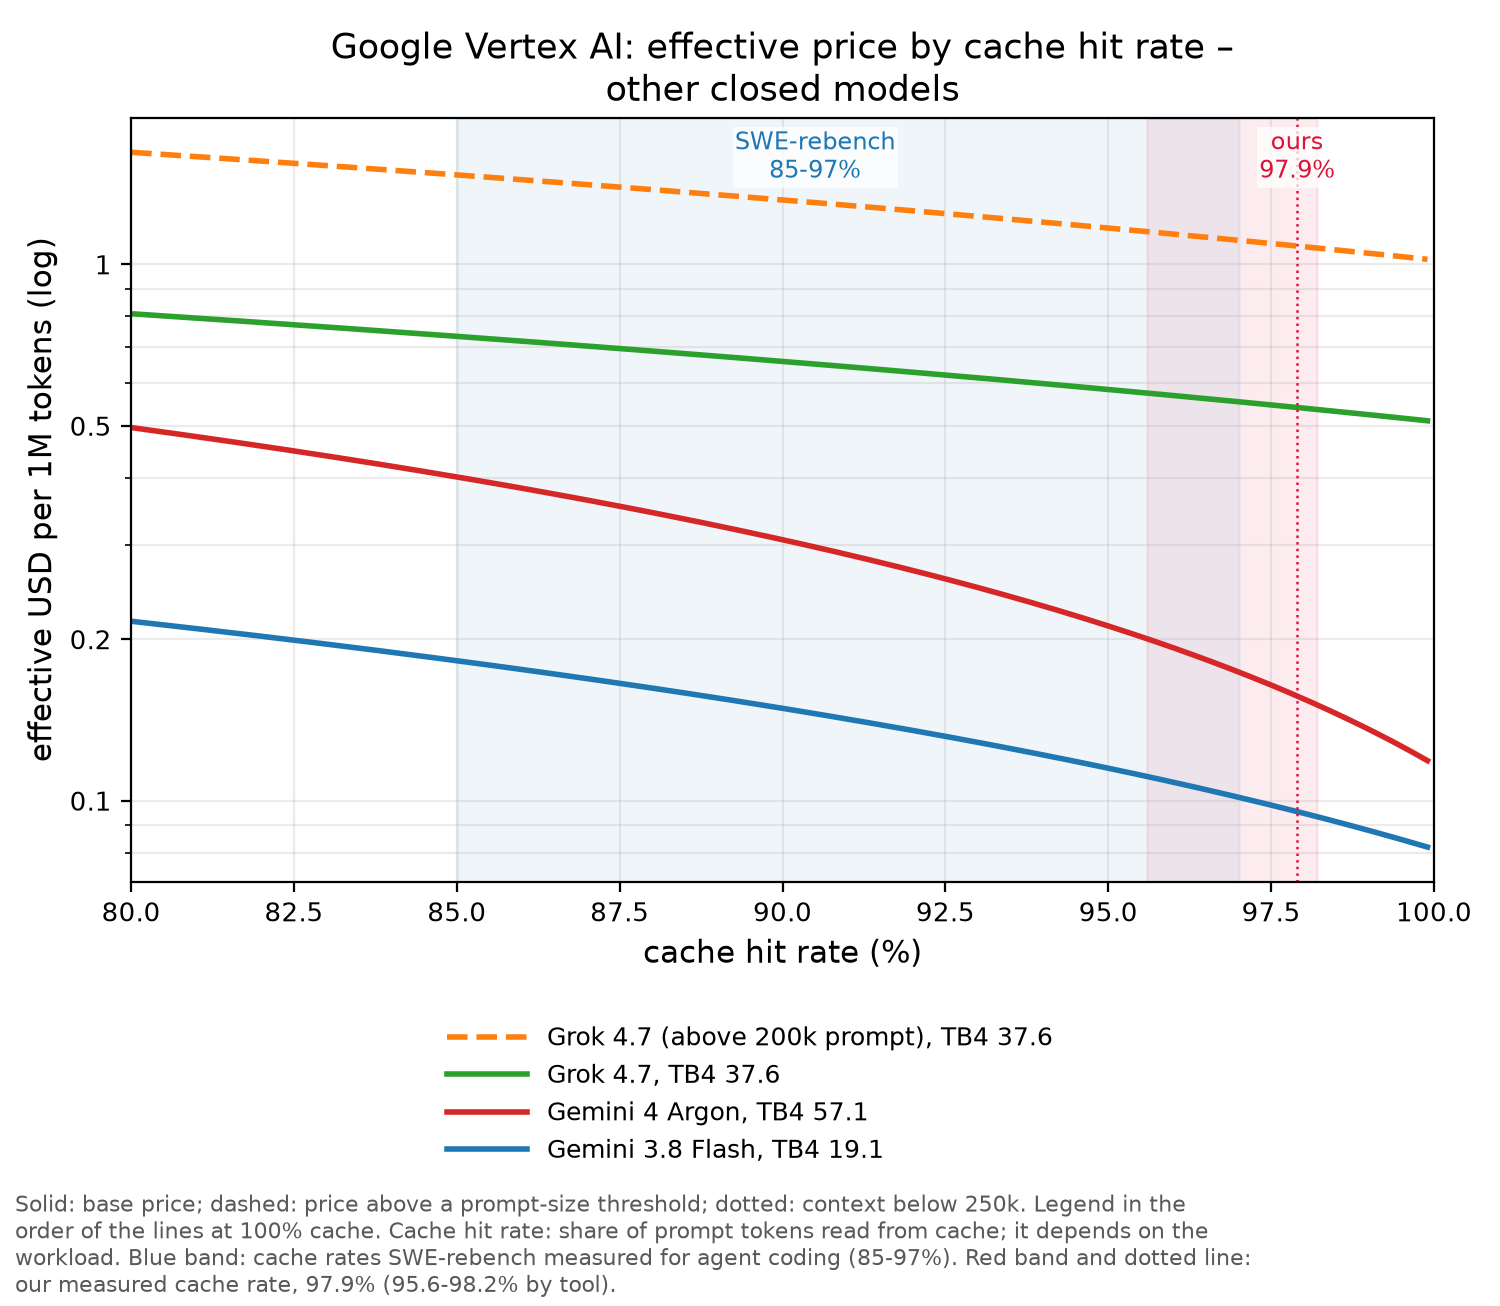
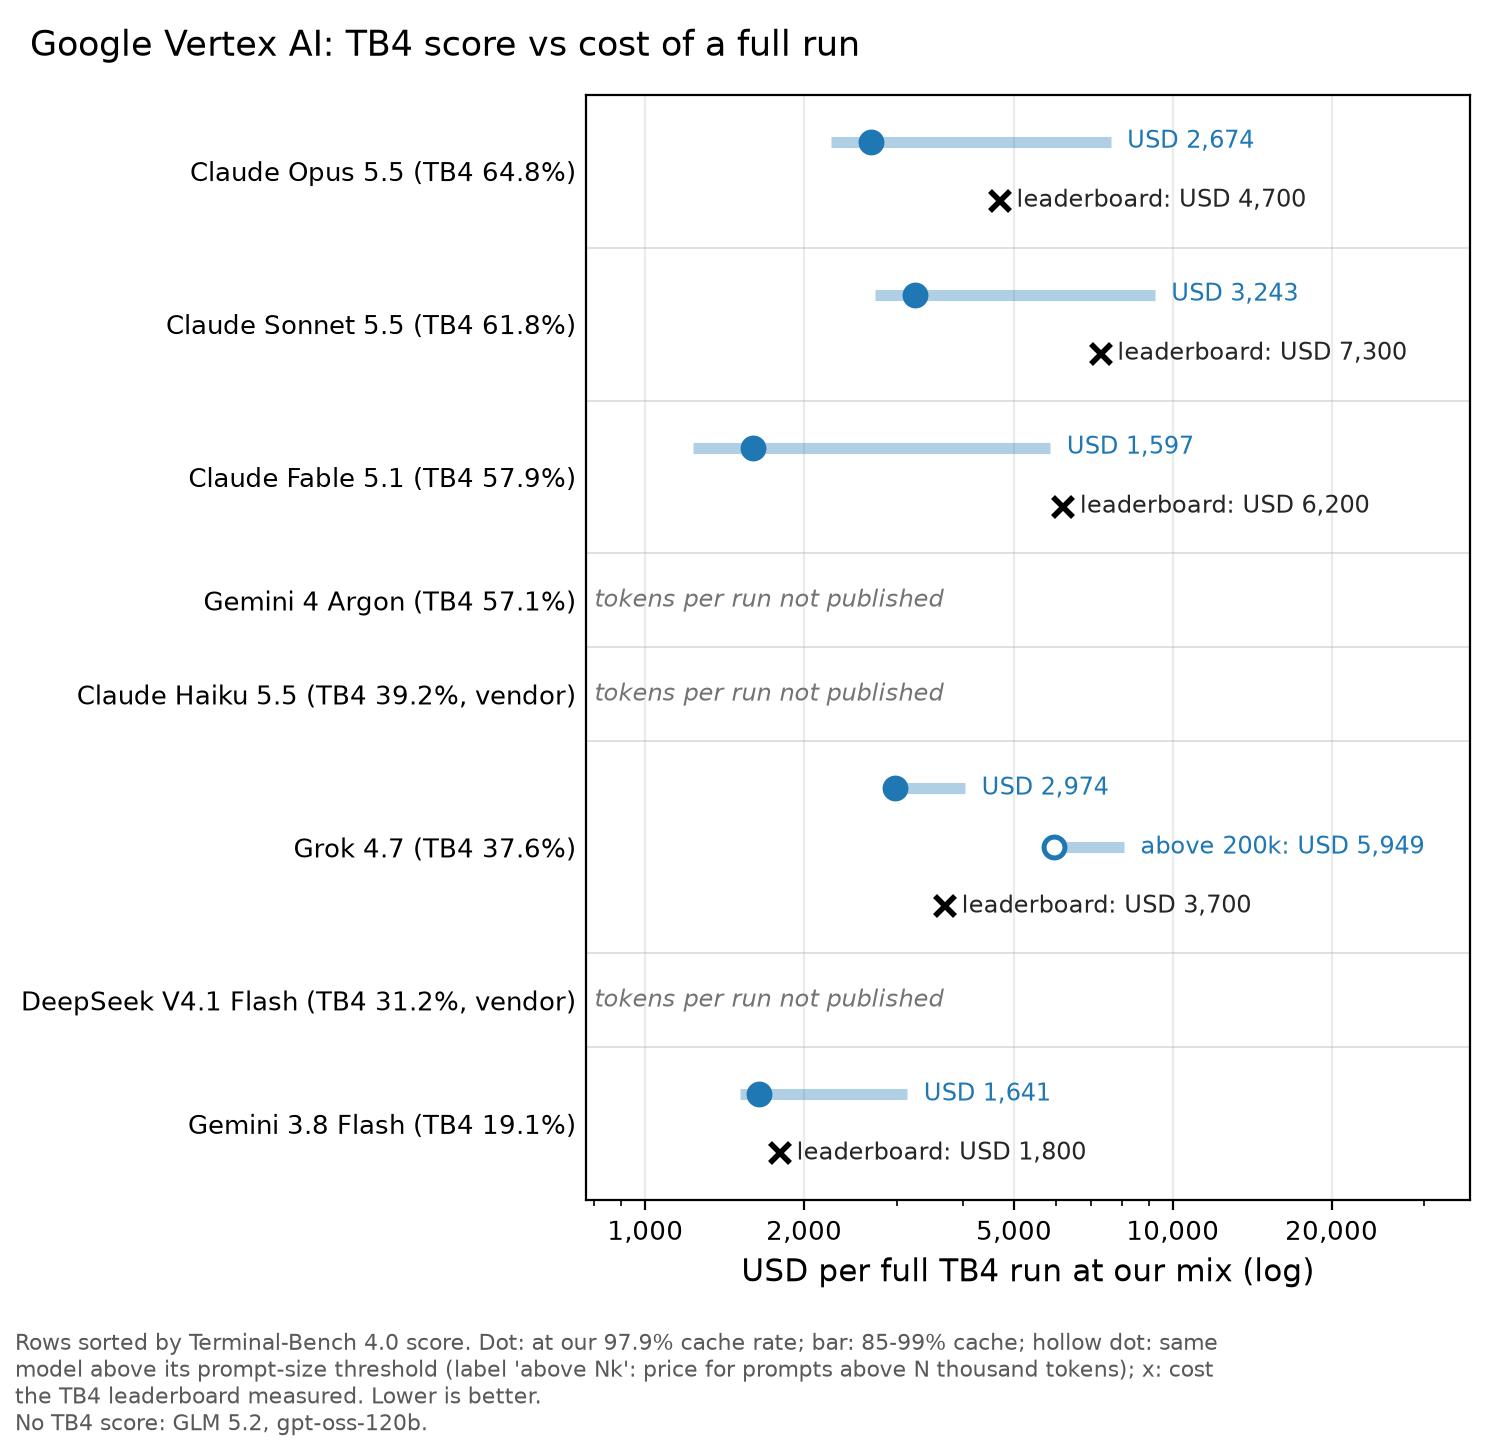
OpenAI API
OpenAI, based in San Francisco, builds the GPT models and Codex, its coding agent. In June 2026 OpenAI reported more than 5 million weekly active Codex users. GPT-6 Astra and GPT-6.1 Sol need 1.5 B tokens per Terminal-Bench run, the fewest of any leading model.
What to know:
- Cheapest top run: GPT-6.1 Sol (58.2%) costs USD 489 per Terminal-Bench run at our mix, against USD 2,674 for Opus 5.5.
- Long-prompt tier applies: Above 272k prompt tokens input doubles to USD 4 and output rises to 15. Our 305k average prompt pays that rate; below 272k Sol costs what Sonnet 5.5 costs.
- Avoid Astra: GPT-6 Astra scores the same 58.2% but costs USD 2.606 per 1M at our mix against 0.326 for Sol.
- Discount tiers: Flex runs at 0.5x for work that can wait; priority costs 2x. Zero data retention is available on request.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GPT-6.1 Sol · TB4 58.2% | 2 / 0.1 / 10 + write 2.5 | 1.1M | 0.326 | USD 489 |
| GPT-6 Astra · TB4 58.2% | 10 / 1 / 50 + write 12.5 | 1.1M | 2.606 | USD 3,909 |
| GPT-6 Sol · TB4 49.4% | 2 / 0.2 / 10 + write 2.5 | 1.1M | 0.521 | USD 2,606 |
| GPT-6 Luna · TB4 16.4% | 0.1 / 0.01 / 0.5 + write 0.12 | 1.1M | 0.026 | USD 102 |
- Other tiers, GPT-6.1 Sol: above 272k prompt: 4 / 0.2 / 15 + write 5; Flex: 0.5x; Fast/priority: 2x; Ultrafast: 6x; Flex above 272k: 1x; Fast/priority above 272k: 4x; Ultrafast above 272k: 12x.
- Other tiers, GPT-6 Astra: above 272k prompt: 20 / 2 / 75 + write 25; Flex: 0.5x; Fast/priority: 2x; Ultrafast: 6x; Flex above 272k: 1x; Fast/priority above 272k: 4x; Ultrafast above 272k: 12x.
- Other tiers, GPT-6 Sol: above 272k prompt: 4 / 0.4 / 15 + write 5; Flex: 0.5x; Fast/priority: 2x; Flex above 272k: 1x; Fast/priority above 272k: 4x.
- Other tiers, GPT-6 Luna: above 272k prompt: 0.2 / 0.02 / 0.75 + write 0.25; Flex: 0.5x; Fast/priority: 2x; Flex above 272k: 1x; Fast/priority above 272k: 4x.
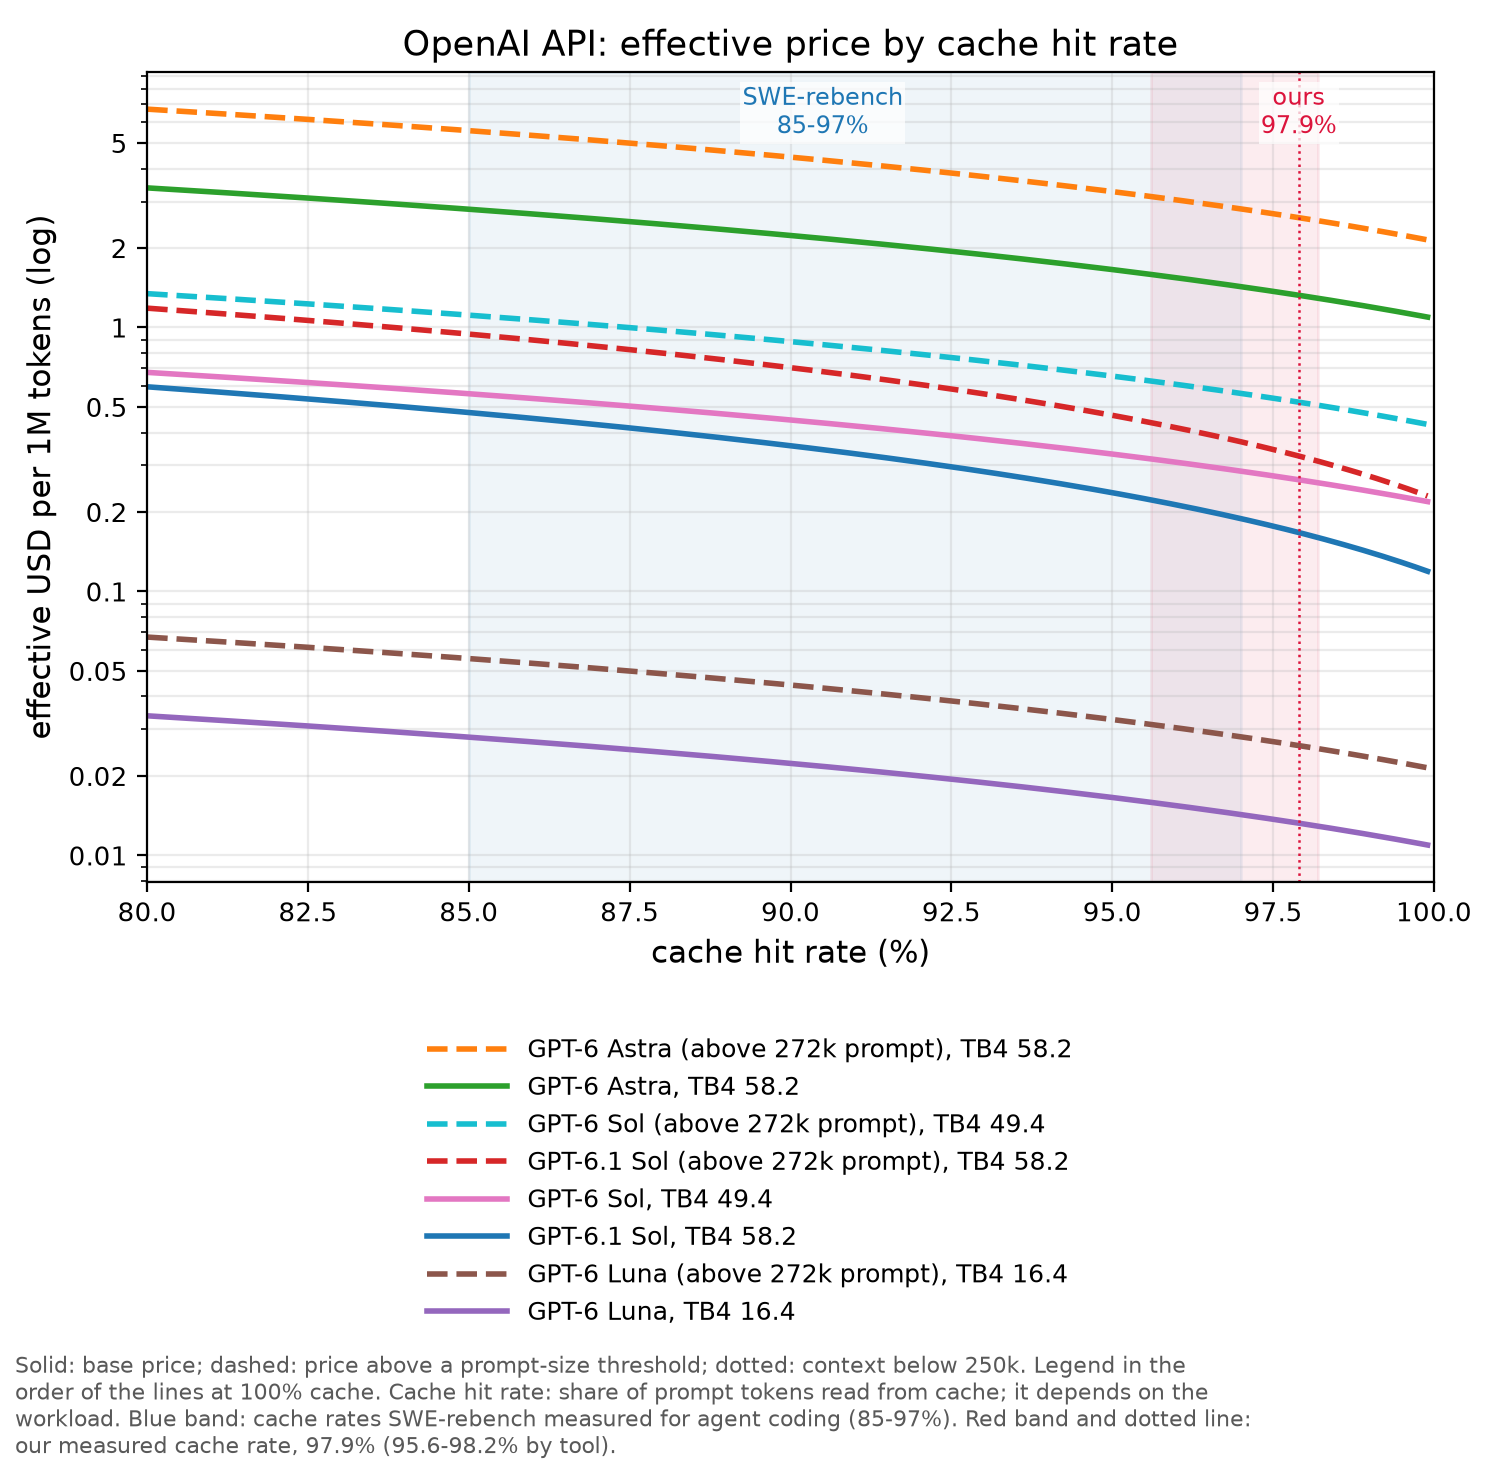
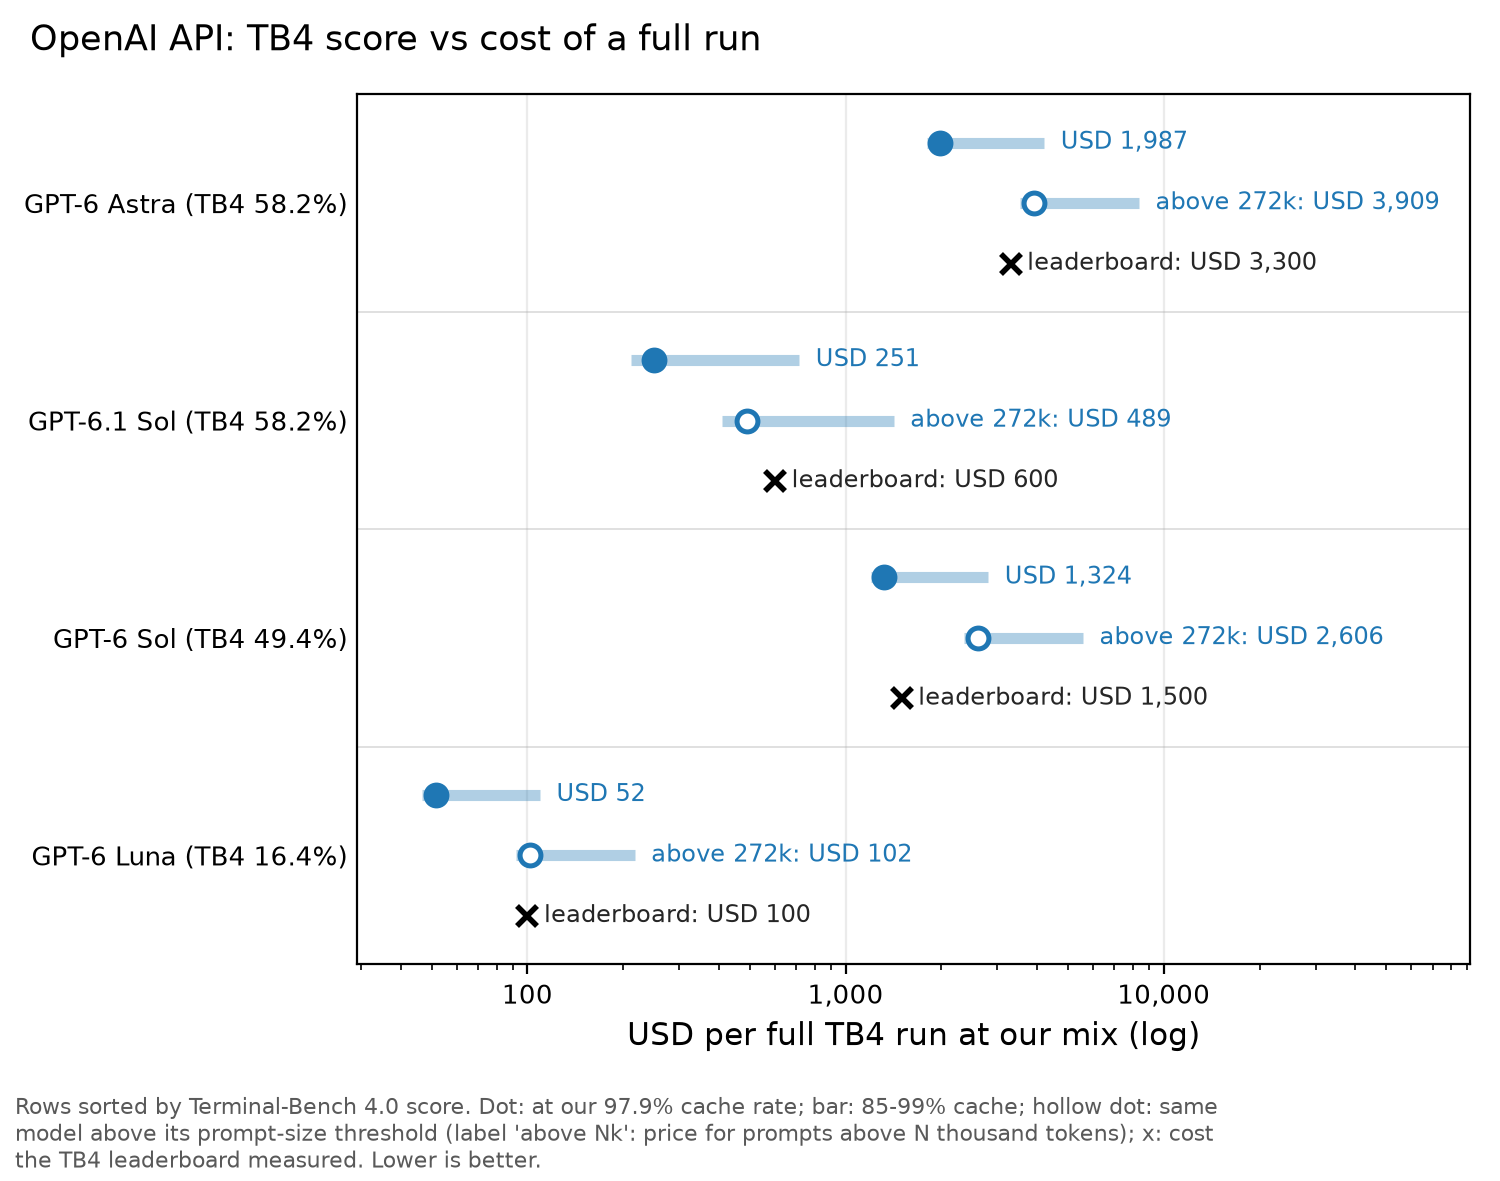
Google AI Studio (Gemini API)
Google, part of Alphabet, sells its Gemini models through the Gemini API with Google AI Studio and through Vertex AI on Google Cloud. Google AI Pro and Ultra subscriptions raise AI Studio quotas; consumer sign-in to Gemini CLI, including for those subscribers, ended on 18 June 2026 and moved to Google's Antigravity tools. In July 2026 Alphabet said its model APIs processed about 22 billion tokens per minute.
What to know:
- Cheapest strong closed: Gemini 4 Argon (57.1%) at USD 0.157 per 1M is the own-agent finder's pick at a 50 to 55 minimum score: USD 157 a month at 1 B tokens.
- Promotion ends 30 November: From 1 December the list price is 4 / 0.20 / 20, USD 0.313 per 1M at our mix, above Sonnet 5.5's 0.167 on Anthropic's API.
- Run cost unknown: Argon's tokens per Terminal-Bench run are not published, so per-task cost cannot be compared with GPT-6.1 Sol's USD 489.
- Skip Gemini 3.8 Flash: It scores 19.1% and costs USD 1,641 per run because a run takes 17.2 B tokens.
- Free tier trains: The AI Studio free tier is used to improve Google products. Keep client code off the free tier.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Gemini 4 Argon · TB4 57.1% | 2 / 0.1 / 10 | 1M | 0.157 | – |
| Gemini 3.8 Flash · TB4 19.1% | 0.75 / 0.075 / 3.75 | 1M | 0.095 | USD 1,641 |
- Other tiers, Gemini 4 Argon: Flex: 0.5x; Fast/priority: 1.8x.
- Other tiers, Gemini 3.8 Flash: Flex: 0.5x; Fast/priority: 1.8x.
At our mix (97.9% cache) Gemini 3.8 Flash costs USD 0.095 per 1M tokens (USD 0.088 to 0.18 at 85-99% cache). At our mix (97.9% cache) Gemini 4 Argon costs USD 0.16 per 1M tokens (USD 0.14 to 0.4 at 85-99% cache).
At our mix a full Terminal-Bench 4.0 run of Gemini 3.8 Flash (TB4 19.1%) costs USD 1,641; the TB4 leaderboard measured USD 1,800.
Mistral API
Mistral AI is a Paris-based model developer founded in 2023. It publishes the Devstral 2 coding models with open weights (modified MIT and Apache 2.0 licences), sells them by the token through Mistral Studio, and includes its Mistral Vibe terminal coding agent in the Le Chat Pro and Team plans. On 8 September 2026 it raised €3 billion at a valuation of more than €21 billion (about $24 billion).
What to know:
- Verified cheap GLM 5.3: Mistral hosts GLM 5.3 at 1.4 / 0.14 / 4.4, confirmed on its own page: USD 0.174 per 1M at our mix against Z.ai's own 0.291.
- Quantisation flag: OpenRouter lists Mistral's GLM 5.3 endpoint as nvfp4. Test quality on your own tasks before you switch.
- EU price unverified: The EU regional row (1.54 / 0.154 / 4.84) sits behind a toggle that did not render. Confirm it if your data must stay in the EU.
- Own models unscored: Devstral 2 (256k, no cached price, USD 0.403 per 1M at our mix) and Mistral Large 4 have no Terminal-Bench 4.0 score here.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.14 / 4.4 | 1M | 0.174 | USD 1,511 |
| Devstral 2 · open | 0.4 / – / 2 | 256k | 0.403 | – |
| GLM 5.2 · open | 1.4 / 0.14 / 4.4 | 1M | 0.174 | – |
| Mistral Large 4 | 0.68 / 0.07 / 2.09 | 1M | 0.086 | – |
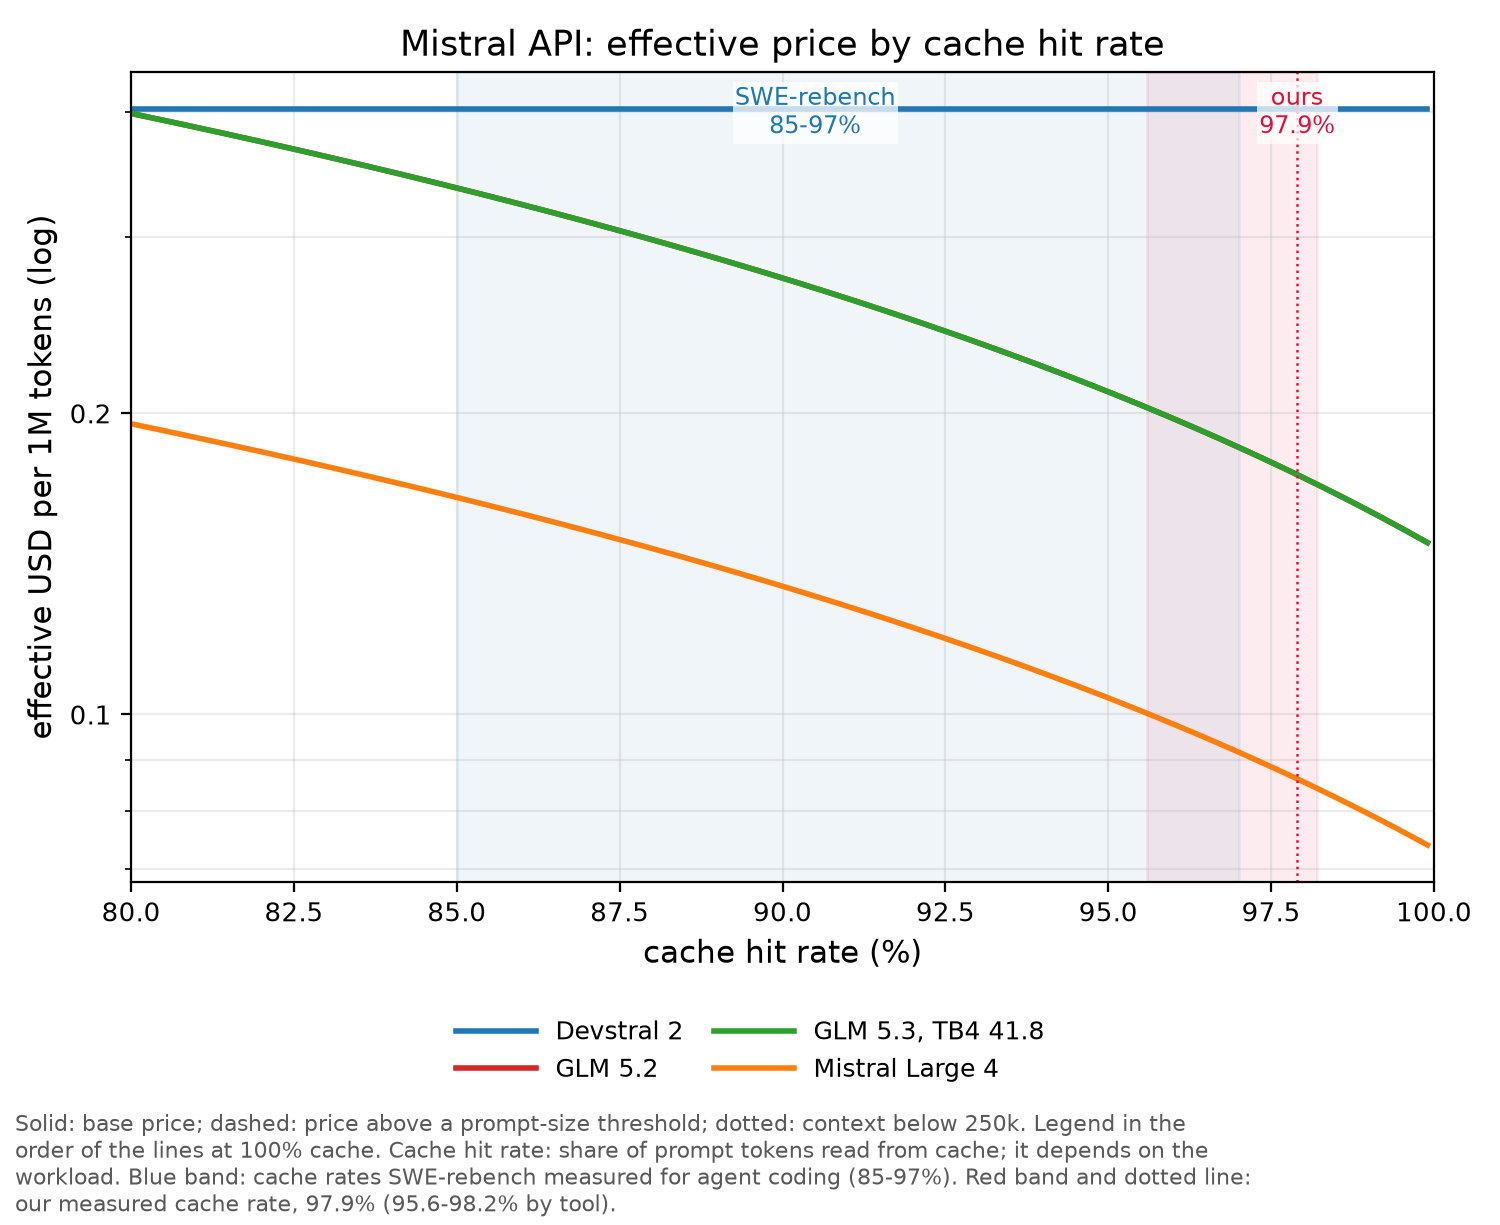
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 1,511; the TB4 leaderboard measured USD 2,700.
Z.ai API
Z.ai, until 2025 known internationally as Zhipu AI, is a Beijing company spun out of Tsinghua University in 2019. In January 2026 it became the first large-language-model company to list on a stock exchange (Hong Kong, ticker 2513). Its GLM family is the strongest open-weight line on Terminal-Bench 4.0: GLM 5.3 came out on 14 August 2026, with weights published two weeks later.
What to know:
- The open reference price: GLM 5.3 (41.8%) costs USD 0.291 per 1M at our mix and USD 2,531 per run, the yardstick for every GLM hoster.
- Weak cache discount: Z.ai's cached price is 0.26 against 1.40 input. Hosters charging 0.14 cached (Mistral, Baseten) come out at 0.174 at our mix.
- Cheapest verified elsewhere: Relace sells GLM 5.3 at 0.32x Z.ai's price, confirmed on its own page, and the Z.ai Coding Plan Max buys 1.8x. The maker's API is rarely your cheapest route.
- Flash for volume: GLM 5.3 Flash (35.8%) costs USD 0.033 per 1M and USD 97 per run, with 1M context.
- Cache lifetime undisclosed: Caching is automatic but its TTL is not disclosed, so your measured cache rate is the only guide.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| GLM 5.2 · open | 1.4 / 0.26 / 4.4 | 1M | 0.291 | – |
| GLM 5.3 FlashX | 0.37 / 0.075 / 1.25 | 1M | 0.083 | – |
- Caching (models with a cached input price (GLM-5.3, GLM-5.3-Flash, ...)): automatic; TTL not disclosed (open beta); "reasonable time limits"; cached discount usually 50% | sources differ: FAQ: approx. 1/5 of price; pricing: GLM-5.3 $0.26 vs $1.40; write fee none (cache storage limited-time free)
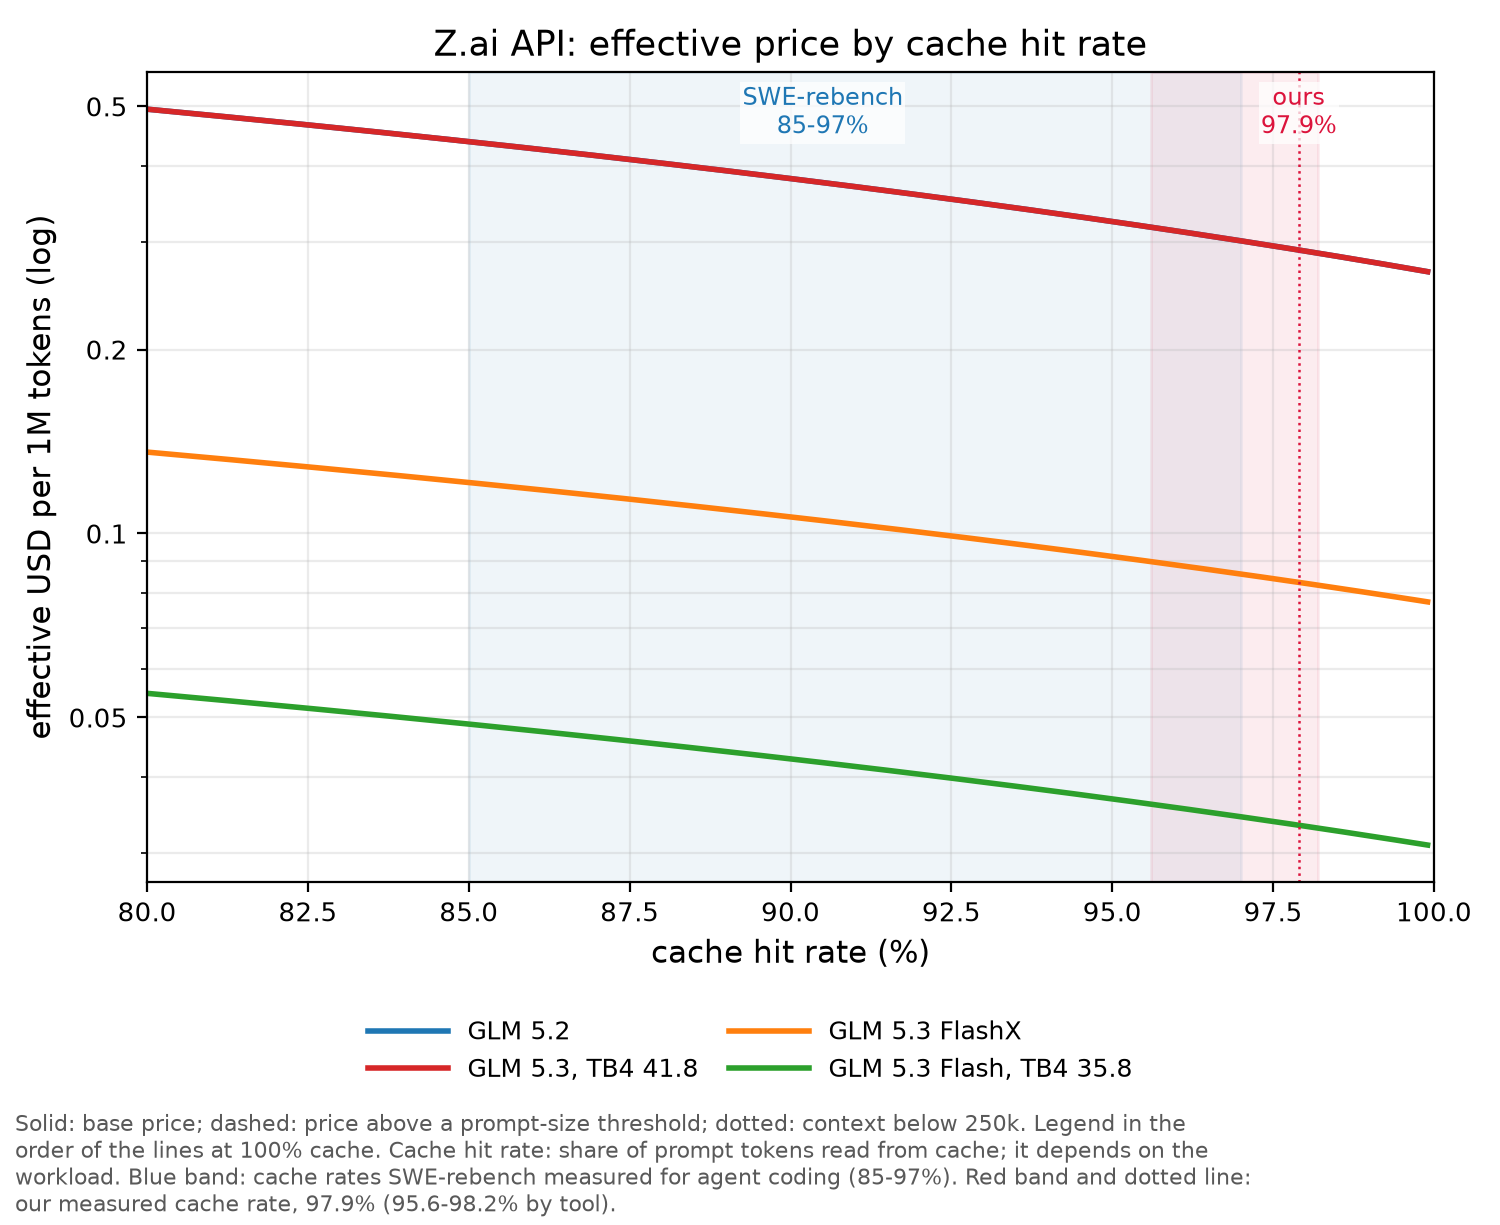
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 2,531; the TB4 leaderboard measured USD 2,700. At our mix a full Terminal-Bench 4.0 run of GLM 5.3 Flash (TB4 35.8%) costs USD 97; the TB4 leaderboard measured USD 2,900.
Alibaba Cloud Model Studio
Alibaba Cloud Model Studio is the model platform of Alibaba Cloud, the cloud unit of China's Alibaba Group. It serves Alibaba's Qwen models, several of which the Qwen team also publishes as open weights, and sells a $50-a-month Coding Plan that runs Qwen, GLM, Kimi and MiniMax models inside third-party coding tools. Alibaba's cloud revenue rose 45% year on year to 48.4 billion yuan in the June 2026 quarter.
What to know:
- GLM 5.3 below Z.ai: GLM 5.3 costs USD 0.264 per 1M at our mix against Z.ai's 0.291, with 1M context and regional price multipliers.
- Kimi K3 marked up: K3 lists 3.45 input here against 3.00 at Moonshot (0.439 against 0.382 at our mix); models.dev shows 3.00, so the price is disputed.
- Avoid hosted DeepSeek: DeepSeek V4 Pro costs USD 0.139 per 1M here, against 0.039 at DeepSeek itself.
- Qwen at the source: Qwen 3.8 Max (27%) costs 0.296 at our mix; DeepInfra sells it at 0.82x, verified.
- No training: Model Studio states that data is never used for training.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.19 / 0.238 / 3.74 | 1M | 0.264 | USD 2,296 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.03 / 1.2 | 1M | 0.038 | – |
| Qwen 3.8 Max · TB4 27% | 2 / 0.25 / 6 | 1M | 0.296 | USD 889 |
| DeepSeek V4 Pro · open · TB4 14% | 1.12 / 0.1122 / 3.37 | 1M | 0.139 | – |
| Kimi K3 · open · TB4 12.6% | 3.45 / 0.345 / 17.25 | 1M | 0.439 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.95 / 0.19 / 4 | 262k | 0.212 | – |
| GLM 5.2 · open | 0.97 / 0.1932 / 3.04 | 1M | 0.214 | – |
| GLM 5.3 Prime | 2.8 / 0.56 / 8.8 | 1M | 0.621 | – |
| Qwen 3.8 2.4T (open) · open | 2 / 0.25 / 6 + write 2.5 | 1M | 0.307 | – |
| Qwen 3.8 Flash · open | 0.15 / 0.016 / 0.47 | 1M | 0.020 | – |
-
Other tiers, GLM 5.3: Fast/priority: 2.35x; Singapore / International: 1.18x; China (Beijing) / Chinese mainland: 0.95x; Germany (Frankfurt) / Global: 0.95x; US (Virginia) / Global: 0.95x; Japan (Tokyo) / Global: 0.95x; Hong Kong (China) / Global: 0.95x.
-
Other tiers, DeepSeek V4.1 Flash: Singapore / International, peak: 1x; Singapore / International, off-peak: 0.5x; China (Beijing) / Chinese mainland, peak: 0.94x; China (Beijing) / Chinese mainland, off-peak: 0.47x; Germany (Frankfurt) / Global, peak: 0.94x; Germany (Frankfurt) / Global, off-peak: 0.47x; US (Virginia) / Global, peak: 0.94x; US (Virginia) / Global, off-peak: 0.47x; Japan (Tokyo) / Global, peak: 0.94x; Japan (Tokyo) / Global, off-peak: 0.47x; Hong Kong (China) / Global, peak: 0.94x; Hong Kong (China) / Global, off-peak: 0.47x.
-
Other tiers, Qwen 3.8 Max: Singapore / International: 1x; China (Beijing) / Chinese mainland: 0.82x; Hong Kong (China) / Global: 0.82x; Germany (Frankfurt) / Global: 0.82x; US (Virginia) / Global: 0.82x; US (Virginia) / US: 1x; Japan (Tokyo) / Global: 0.82x.
-
Other tiers, DeepSeek V4 Pro: Singapore / International: 2.14x; Singapore / International, peak: 1.18x; Singapore / International, off-peak: 0.59x; China (Beijing) / Chinese mainland: 1.47x; China (Beijing) / Chinese mainland, peak: 1.13x; China (Beijing) / Chinese mainland, off-peak: 0.57x; Germany (Frankfurt) / Global: 1.47x; Germany (Frankfurt) / Global, peak: 1.13x; Germany (Frankfurt) / Global, off-peak: 0.57x; US (Virginia) / Global: 1.47x; US (Virginia) / Global, peak: 1.13x; US (Virginia) / Global, off-peak: 0.57x; US (Virginia) / International: 2.14x; Japan (Tokyo) / Global: 1.47x; Japan (Tokyo) / Global, peak: 1.13x; Japan (Tokyo) / Global, off-peak: 0.57x; Japan (Tokyo) / International: 2.14x; Hong Kong (China) / Global, peak: 1.13x; Hong Kong (China) / Global, off-peak: 0.57x.
-
Other tiers, Kimi K3: China (Beijing) / Chinese mainland: 0.82x; Germany (Frankfurt) / Global: 0.82x; US (Virginia) / Global: 0.82x; US (Virginia) / International: 0.87x; Japan (Tokyo) / Global: 0.82x; Singapore / International: 0.87x; Hong Kong (China) / Global: 0.82x.
-
Other tiers, Kimi K2.7 Code: China (Beijing) / Chinese mainland: 0.94x; Germany (Frankfurt) / Global: 0.94x; US (Virginia) / Global: 0.94x; Japan (Tokyo) / Global: 0.94x; Singapore / International: 1x; Hong Kong (China) / Global: 0.94x.
-
Other tiers, GLM 5.2: Fast/priority: 2.39x; Singapore / International: 1.45x; China (Beijing) / Chinese mainland: 1.14x; Germany (Frankfurt) / Global: 1.14x; US (Virginia) / Global: 1.14x; US (Virginia) / US: 1.45x; Hong Kong (China) / Global: 1.14x.
-
Other tiers, Qwen 3.8 2.4T (open): Singapore / International: 1x; China (Beijing) / Chinese mainland: 0.82x.
-
Other tiers, Qwen 3.8 Flash: Singapore / International: 1x; China (Beijing) / Chinese mainland: 0.75x; Hong Kong (China) / Global: 0.75x; Germany (Frankfurt) / Global: 0.75x; US (Virginia) / Global: 0.75x; US (Virginia) / US: 1x; Japan (Tokyo) / Global: 0.75x.
-
Caching (Qwen, hosted DeepSeek, Kimi; kimi-k3 implicit only; qwen3-coder-flash only Coder listed | sources differ: OpenRouter lists qwen3-coder-plus): both; TTL explicit 5 min, resets on hit; implicit indeterminate; cached discount explicit 90%, implicit 80%; deepseek-v4.1-flash implicit 90%; qwen3.8-max/flash, deepseek-v4-pro: console only; write fee explicit 1.25x input on new increment only; implicit none; peak pricing: yes: night discounts 22:00-08:00 UTC+8 on some Qwen; hosted DeepSeek busy 08-22 UTC+8, idle half
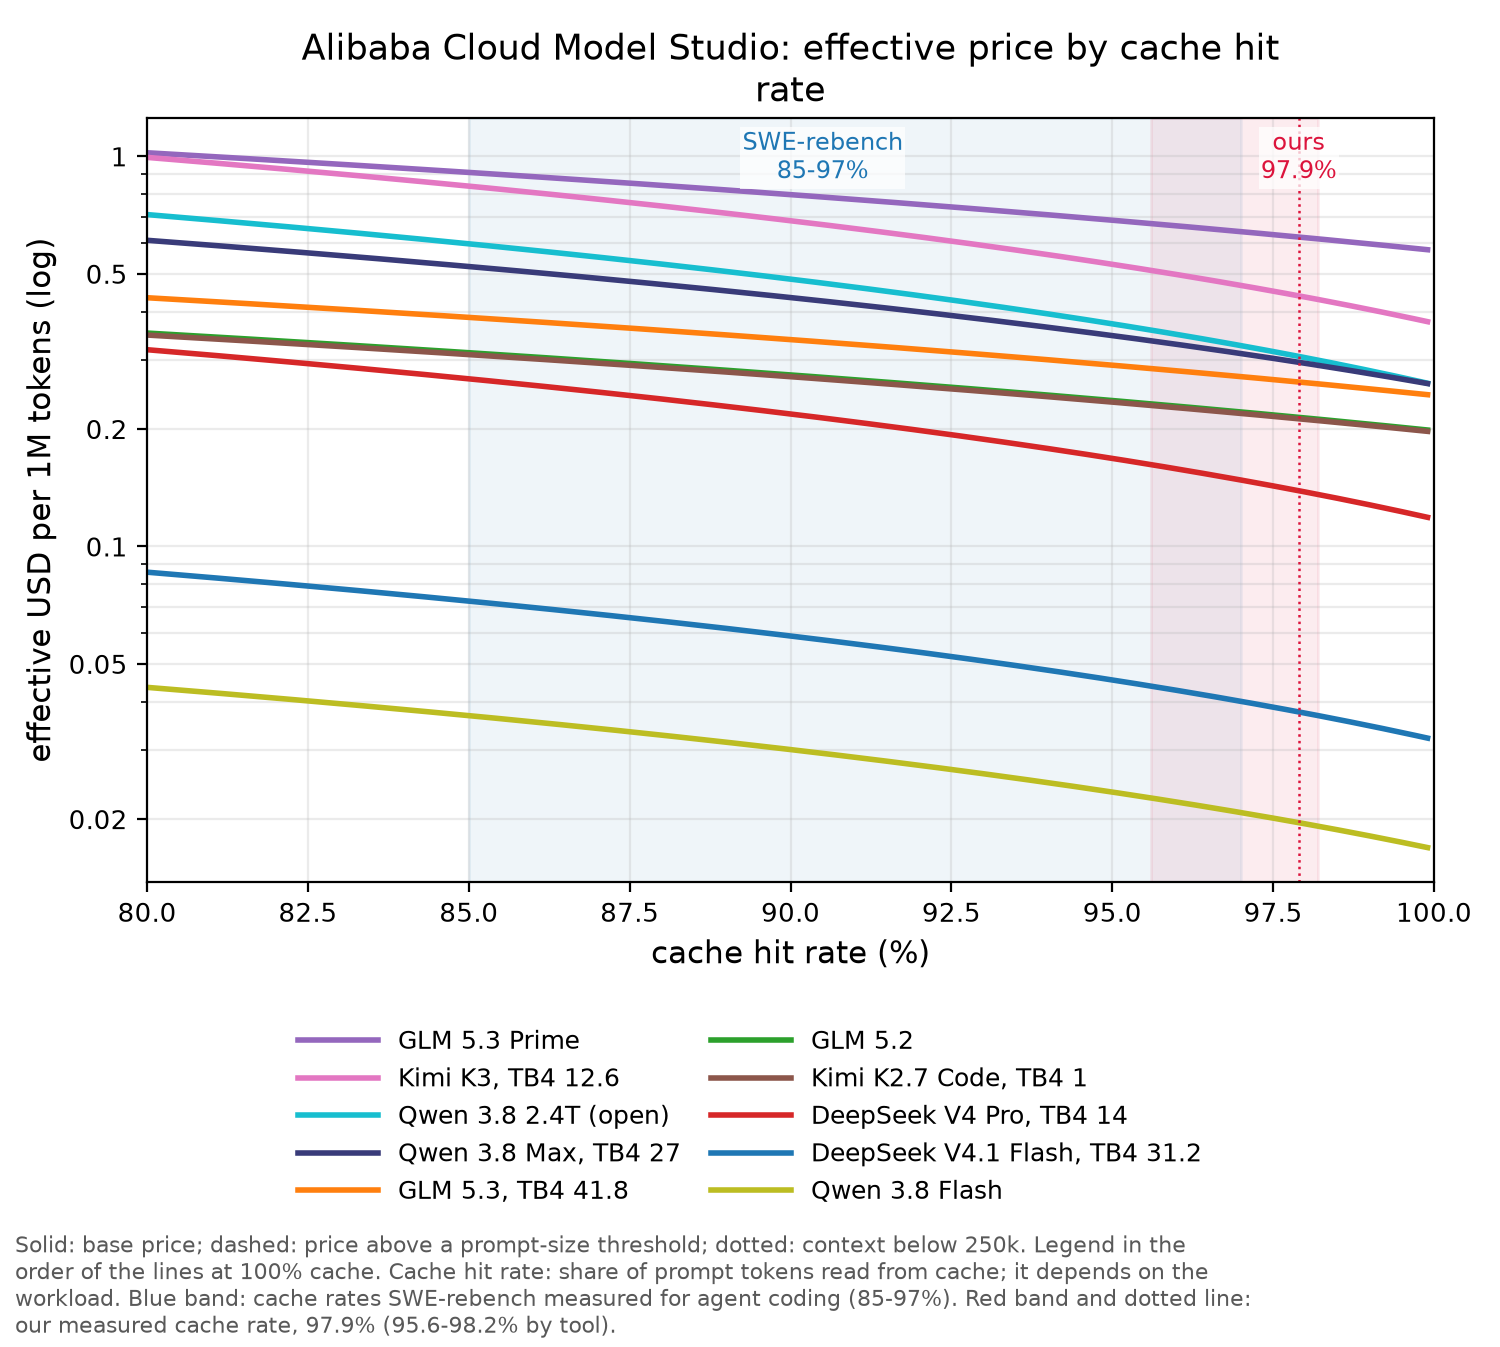
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 2,296; the TB4 leaderboard measured USD 2,700. At our mix a full Terminal-Bench 4.0 run of Qwen 3.8 Max (TB4 27%) costs USD 889; the TB4 leaderboard measured USD 4,600.
QwenCloud API
QwenCloud (qwencloud.com) is a developer site that Alibaba Cloud launched in Singapore on 26 May 2026 for markets outside China. It offers Qwen models and selected third-party models such as DeepSeek through one OpenAI-compatible key, a command-line tool and agent "skills", and sells a fixed-fee Token Plan subscription. Alibaba describes it as the overseas counterpart to its domestic Qwen cloud site rather than a module of the classic cloud console.
What to know:
- Context not stated: No model on QwenCloud lists a context window, so the 250k floor cannot be confirmed for any of them.
- DeepSeek costs more here: DeepSeek V4.1 Flash costs USD 0.019 per 1M at our mix, against 0.0071 at DeepSeek, and peak hours bill 2x.
- GLM 5.3 above maker: GLM 5.3 costs 0.310 against Z.ai's 0.291. Qwen 3.8 Max matches Alibaba at 0.296.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.28 / 4.4 | – | 0.310 | USD 2,701 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.15 / 0.015 / 0.6 | – | 0.019 | – |
| Qwen 3.8 Max · TB4 27% | 2 / 0.25 / 6 | – | 0.296 | USD 889 |
| DeepSeek V4 Pro · open · TB4 14% | 0.66 / 0.066 / 1.98 | – | 0.082 | – |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | – | 0.382 | – |
| GLM 5.3 Prime | 2.8 / 0.56 / 8.8 | – | 0.621 | – |
| Qwen 3.8 2.4T (open) · open | 2 / 0.25 / 6 | – | 0.296 | – |
| Qwen 3.8 Flash · open | 0.15 / 0.016 / 0.47 | – | 0.020 | – |
- Other tiers, DeepSeek V4.1 Flash: off-peak: 1x; peak: 2x.
- Other tiers, DeepSeek V4 Pro: off-peak: 1x; peak: 2x.
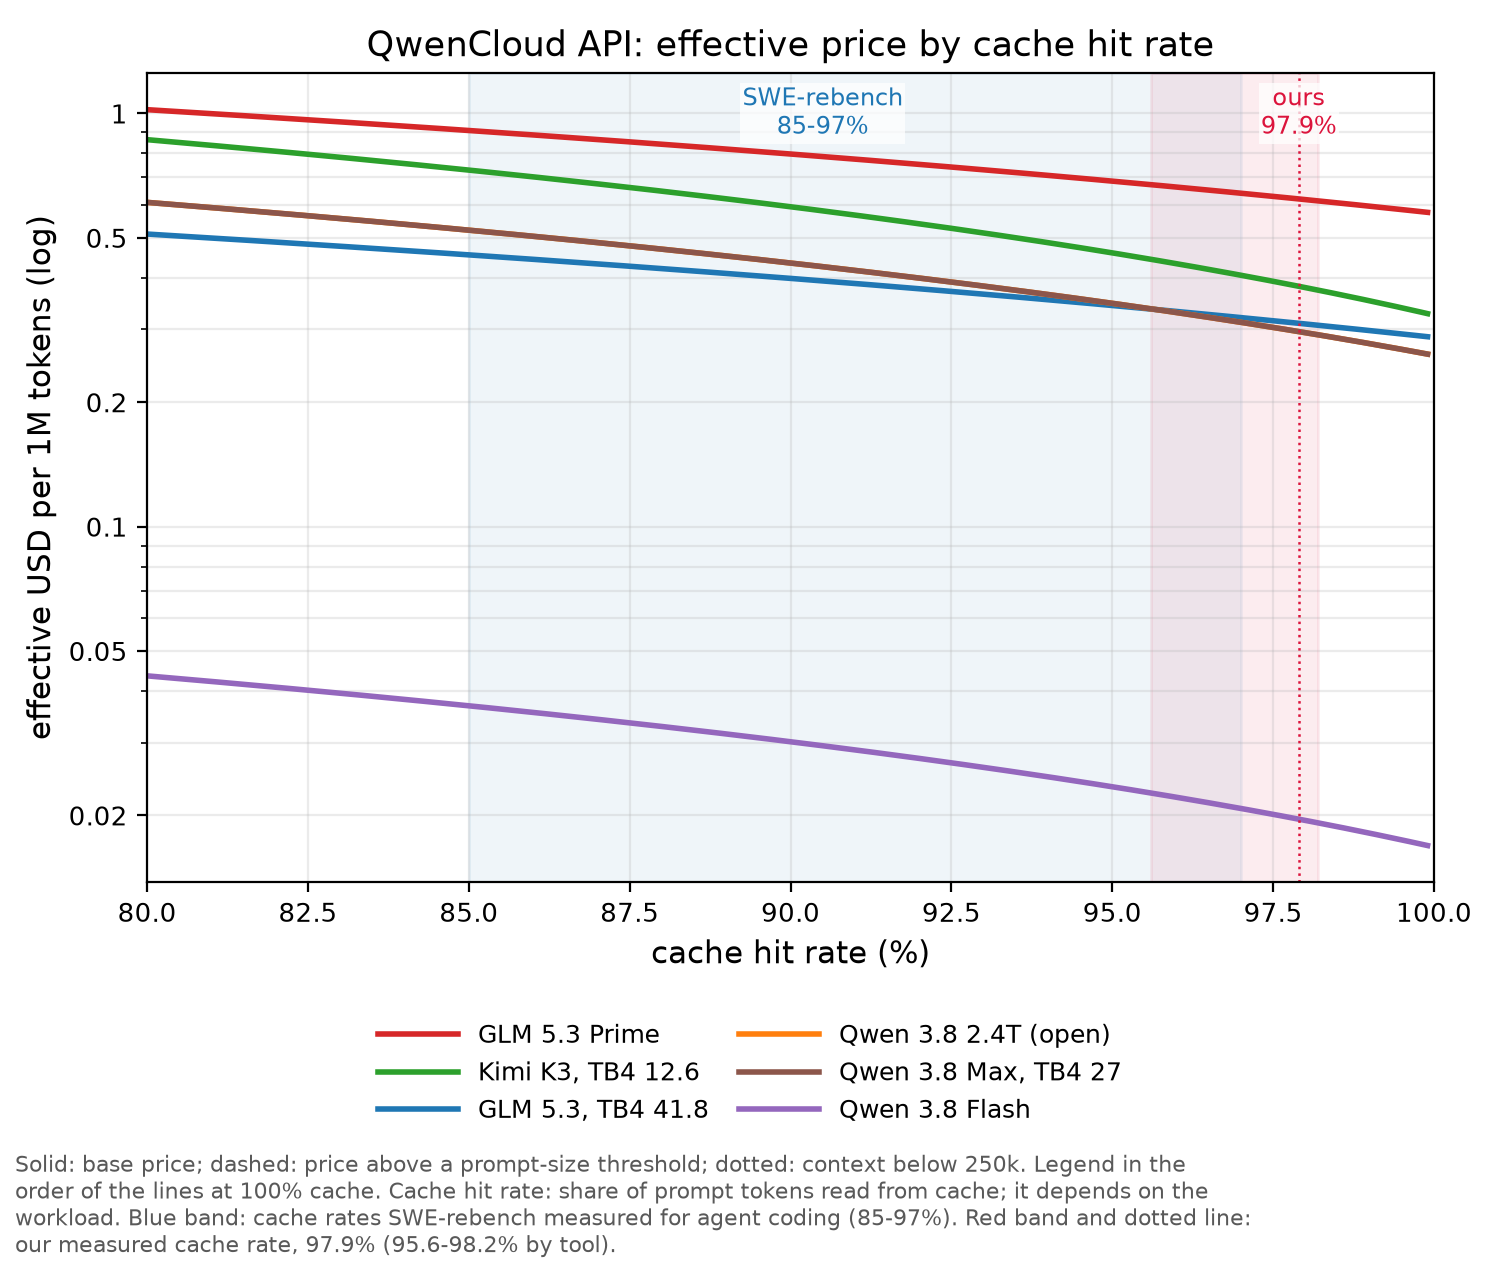
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 2,701; the TB4 leaderboard measured USD 2,700. At our mix a full Terminal-Bench 4.0 run of Qwen 3.8 Max (TB4 27%) costs USD 889; the TB4 leaderboard measured USD 4,600.
xAI API
xAI, Elon Musk's AI company, has been part of SpaceX since a February 2026 all-stock deal that valued xAI at $250 billion; its developer documentation now carries SpaceX branding. It sells Grok models by the token, including grok-4.7 and the coding model grok-build-0.1, and ships the Grok Build coding agent for the terminal. SpaceX raised $75 billion in its June 2026 Nasdaq initial public offering.
What to know:
- Long prompts double: Above 200k prompt tokens Grok 4.7 costs 4 / 1 / 12, so our mix pays USD 1.082 per 1M and USD 5,949 per run, the dearest run listed.
- Buy Grok on Bedrock: Bedrock lists Grok 4.7 without the long-prompt tier, confirmed on its own page: USD 0.541 per 1M and USD 2,974 per run at our mix.
- Weak for the price: Grok 4.7 scores 37.6%, below GLM 5.3 (41.8%) at USD 0.291 on Z.ai's API.
- Grok Build untested: Grok Build 0.1 has 256k context and no Terminal-Bench 4.0 score. Batch is 20% off; priority 2x.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Grok 4.7 · TB4 37.6% | 2 / 0.5 / 6 | 500k | 1.082 | USD 5,949 |
| Grok Build 0.1 | 1 / 0.2 / 2 | 256k | 0.440 | – |
- Other tiers, Grok 4.7: above 200k prompt: 4 / 1 / 12; Fast/priority: 2x; Fast/priority above 200k: 4x.
- Other tiers, Grok Build 0.1: above 200k prompt: 2 / 0.4 / 4; Fast/priority: 2x; Fast/priority above 200k: 4x.
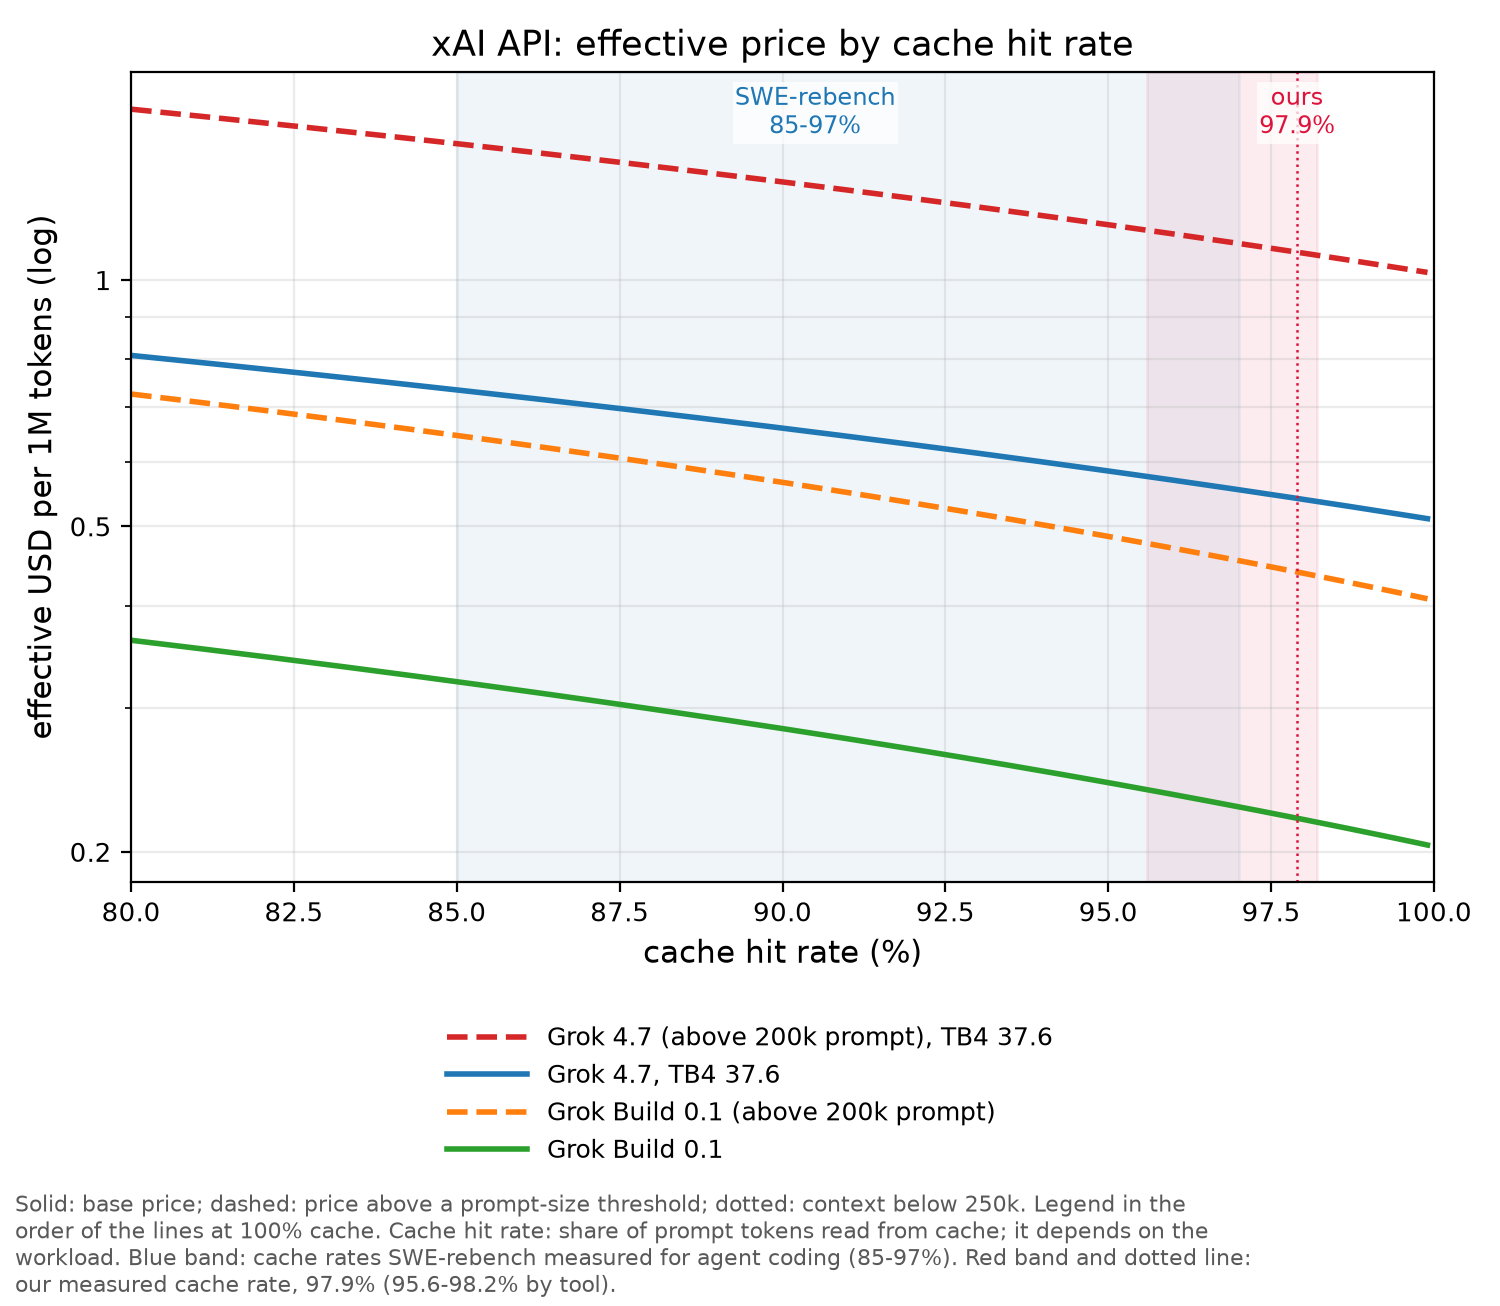
At our mix a full Terminal-Bench 4.0 run of Grok 4.7 (TB4 37.6%) costs USD 2,974 (USD 5,949 above 200k prompt); the TB4 leaderboard measured USD 3,700.
Xiaomi MiMo API
Xiaomi, the Beijing-based phone and electric-vehicle maker founded in 2010, builds the MiMo models through a team led by former DeepSeek researcher Luo Fuli. It publishes MiMo weights under the MIT licence, most recently MiMo-V2.6 Pro and Flash (22 September 2026), and sells access through its own platform and the MiMo Code app. In March 2026 it pledged at least 60 billion yuan ($8.7 billion) for AI over three years.
What to know:
- Cheapest at 35%: MiMo V2.6 Pro (34.8%) costs USD 0.014 per 1M at our mix with 1M context, 21% of Claude Haiku 5.5's price.
- Near-free cache: Cached input costs 0.0036 against 0.43 input, so at our 97.9% cache reads the input price barely matters.
- Flash for bulk: MiMo V2.6 Flash (28.8%, vendor-reported) costs USD 0.006 per 1M, 9% of Claude Haiku 5.5's price.
- Plan adds little: The Token Plan Max buys only 1.2x the API's tokens and adds a hard stop. Pay per use instead.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| MiMo V2.6 Pro · open · TB4 34.8% | 0.43 / 0.0036 / 0.87 | 1M | 0.014 | – |
| MiMo V2.6 Flash · open · TB4 28.8% (vendor) | 0.14 / 0.0028 / 0.28 | 1M | 0.006 | – |
At our mix (97.9% cache) MiMo V2.6 Flash costs USD 0.0061 per 1M tokens (USD 0.0046 to 0.024 at 85-99% cache). At our mix (97.9% cache) MiMo V2.6 Pro costs USD 0.014 per 1M tokens (USD 0.0094 to 0.07 at 85-99% cache).
DeepSeek API
DeepSeek is a Hangzhou-based model developer created in 2023 by the quantitative hedge fund High-Flyer, whose founder Liang Wenfeng leads it. It publishes open weights for its models, most recently the DeepSeek-V4 Pro and Flash family (April 2026), and sells pay-per-token access with off-peak discounts. In June 2026 it raised about $7.4 billion at a valuation above $50 billion in its first outside funding round.
What to know:
- Cheapest maker API: DeepSeek V4.1 Flash costs USD 0.0071 per 1M at our mix with 1M context; Alibaba, Atlas Cloud and Vertex charge 5.3 times more.
- Cache built for agents: Cached input is about 98% off for Flash and 99% for V4 Pro, with no fixed TTL; unused entries clear after hours to days.
- Off-peak half price: Prices halve outside peak hours (01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday). Schedule batch work there.
- V4 Pro: buy direct: DeepSeek V4 Pro (14%) is cheapest at the maker, USD 0.039 per 1M; the cheapest reseller, GMICloud, is 1.6x and quantised.
- Training opt-out: De-identified data trains DeepSeek models unless you opt out.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.15 / 0.003 / 0.6 | 1M | 0.007 | – |
| DeepSeek V4 Pro · open · TB4 14% | 0.66 / 0.022 / 1.98 | 1M | 0.039 | – |
- Caching (deepseek-flash (V4.1-Flash), deepseek-v4-pro): automatic; TTL no fixed TTL; unused cache cleared in a few hours to a few days; cached discount ~98% Flash, ~99.17% Pro (13 Aug 2026 prices) | sources differ: third-party Sep 2026: ~96.7% V4-Pro ($0.044 vs $1.32); write fee none (storage free); peak pricing: yes: off-peak half price; peak 01-04 and 06-10 UTC Mon-Fri
At our mix (97.9% cache) DeepSeek V4.1 Flash costs USD 0.0071 per 1M tokens (USD 0.0055 to 0.026 at 85-99% cache). At our mix (97.9% cache) DeepSeek V4 Pro costs USD 0.039 per 1M tokens (USD 0.032 to 0.12 at 85-99% cache).
Moonshot AI API
Moonshot AI is a Beijing-based model developer founded in spring 2023. It releases the Kimi models, including the open-weight Kimi K3 (July 2026), sells access through its developer platform, and includes the Kimi Code desktop app, command-line tool and VS Code extension in its Kimi membership. In September 2026 it filed confidentially for a Hong Kong listing.
What to know:
- Expensive for its score: Kimi K3 costs USD 0.382 per 1M at our mix for 12.6% on Terminal-Bench 4.0, 768% of GPT-6 Luna's price, which scores higher.
- Short cache, write fee: The K3 cache lives 5 minutes by default (1 hour optional), and writes bill 1x input for 5 minutes, 2x for 1 hour.
- Cheaper elsewhere, unconfirmed: NanoGPT sells K3 at 0.52x and Chutes at 0.62x, both from aggregator data only.
- K2.7 Code skip: Kimi K2.7 Code has 262k context and scores 1%.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 + write 3 | 1M | 0.382 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.95 / 0.19 / 4 | 262k | 0.212 | – |
-
Other tiers, Kimi K2.7 Code: Fast/priority: 2x.
-
Caching (kimi-k3): automatic; TTL 5 min default or 1 h (prompt_cache_options / top-level cache_control); renews on hit; locked at first write; cached discount 90% ($0.30 vs $3.00); write fee separate line item: 1x input (5 min), 2x input (1 h), derived from example | sources differ: third-party catalog: $0 writes
-
Caching (kimi-k2.7, kimi-k2.7-highspeed, kimi-k2.6 (incl. k2.7-code per third-party)): automatic; TTL 5 min default or 1 h; renews on hit; locked at first write; cached discount 80% on kimi-k2.7-code ($0.19 vs $0.95, third-party catalogs only); write fee none (Cache Write not supported on these models)
At our mix (97.9% cache) Kimi K2.7 Code costs USD 0.21 per 1M tokens (USD 0.2 to 0.31 at 85-99% cache). At our mix (97.9% cache) Kimi K3 costs USD 0.38 per 1M tokens (USD 0.35 to 0.73 at 85-99% cache).
MiniMax API
MiniMax is a Chinese model developer founded in 2022. It sells its M-series models by the token, describes its current M3 model as open-weight with a full release on Hugging Face and GitHub announced, and offers a Token Plan from $22 a month that covers third-party coding tools and its own MiniMax Code agent. It listed in Hong Kong on 9 January 2026 after raising about HK$4.8 billion ($620 million).
What to know:
- Cheap token, weak task: MiniMax M3 costs USD 0.067 per 1M at our mix but scores 2%, 206% of GPT-6 Luna's price for a lower score.
- Context stops at 524k: M3 offers 524k context, and prompts above 512k pay double (0.6 / 0.12 / 2.4).
- Cache discount unstated: MiniMax gives no cached-input number on its own pages; the 80% comes from third-party listings.
- Plan beats the API: If you use M3, Token Plan Ultra buys 4.4x the API's tokens. Priority tier costs 1.5x.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| MiniMax M3 · open · TB4 2% | 0.3 / 0.06 / 1.2 | 524k | 0.067 | – |
-
Other tiers, MiniMax M3: above 512k prompt: 0.6 / 0.12 / 2.4.
-
Caching (MiniMax M3 and API models): both; TTL explicit 5 min, refreshes free on hit; automatic not stated; cached discount "discounted price", no number first-party; third-party M3 $0.06 vs $0.30 (80%); write fee automatic: none stated; explicit: write price in table not captured; peak pricing: not stated (Priority tier 1.5x is a service tier)
At our mix (97.9% cache) MiniMax M3 costs USD 0.067 per 1M tokens (USD 0.064 to 0.098 at 85-99% cache). At our mix (97.9% cache) MiniMax M3 (above 512k prompt) costs USD 0.13 per 1M tokens (USD 0.13 to 0.2 at 85-99% cache).
DeepInfra
DeepInfra is a US inference company that runs its own GPU servers in eight US data centres and serves more than 150 open-weight models through OpenAI-compatible endpoints, billed per token. Its founders previously built the messaging app imo. On 4 May 2026 it announced a $107 million Series B ($67 million equity, $40 million debt) with investors including Nvidia and Samsung Next.
What to know:
- Cheap GLM, quantised: GLM 5.3 costs USD 0.138 per 1M at our mix, 0.48x Z.ai's 0.291, the second-cheapest verified offer after Relace. OpenRouter lists it as fp4.
- Cheapest verified Qwen: 0.244 against Alibaba's 0.296 (0.82x), though context stops at 256k, just above the floor.
- DeepSeek near maker price: DeepSeek V4.1 Flash costs USD 0.0078 per 1M against DeepSeek's own 0.0071, with Flex at 0.8x.
- Cheapest K2.7 Code: Kimi K2.7 Code at 0.72x the maker, from aggregator data only, and the model scores 1%.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 0.56 / 0.125 / 2.5 | 1M | 0.138 | USD 1,202 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.07 / 0.015 / 0.25 | 1M | 0.017 | USD 48 |
| MiMo V2.6 Pro · open · TB4 34.8% | 0.43 / 0.0036 / 0.87 | 1M | 0.014 | – |
| Step 5 Preview · open · TB4 33.3% | 1 / 0.1 / 2.7 | 1M | 0.123 | – |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.14 / 0.0042 / 0.42 | 1M | 0.008 | – |
| MiMo V2.6 Flash · open · TB4 28.8% (vendor) | 0.13 / 0.0027 / 0.27 | 1M | 0.006 | – |
| Qwen 3.8 Max · TB4 27% | 1.65 / 0.206 / 4.95 | 256k | 0.244 | USD 733 |
| DeepSeek V4 Pro · open · TB4 14% | 1.3 / 0.1 / 2.6 | 1M | 0.129 | – |
| Kimi K3 · open · TB4 12.6% | 2.85 / 0.285 / 14.25 + write 3.56 | 1M | 0.377 | – |
| MiniMax M3 · open · TB4 2% | 0.28 / 0.056 / 1.1 | 524k | 0.062 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.68 / 0.136 / 3.4 | 262k | 0.153 | – |
| GLM 5.2 · open | 0.56 / 0.105 / 1.8 + write 0.7 | 1M | 0.120 | – |
| gpt-oss-120b · open | 0.04 / – / 0.17 | 131k (below 250k) | 0.037 | – |
| Nemotron 3 Ultra · open | 0.5 / 0.1 / 2.2 | 262k | 0.112 | – |
| Qwen 3.8 27B · open | 0.2 / 0.05 / 2.5 | 262k | 0.057 | – |
| Qwen 3.8 Flash · open | 0.11 / 0.0141 / 0.38 | 1M | 0.017 | – |
-
Other tiers, GLM 5.3: Flex: 0.8x.
-
Other tiers, DeepSeek V4.1 Flash: Flex: 0.8x; Fast/priority: 1.5x.
-
Other tiers, DeepSeek V4 Pro: Fast/priority: 1.5x; Flex: 0.8x.
-
Other tiers, MiniMax M3: Flex: 0.8x.
-
Other tiers, GLM 5.2: Flex: 0.8x; Fast/priority: 1.5x.
-
Other tiers, Nemotron 3 Ultra: Flex: 0.8x.
-
Caching (supported models (not named); retention on some models): both; TTL default: expires after inactivity (no duration); paid retention: 5 min or 1 h; cached discount per-model cached price, no single % (e.g. GLM-5.3 list $0.20 vs $1.20); write fee none by default; retention: upfront cache-write premium (amount not captured)
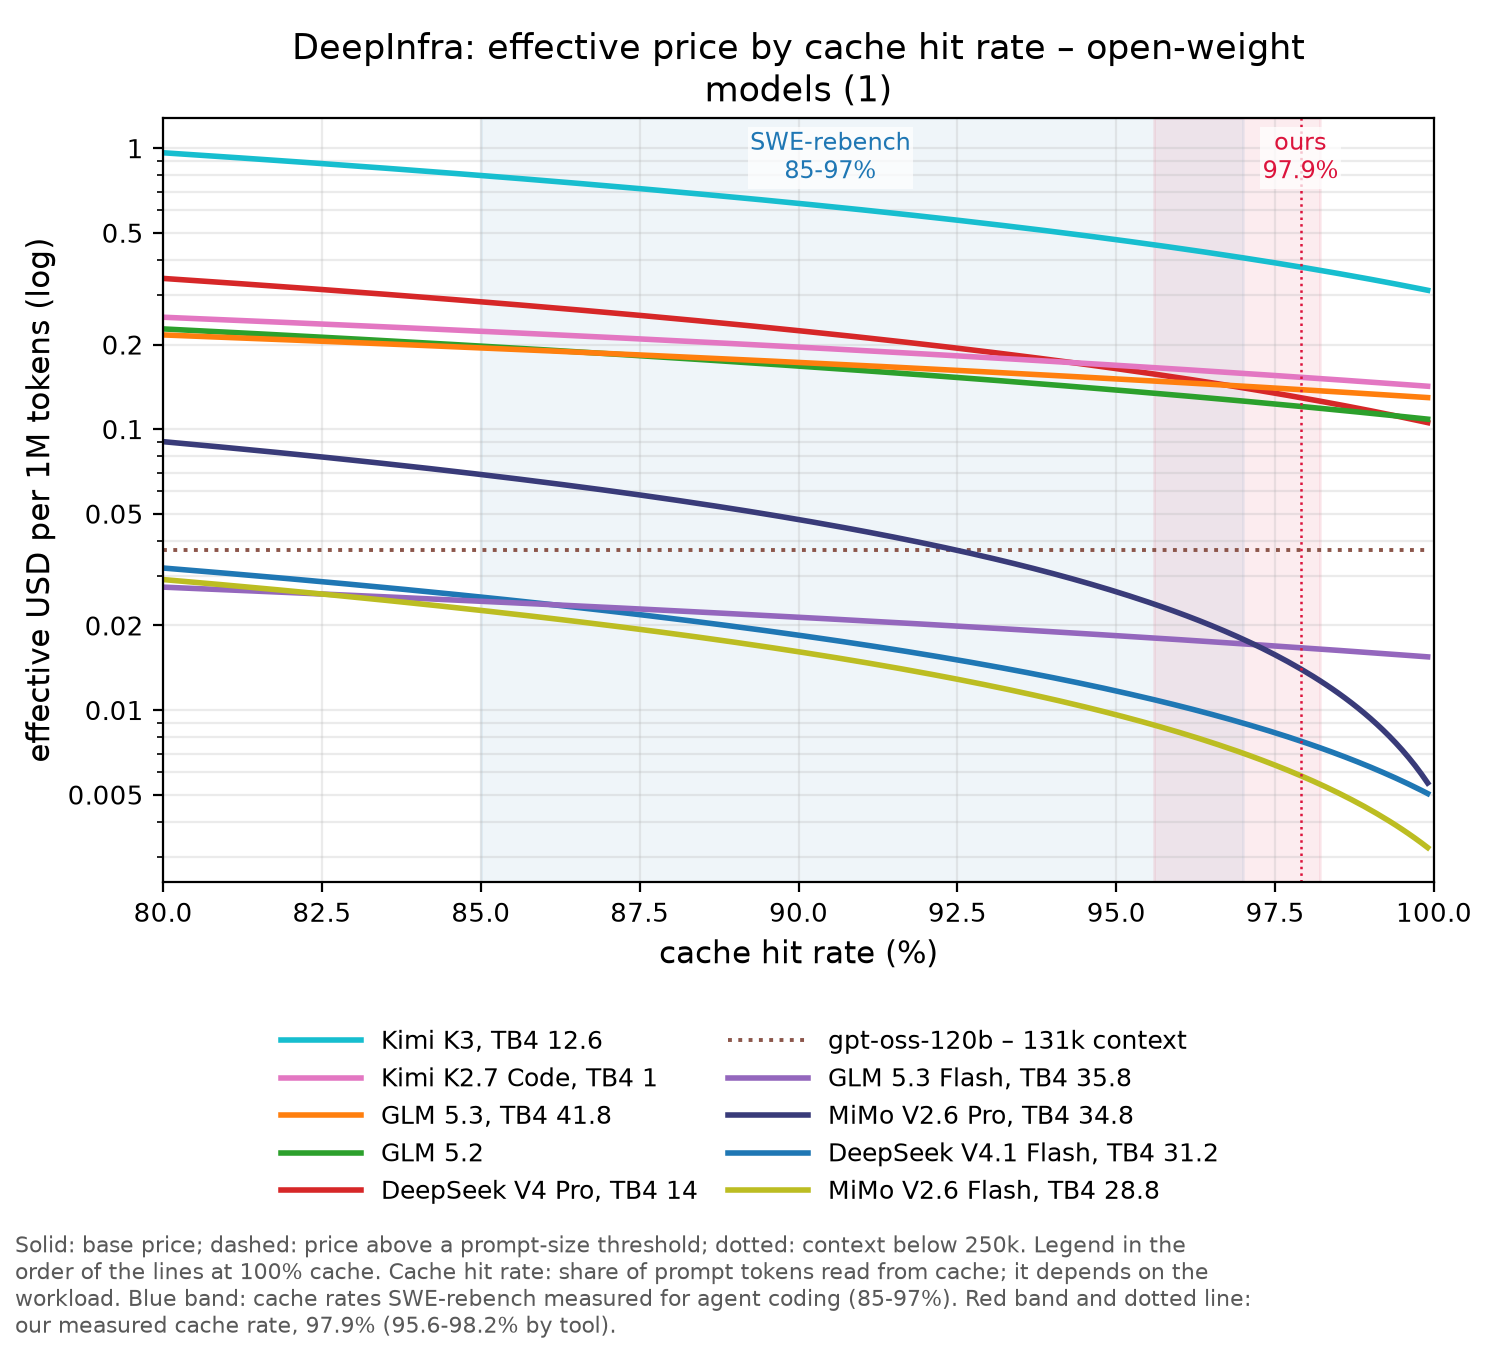
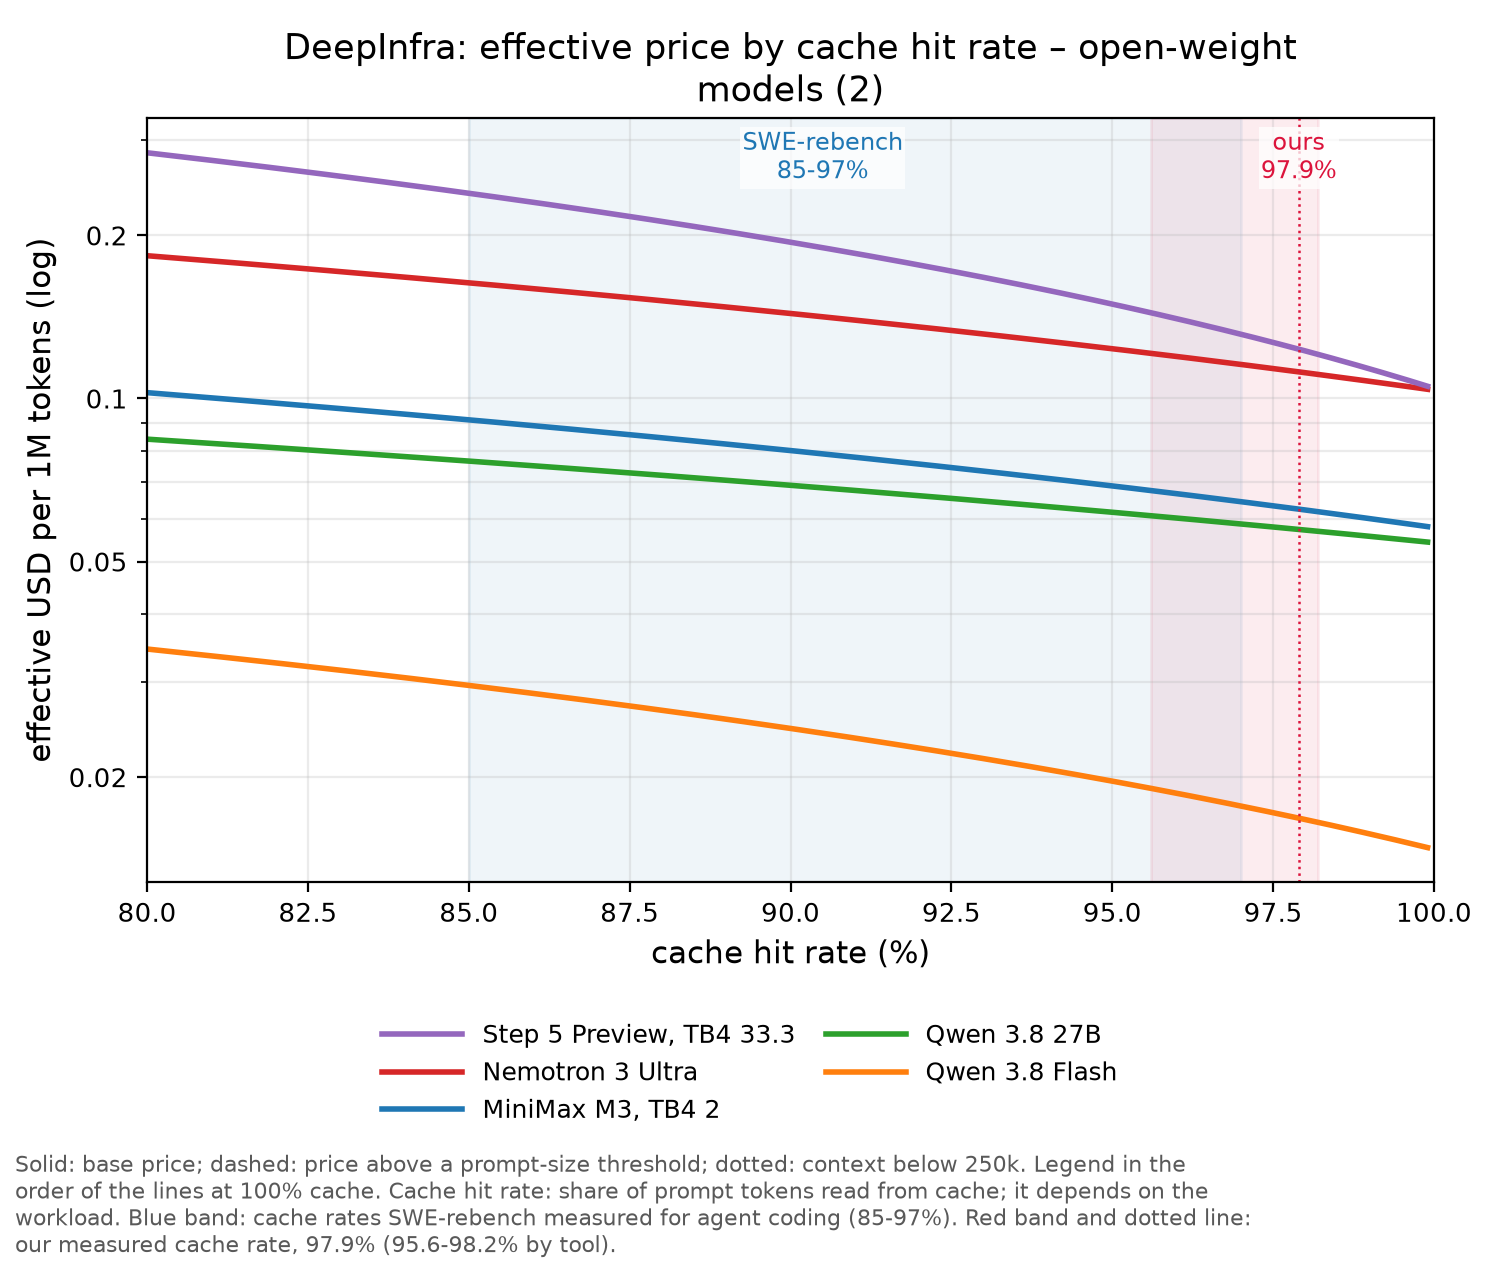
At our mix (97.9% cache) Qwen 3.8 Max costs USD 0.24 per 1M tokens (USD 0.23 to 0.43 at 85-99% cache).
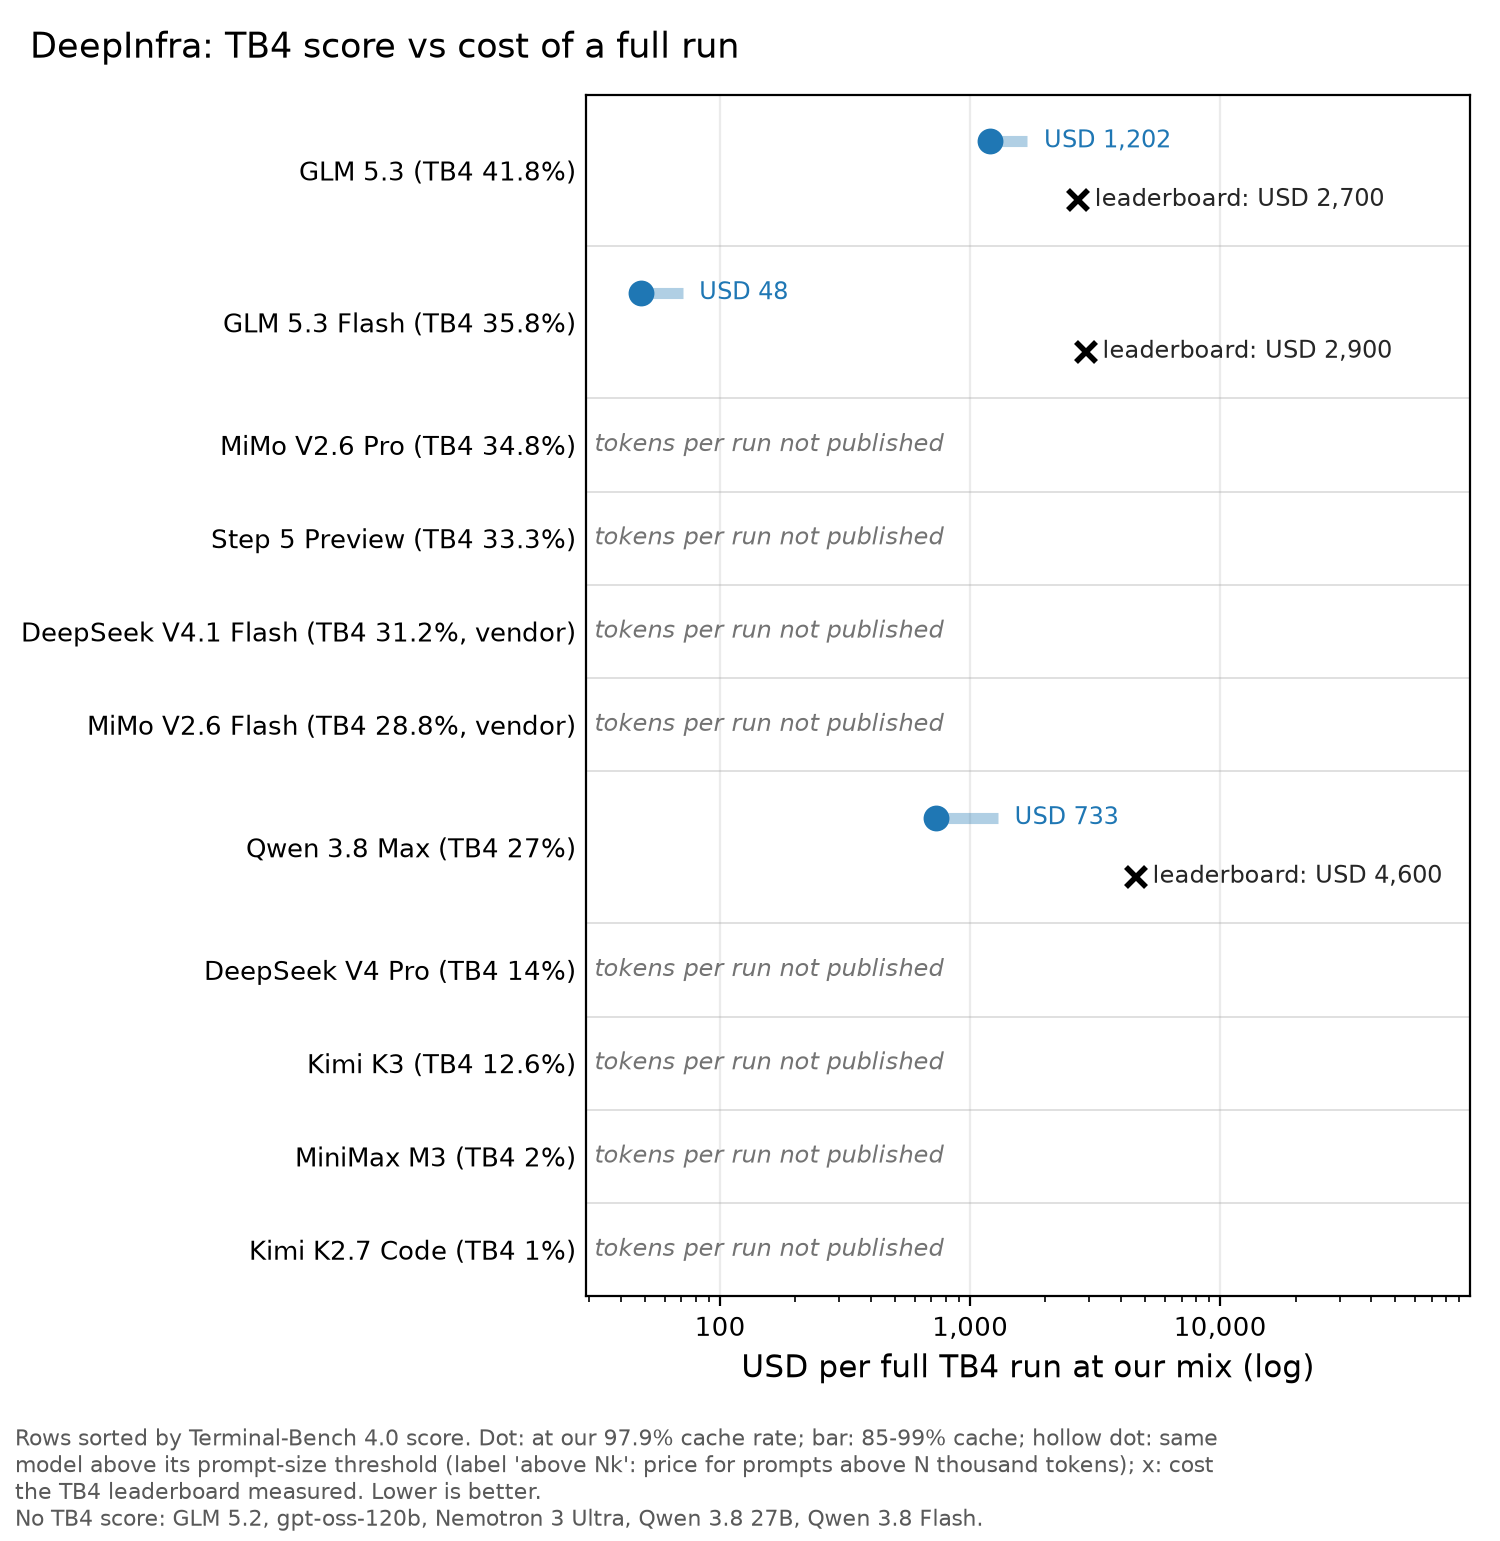
Microsoft Azure AI Foundry
Microsoft Foundry, formerly Azure AI Foundry, is Microsoft's platform for deploying models and agents on Azure. Microsoft says its catalogue holds more than 11,000 models, including models from OpenAI, Anthropic, Mistral and xAI and Microsoft's own MAI family. On 29 July 2026 Microsoft said Foundry had 100,000 customers and that Foundry revenue had more than doubled year on year.
What to know:
- Closed models at list: GPT-6.1 Sol (0.326) and Claude Opus 5.5 (0.334) cost exactly the makers' prices at our mix. Choose Azure for contract or credits.
- Avoid hosted DeepSeek: DeepSeek V4 Pro costs USD 0.203 per 1M here against 0.039 at DeepSeek.
- Startup credits limited: Microsoft for Startups gives USD 1,000, then 4,000, up to 150,000 with an investor; Azure OpenAI is not named as covered.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Claude Opus 5.5 · TB4 64.8% | 4 / 0.2 / 20 + write 5 | 1M | 0.334 | USD 2,674 |
| Claude Sonnet 5.5 · TB4 61.8% | 2 / 0.1 / 10 + write 2.5 | 1M | 0.167 | USD 3,243 |
| GPT-6.1 Sol · TB4 58.2% | 2 / 0.1 / 10 + write 2.5 | 1.1M | 0.326 | USD 489 |
| GPT-6 Astra · TB4 58.2% | 10 / 1 / 50 + write 12.5 | 1.1M | 2.606 | USD 3,909 |
| Claude Fable 5.1 · TB4 57.9% | 10 / 0.25 / 50 + write 12.5 | 1M | 0.591 | USD 1,597 |
| GPT-6 Sol · TB4 49.4% | 2 / 0.2 / 10 + write 2.5 | 1.1M | 0.521 | USD 2,606 |
| Claude Haiku 5.5 · TB4 39.2% (vendor) | 0.1 / 0.01 / 0.5 + write 0.12 | 1M | 0.066 | – |
| GPT-6 Luna · TB4 16.4% | 0.1 / 0.01 / 0.5 + write 0.12 | 1.1M | 0.026 | USD 102 |
| DeepSeek V4 Pro · open · TB4 14% | 1.91 / 0.16 / 3.83 | 1M | 0.203 | – |
- Other tiers, GPT-6.1 Sol: above 272k prompt: 4 / 0.2 / 15 + write 5.
- Other tiers, GPT-6 Astra: above 272k prompt: 20 / 2 / 75 + write 25.
- Other tiers, GPT-6 Sol: above 272k prompt: 4 / 0.4 / 15 + write 5.
- Other tiers, Claude Haiku 5.5: above 100k prompt: 0.5 / 0.05 / 2.5 + write 0.62.
- Other tiers, GPT-6 Luna: above 272k prompt: 0.2 / 0.02 / 0.75 + write 0.25.
At our mix (97.9% cache) DeepSeek V4 Pro costs USD 0.2 per 1M tokens (USD 0.18 to 0.43 at 85-99% cache).
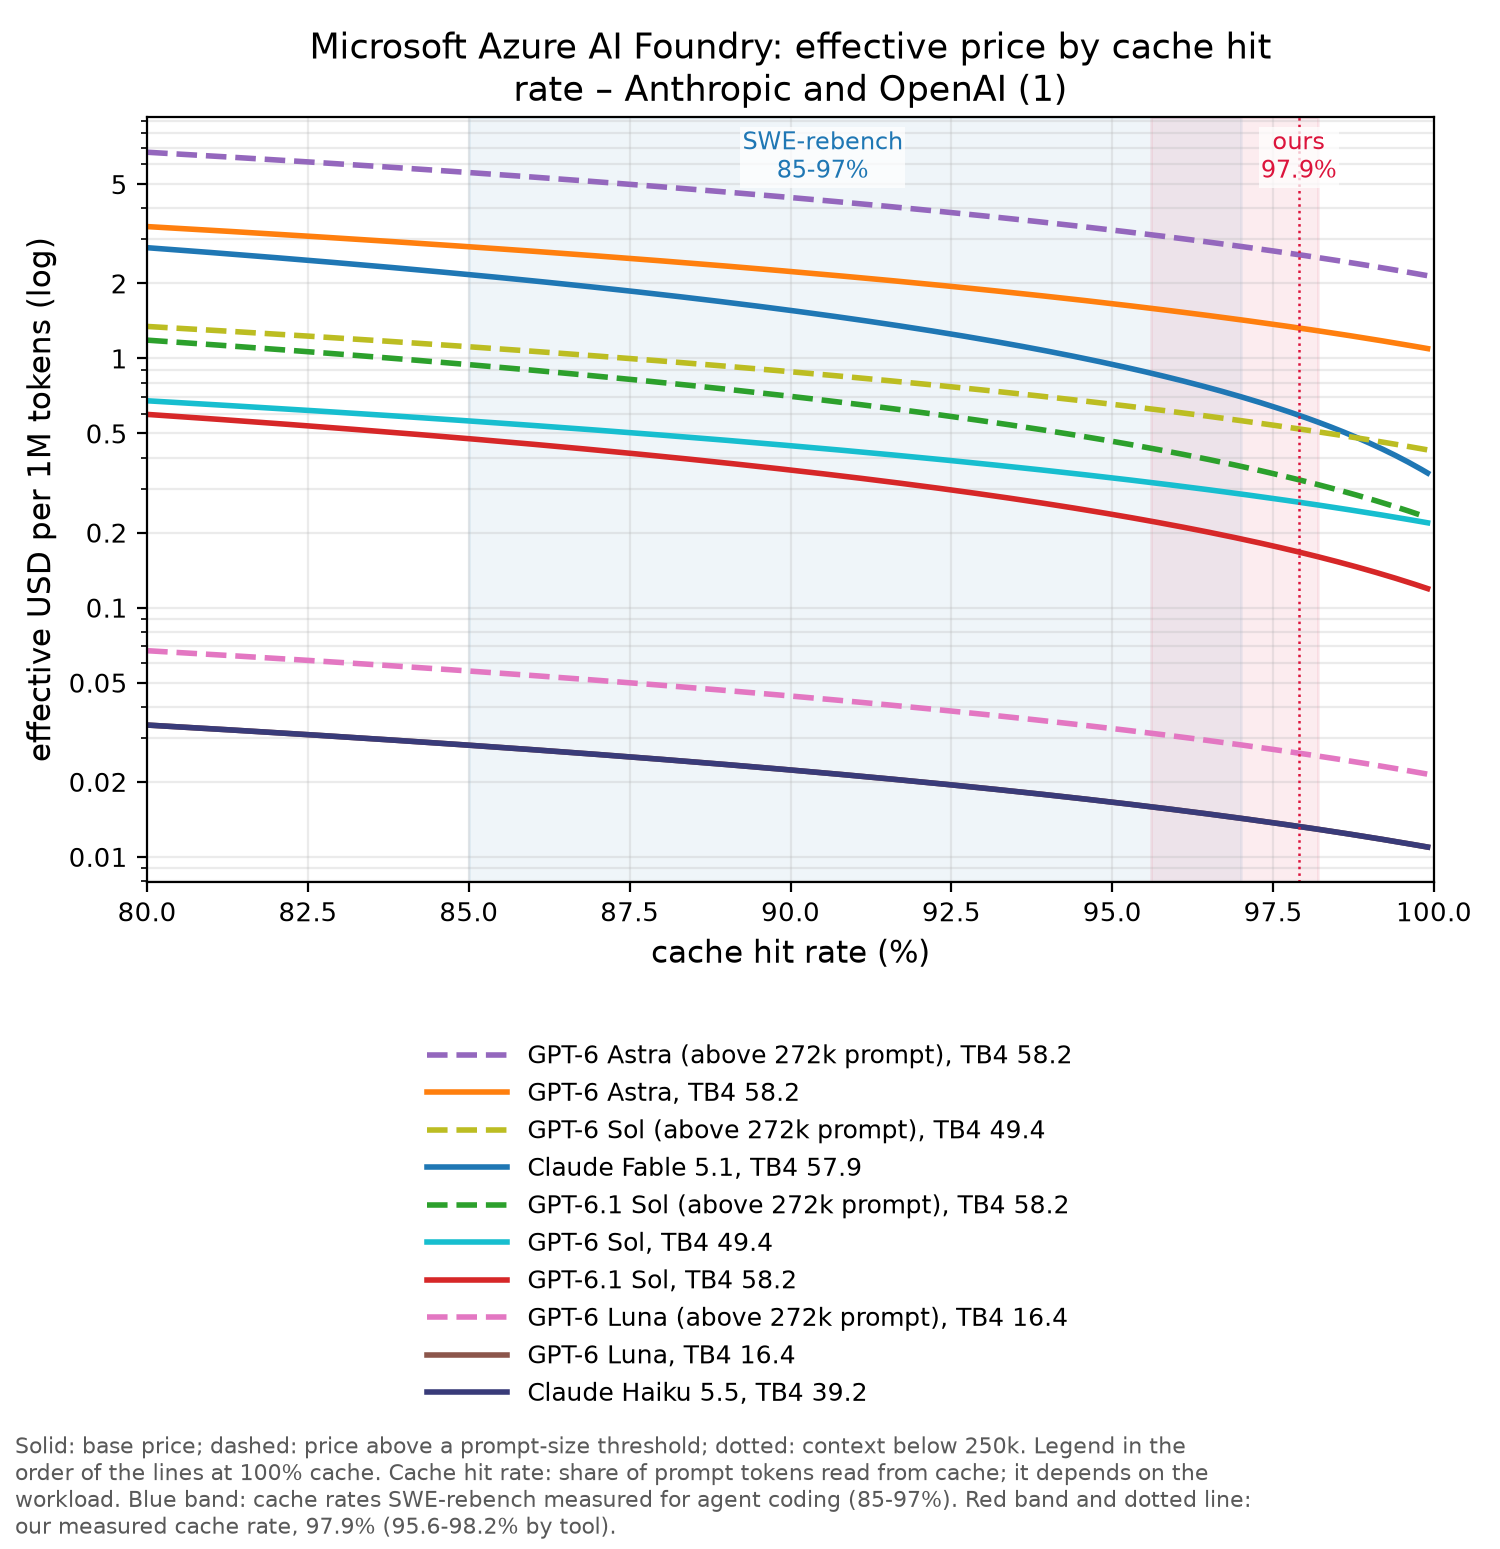
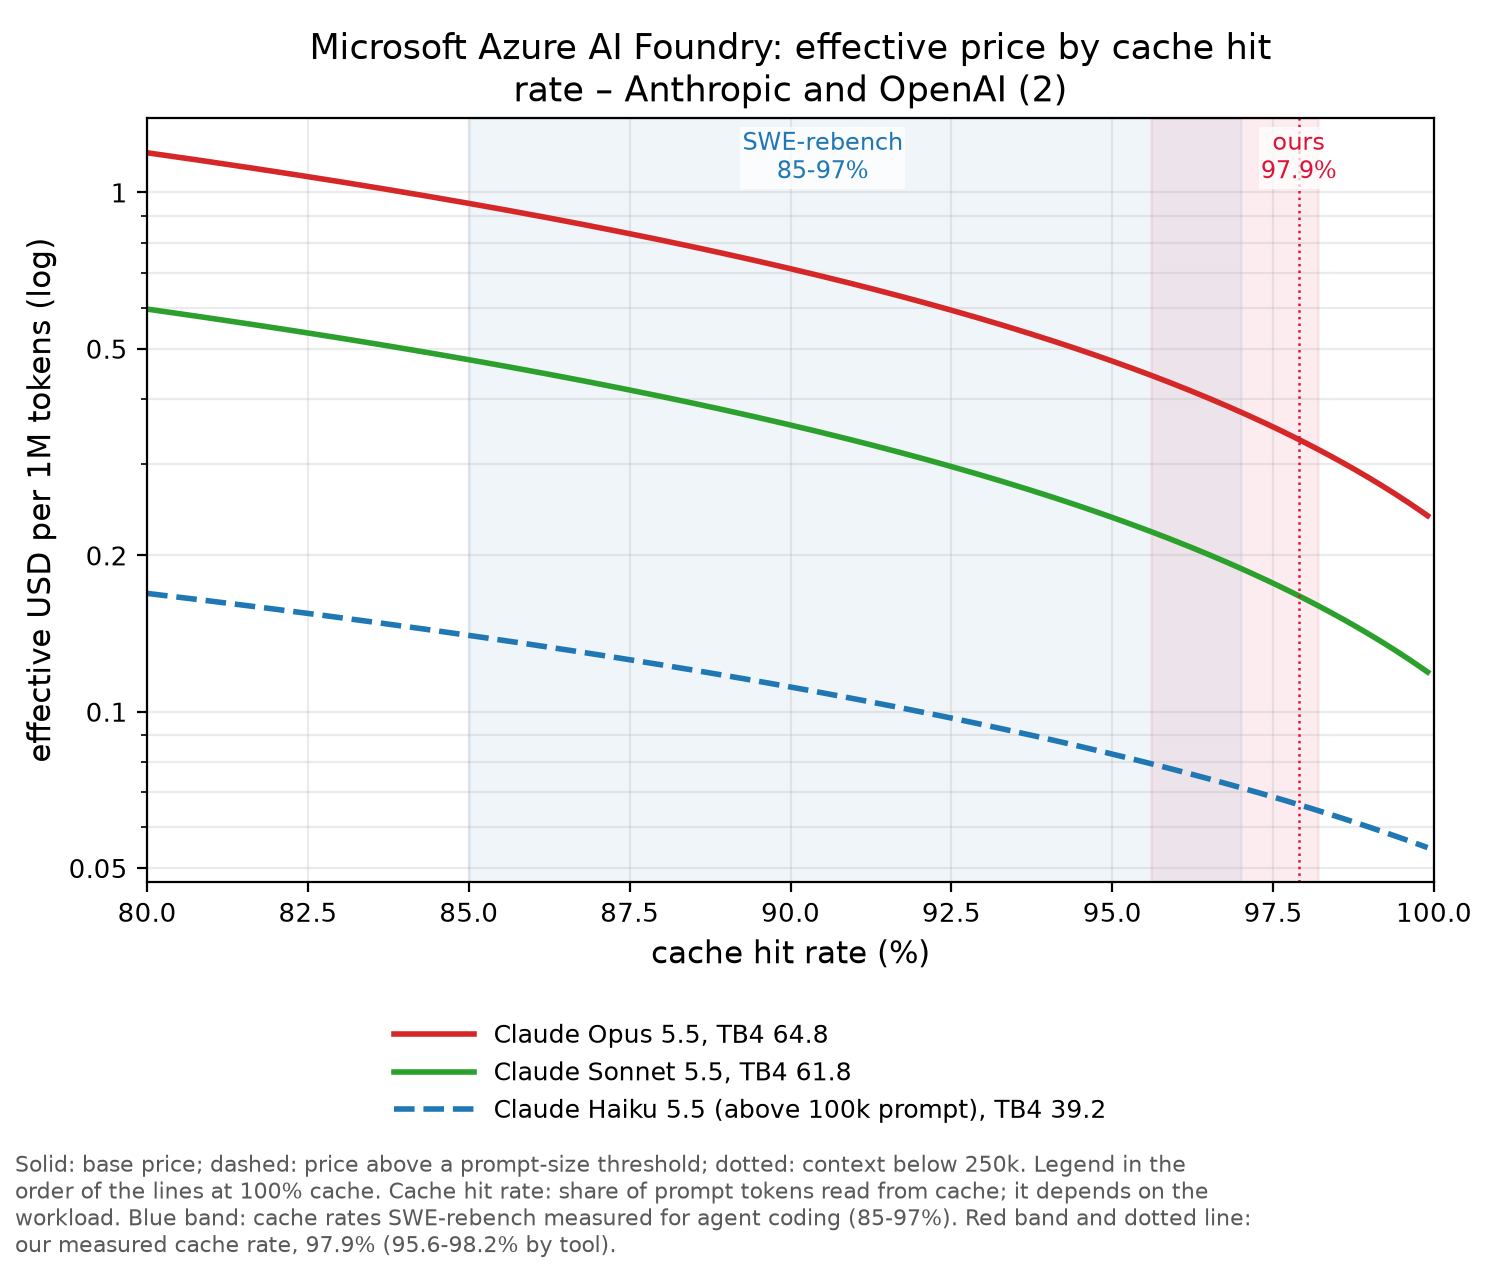
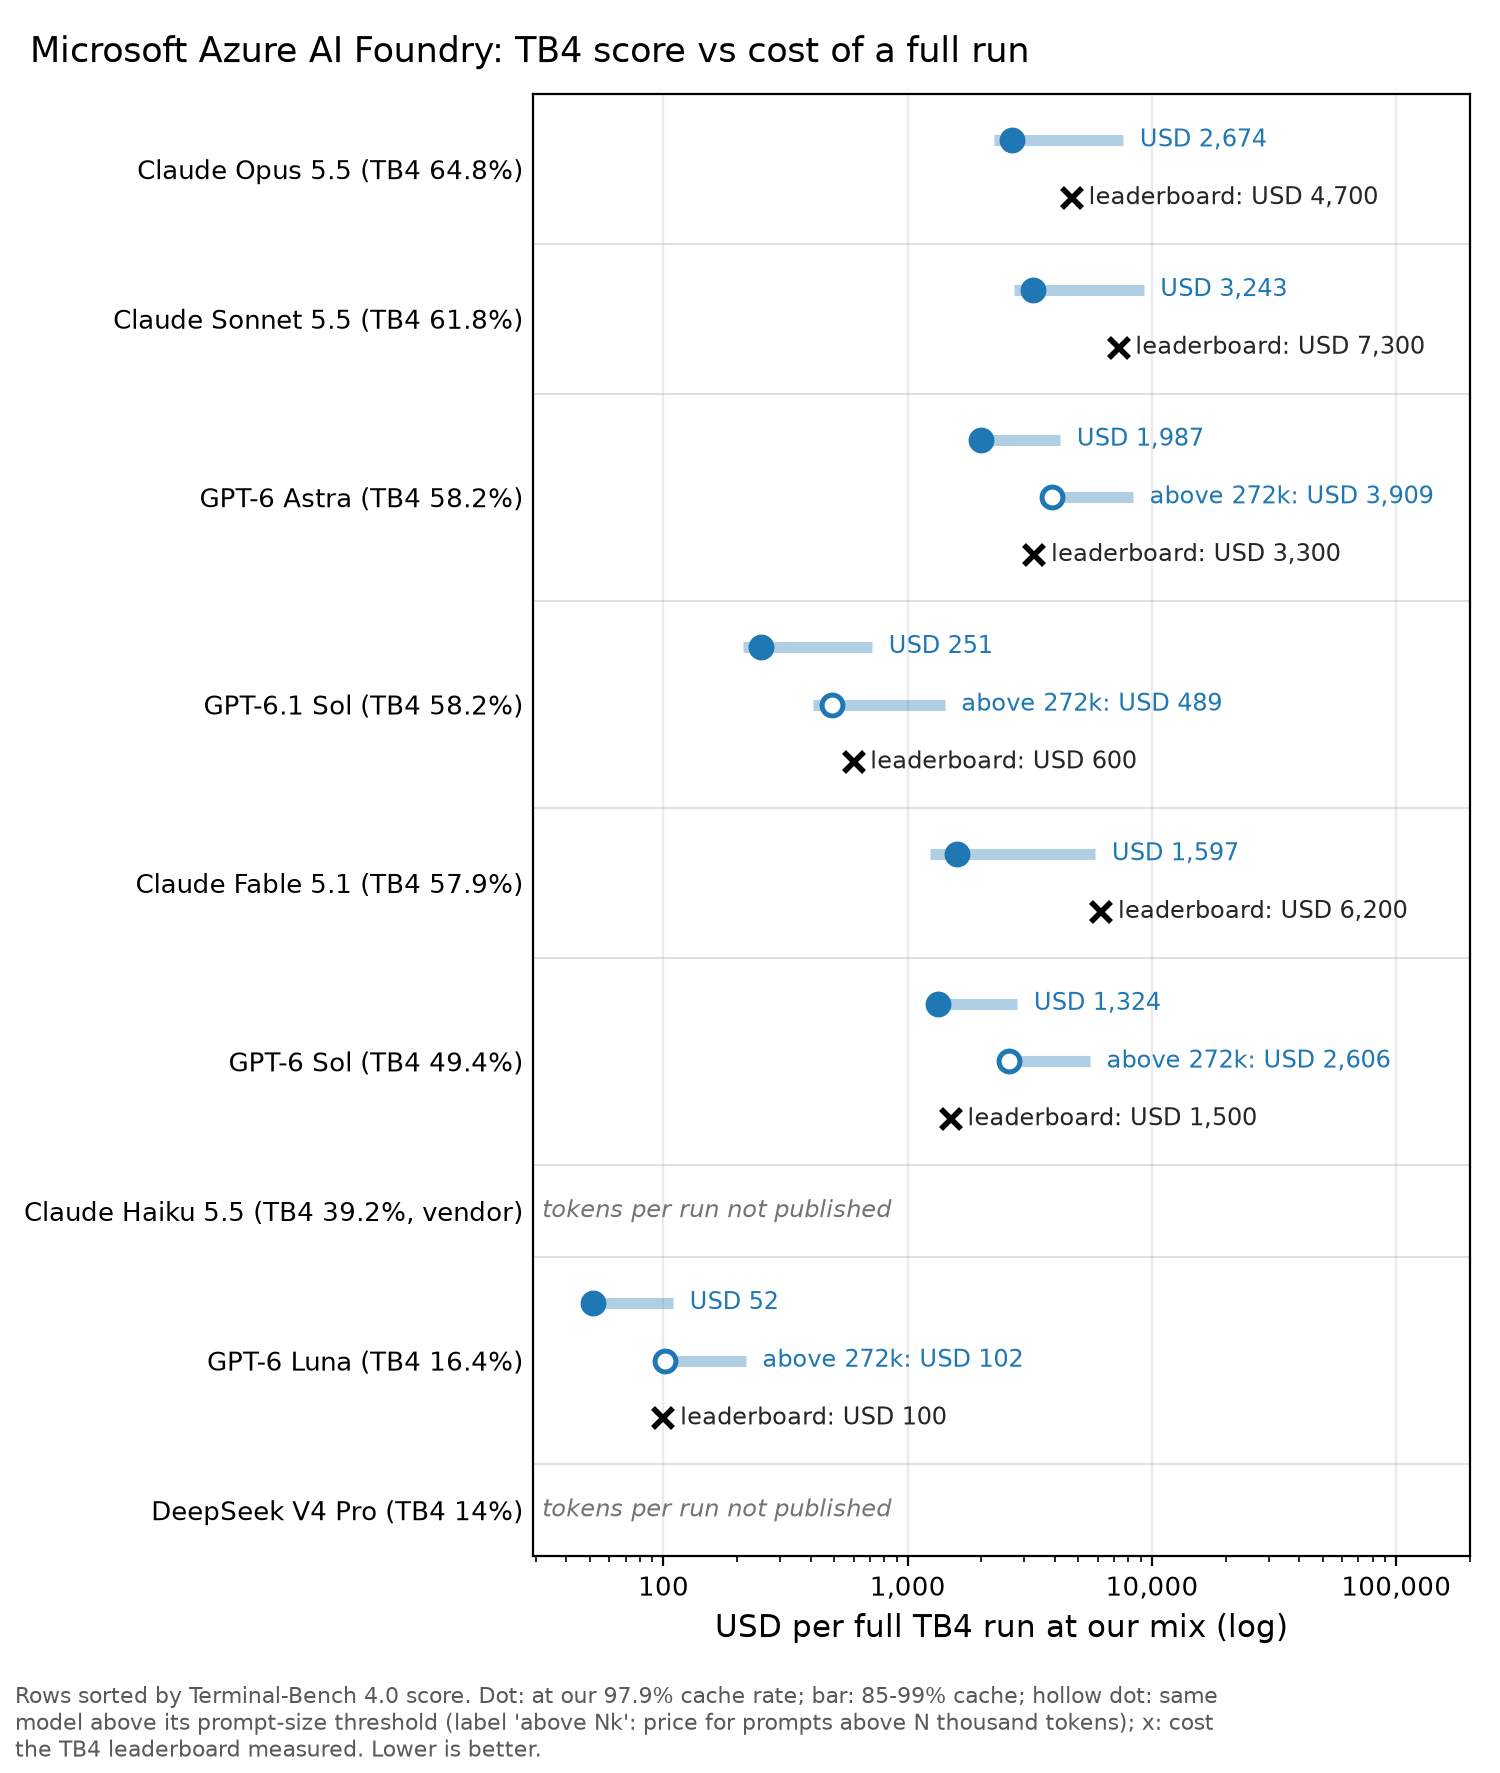
Fireworks
Fireworks AI, founded in California in 2022 by engineers from Meta's PyTorch team, does not train its own models: it runs open-weight models for other companies, with Cursor, Uber and Shopify among its named customers. It raised USD 1.5 billion at a USD 17.5 billion valuation in July 2026 and reported more than USD 1 billion in annualised revenue.
What to know:
- Maker prices, open models: GLM 5.3 (0.291), Kimi K3 (0.382) and MiniMax M3 (0.067) match the makers at our mix. You pay for serving quality, not a discount.
- Cache needs affinity: The cache is per replica with a default 50% discount; send the x-session-affinity header to keep agent sessions on one replica.
- US region surcharge: US-region serving costs 1.5x; batch halves the price.
- DeepSeek costs more: DeepSeek V4.1 Flash costs USD 0.014 per 1M here against 0.0071 at DeepSeek.
- Startup credits: Fireworks for Startups gives credits per application; the amount is not in sources.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| GLM 5.3 Fast · open · TB4 41.8% | 2.1 / 0.39 / 6.6 | 1M | 0.436 | USD 3,797 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.006 / 1.2 | 1M | 0.014 | – |
| Qwen 3.8 Max · TB4 27% | 2 / 0.25 / 6 | 262k | 0.296 | USD 889 |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | 1M | 0.382 | – |
| Kimi K3 Fast · open · TB4 12.6% | 4.5 / 0.45 / 22.5 | 1M | 0.572 | – |
| MiniMax M3 · open · TB4 2% | 0.3 / 0.06 / 1.2 | 512k | 0.067 | – |
| GLM 5.2 · open | 1.4 / 0.14 / 4.4 | – | 0.174 | – |
| gpt-oss-120b · open | 0.15 / 0.015 / 0.6 | 131k (below 250k) | 0.019 | – |
| Muse Spark Open · open | 1.25 / – / 4.25 | 1M | 1.255 | – |
| Nemotron 3 Ultra · open | 0.6 / 0.12 / 2.4 | 262k | 0.134 | – |
-
Other tiers, GLM 5.3: Fast/priority: 1.25x; Batch: 0.5x; US region: 1.5x; US region, batch: 0.75x; US region, fast/priority: 1.88x; Fast: 1.5x.
-
Other tiers, GLM 5.3 Flash: Batch: 0.5x; Fast/priority: 1.25x; US region: 1.5x; US region, batch: 0.75x; US region, fast/priority: 1.88x.
-
Other tiers, DeepSeek V4.1 Flash: Batch: 0.5x; Fast/priority: 1.25x; US region: 1.5x; US region, batch: 0.75x; US region, fast/priority: 1.88x.
-
Other tiers, Qwen 3.8 Max: Batch: 0.5x; Fast/priority: 1.5x.
-
Other tiers, Kimi K3: Fast/priority: 1.25x; Batch: 0.5x; Fast: 1.5x; US region: 1.5x; US region, batch: 0.75x; US region, fast/priority: 1.88x.
-
Other tiers, MiniMax M3: Batch: 0.5x; Fast/priority: 1.5x.
-
Other tiers, GLM 5.2: Fast/priority: 1.25x; Fast: 1.5x.
-
Caching (all priced models (size-priced models have no cached rate)): automatic; TTL not fixed; several minutes up to several hours, oldest evicted first; cached discount default 50%, varies by model (e.g. Kimi K3 $0.30 vs $3.00; GLM-5.2 Fast 90%); write fee not stated
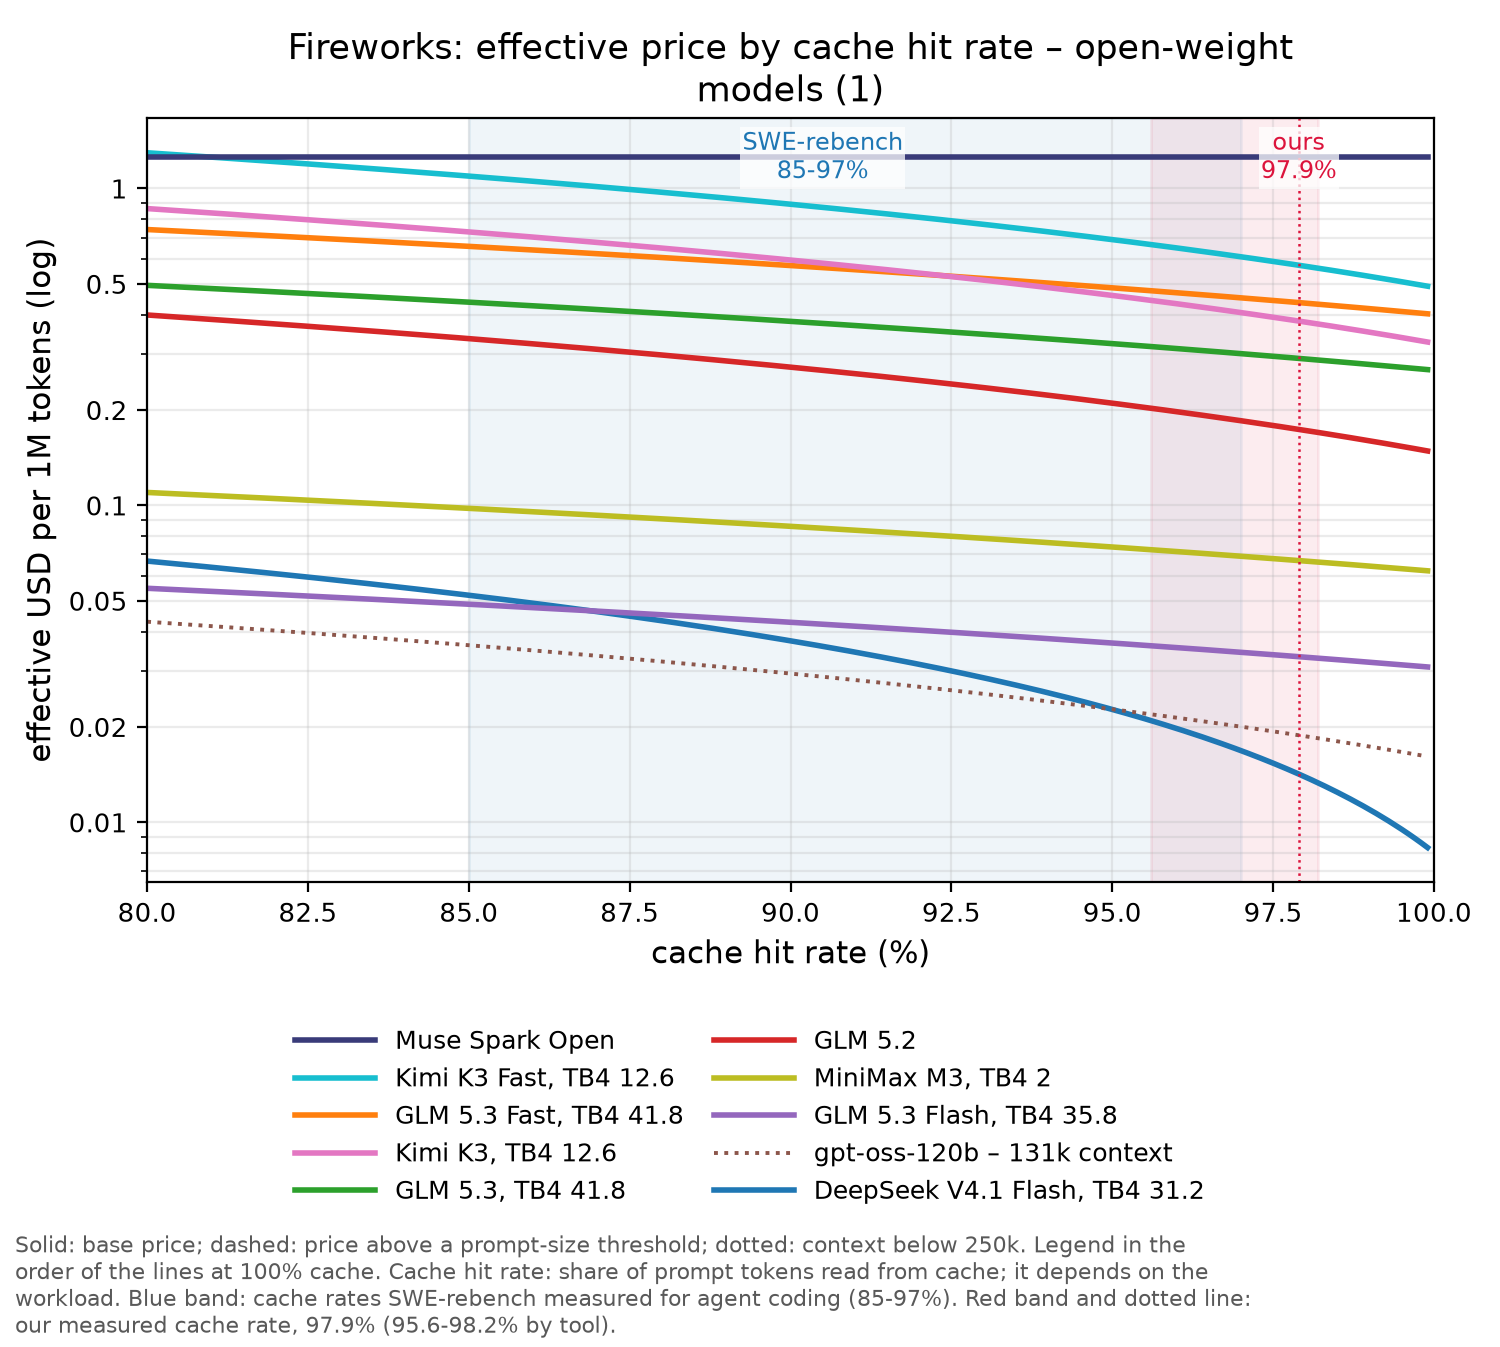
At our mix (97.9% cache) Nemotron 3 Ultra costs USD 0.13 per 1M tokens (USD 0.13 to 0.2 at 85-99% cache).
At our mix (97.9% cache) Qwen 3.8 Max costs USD 0.3 per 1M tokens (USD 0.28 to 0.52 at 85-99% cache).
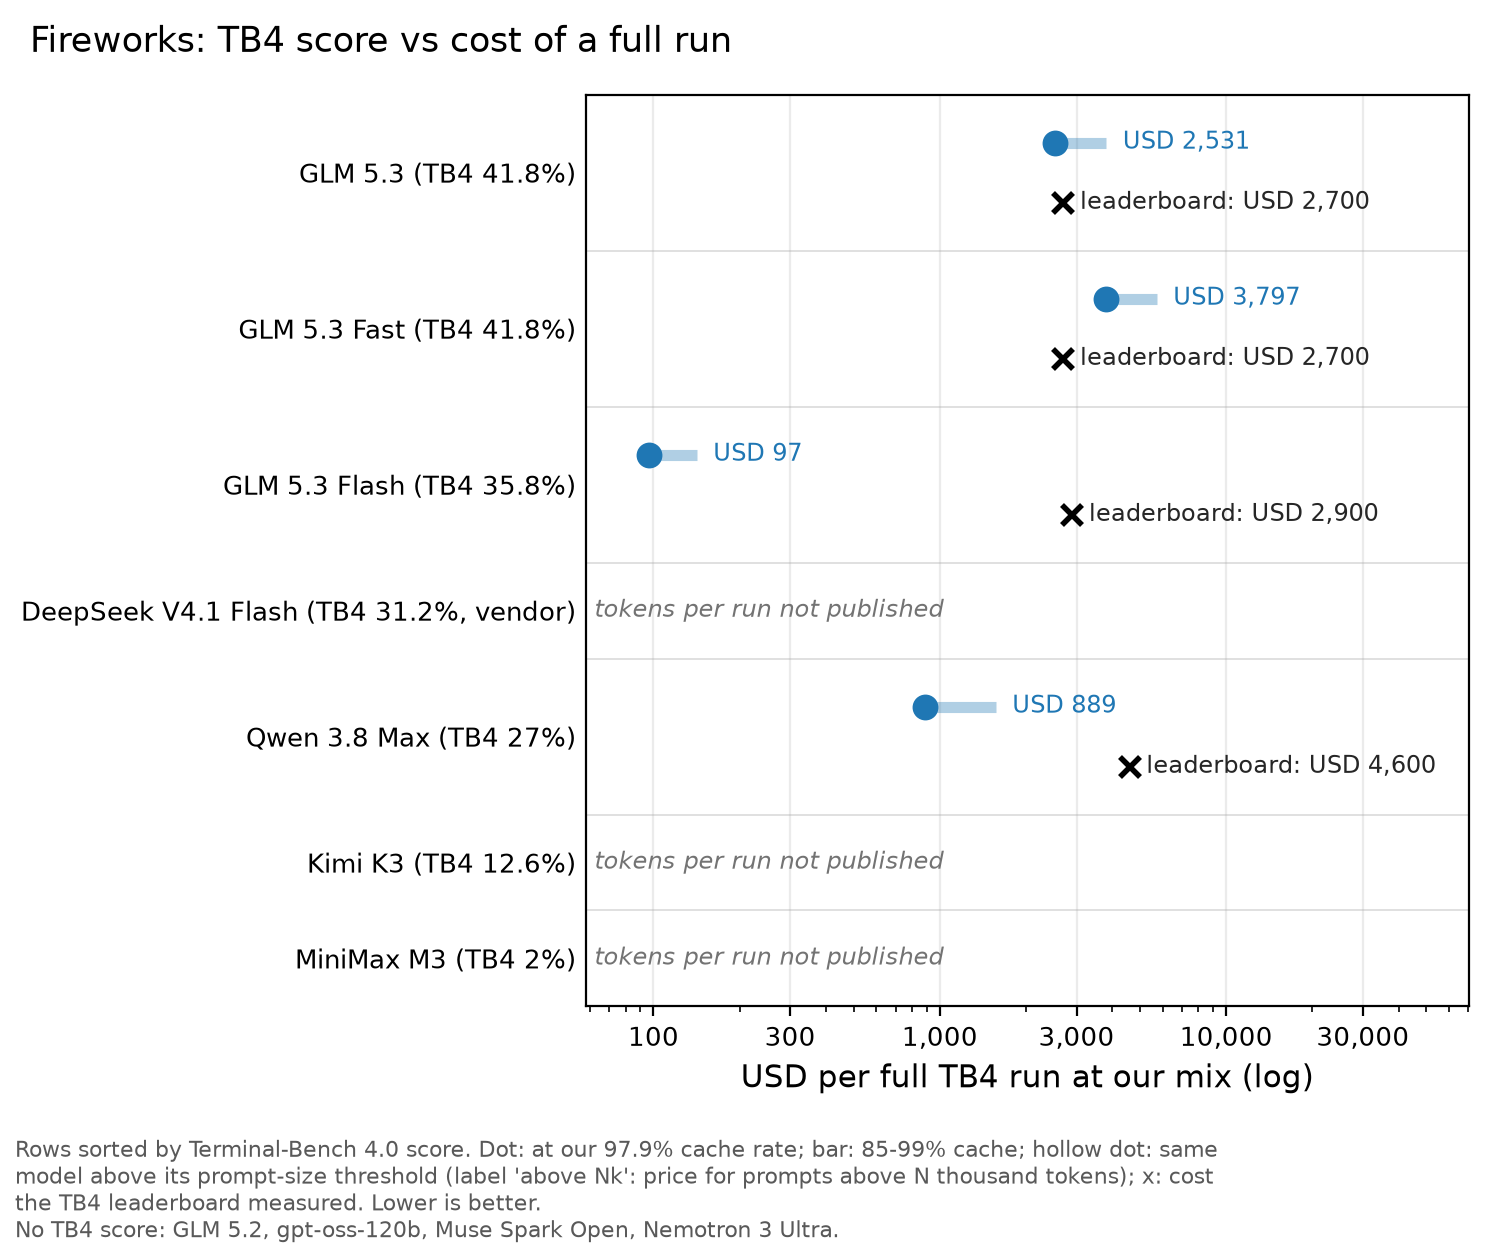
Together AI
Together AI is a San Francisco-based inference and GPU-cloud company founded in 2022. It runs serverless and dedicated inference for open-weight models such as DeepSeek, MiniMax and Kimi, and rents Nvidia GPU clusters. On 1 July 2026 it raised an $800 million Series C at an $8.3 billion valuation; TechCrunch reported the company's claim of annual bookings above $1.15 billion as of its last quarter.
What to know:
- Maker prices, quantised: GLM 5.3 costs Z.ai's 0.291 at our mix, but Together's own page lists it as fp4 (MiniMax M3 fp4, GLM 5.3 Flash fp8).
- Best-effort cache: No TTL; the cache is fleet-shared and evicted as traffic shifts, with an optional prompt_cache_key that improves odds without a guarantee. Cache writes are free.
- Avoid hosted DeepSeek: DeepSeek V4 Pro costs USD 0.161 per 1M here against 0.039 at DeepSeek.
- Reserved capacity: Provisioned throughput starts at USD 0.05 per unit per minute with a one-month minimum. The startup accelerator is selection-based.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.006 / 1.2 | 1M | 0.014 | – |
| DeepSeek V4 Pro · open · TB4 14% | 1.32 / 0.13 / 3.96 | 1M | 0.161 | – |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | 1M | 0.382 | – |
| MiniMax M3 · open · TB4 2% | 0.3 / 0.06 / 1.2 | 524k | 0.067 | – |
| GLM 5.2 · open | 1.4 / 0.26 / 4.4 | 1M | 0.291 | – |
| gpt-oss-120b · open | 0.15 / – / 0.6 | 131k (below 250k) | 0.151 | – |
| Muse Spark Open · open | 1.25 / 0.15 / 4.25 | 1M | 0.180 | – |
| Nemotron 3 Ultra · open | 0.6 / 0.2 / 3.6 | 512k | 0.214 | – |
| Qwen 3.8 2.4T (open) · open | 2 / 0.25 / 6 | 1M | 0.296 | – |
| Qwen 3.8 Flash · open | 0.09 / – / 0.28 | 1M | 0.090 | – |
- Caching (models with a cached input price): automatic; TTL no TTL; best-effort, fleet-shared, evicted as traffic shifts; cached discount per-model cached price, no single % (e.g. GLM-5.1 81%, Qwen3.5-397B 42%); write fee none
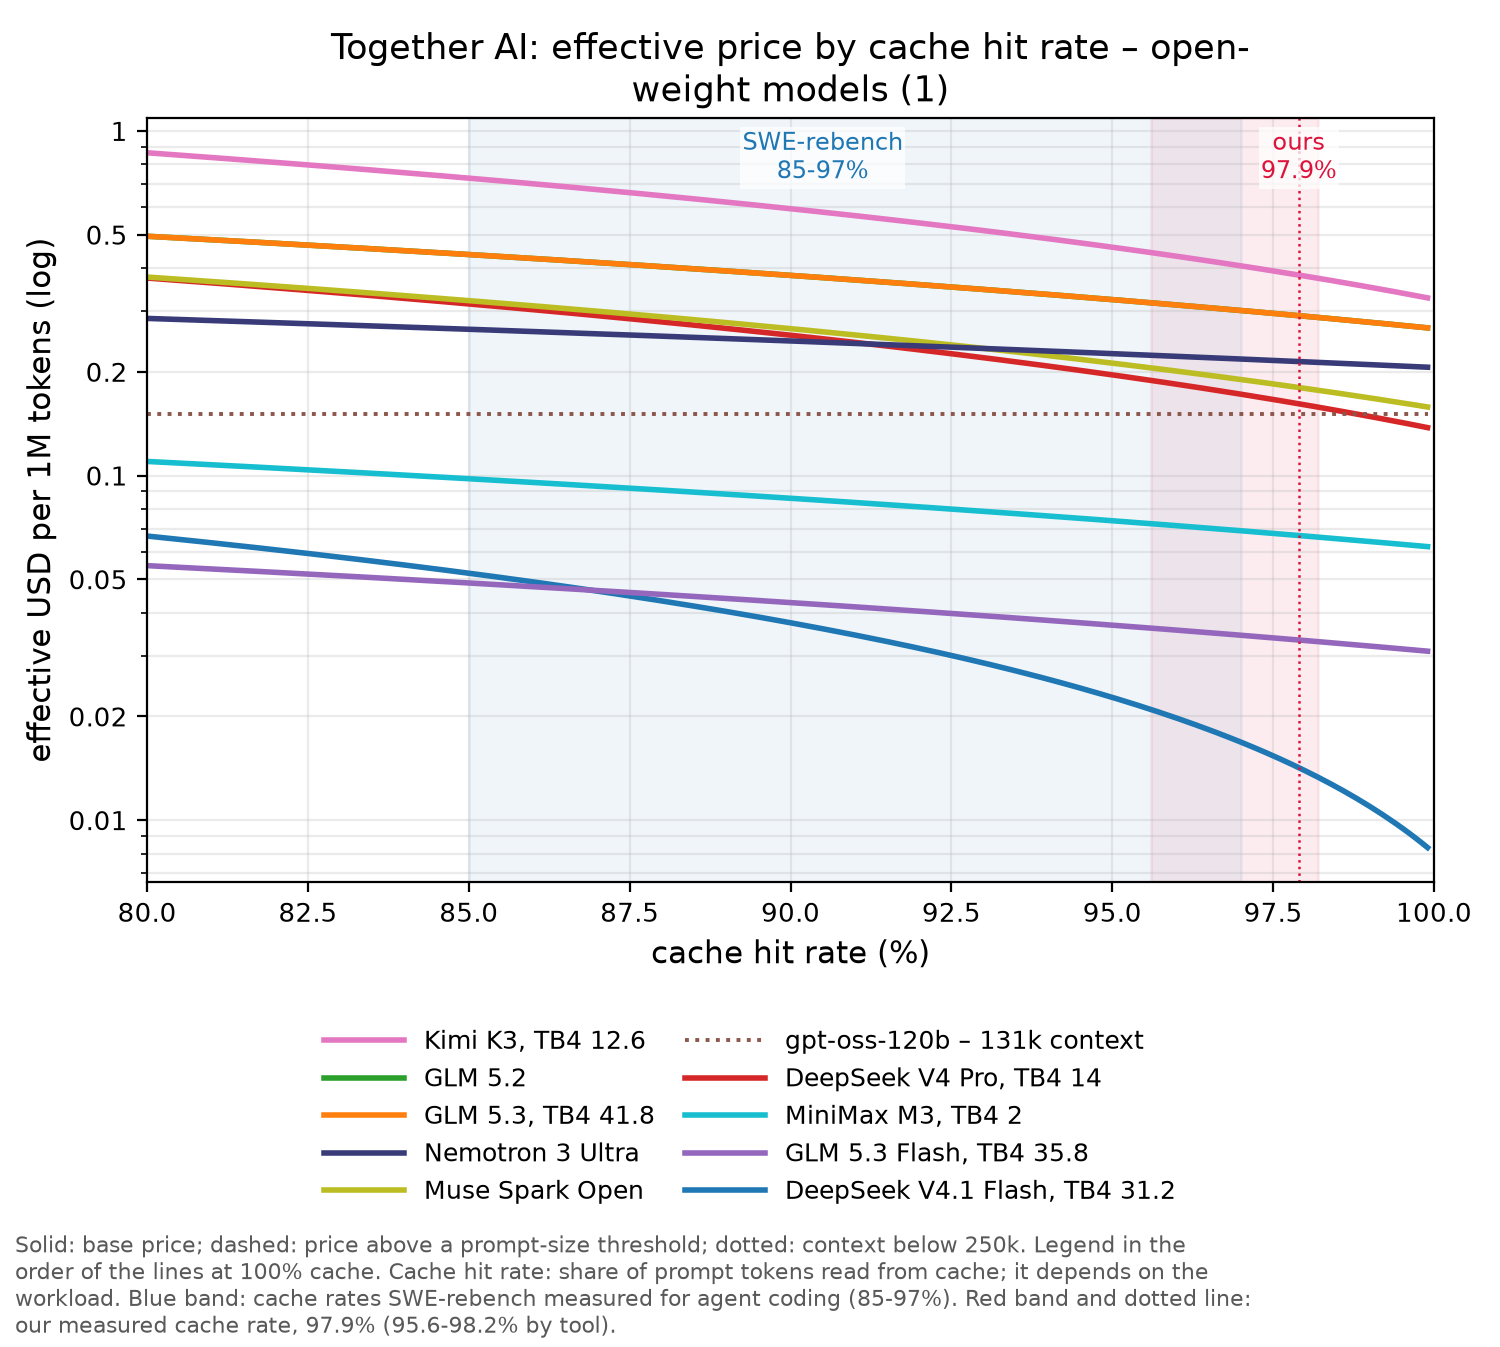
At our mix (97.9% cache) Qwen 3.8 2.4T (open) costs USD 0.3 per 1M tokens (USD 0.28 to 0.52 at 85-99% cache). At our mix (97.9% cache) Qwen 3.8 Flash costs USD 0.09 per 1M tokens (USD 0.09 to 0.09 at 85-99% cache).
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 2,531; the TB4 leaderboard measured USD 2,700. At our mix a full Terminal-Bench 4.0 run of GLM 5.3 Flash (TB4 35.8%) costs USD 97; the TB4 leaderboard measured USD 2,900.
Baseten
Baseten is a San Francisco-based inference company founded in 2019. It sells Model APIs for open-weight models, dedicated deployments and post-training of custom models, running across 87 clusters on 18 clouds. On 22 June 2026 it raised a $1.5 billion Series F at a $13 billion valuation and said its revenue had grown about 20-fold year on year.
What to know:
- Verified cheap GLM 5.3: Baseten's own page confirms 1.40 / 0.14 / 4.40, so GLM 5.3 costs USD 0.174 per 1M at our mix against Z.ai's 0.291.
- Quantisation flag: OpenRouter lists Baseten's GLM 5.3 endpoint as fp4. Test on your own tasks.
- Avoid DeepSeek here: No cached price, so DeepSeek V4 Pro costs USD 1.324 per 1M at our mix against 0.039 at DeepSeek.
- Check context: gpt-oss-120b (128k) and Nemotron 3 Ultra (203k) fall below the 250k floor.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.14 / 4.4 | 1M | 0.174 | USD 1,511 |
| GLM 5.3 Fast · open · TB4 41.8% | 2.1 / 0.21 / 6.6 | 1M | 0.260 | USD 2,266 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.007 / 1.2 | 1M | 0.015 | – |
| DeepSeek V4 Pro · open · TB4 14% | 1.32 / – / 3.96 | 1M | 1.324 | – |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | 1M | 0.382 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.95 / 0.16 / 4 | 262k | 0.183 | – |
| GLM 5.2 · open | 1.4 / 0.14 / 4.4 | 1M | 0.174 | – |
| gpt-oss-120b · open | 0.1 / 0.1 / 0.5 | 128k (below 250k) | 0.101 | – |
| Muse Spark Open · open | 1.25 / 0.15 / 4.25 | 1M | 0.180 | – |
| Nemotron 3 Ultra · open | 0.6 / 0.12 / 2.4 | 203k (below 250k) | 0.134 | – |
-
Other tiers, GLM 5.3: Fast/priority: 1.5x.
-
Other tiers, DeepSeek V4.1 Flash: Fast/priority: 2x.
-
Other tiers, GLM 5.2: Fast/priority: 1.5x.
-
Caching (Model APIs): automatic; TTL not stated; cached discount per-model cache input price, no % (e.g. Kimi K2.6 $0.16 vs $0.95); write fee not stated
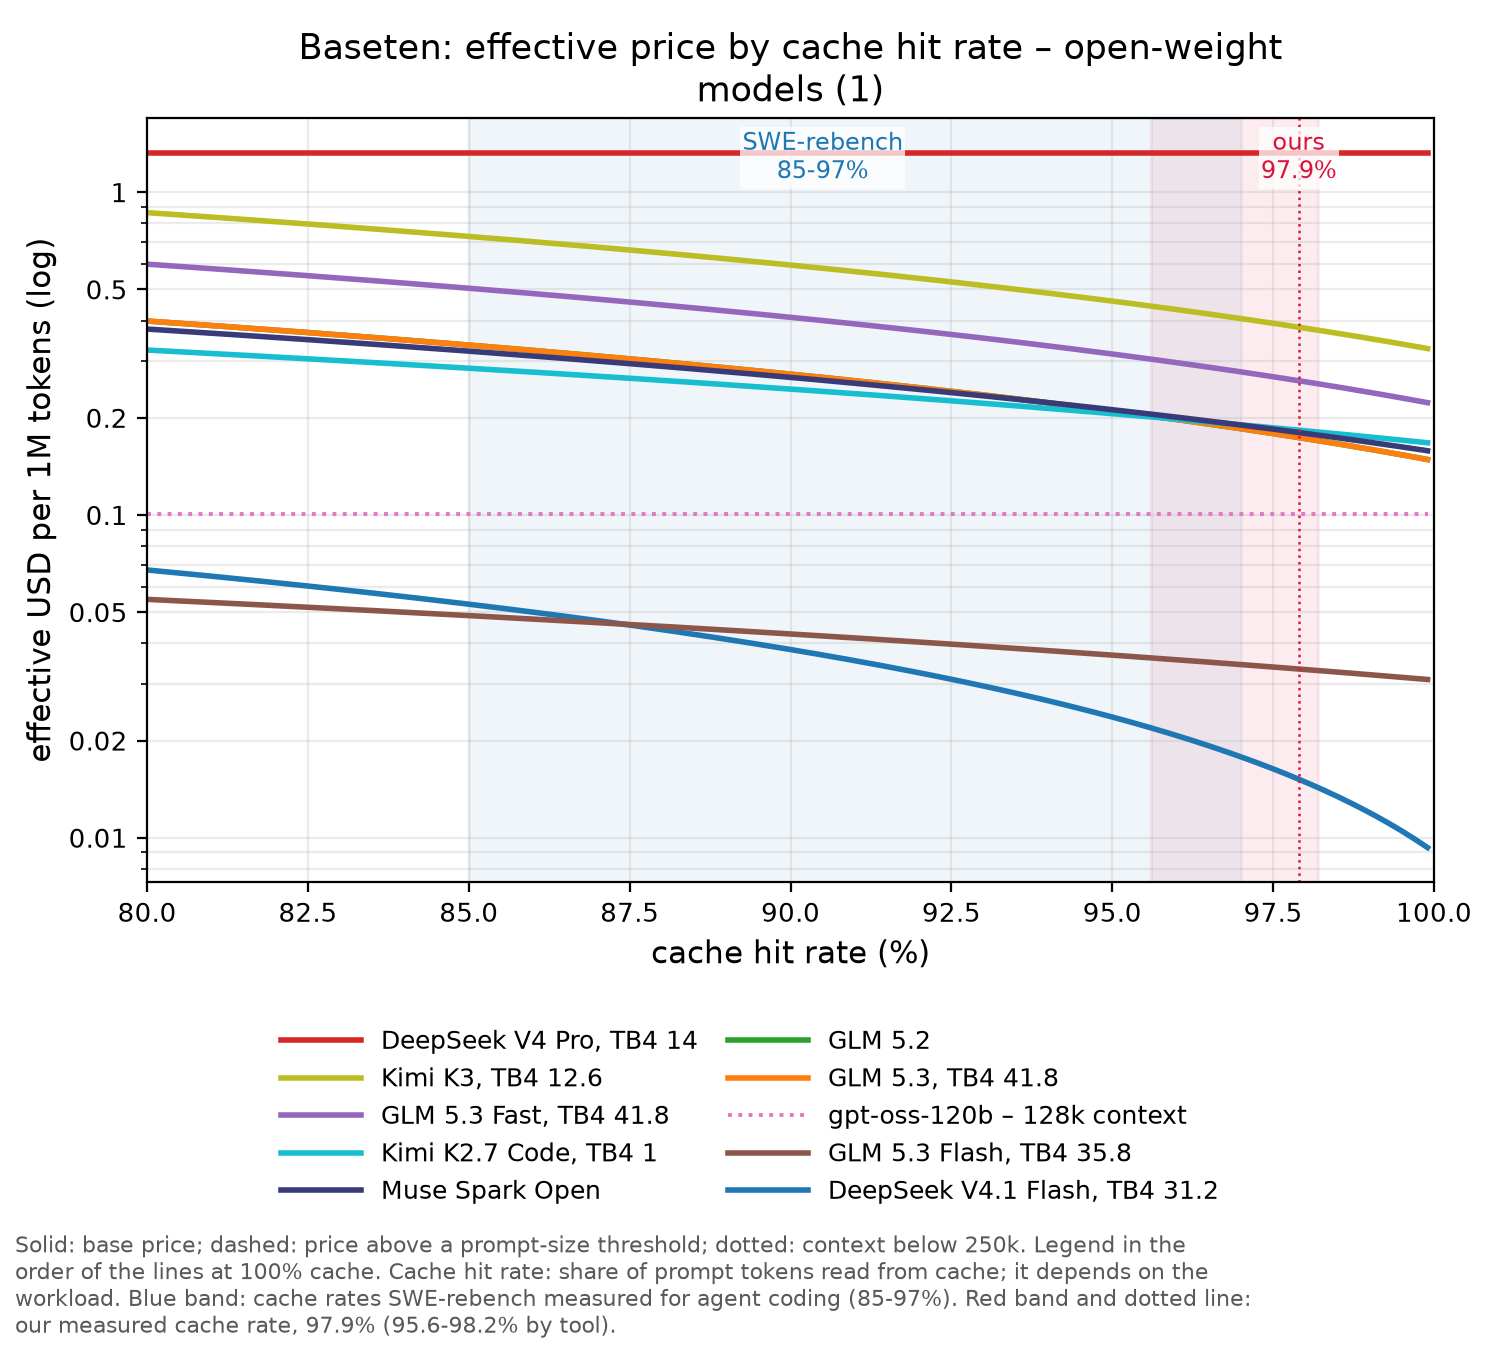
At our mix (97.9% cache) Nemotron 3 Ultra – 203k context costs USD 0.13 per 1M tokens (USD 0.13 to 0.2 at 85-99% cache).
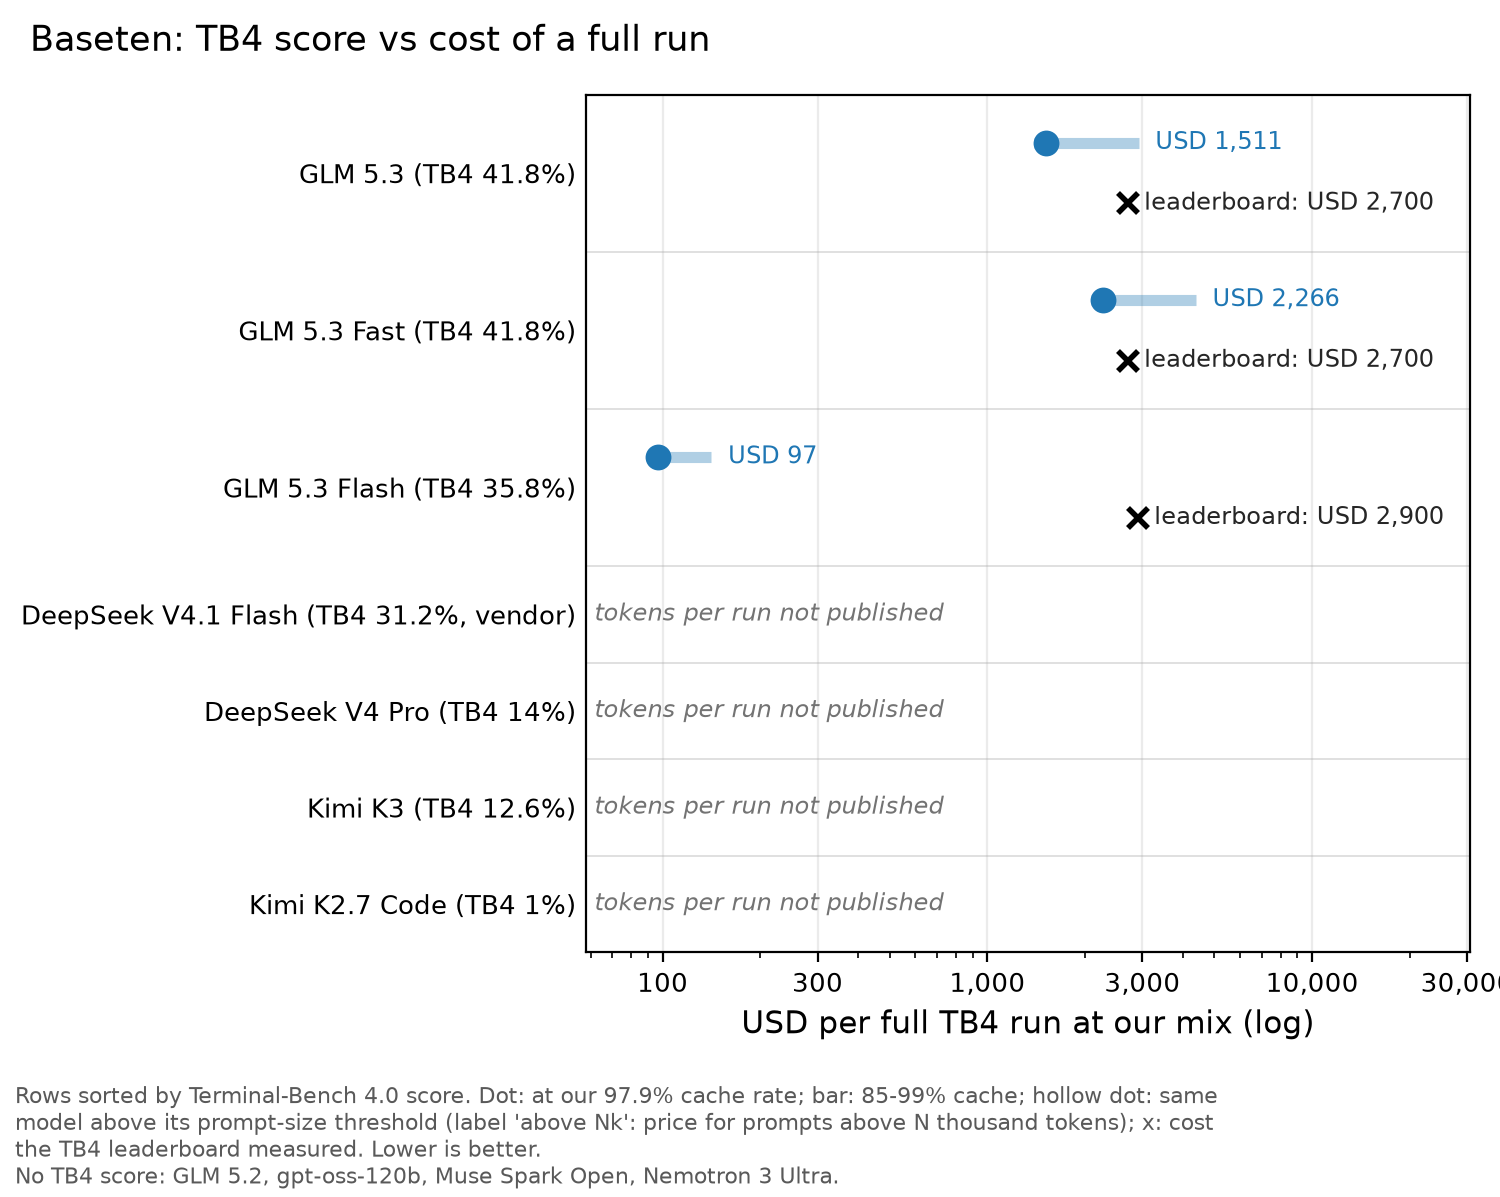
Novita AI
Novita AI is a San Francisco-based cloud provider that serves more than 200 open-weight models, including DeepSeek, Kimi, GLM, MiniMax and MiMo, through a serverless per-token interface, alongside GPU instances and an agent sandbox.
What to know:
- Maker prices, quantised: GLM 5.3 costs Z.ai's 0.291 at our mix; OpenRouter lists it as fp8 and Kimi K2.7 Code as int4.
- Longer M3 context: MiniMax M3 runs at 1M context here against 524k at MiniMax, at the same 0.067 per 1M up to 524k.
- Full-price cache writes: Writes bill at the input price, so short sessions cost more than at hosters with free writes.
- DeepSeek costs more: DeepSeek V4 Pro costs 0.077 per 1M against 0.039 at DeepSeek.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| MiMo V2.6 Pro · open · TB4 34.8% | 0.43 / 0.0036 / 0.87 | 1M | 0.014 | – |
| Step 5 Preview · open · TB4 33.3% | 1 / 0.1 / 2.7 | 977k | 0.123 | – |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.006 / 1.2 | 1M | 0.014 | – |
| MiMo V2.6 Flash · open · TB4 28.8% (vendor) | 0.14 / 0.0028 / 0.28 | 1M | 0.006 | – |
| Qwen 3.8 Max · TB4 27% | 2 / 0.25 / 6 | 977k | 0.296 | USD 889 |
| DeepSeek V4 Pro · open · TB4 14% | 1.32 / 0.044 / 3.96 | 1M | 0.077 | – |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | 1M | 0.382 | – |
| MiniMax M3 · open · TB4 2% | 0.3 / 0.06 / 1.2 | 1M | 0.067 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.95 / 0.19 / 4 | 256k | 0.212 | – |
| GLM 5.2 · open | 1.4 / 0.26 / 4.4 | 1M | 0.291 | – |
| gpt-oss-120b · open | 0.05 / – / 0.25 | 131k (below 250k) | 0.050 | – |
| Qwen 3.8 2.4T (open) · open | 2 / 0.25 / 6 | 1M | 0.296 | – |
| Qwen 3.8 27B · open | 0.42 / 0.085 / 3 | 977k | 0.097 | – |
| Qwen 3.8 Flash · open | 0.15 / 0.016 / 0.47 | 977k | 0.020 | – |
-
Other tiers, MiniMax M3: above 524k prompt: 0.6 / 0.12 / 2.4.
-
Caching (several serverless models (list not captured)): automatic; TTL not stated; cached discount about 1/10 of input, varies by model (e.g. GLM 5.3 $0.26 vs $1.40); write fee full input price
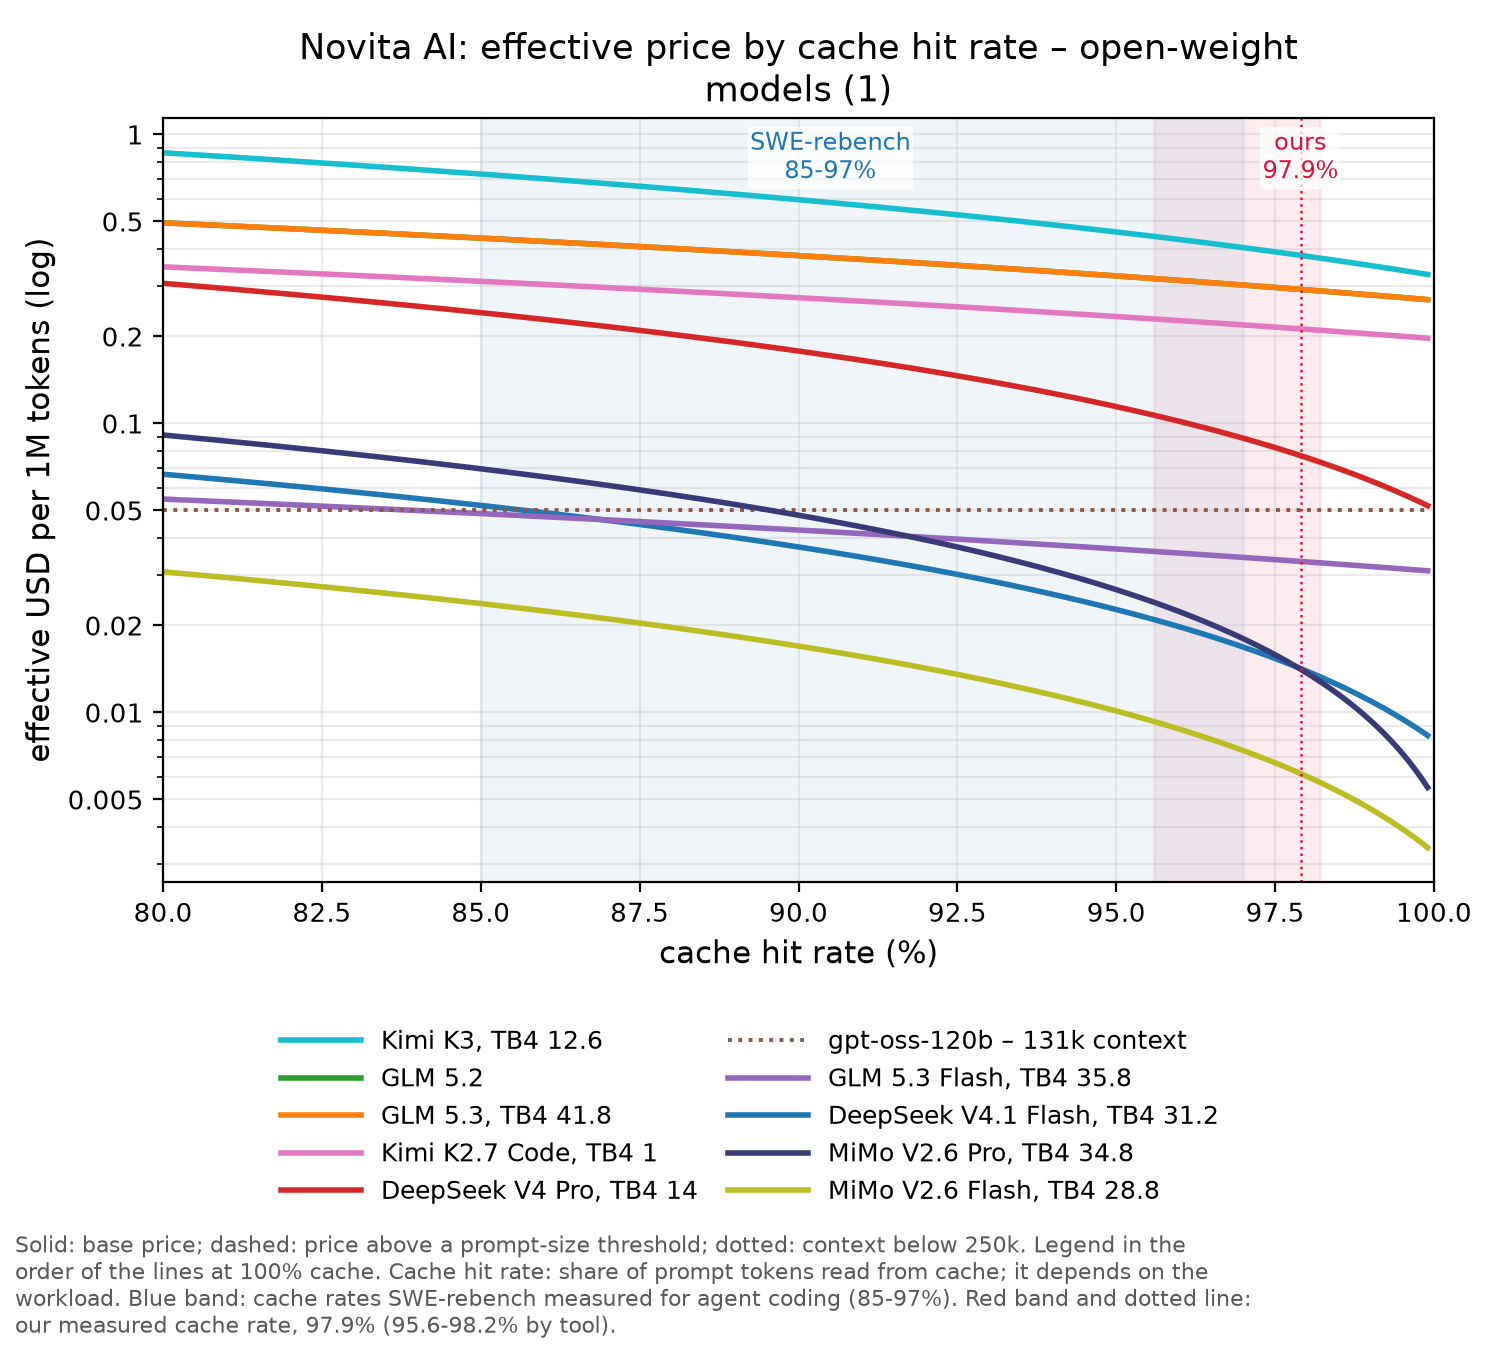
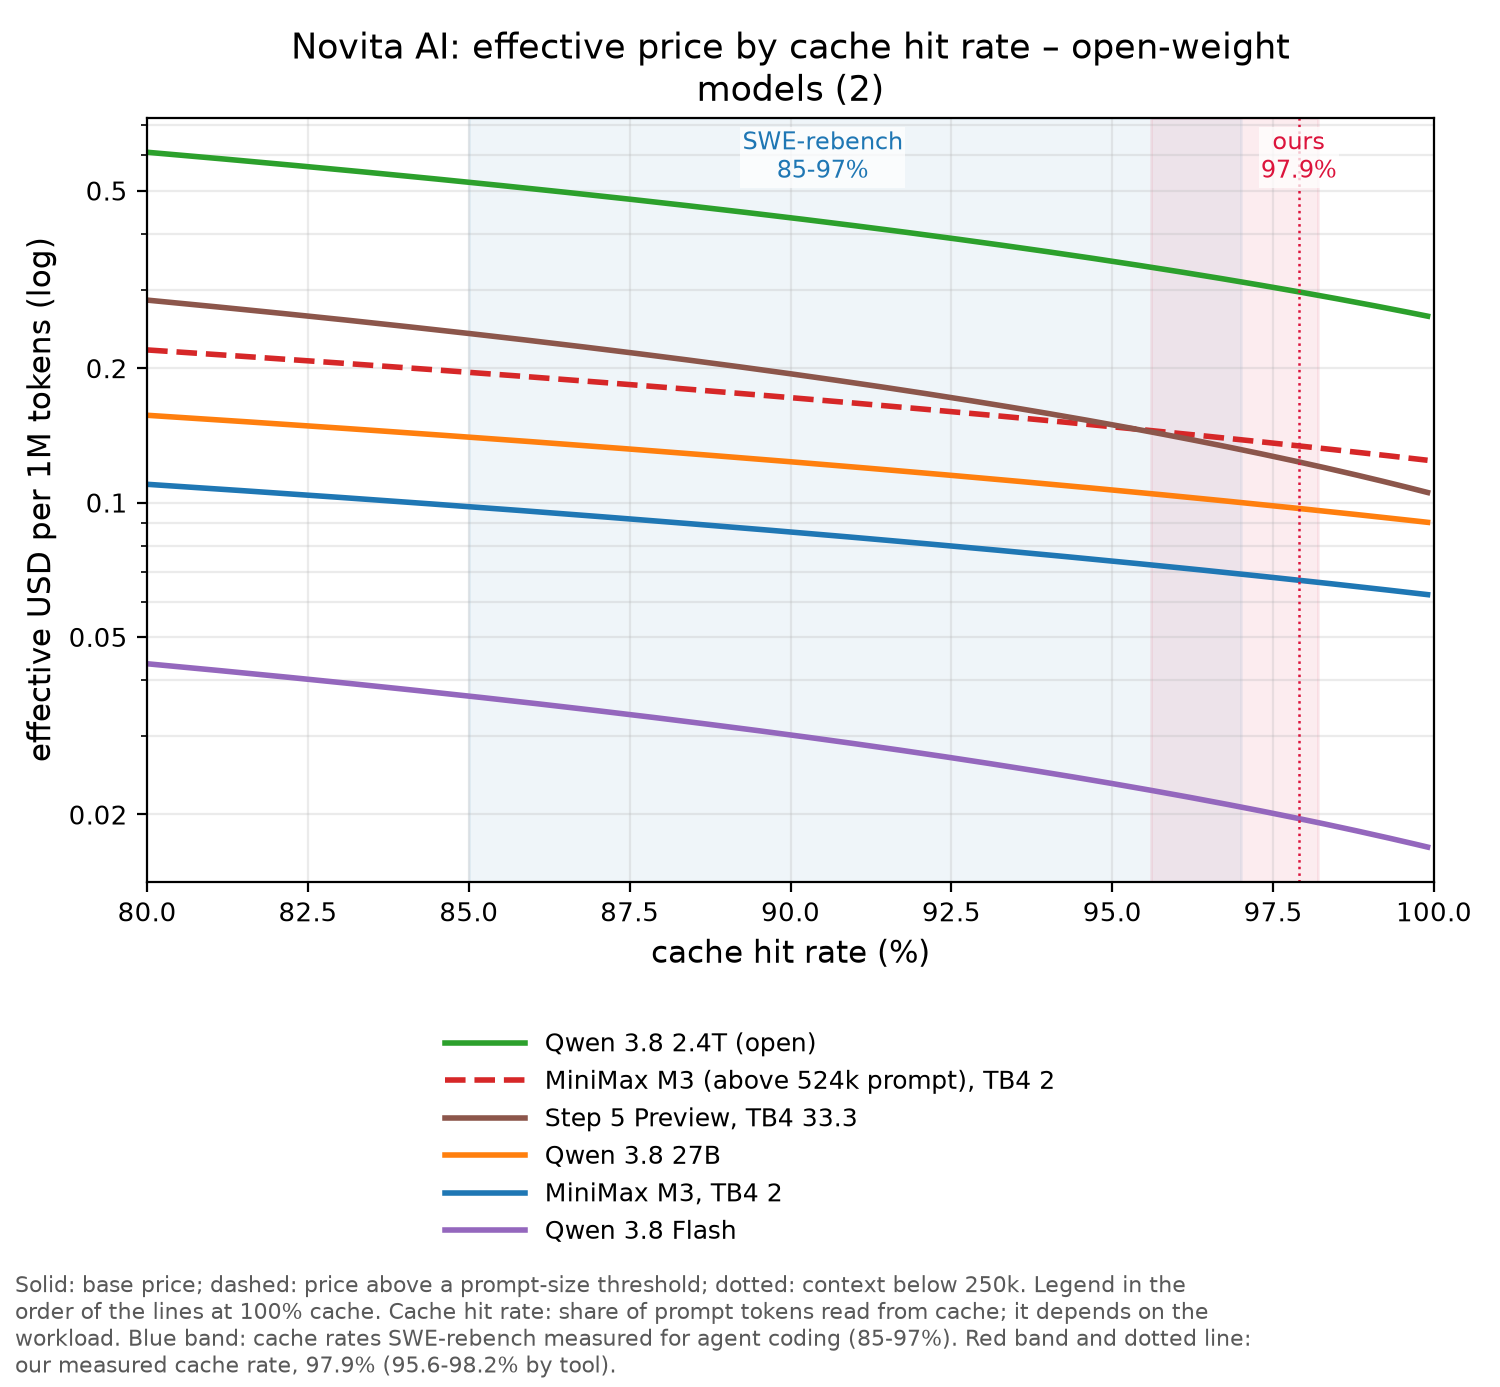
At our mix (97.9% cache) Qwen 3.8 Max costs USD 0.3 per 1M tokens (USD 0.28 to 0.52 at 85-99% cache).
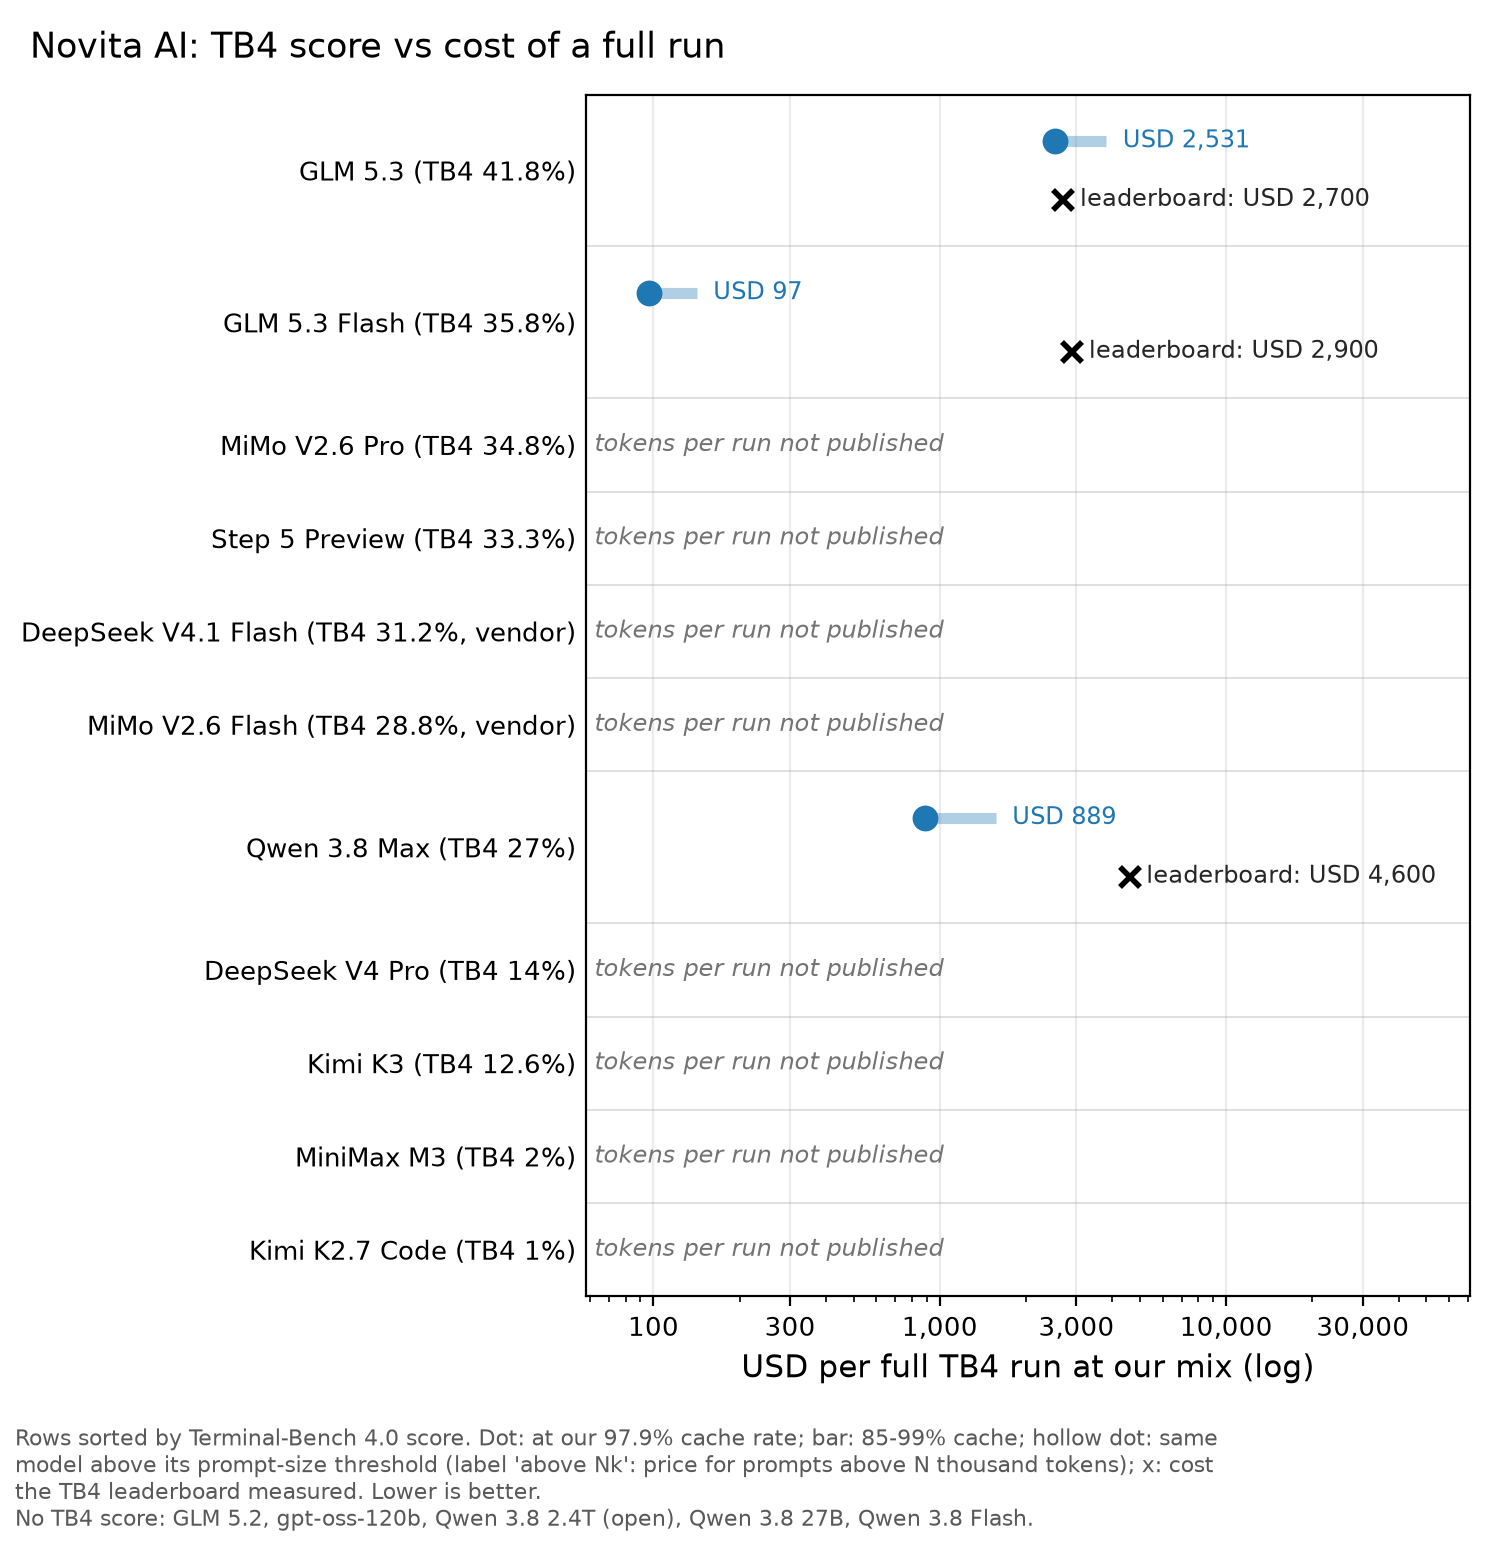
SiliconFlow
SiliconFlow is a Beijing-based inference company founded in 2023 that sells serverless per-token access, dedicated instances and on-premise deployment for open-weight models; its model platform launched in May 2024. It reported more than 10 million registered users as of 30 April 2026, filed for a Hong Kong listing on 30 June 2026, and raised nearly 2.9 billion yuan in 2026.
What to know:
- DeepSeek at maker price: DeepSeek V4.1 Flash costs USD 0.0071 per 1M at our mix, the same as DeepSeek, with 1M context.
- Slightly cheaper Kimi K3: K3 costs 0.343 against Moonshot's 0.382, from SiliconFlow's own price page.
- Avoid MiniMax M3 here: No cached price, so M3 costs 0.302 per 1M at our mix against MiniMax's 0.067.
- Quantisation flag: OpenRouter lists its GLM 5.3, GLM 5.3 Flash and DeepSeek V4.1 Flash endpoints as fp8.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.15 / 0.003 / 0.6 | 1M | 0.007 | – |
| DeepSeek V4 Pro · open · TB4 14% | 1.32 / 0.044 / 3.96 | 1M | 0.077 | – |
| Kimi K3 · open · TB4 12.6% | 2.7 / 0.27 / 13.5 | 1M | 0.343 | – |
| MiniMax M3 · open · TB4 2% | 0.3 / – / 1.2 | 1M | 0.302 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.86 / 0.1799 / 3.8 | 262k | 0.200 | – |
| GLM 5.2 · open | 1.3 / 0.26 / 4.09 | 1M | 0.288 | – |
| gpt-oss-120b · open | 0.05 / 0.075 / 0.45 | 131k (below 250k) | 0.075 | – |
| Qwen 3.8 2.4T (open) · open | 2 / 0.25 / 6 | 1M | 0.296 | – |
- Caching (supported models (not listed)): not stated; TTL not stated; cached discount model-specific cache read price (e.g. GLM 5.3 $0.26 vs $1.40); write fee not stated
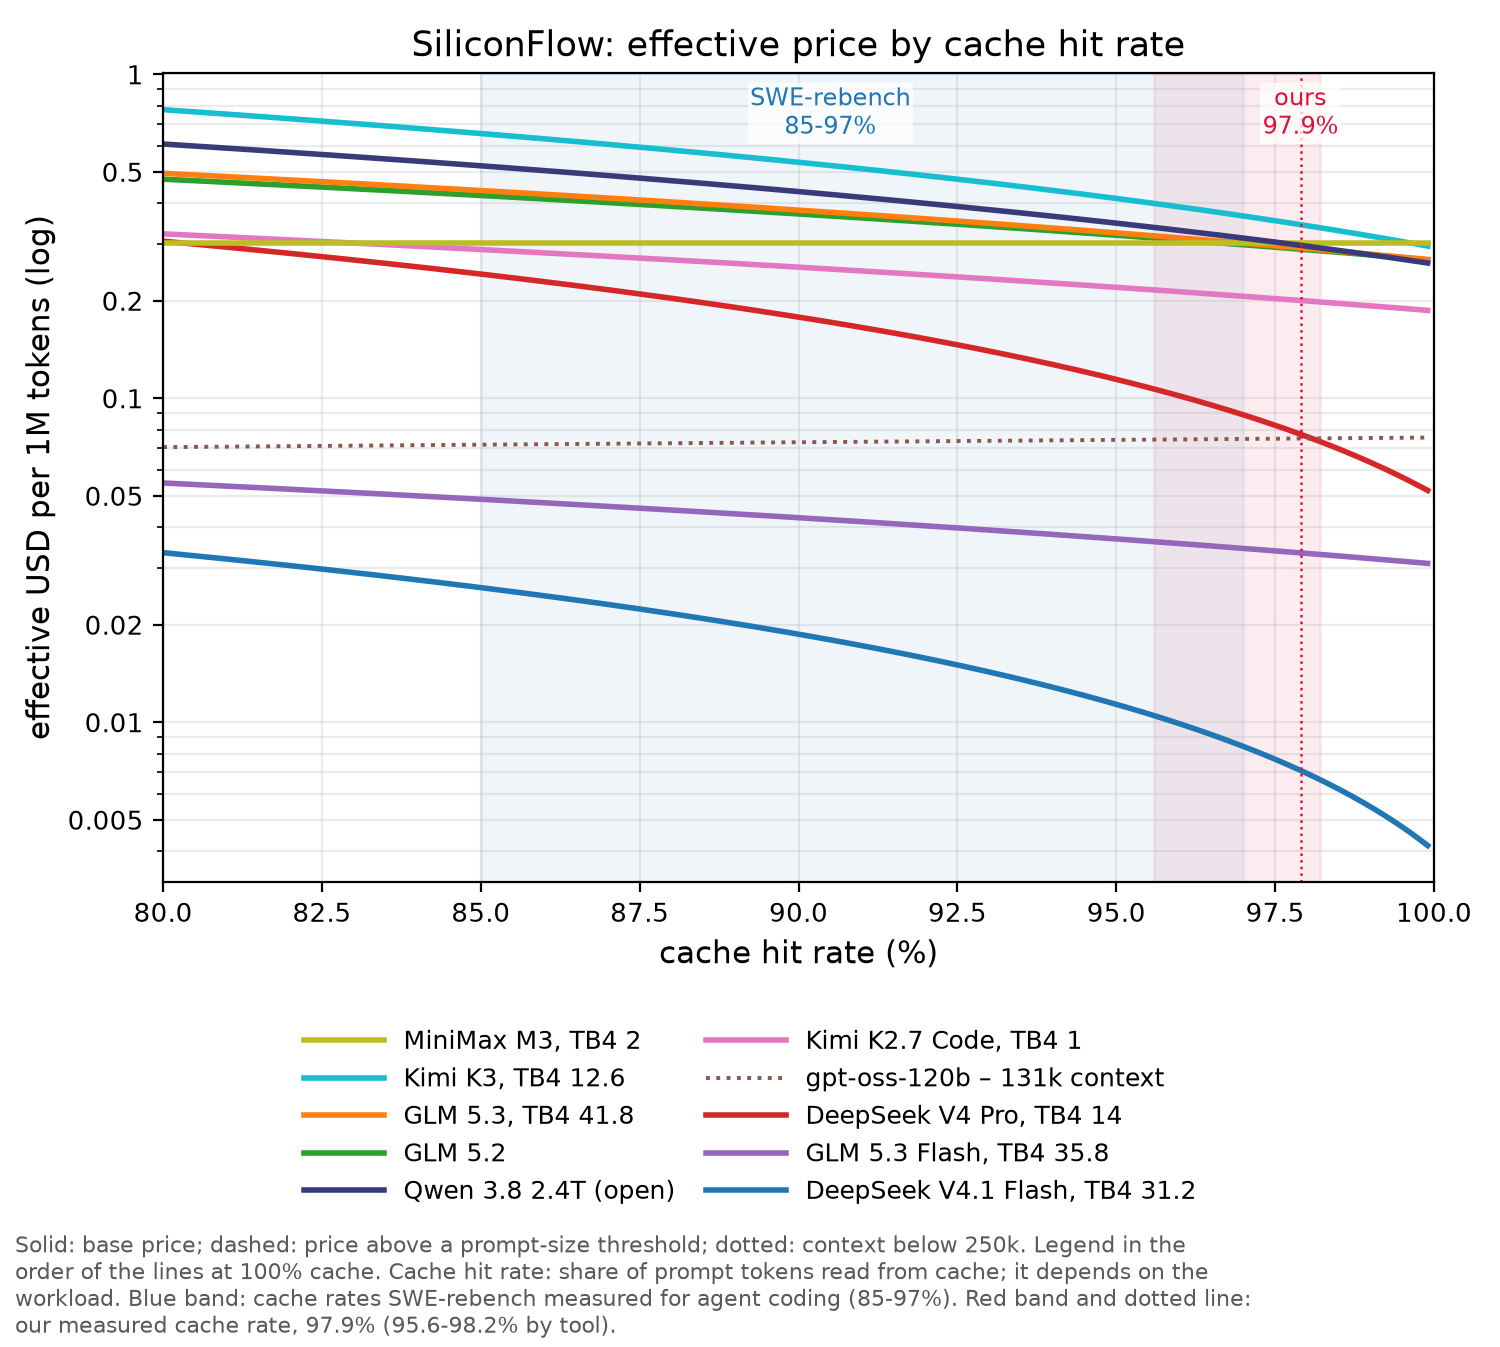
At our mix a full Terminal-Bench 4.0 run of GLM 5.3 (TB4 41.8%) costs USD 2,531; the TB4 leaderboard measured USD 2,700. At our mix a full Terminal-Bench 4.0 run of GLM 5.3 Flash (TB4 35.8%) costs USD 97; the TB4 leaderboard measured USD 2,900.
OpenCode Zen
OpenCode is an open-source coding agent built by Anomaly, the team behind SST. Its site reports more than 16 million developers a month and 208,000 GitHub stars. Next to the free agent, OpenCode sells model access: Zen per token and Go as a subscription.
What to know:
- One key, list prices: Zen sells Claude, GPT, Gemini and open models per token; Opus 5.5 costs Anthropic's 0.334 per 1M at our mix.
- Cached input marked up: Sonnet 5.5 cached costs 0.2 against Anthropic's 0.1 (0.265 against 0.167 at our mix); GPT-6.1 Sol 0.521 against 0.326.
- Gemini half off: Zen lists Gemini 4 Argon at 4 / 0.20 / 20 (0.313 per 1M at our mix) with 50% off through 30 November, which matches AI Studio's 0.157.
- Compare with Go: Go Plus covers 0.82 B GLM 5.3 tokens a month for USD 40; on Zen, GLM 5.3 costs USD 0.291 per 1M at our mix.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Claude Opus 5.5 · TB4 64.8% | 4 / 0.2 / 20 + write 5 | 1M | 0.334 | USD 2,674 |
| Claude Sonnet 5.5 · TB4 61.8% | 2 / 0.2 / 10 + write 2.5 | 1M | 0.265 | USD 5,139 |
| GPT-6.1 Sol · TB4 58.2% | 2 / 0.2 / 10 + write 2.5 | 1.1M | 0.521 | USD 782 |
| GPT-6 Astra · TB4 58.2% | 10 / 1 / 50 + write 12.5 | 1.1M | 2.606 | USD 3,909 |
| Claude Fable 5.1 · TB4 57.9% | 10 / 0.25 / 50 + write 12.5 | 1M | 0.591 | USD 1,597 |
| Gemini 4 Argon · TB4 57.1% | 4 / 0.2 / 20 | 1M | 0.313 | – |
| GPT-6 Sol · TB4 49.4% | 2 / 0.2 / 10 + write 2.5 | 1.1M | 0.521 | USD 2,606 |
| GLM 5.3 · open · TB4 41.8% | 1.4 / 0.26 / 4.4 | 1M | 0.291 | USD 2,531 |
| Claude Haiku 5.5 · TB4 39.2% (vendor) | 0.1 / 0.01 / 0.5 + write 0.12 | 1M | 0.066 | – |
| Grok 4.7 · TB4 37.6% | 2 / 0.5 / 6 | 500k | 1.082 | USD 5,949 |
| GLM 5.3 Flash · open · TB4 35.8% | 0.15 / 0.03 / 0.5 | 1M | 0.033 | USD 97 |
| DeepSeek V4.1 Flash · open · TB4 31.2% (vendor) | 0.3 / 0.006 / 1.2 | 1M | 0.014 | – |
| Qwen 3.8 Max · TB4 27% | 2 / 0.25 / 6 + write 2.5 | 262k | 0.307 | USD 921 |
| Gemini 3.8 Flash · TB4 19.1% | 1.5 / 0.15 / 7.5 | 1M | 0.191 | USD 3,282 |
| GPT-6 Luna · TB4 16.4% | 0.1 / 0.01 / 0.5 + write 0.12 | 1.1M | 0.026 | USD 102 |
| Muse Spark 1.3 · TB4 14.5% | 1.25 / 0.15 / 4.25 | 1M | 0.180 | USD 1,620 |
| DeepSeek V4 Pro · open · TB4 14% | 1.74 / 0.145 / 3.48 | 1M | 0.184 | – |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 | 1M | 0.382 | – |
| MiniMax M3 · open · TB4 2% | 0.3 / 0.06 / 1.2 | 512k | 0.067 | – |
| Kimi K2.7 Code · open · TB4 1% | 0.95 / 0.19 / 4 | 262k | 0.212 | – |
| GLM 5.2 · open | 1.4 / 0.26 / 4.4 | 1M | 0.291 | – |
| Grok Build 0.1 | 1 / 0.2 / 2 | 256k | 0.220 | – |
| Mistral Large 4 | 1.36 / 0.14 / 4.18 | 524k | 0.172 | – |
| Qwen 3.8 Flash · open | 0.15 / 0.016 / 0.47 + write 0.2 | 1M | 0.021 | – |
- Other tiers, GPT-6.1 Sol: above 272k prompt: 4 / 0.4 / 15 + write 5.
- Other tiers, GPT-6 Astra: above 272k prompt: 20 / 2 / 75 + write 25.
- Other tiers, Gemini 4 Argon: promo 50% off through 2026-11-30: 0.5x.
- Other tiers, GPT-6 Sol: above 272k prompt: 4 / 0.4 / 15 + write 5.
- Other tiers, Claude Haiku 5.5: above 100k prompt: 0.5 / 0.05 / 2.5 + write 0.62.
- Other tiers, Grok 4.7: above 200k prompt: 4 / 1 / 12.
- Other tiers, GPT-6 Luna: above 272k prompt: 0.2 / 0.02 / 0.75 + write 0.25.
- Other tiers, Mistral Large 4: promo 50% off: 0.5x.
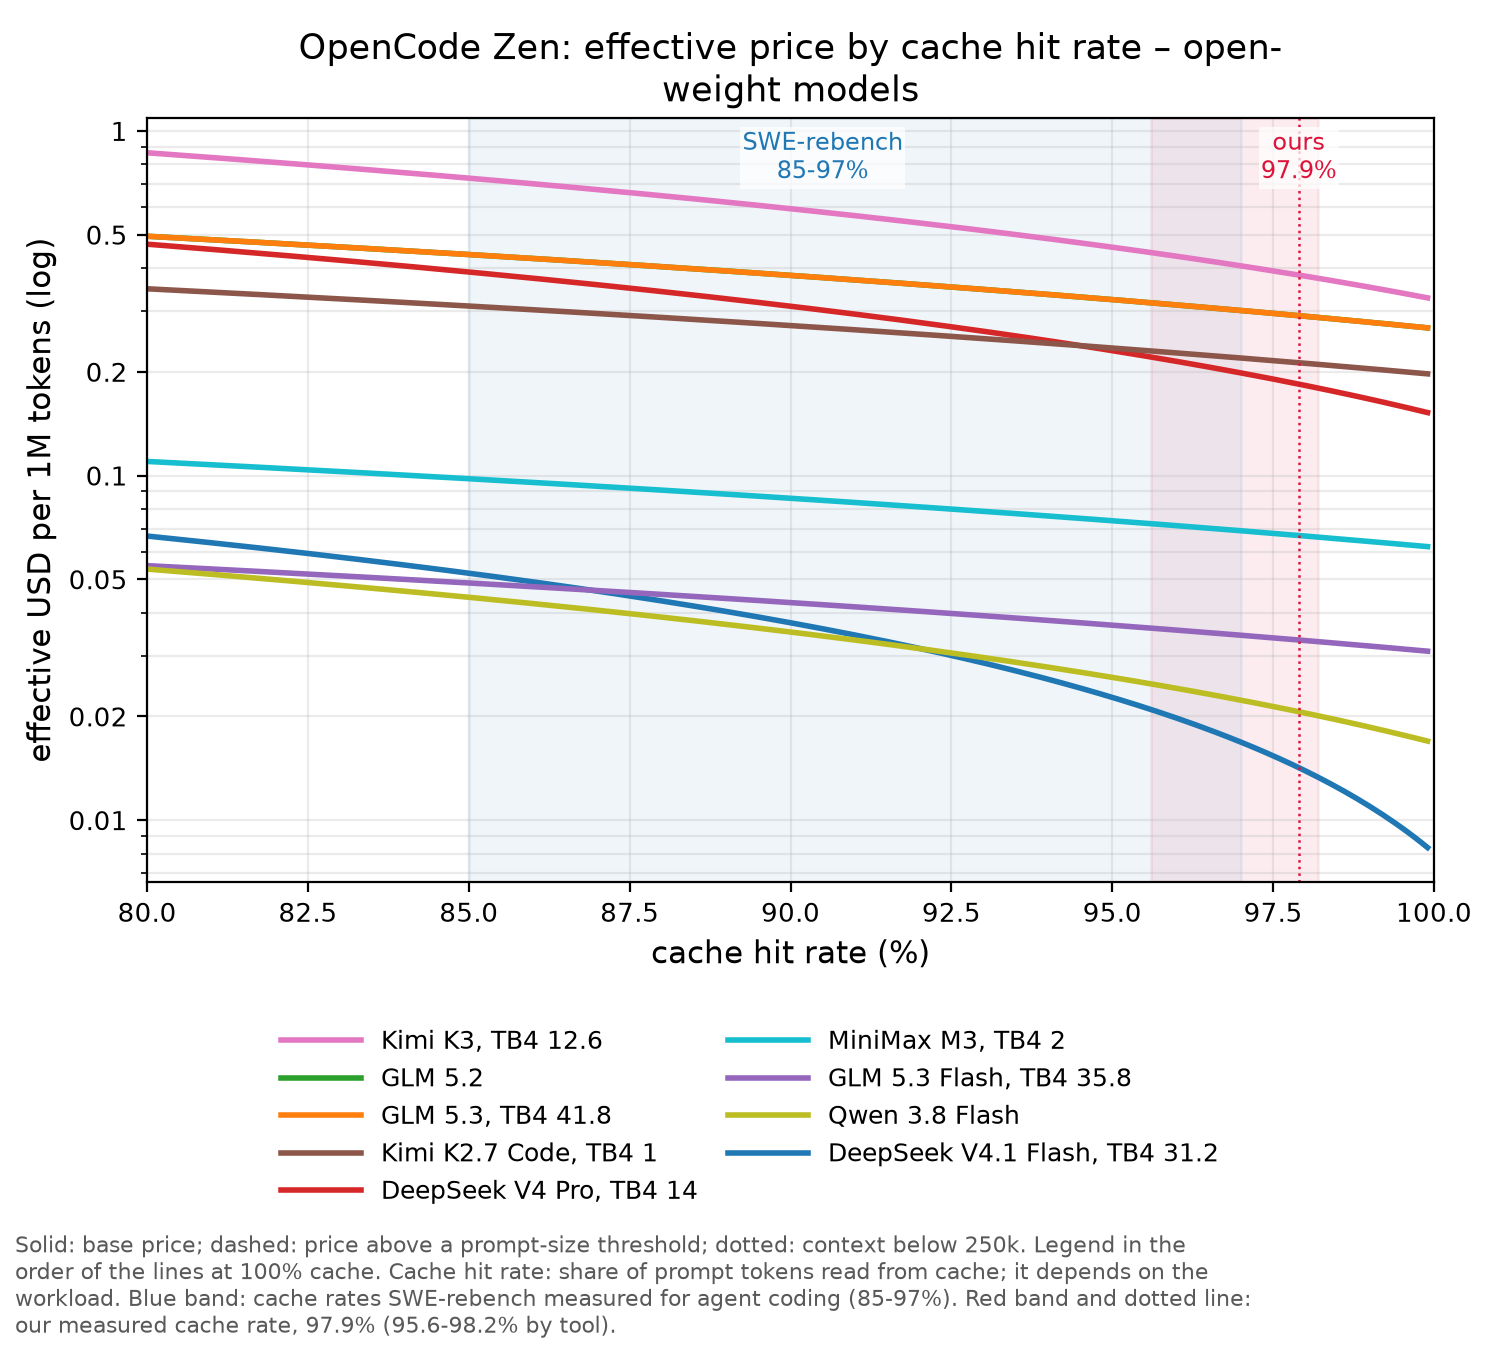
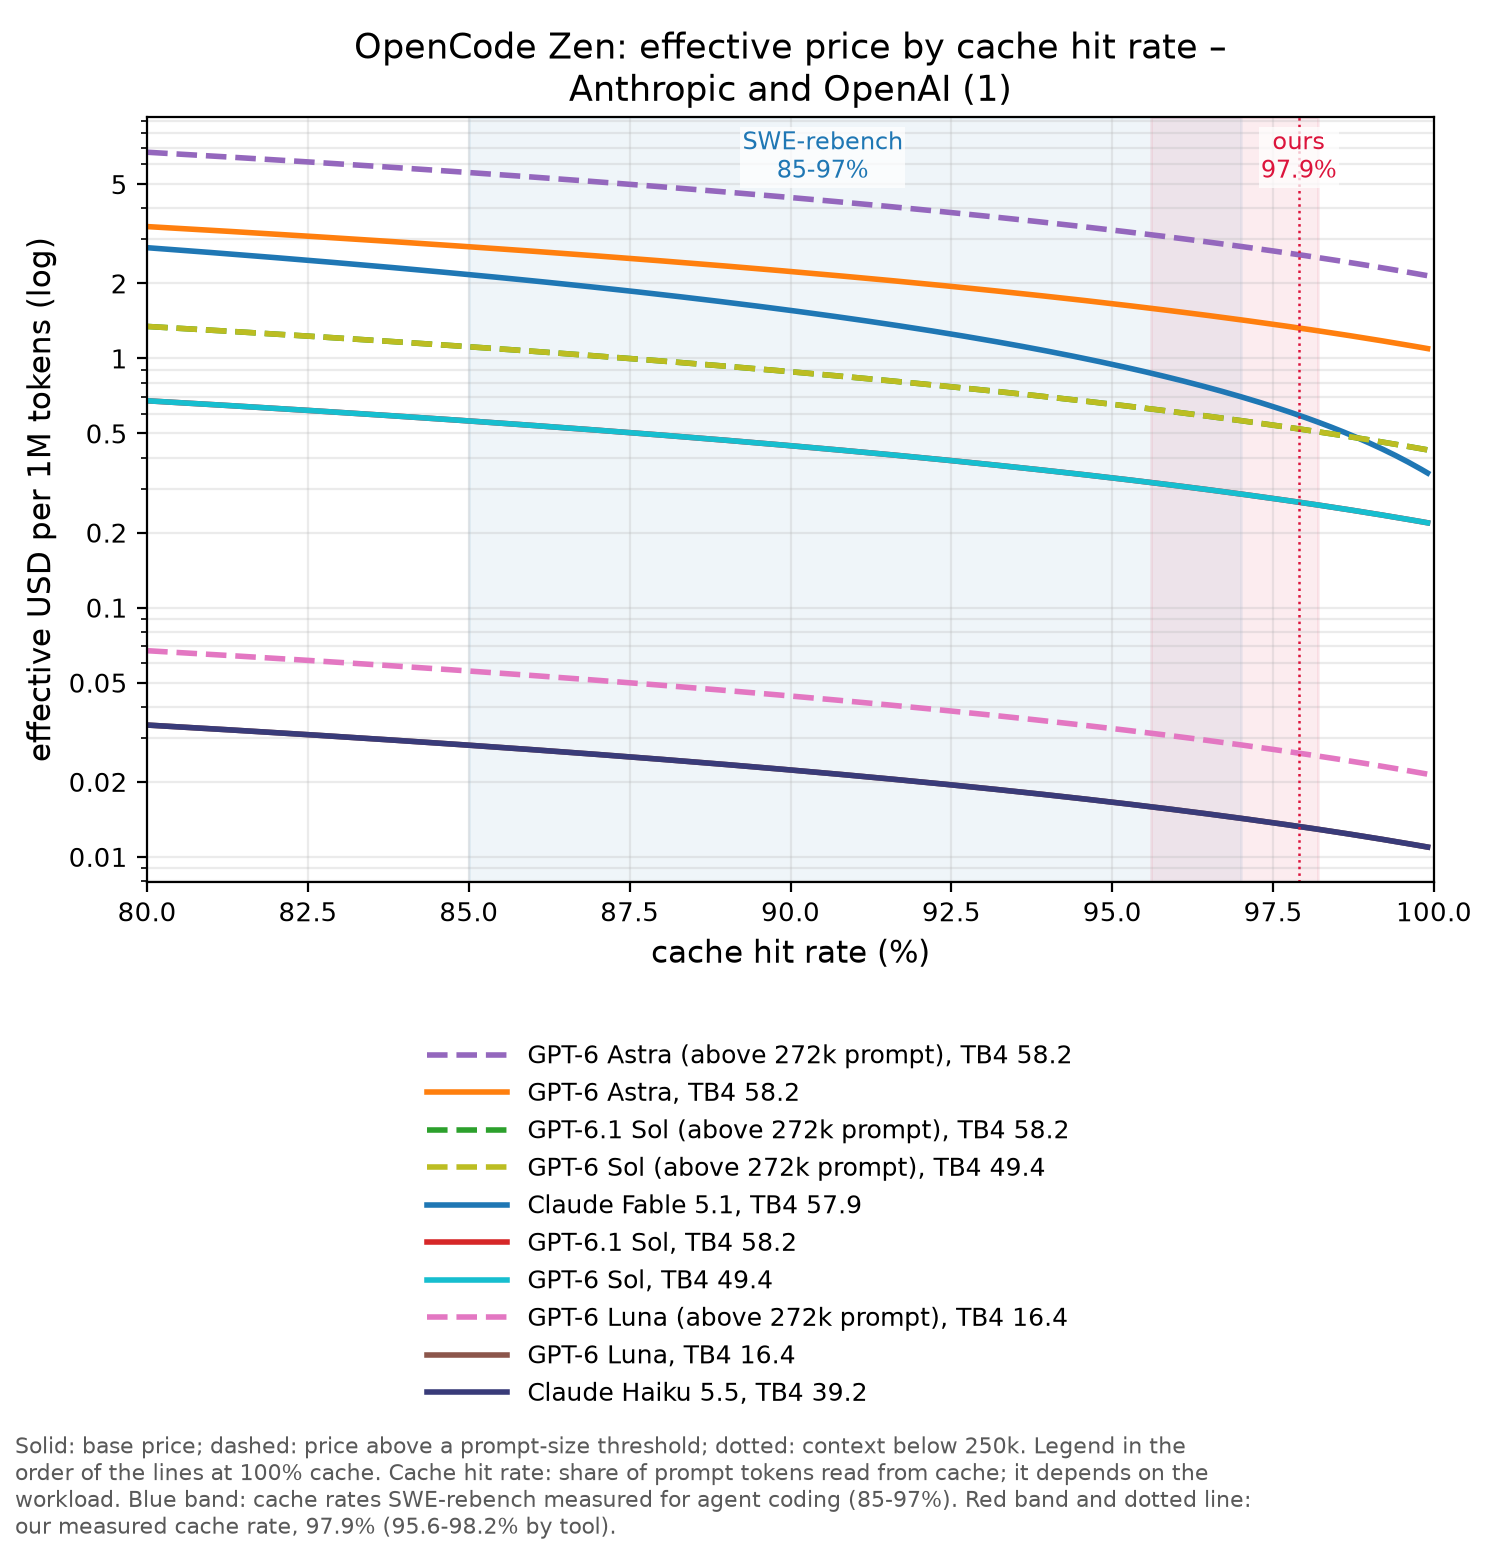
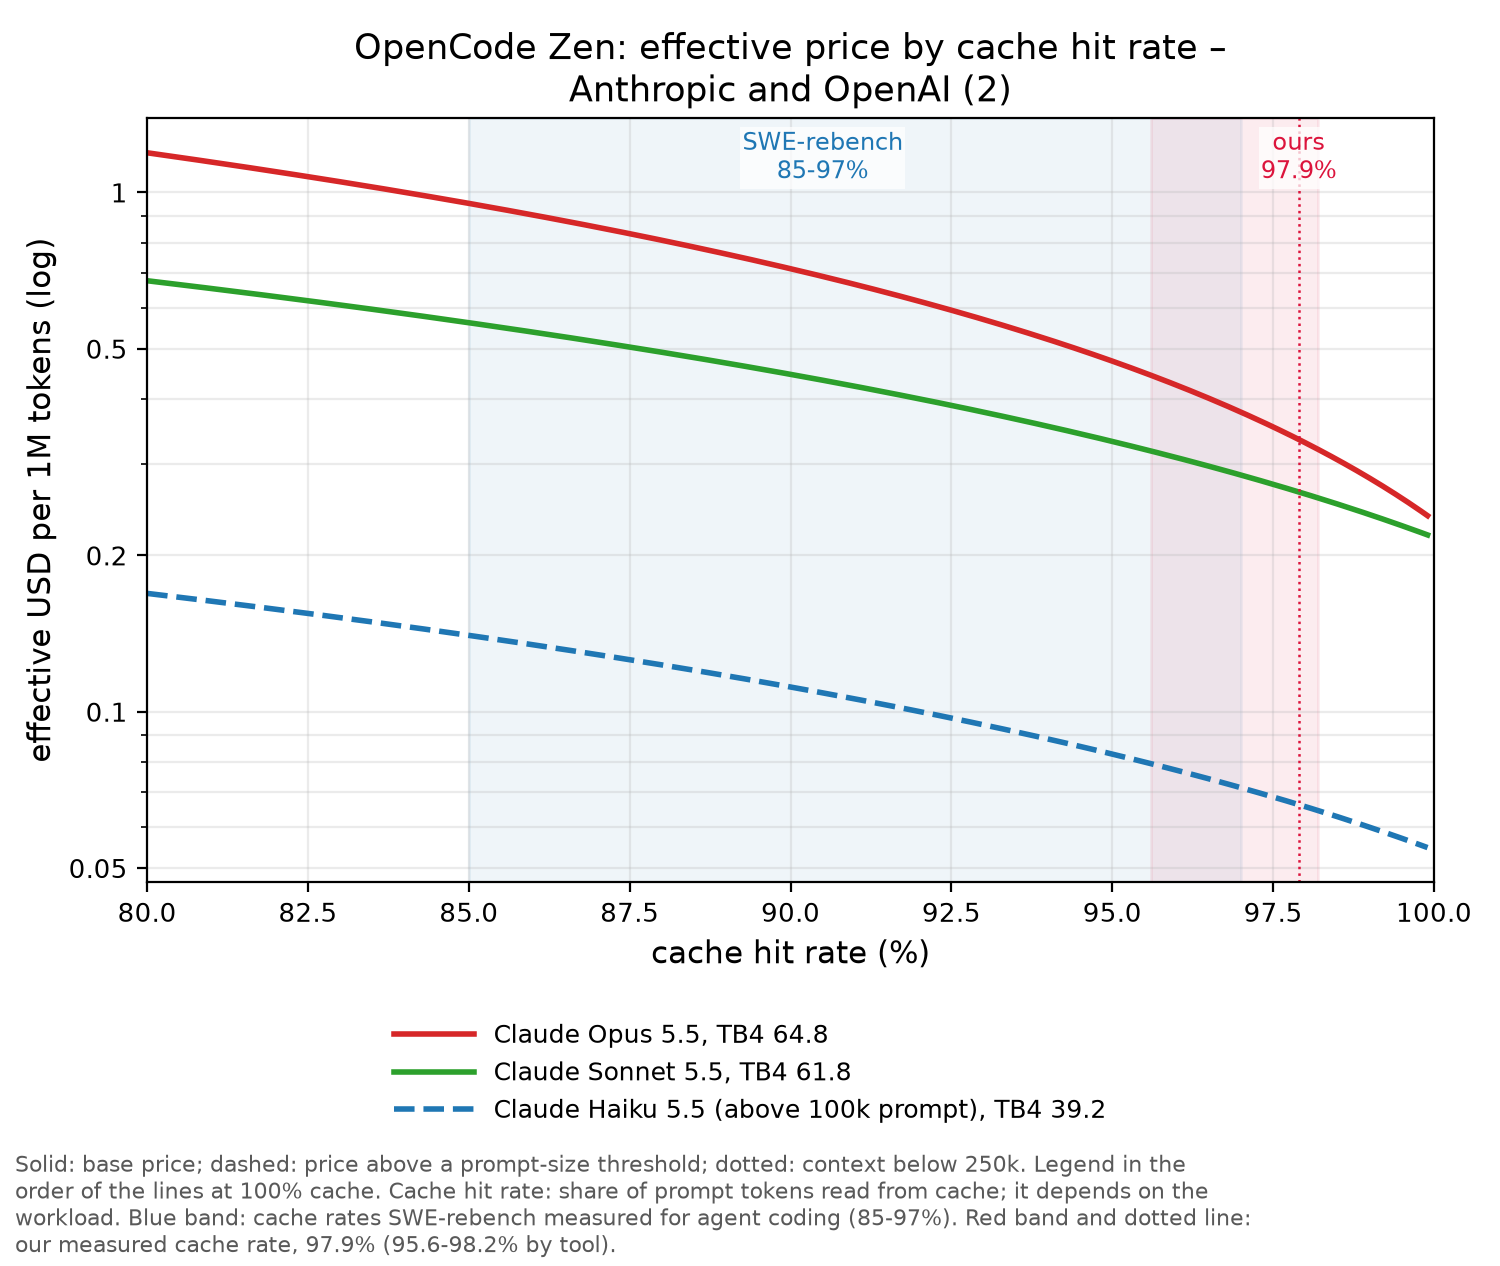
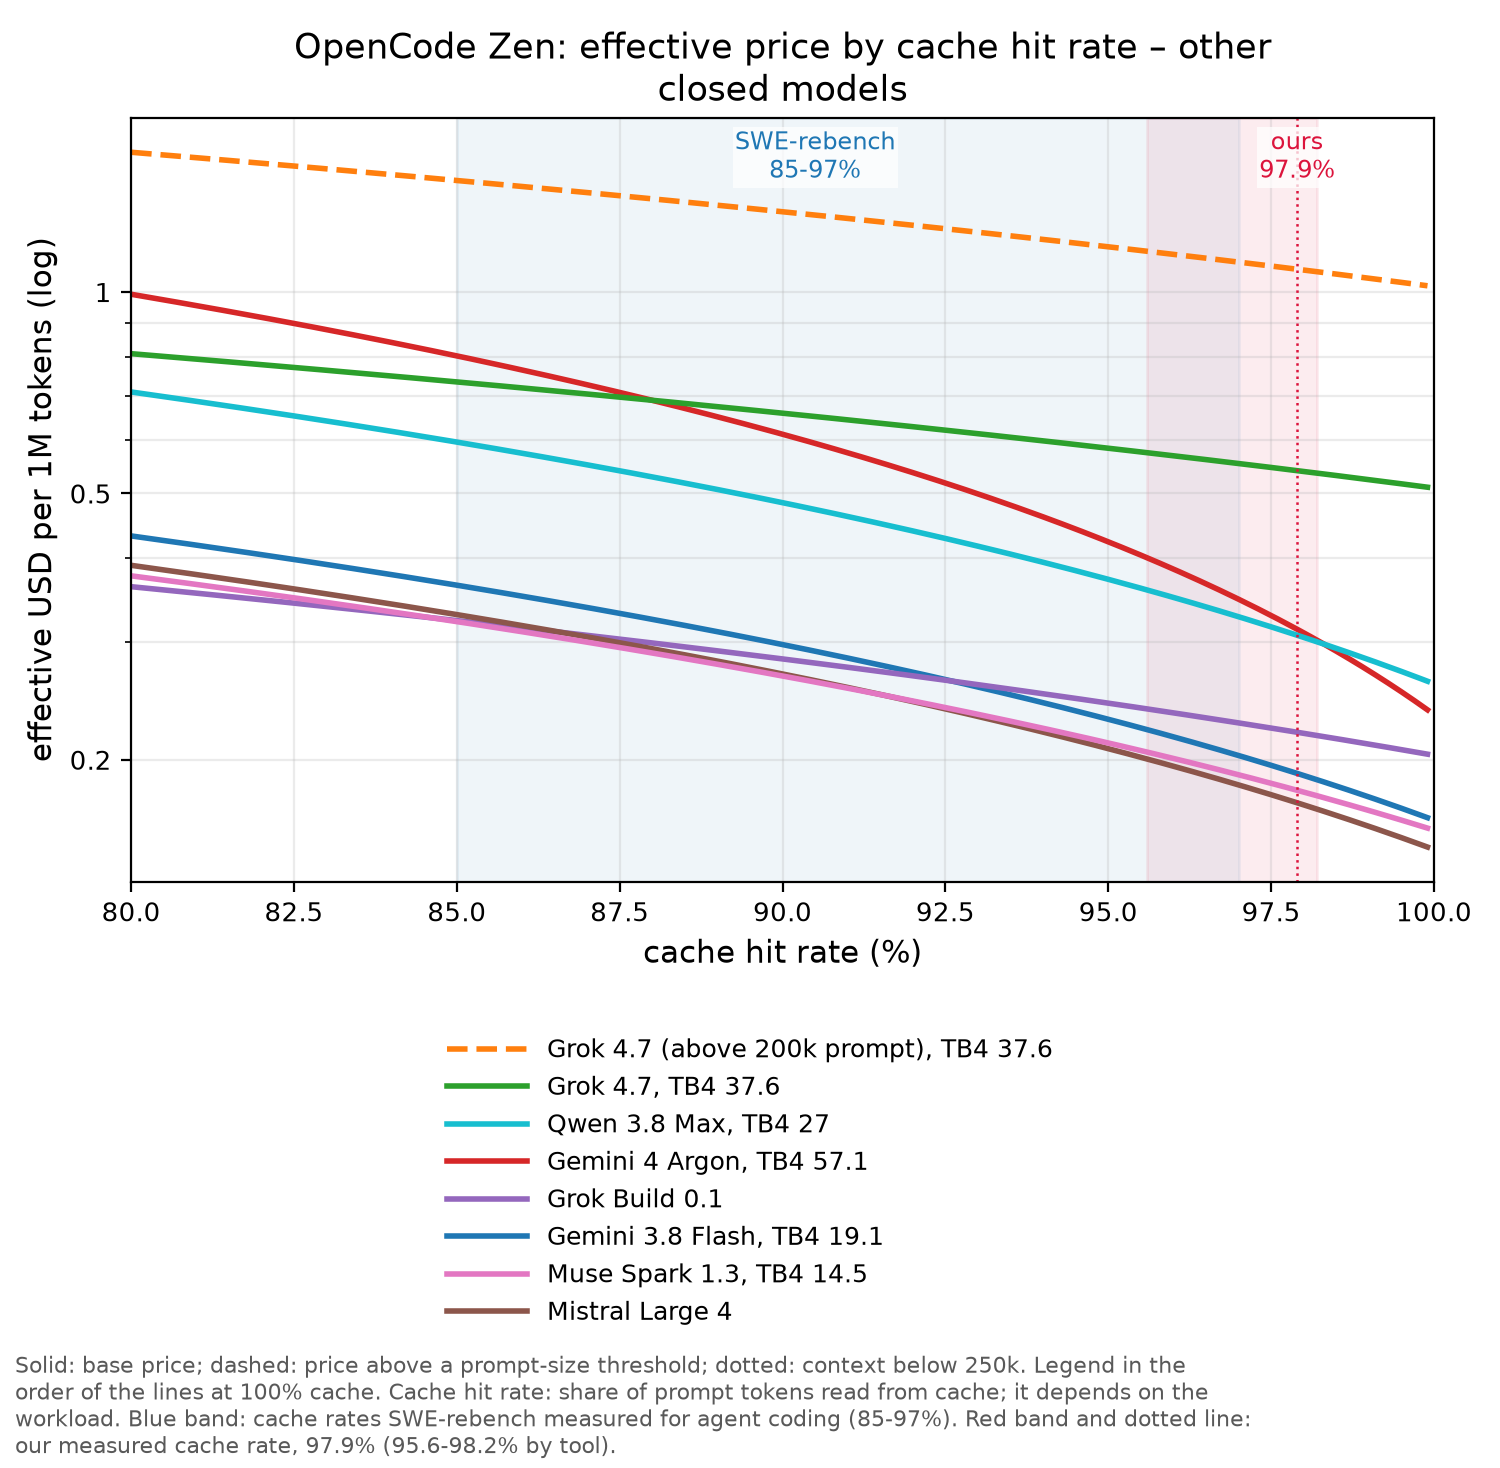
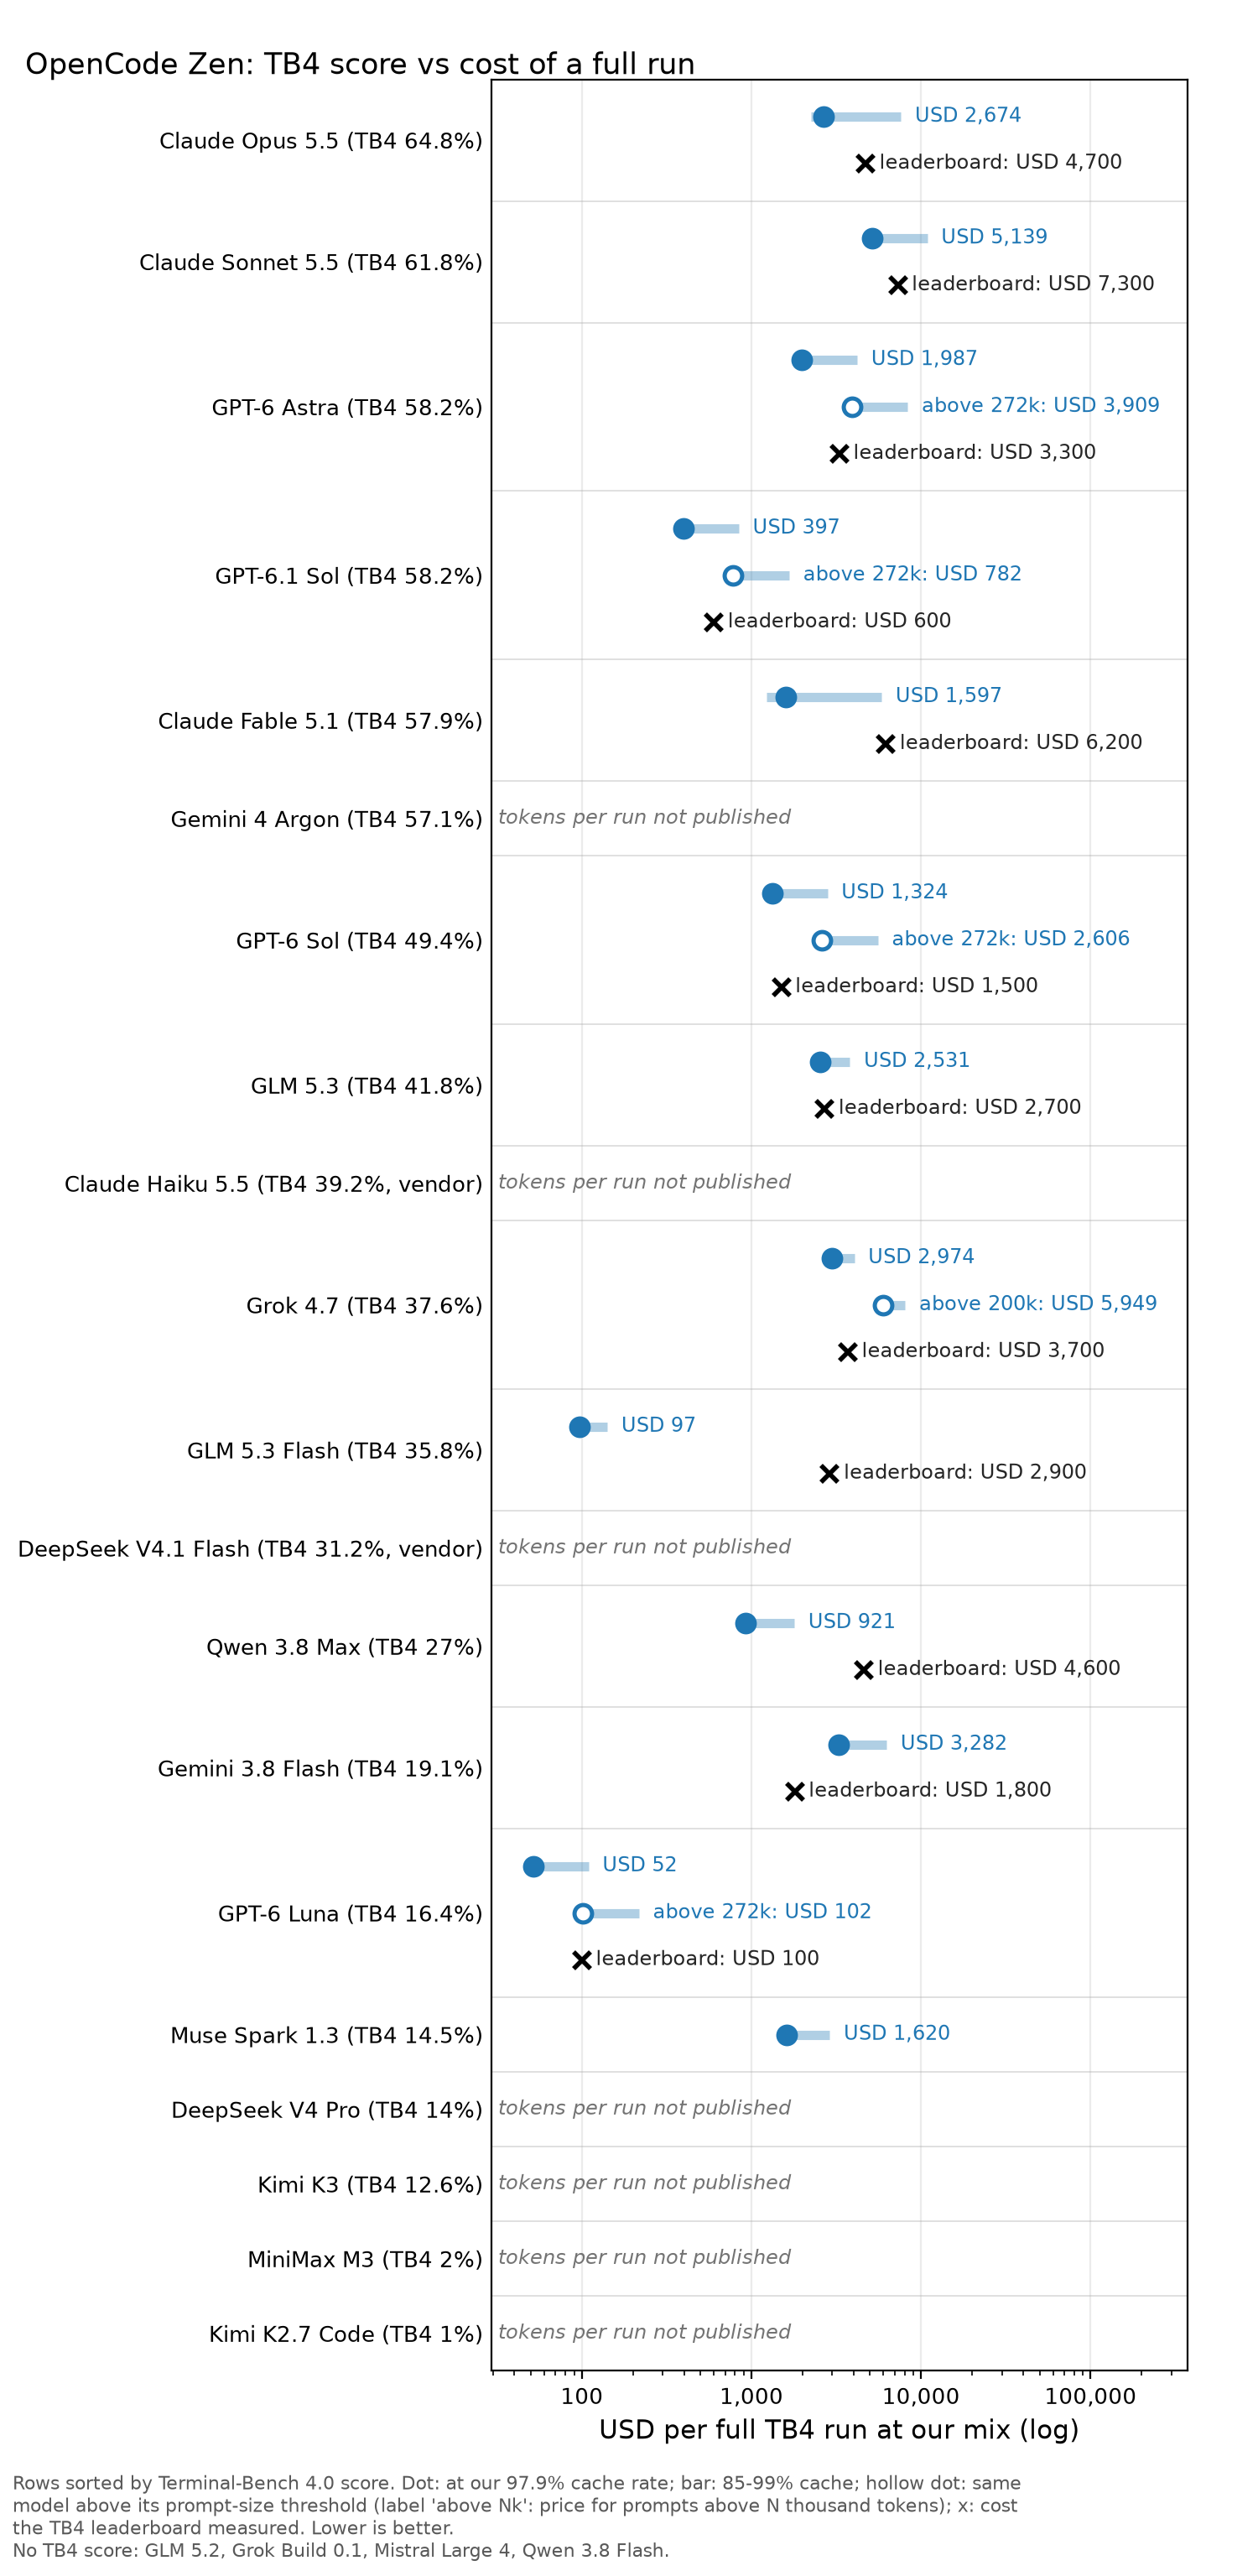
Amazon Bedrock
Amazon Bedrock is the managed model service of Amazon Web Services (AWS). It serves models from Anthropic, OpenAI and other labs alongside open-weight models such as DeepSeek, Qwen3 Coder Next, Kimi and MiniMax, billed per token inside AWS accounts. Amazon said in July 2026 that hundreds of thousands of customers use Bedrock and that customers spent more in the second quarter than in all prior quarters combined.
What to know:
- Best place for Grok: Grok 4.7 on Bedrock has no long-prompt tier, confirmed on AWS's page: USD 0.541 per 1M at our mix against 1.082 at xAI.
- Credits cover Claude, GPT: AWS Activate gives USD 1,000 (up to 5,000) self-funded and up to USD 200,000 with an investor, the only programme here covering both.
- OpenAI 10% dearer: GPT-6.1 Sol costs 0.358 per 1M at our mix against 0.326 at OpenAI. Claude matches Anthropic's list price.
- Open models cost more: GLM 5.3 costs 0.394 against Z.ai's 0.291, with a cache-write fee. Kimi K3 costs 0.397.
- Contract levers: Batch 50% off, Flex 50% off, priority plus 75%, and zero data retention as a per-Region setting.
| Model | USD per 1M: in / cached / out | Context | At our mix, per 1M | Per TB4 run at our mix |
|---|---|---|---|---|
| Claude Opus 5.5 · TB4 64.8% | 4 / 0.2 / 20 + write 5 | 1M | 0.334 | USD 2,674 |
| Claude Sonnet 5.5 · TB4 61.8% | 2 / 0.1 / 10 + write 2.5 | 1M | 0.167 | USD 3,243 |
| GPT-6.1 Sol · TB4 58.2% | 2.2 / 0.11 / 11 + write 2.75 | 1.1M | 0.358 | USD 538 |
| GPT-6 Astra · TB4 58.2% | 11 / 1.1 / 55 + write 13.75 | 1.1M | 2.867 | USD 4,300 |
| Claude Fable 5.1 · TB4 57.9% | 10 / 0.25 / 50 + write 12.5 | 1M | 0.591 | USD 1,597 |
| GPT-6 Sol · TB4 49.4% | 2.2 / 0.22 / 11 + write 2.75 | 1.1M | 0.573 | USD 2,867 |
| GLM 5.3 · open · TB4 41.8% | 1.85 / 0.3432 / 5.81 + write 2.31 | 1M | 0.394 | USD 3,425 |
| Claude Haiku 5.5 · TB4 39.2% (vendor) | 0.1 / 0.01 / 0.5 + write 0.12 | 1M | 0.066 | – |
| Grok 4.7 · TB4 37.6% | 2 / 0.5 / 6 | 500k | 0.541 | USD 2,974 |
| GPT-6 Luna · TB4 16.4% | 0.11 / 0.011 / 0.55 + write 0.14 | 1.1M | 0.029 | USD 112 |
| Kimi K3 · open · TB4 12.6% | 3 / 0.3 / 15 + write 3.75 | 1M | 0.397 | – |
| Devstral 2 | 0.4 / – / 2 | 262k | 0.403 | – |
| gpt-oss-120b · open | 0.15 / – / 0.6 | 128k (below 250k) | 0.151 | – |
-
Other tiers, GPT-6.1 Sol: above 272k prompt: 4.4 / 0.22 / 16.5 + write 5.5.
-
Other tiers, GPT-6 Astra: above 272k prompt: 22 / 2.2 / 82.5 + write 27.5.
-
Other tiers, GPT-6 Sol: above 272k prompt: 4.4 / 0.44 / 16.5 + write 5.5.
-
Other tiers, GLM 5.3: Global CRIS; cache write TTL 30 min: 0.91x; US CRIS; cache write TTL 30 min: 1x.
-
Other tiers, Claude Haiku 5.5: above 100k prompt: 0.5 / 0.05 / 2.5 + write 0.62.
-
Other tiers, Grok 4.7: us.xai.grok-4.7: 1.1x; global.xai.grok-4.7: 1x.
-
Other tiers, GPT-6 Luna: above 272k prompt: 0.22 / 0.022 / 0.82 + write 0.28.
-
Other tiers, Kimi K3: Global CRIS; cache write TTL 30 min: 1x; US CRIS; cache write TTL 30 min: 1.1x.
-
Other tiers, Devstral 2: US East (N. Virginia), US East (Ohio) and US West (Oregon): 1x; Asia Pacific (Mumbai): 1.2x; South America (Sao Paulo) and Asia Pacific (Tokyo): 1.2x; Europe (Ireland) and Europe (Milan): 1.2x; Europe (London): 1.55x; Asia Pacific (Sydney): 1.02x; Asia Pacific (Jakarta), Europe (Frankfurt) , Europe (Stockholm): 1.2x.
-
Caching (Claude (Opus/Sonnet 4.5 and later)): both; TTL 5 min or 1 h; resets on each hit; cached discount 90% (AWS blog); Sonnet 5.5 cache reads cut 50% from 7 Oct 2026; write fee 1.25x input (5 min); 2x input (1 h); peak pricing: not stated (Priority +75%, Flex -50% service tiers)
-
Caching (Kimi K3): both | sources differ: prompt-caching guide's explicit table omits Kimi K3; TTL at least 30 min; resets on each hit; cached discount 90% ($0.30 vs $3.00, Global CRIS); write fee separate line item: $3.75/1M (30 min) = 1.25x input, Global CRIS; peak pricing: not stated (Priority +75%, Flex -50% service tiers)
-
Caching (other open-weight models (MiniMax M2.5, DeepSeek v3.2, Qwen3 Coder 30B)): not stated (varies by model, see model card); TTL not stated; cached discount no cached price listed ("–"); write fee not stated; peak pricing: not stated (Priority +75%, Flex -50% service tiers)
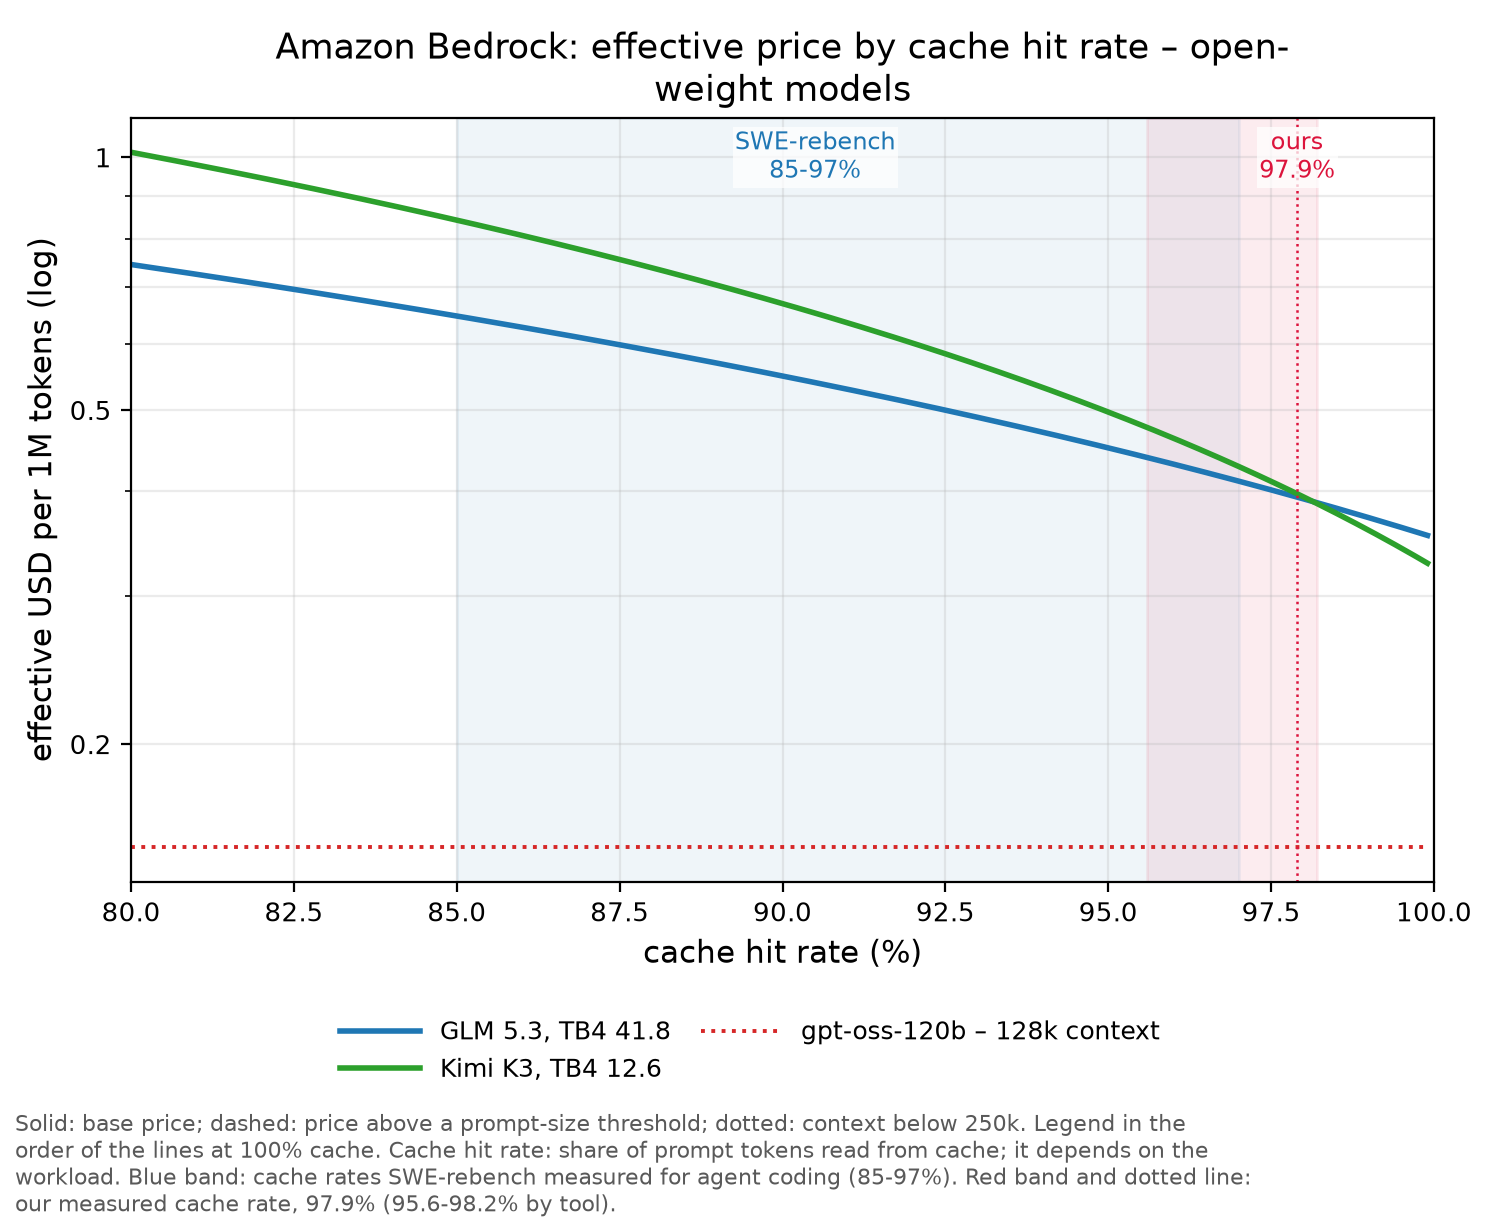
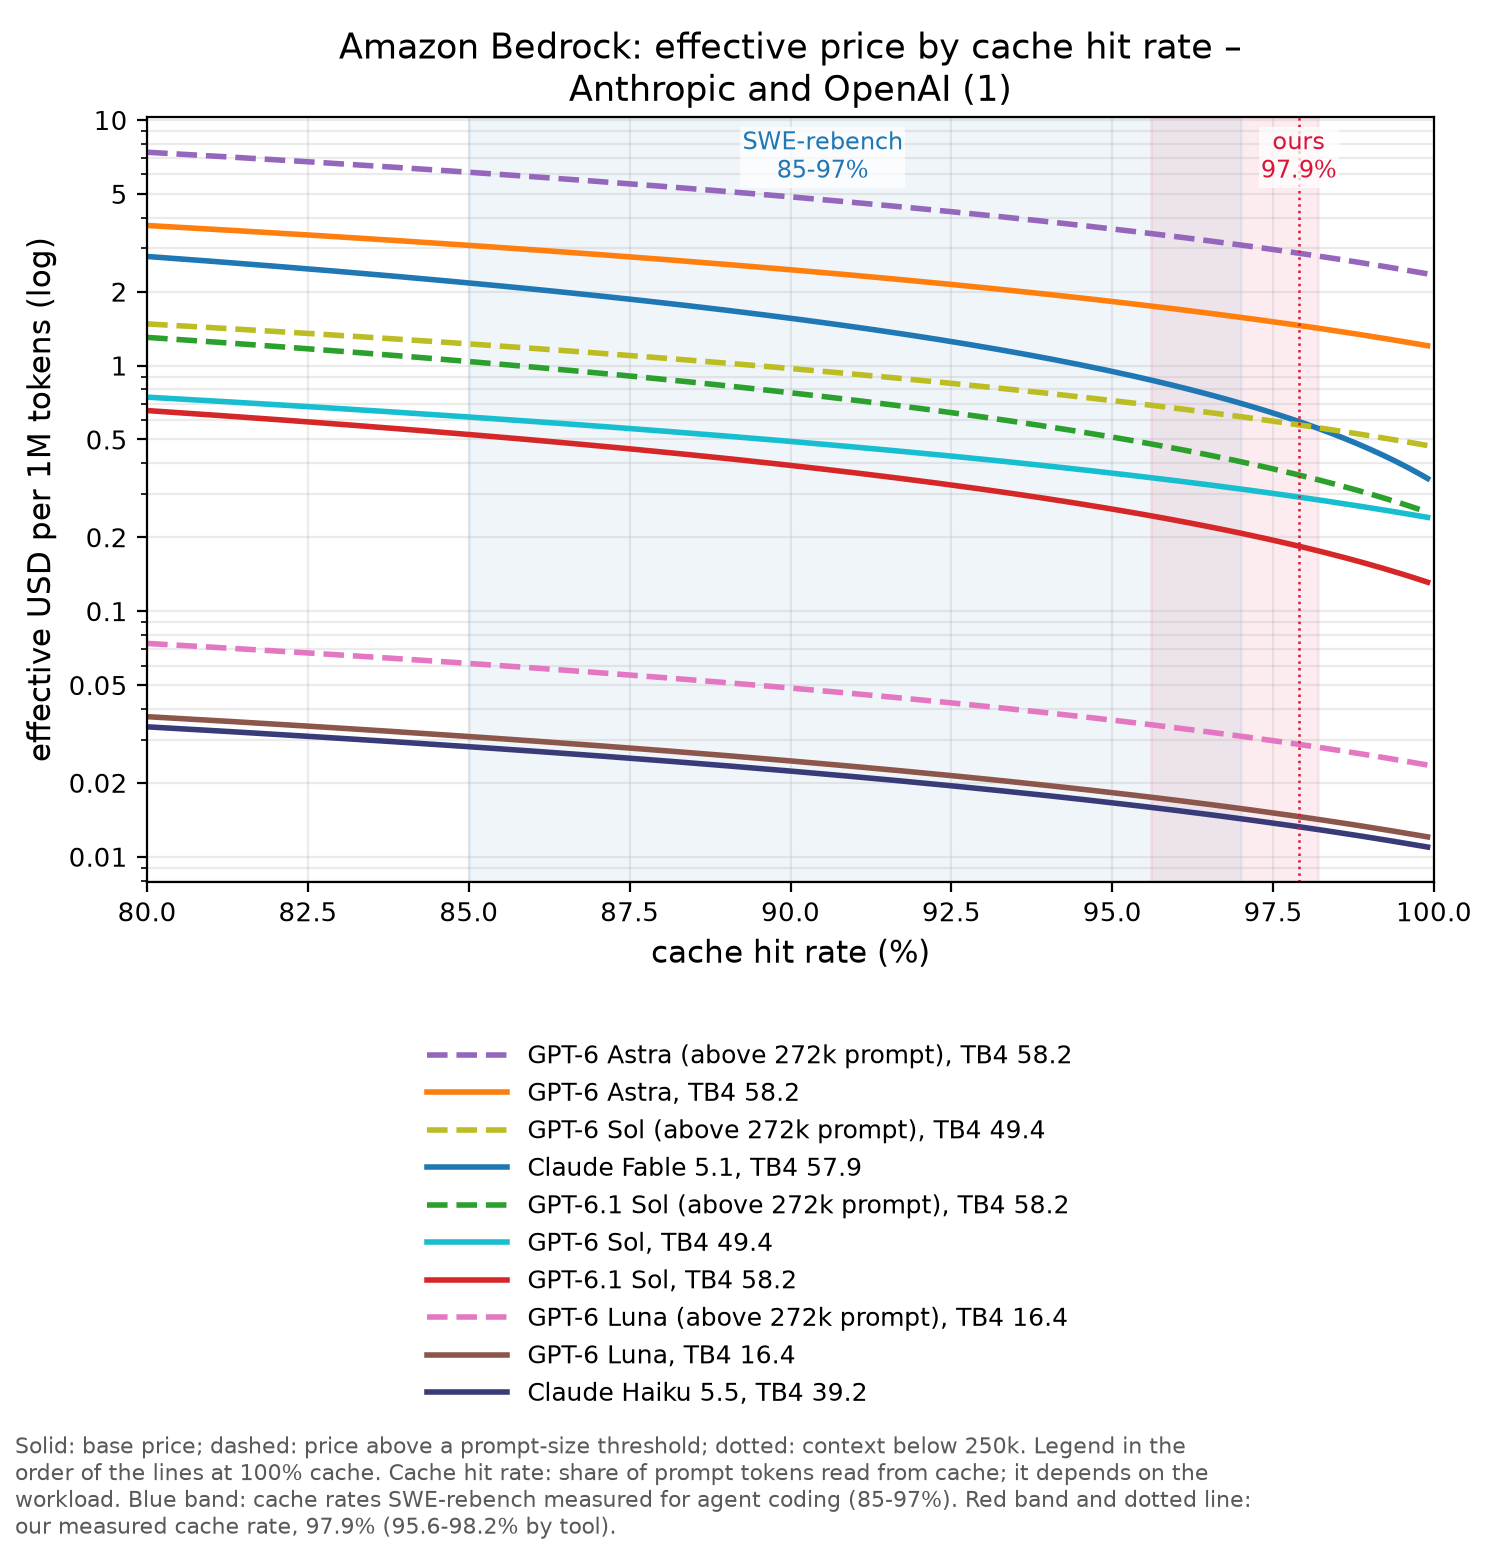
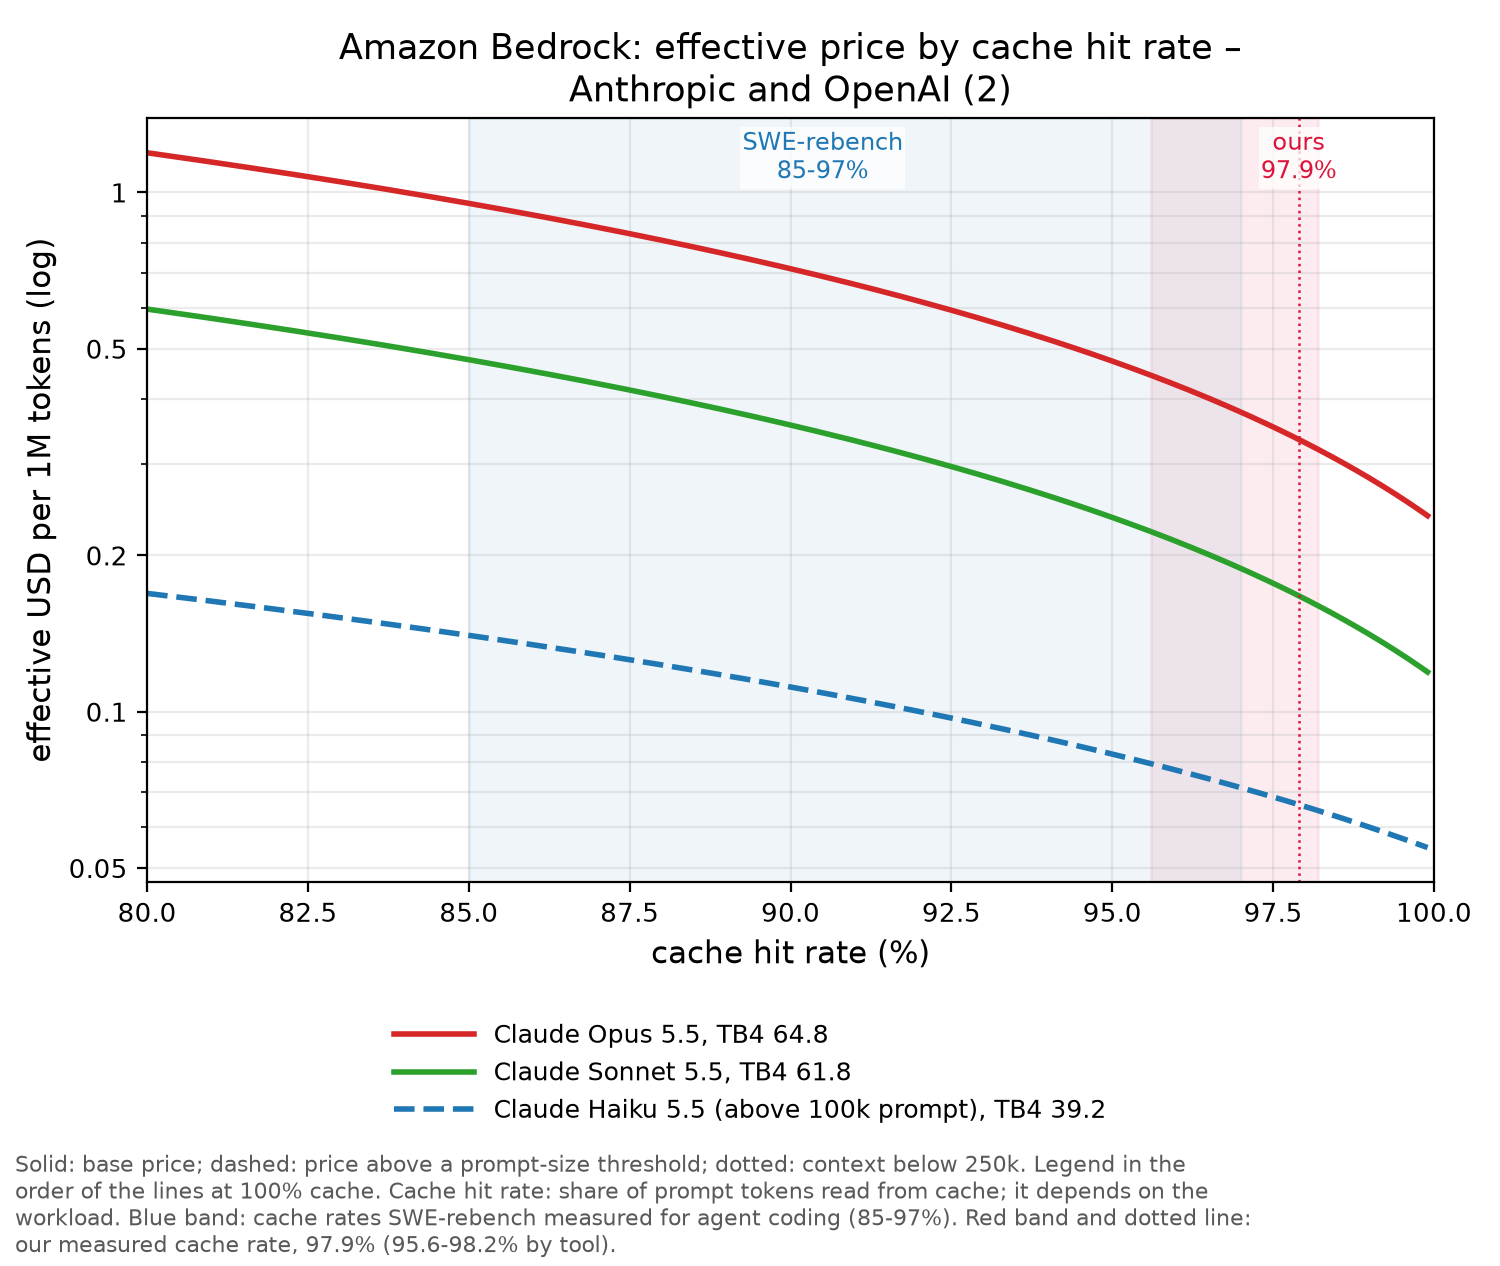
At our mix (97.9% cache) Devstral 2 costs USD 0.4 per 1M tokens (USD 0.4 to 0.4 at 85-99% cache). At our mix (97.9% cache) Grok 4.7 costs USD 0.54 per 1M tokens (USD 0.52 to 0.73 at 85-99% cache).
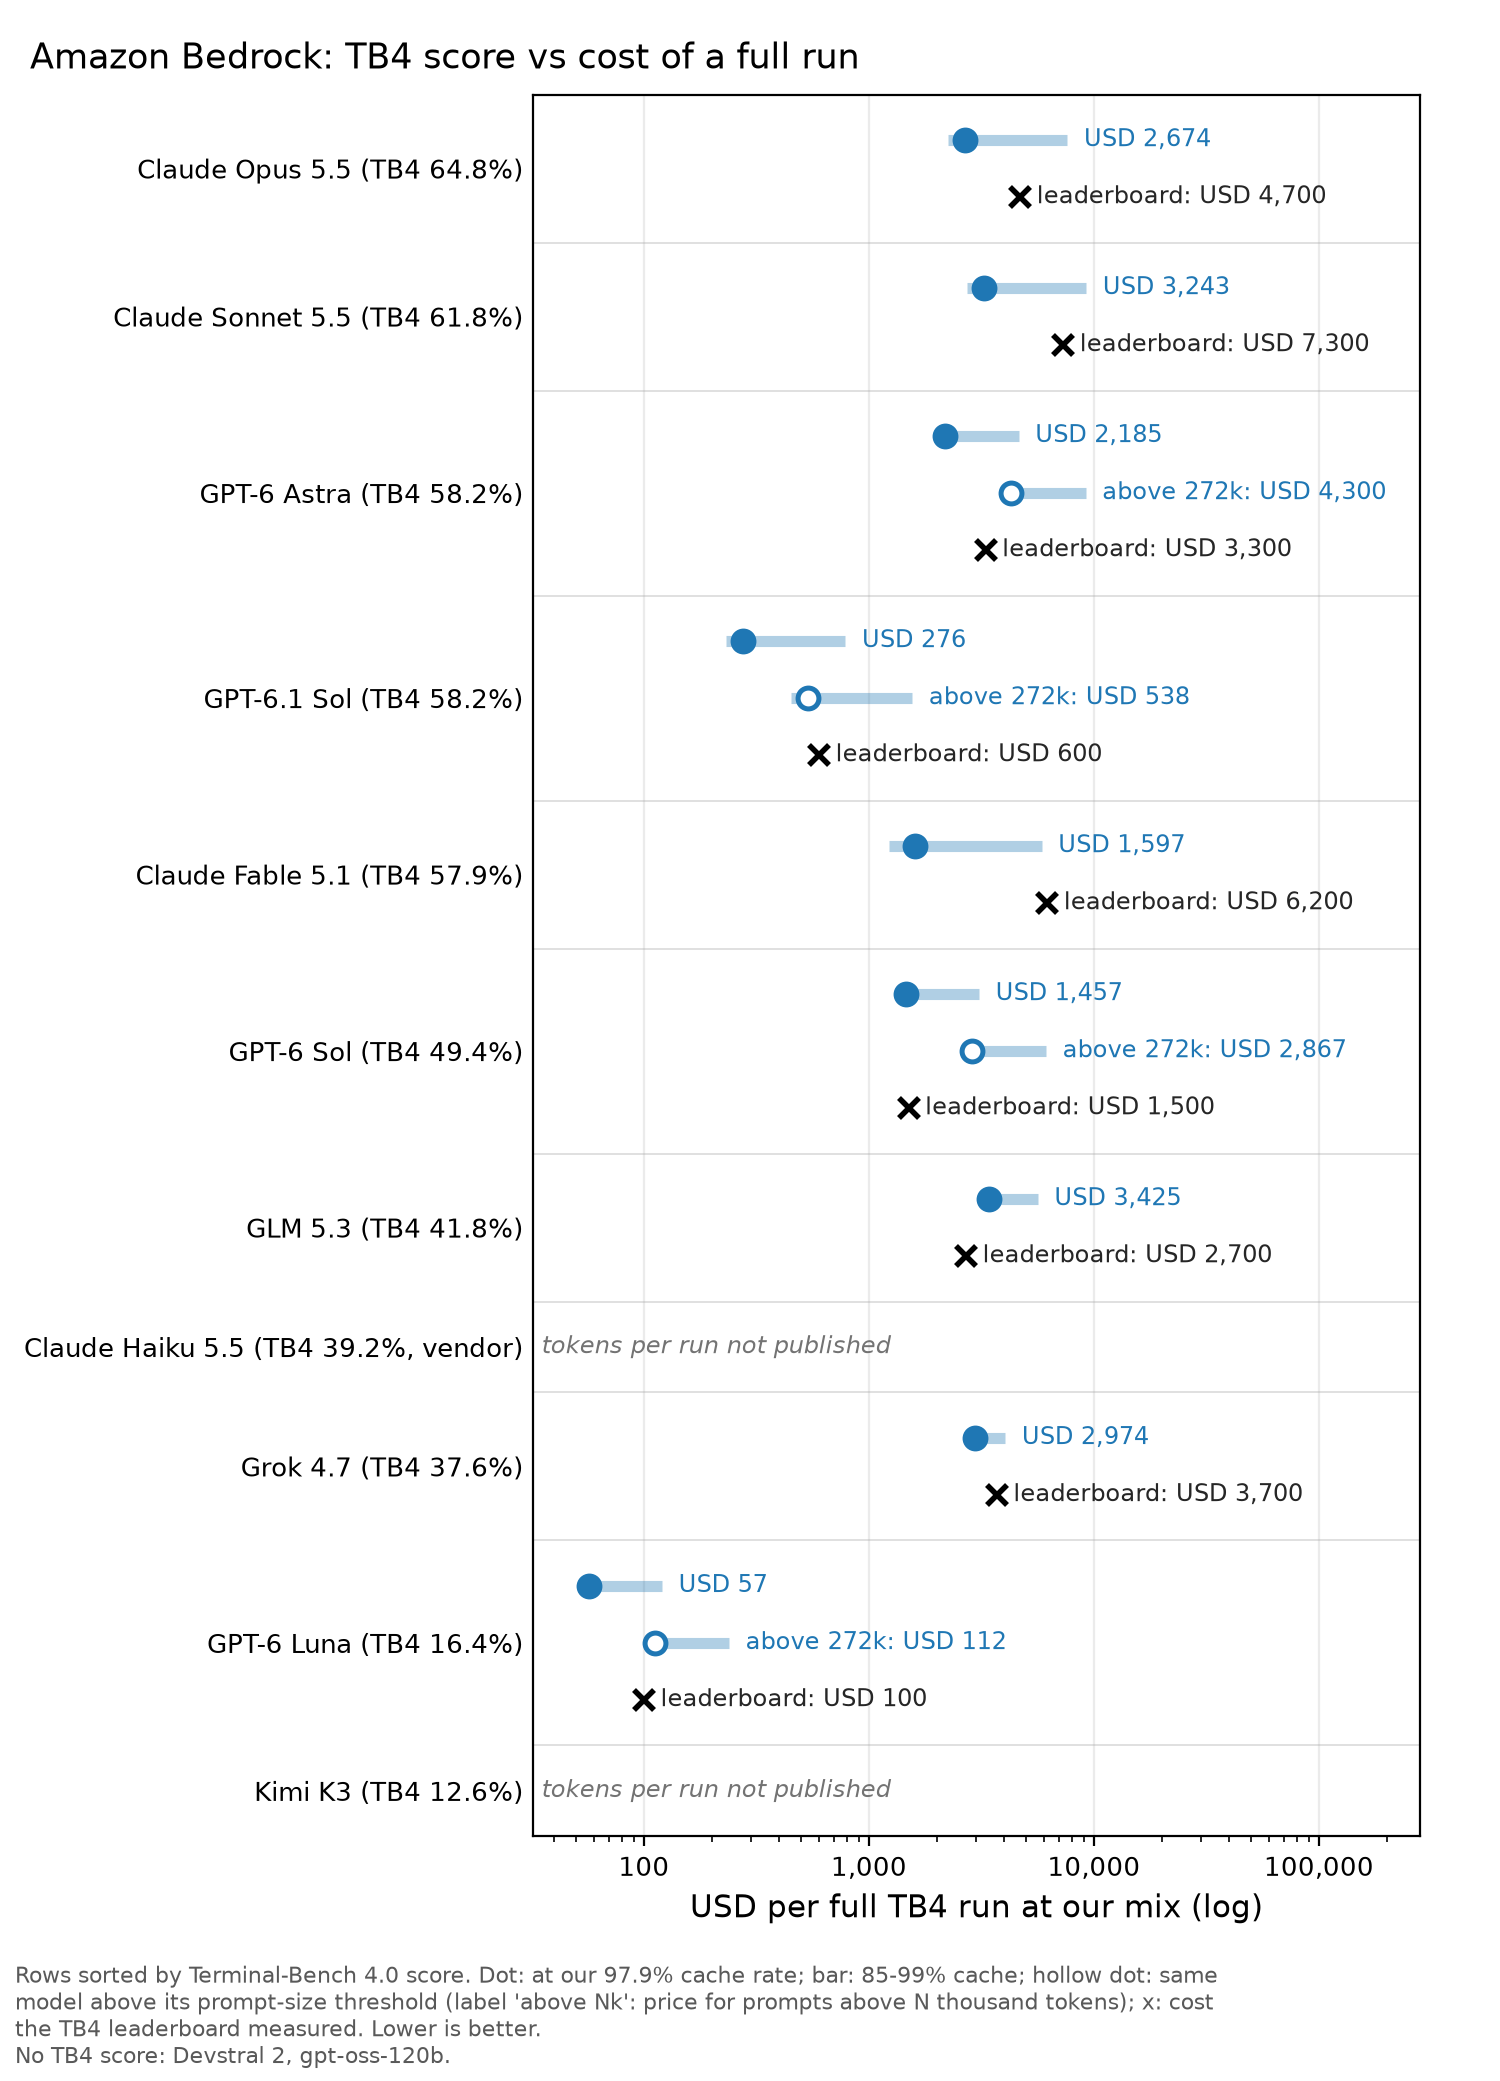
Sources
Cost of agentic work
- gartner.com: 2026 06 24 gartner predicts ai coding costs will surpass ave…
- computerweekly.com: Gartner AI coding agents will cost more than real developers
- jellyfish.co: state of ai software engineering
- code.claude.com: costs
- requesty.ai: The Coding Agent Economy
- mckinsey.com.br: is that ai agent worth it agentic economics and the modern o…
- bloomberg.com: startups like harvey embrace open models to cut reliance on …
- finance.yahoo.com: openai anthropic costs push more 160523322
- csdisco.com: legal ais next challenge isnt accuracy its the bill
- markets.ft.com: detail
- csdisco.app.box.com: 2026 Legal AI Report
- ey.com: ey us can ai pay for itself
- ey.com: agentic ai token costs
- businessinsider.com: marc benioff salesforce anthropic spend tokens slack 2026 5
- kpmg.com: global ceo outlook survey
- kpmg.com: global ceo outlook survey
- gartner.com: gartner survey finds only 22 percent of organizations have s…
- hrdive.com: 814279
- businessinsider.com: meta ai employee performance review overhaul 2025 11
- futurumgroup.com: 46 9 of enterprises report ai spend over budget in 2h 2026
- doit.com: ai spending survey
- cfodive.com: 825961
- theverge.com: microsoft claude code discontinued notepad
- finance.yahoo.com: blowing entire 2026 ai budget 174815792
- cloudzero.com: 20260624
- data.finops.org
- pwc.com: pwc 2026 global ceo survey
- pwc.com: ceo survey mid year snapshot
Benchmarks
Measured subscription limits
- wokey.ai: claude pro limits
- wokey.ai: claude usage limits
- newsletter.semianalysis.com: anthropic subscriptions offer 5x
- finopsllm.com: claude vs codex october 2026
- danubelabs.net: claude max weekly limits cut
- github.com: 97467
- github.com: 100746
- wokey.ai: claude max limits
- zenn.dev: 25c0ab111c277c
- wokey.ai: codex usage limits
- inventivehq.com: codex subscription usage measured
- electricitybench.com: antigravity cli
- discuss.ai.google.dev: 183629
- developertoolkit.ai: gemini cli
- kimi.com: membership overview
- linux.do: 2936074
- blog.margrop.net: kimi 199 new vs old subscription token quota analysis
- reddit.com: chinese max plan burns its 5h window 9x faster
- linux.do: 2617259
- linux.do: 2620965
- linux.do: 2615396
- v2ex.com: 1235826
- v2ex.com: 1228735
- forum.moonshot.ai: 476
- forum.moonshot.ai: 486
- reddit.com: plans limits tokens api pricing
- linux.do: 2925074
- github.com: kimi adoption round6 2026 09 08.json
- github.com: codingplan
- v2ex.com: 1239593
- reddit.com: i got a official response about tiers usagelimits
- github.com: minimax m31 flash preview cn round1 2026 10 01.json
- platform.minimax.io: token plan notice
- platform.minimax.io: intro
- platform.minimax.cn: intro
- platform.minimax.io: pricing token plan
- reddit.com: im done
- reddit.com: can someone explain how the new token plan quota
- reddit.com: minimax max plan review
- docs.z.ai: overview
- linux.do: 2966676
- reddit.com: am i misunderstanding something or glms coding
- reddit.com: coding plans are good again
- 163.com: L4ILFQL60519DDOA
- linux.do: 2756196
- x.com: 2075798274603397535
- github.com: awesome coding plan
- linux.do: 2572675
- reddit.com: modelark coding plan experience
- reddit.com: byteplus coding plan advertised as 3x claude pro
- docs.byteplus.com: 1925114
- docs.byteplus.com: coding plan personal faq
- cloud.tencent.com: 133811
- forum.cursor.com: 207
- forum.cursor.com: 174450
- forum.cursor.com: 200
- forum.cursor.com: 301
- forum.cursor.com: 300
- forum.cursor.com: 312
- github.com: 07 supergrok no x
- github.com: 01 supergrok
- modeldial.com: grok
- v2ex.com: 1236614
- linkedin.com: zaid chrifi ive measured the exact supergrok cursor activity…
- bshp.io: i finally hit the supergrok limit
- remakebench.com: supergrok heavy
- unrollnow.com: 2094858803644903474
- github.com: 85233
- forum.cursor.com: 170206
- forum.cursor.com: 29
- forum.cursor.com: 174358
- forum.cursor.com: 292
- forum.cursor.com: 42
- forum.cursor.com: 48
- forum.cursor.com: 23
- forum.cursor.com: 28
- forum.cursor.com: 69
- forum.cursor.com: 57
- forum.cursor.com: 65
- forum.cursor.com: 74
- forum.cursor.com: 35
- forum.cursor.com: 37
- forum.cursor.com: 34
- forum.cursor.com: 22
- forum.cursor.com: 16
- forum.cursor.com: 172012
- forum.cursor.com: 25
- linkedin.com: serhii vecherenko deepseek v4 flash 0731 still almost unlimi…
- x.com: 2103920755352445306
- feedbackbench.com: factory
- news.ycombinator.com: item
- news.ycombinator.com: item
- github.com: 04 muse code
- linkedin.com: sushanthreddy ai coding claudecode activity 7501117078209474…
- kingy.ai: muse wonder full pricing benchmarks comparison
- mistral.ai: pricing
- aifreeapi.com: mistral api free tier
- reddit.com: mistral pro usage limit
- reddit.com: token consumption in pro plan
- reddit.com: long rant about the stupidity that is mistral
- devin.ai: windsurf pricing plans
- reddit.com: is windsurf still practical
- linux.do: 2995053
- github.com: 13707
- standardcompute.com: clinepass
- synthetic.new: rate limits
- synthetic.new: pricing
- standardcompute.com: synthetic
- alibabacloud.com: coding plan
- zenn.dev: 25c0ab111c277c
- rhombus.so: limits
- finopsllm.com: claude max 20x vs 5x weekly limit
- github.com: quotas web 2026 09.json
- github.com: cli command reference
- reddit.com: how does the usage credit scale for each plan
- reddit.com: how are pros usage limit in regard to codex and
- usagepricing.com: factory
- threatfrontier.com: github copilot pro vs pro plus ai credits explained
- ston.is: copilot credit budget
- reddit.com: copilot pro usage limits
- quotawire.com: gemini
- blog.laozhang.ai: gemini 4 argon usage limits
- shipwithmuse.live: muse code
- o-mega.ai: muse code pricing 2026 plans limits wonder full access
- toolcolumn.com: meta muse usage limits by plan
- v2ex.com: 1227856
- owent.net: 2606
- kingy.ai: ai coding plan limits
- threatfrontier.com: best 10 dollar open model coding plan october 2026
- learn.chatgpt.com: pricing
- community.openai.com: 1407483
- cloud.tencent.com: 130092
- intl.cloud.tencent.com: 81315
- mimo.mi.com: token plan
- developersdigest.tech: zai
- docs.z.ai: usage revision
- zcode.z.ai: configuration
- v2ex.com: 1190063
Subscription terms and prices
- opencode.ai: zen
- opencode.ai: zen
- opencode.ai: go
- opencode.ai: go
- docs.cline.bot: clinepass
- cline.bot: cline pass
- nano-gpt.com: pricing
- nano-gpt.com: support
- nano-gpt.com: terms of service
- commandcode.ai: pricing limits
- commandcode.ai: pricing
- commandcode.ai: goat
- commandcode.ai: pro
- commandcode.ai: max
- dev.synthetic.new: models
- ollama.com: pricing
- ollama.com: transparent pricing
- atlascloud.ai: coding plan
- atlascloud.ai: coding plan codex usage limits workaround
- standardcompute.com: pricing
- standardcompute.com: standard compute facts
- docs.devin.ai: self serve
- docs.devin.ai: quota
- warp.dev: pricing
- docs.warp.dev: pricing faqs
- mistral.ai: pricing
- docs.mistral.ai: subscriptions
- z.ai: subscribe
- docs.z.ai: faq
- docs.z.ai: subscription terms
- docs.z.ai: usage policy
- docs.z.ai: teamplan
- kimi.com: pricing
- kimi.com: membership
- kimi.com: models
- kimi.com: claude code
- kimi.com: community guidelines
- kimi.com: membership pricing
- kimi.com: membership update rules
- platform.minimax.io: faq
- platform.minimax.io: monthly offer
- minimax.io: m plan
- platform.minimax.io: usage rules
- minimax.io: minimax m3
- alibabacloud.com: coding plan faq
- alibabacloud.com: what is model studio
- deepseek.com: platform
- api-docs.deepseek.com: pricing
- api-docs.deepseek.com: rate limit
- api-docs.deepseek.com: list models
- cdn.deepseek.com: deepseek terms of use
- mimo.mi.com: subscription
- mimo.mi.com: team
- mimo.mi.com: tools overview
- docs.byteplus.com: model pricing
- docs.byteplus.com: coding plan personal plan overview
- byteplus.com: arkcodingplan
- tencentcloud.com: 81315
- tencentcloud.com: ai landing page token
- cloud.tencent.com: 130663
- tencentcloud.com: 84379
- tencentcloud.com: 77269
- codebuddy.ai: term
- cloud.tencent.com: 106125
- codebuddy.ai: iam
- tencentcloud.com: 77270
- codebuddy.ai: enterprise agreement
- support.claude.com: 8325606 what is the pro plan
- claude.com: pricing
- support.claude.com: 11647753 how do usage and length limits work
- support.claude.com: 13189465 log in to your claude account
- code.claude.com: legal and compliance
- anthropic.com: consumer terms
- anthropic.com: updates to our consumer terms
- support.claude.com: 11049741 what is the max plan
- help.openai.com: 6825453 chatgpt usage limits
- openai.com: chatgpt pricing
- help.openai.com: 20001542 using your chatgpt plan in other apps and sites
- help.openai.com: 20001275 chatgpt work and codex
- help.openai.com: 6950777 what is chatgpt plus
- learn.chatgpt.com: auth
- gemini.google.com: advanced
- gemini.google.com: advanced
- one.google.com: google one ai subscription benefits
- support.google.com: 16275805
- blog.google: google ai subscriptions
- blog.google: gemini cli code assist higher limits
- one.google.com: google ai plans
- support.google.com: 14534406
- developers.google.com: plans and pricing
- docs.cloud.google.com: quotas
- docs.github.com: plans
- docs.github.com: models and pricing
- docs.github.com: billing
- docs.github.com: about third party coding agents
- docs.github.com: github terms of service
- github.com: copilot
- cursor.com: pricing
- cursor.com: usage limits
- cursor.com: new tier
- cursor.com: available models
- cursor.com: models and pricing
- prod.cursor.com: acceptable use policy
- docs.factory.ai: individuals
- docs.factory.ai: models
- factory.ai: pricing
- factory.ai: terms individual
- docs.x.ai: pricing
- docs.x.ai: faq
- cursor.com: pricing
- x.ai: x subscription
- docs.x.ai: release notes
- docs.x.ai: usage limits
- dev.meta.ai: what is a muse code subscription
- dev.meta.ai: subscriptions
- dev.meta.ai: muse wonder
- dev.meta.ai: models
- dev.meta.ai: terms of service
- dev.meta.ai: coding agents
Team, enterprise and startup terms
- docs.factory.ai: organizations
- kimi.com: kimi business
- x.ai: grok business
- mistral.ai: vibe agent
- docs.devin.ai: usage
- cursor.com: pricing
- cursor.com: privacy and data governance
- docs.github.com: seats and billing cycles
- cloud.google.com: pricing
- workspace.google.com: ai
- workspace.google.com: pricing
- support.claude.com: 9266767 what is the team plan
- support.claude.com: 9797531 what is the enterprise plan
- help.openai.com: 8792828
- help.openai.com: 20001264
- platform.minimax.io: pricing token plan team
- alibabacloud.com: ai token plan
- alibabacloud.com: ai scene ai agent qoder
- docs.x.ai: pricing
- docs.x.ai: rate limits
- platform.minimax.io: overview
- docs.fireworks.ai: reserved throughput
- docs.fireworks.ai: reservations
- docs.fireworks.ai: batch inference
- fireworks.ai: pricing
- docs.together.ai: provisioned throughput
- docs.together.ai: pricing
- together.ai: introducing the together enterprise platform
- learn.microsoft.com: provisioned throughput
- azure.microsoft.com: microsoft foundry
- docs.anthropic.com: pricing
- platform.claude.com: service tiers
- docs.anthropic.com: zero data retention
- docs.anthropic.com: claude on vertex ai
- openai.com: api scale tier
- openai.com: api reserved tier
- developers.openai.com: your data
- cloud.google.com: pricing
- docs.cloud.google.com: priority paygo
- aws.amazon.com: pricing
- docs.aws.amazon.com: model card anthropic claude sonnet 4
- docs.aws.amazon.com: prov throughput
- docs.aws.amazon.com: data retention
- together.ai: startup accelerator
- forum.cursor.com: 174672
- cursor.com: student discount
- learn.microsoft.com: mfs faqs
- claude.com: were expanding the claude startups program to help founders …
- claude.com: startups
- fireworks.ai: startups
- openai.com: startups
- openai.com: supporting next generation ai startups thailand
- cloud.google.com: benefits
- cloud.google.com: early stage
- cloud.google.com: ai
- github.com: startups
- aws.amazon.com: credits
- aws.amazon.com: everything you need to know about aws activate credits
- x.ai: startup program terms
Hoster price checks (own sites)
- intl.cloud.baidu.com: qianfan campaign
- cloud.baidu.com: wmh4sv6ya
- baseten.co: pricing
- crusoe.ai: pricing
- cogito.decart.ai: pricing
- cogito.decart.ai: models
- cloudeka.id: deka llm en
- inference.net: glm 5.3
- inference.net: glm 5.3 flash
- makora.com
- makora.com: pricing
- docs.mistral.ai: pricing
- docs.mistral.ai: zai glm 5 3
- morphllm.com: pricing
- near.ai: pricing
- near.ai: pricing
- openinference.ai
- openrouter.ai: open inference))
- developer.reka.ai: pricing
- docs.sailresearch.com: pricing
- streamlake.ai: mgrnm4xm362hvp5wyce
- console.tenstorrent.com: pricing
- pass.wafer.ai: models
- zenmux.ai: deepseek v4 pro
- docs.aws.amazon.com: model card xai grok 4 7
Vendor profiles
- moonshot.ai: about
- platform.kimi.ai: models
- kimi.com: en
- scmp.com: moonshot ais kimi chatbot
- deepseek.com: v4 preview
- api-docs.deepseek.com: pricing
- techcrunch.com: deepseek everything you need to know about the ai chatbot ap…
- cnbc.com: deepseek v4 llm preview open source ai competition china
- cnbc.com: no poaching our people chinas deepseek reportedly tells inve…
- alibabacloud.com: qwen coder
- github.com: Qwen3.6
- cnbc.com: alibaba cloud revenue
- cnbc.com: minimax hong kong ipo ai tigers zhipu
- minimax.io: m3
- platform.minimax.io: token plan
- mi.com: index
- mimo.mi.com: model
- thenextweb.com: xiaomi mimo v2 6 open weight model anthropic distillation
- yicaiglobal.com: chinas xiaomi to invest over usd87 billion in ai in next thr…
- ai.google.dev: google ai plans
- geminicli.com: quota and pricing
- developers.google.com: code assist individuals
- blog.google: alphabet earnings q2 2026
- docs.x.ai: grok 4 7
- x.ai: grok build 0 1
- docs.x.ai: overview
- cnbc.com: musk xai spacex biggest merger ever
- cnbc.com: elon musk spacex xai ipo
- content.spacex.com: SpaceX PricingAnnouncement
- cnbc.com: spacex raises 75 billion in record setting ipo ahead of nasd…
- mistral.ai: devstral 2 vibe cli
- mistral.ai: mistral vibe 2 0
- techcrunch.com: mistral raises e3b as sovereign ai becomes big business
- cnbc.com: mistral ai funding valuation samsung
- cnbc.com: mistral cnbc disruptor 50 ranking
- ir.aboutamazon.com: Amazon com Announces Second Quarter Results
- aws.amazon.com: amazon bedrock adds support six open weights models
- microsoft.com: earnings fy 2026 q4
- azure.microsoft.com: models
- techcrunch.com: neocloud together ai raises 800m leaps to 8 3b valuation
- aramcoventures.com: together ai raises 800 million at 8 3 billion valuation to m…
- together.ai: serverless inference
- together.ai: announcing our series c
- deepinfra.com: series b
- deepinfra.com: DeepInfra%20Series%20B%20Media%20FAQ
- bloomberg.com: nvidia backs deepinfra in 107 million raise video
- businesswire.com: Baseten Raises $1.5 Billion to Power the Next Era of AI Infe…
- baseten.co: model apis
- baseten.co: announcing our series f
- news.crunchbase.com: biggest funding rounds ai marketing robotics baseten
- crunchbase.com: novita ai
- novita.ai
- novita.ai: models
- finance.sina.com.cn: doc inismzux1606673.shtml
- www1.hkexnews.hk: 2026092100319
- finance.eastmoney.com: 202609213879573276
- caixinglobal.com: ai firm siliconflow raises new funds 102487398
- en.wikipedia.org: BytePlus
- byteplus.com: modelark
- byteplus.com: codingplan
- volcengine.com: 37637
- chinadaily.com.cn: WS69ce3326a310d6866eb41733
- intl.cloud.tencent.com: 78941
- tencentcloud.com: 81035
- tencent.com: Tencent Announces 2026 Second Quarter Results
- cnbc.com: china tencent earnings q2 2026 gaming ai advertising
- github.blog: 2026 06 01 updates to github copilot billing and plans
- microsoft.com: earnings fy 2026 q4
- cnbc.com: microsoft msft q4 earnings report 2026
- cnbc.com: cursor cnbc disruptor 50 ranking
- cnbc.com: spacex spcx cursor acquisition ipo
- sec.gov: spcx 20260814
- cursor.com: joining spacex
- docs.x.ai: overview
- finance.yahoo.com: cline raises 32m seed series 170000715
- cline.bot
- commandcode.ai: launch
- pwv.com: ahmad awais
- commandcode.ai: about
- finance.yahoo.com: atlas cloud ai newyork greencloud 170000673
- linkedin.com: atlas cloudai
- inc.com: 91366933
- standardcompute.com: about
- standardcompute.com: terms
- standardcompute.com
- synthetic.new: 2026 01 01
- synthetic.new: subscriptions
- linkedin.com: milandereede
- nano-gpt.com: press
- techcrunch.com: popular open source ai developer tool ollama raises 65m grow…
- factory.com: 5 billion valuation
- factory.com: series c
- techcrunch.com: factory hits 1 5b valuation to build ai coding for enterpris…
- forbes.com: meta launches muse code a new ai coding agent powered by spa…
- dev.meta.ai: muse code new plans and features
- cnbc.com: meta debuts muse code to take on anthropic and openai
- techcrunch.com: meta is paying to peek at how you use their latest ai model
- warp.dev: warp open sources its agentic development environment
- warp.dev: warp is now open source
- warp.dev: warp launches oz the orchestration platform for cloud coding…
- cnbc.com: cognition valued at 10point2 billion two months after windsu…
- devin.ai: windsurf is now devin desktop
- techcrunch.com: cognition hits 48b valuation signaling investors believe ai …
- techcrunch.com: openrouter more than doubles valuation to 1 3b in a year
- openrouter.ai: about
- cnbc.com: stripe openrouter fintech ai model marketplace
- stripe.com: stripe agrees to acquire openrouter
- seekingalpha.com: 4635068 stripe confirms openrouter acquisition terms undiscl…
Price data
Prices, plans and benchmark scores as of 18 October 2026.